Build Log - Ceph Cluster - Homelab redesign

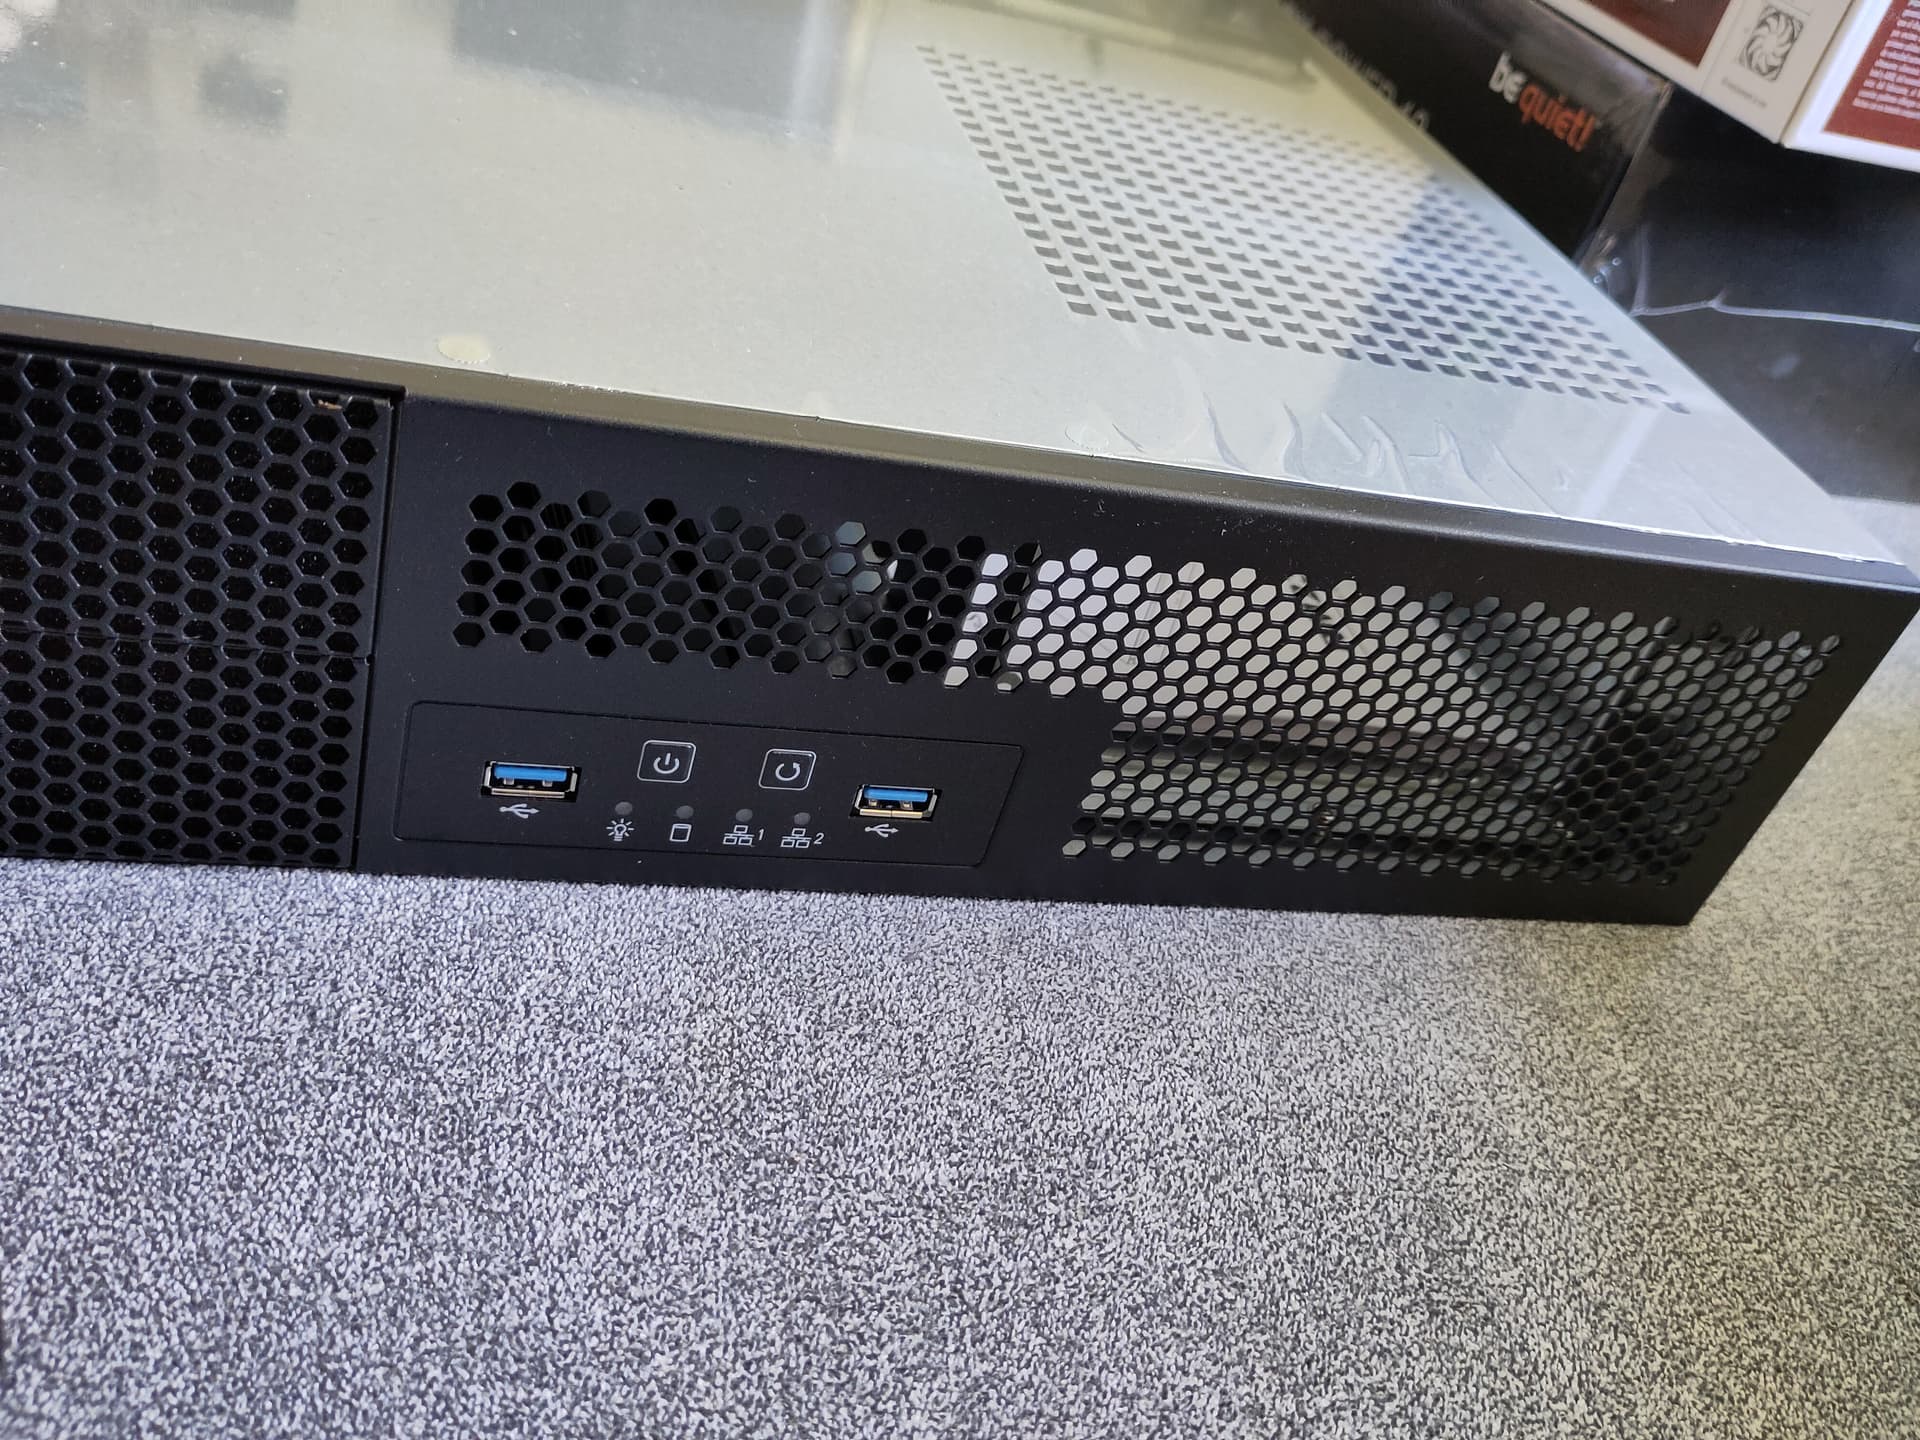
My AIO cooler in my homeserver died two weeks ago and I decided to repurpose the existing machine from my Silverstone CS 381 to a 2U chassis (Silverstone RM23-502).

I was planning to build a Ceph cluster eventually, but this was pretty much the kickoff to buy new and fancy stuff.
For the time being, particularly because I lack hardware for the other nodes, this will serve as a single node cluster until I buy the other hardware and networking needed/desired.

Full cluster will be 3x 2U or 2x 2U +1x4U nodes (2x Ryzen, 1xEPYC) with 25GbE. Storage will be served by 2x HDDs I keep on using as well as 2-4 Enterprise SSDs with 2-8TB, both per node.

Existing server is:
Ryzen 5900x
128GB ECC
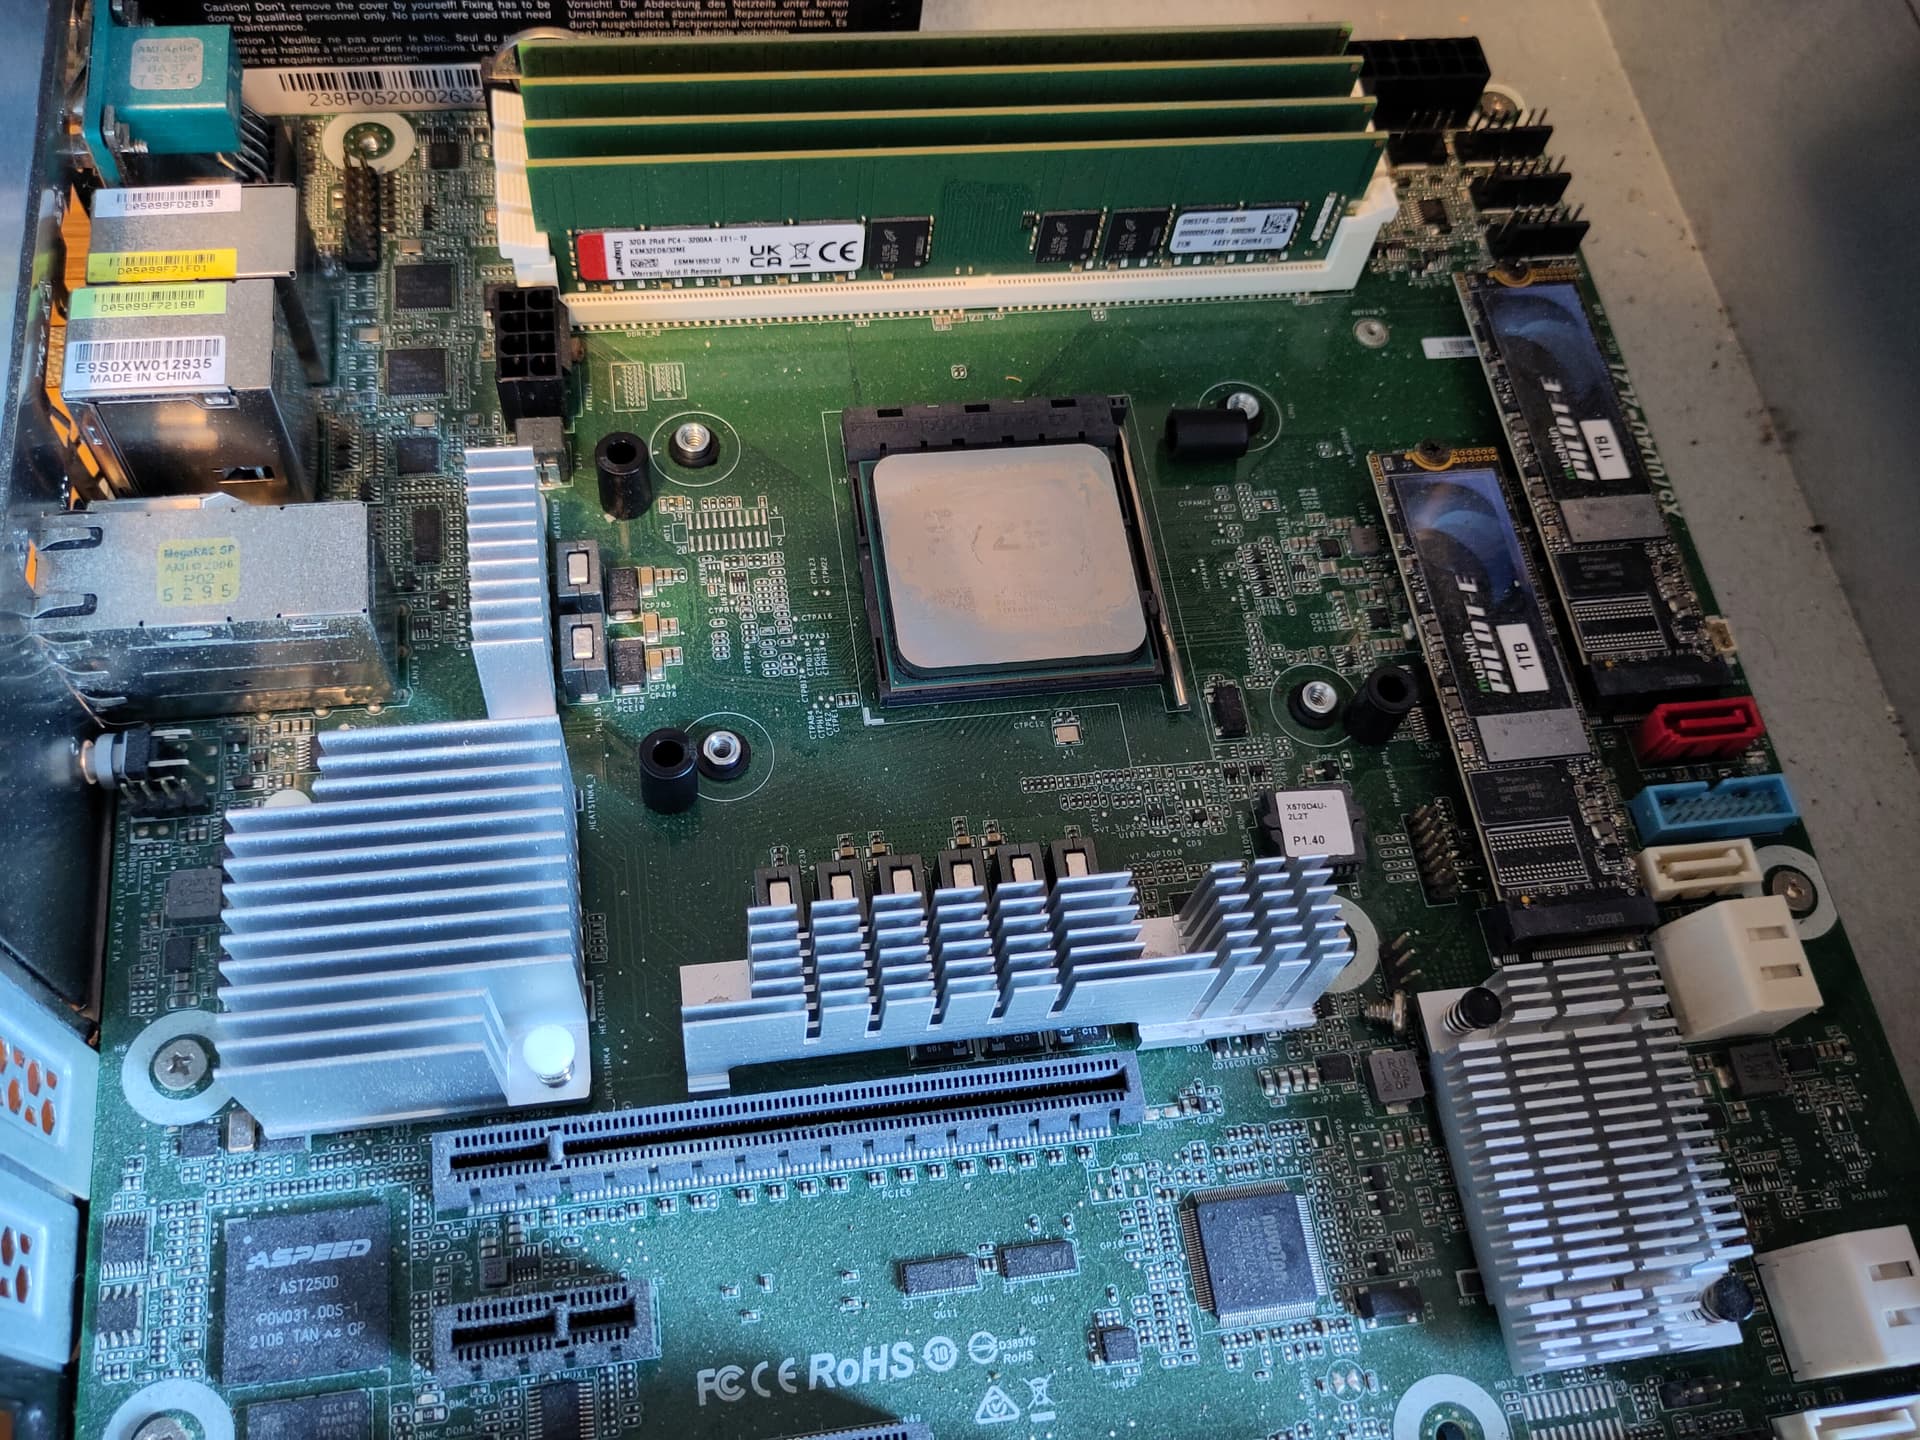
AsRock Rack D4U-2L2T board
broken AIO cooler
6x 16T Toshiba HDDs, 2x 1TB M.2 consumer drives, 2x SATA SSD

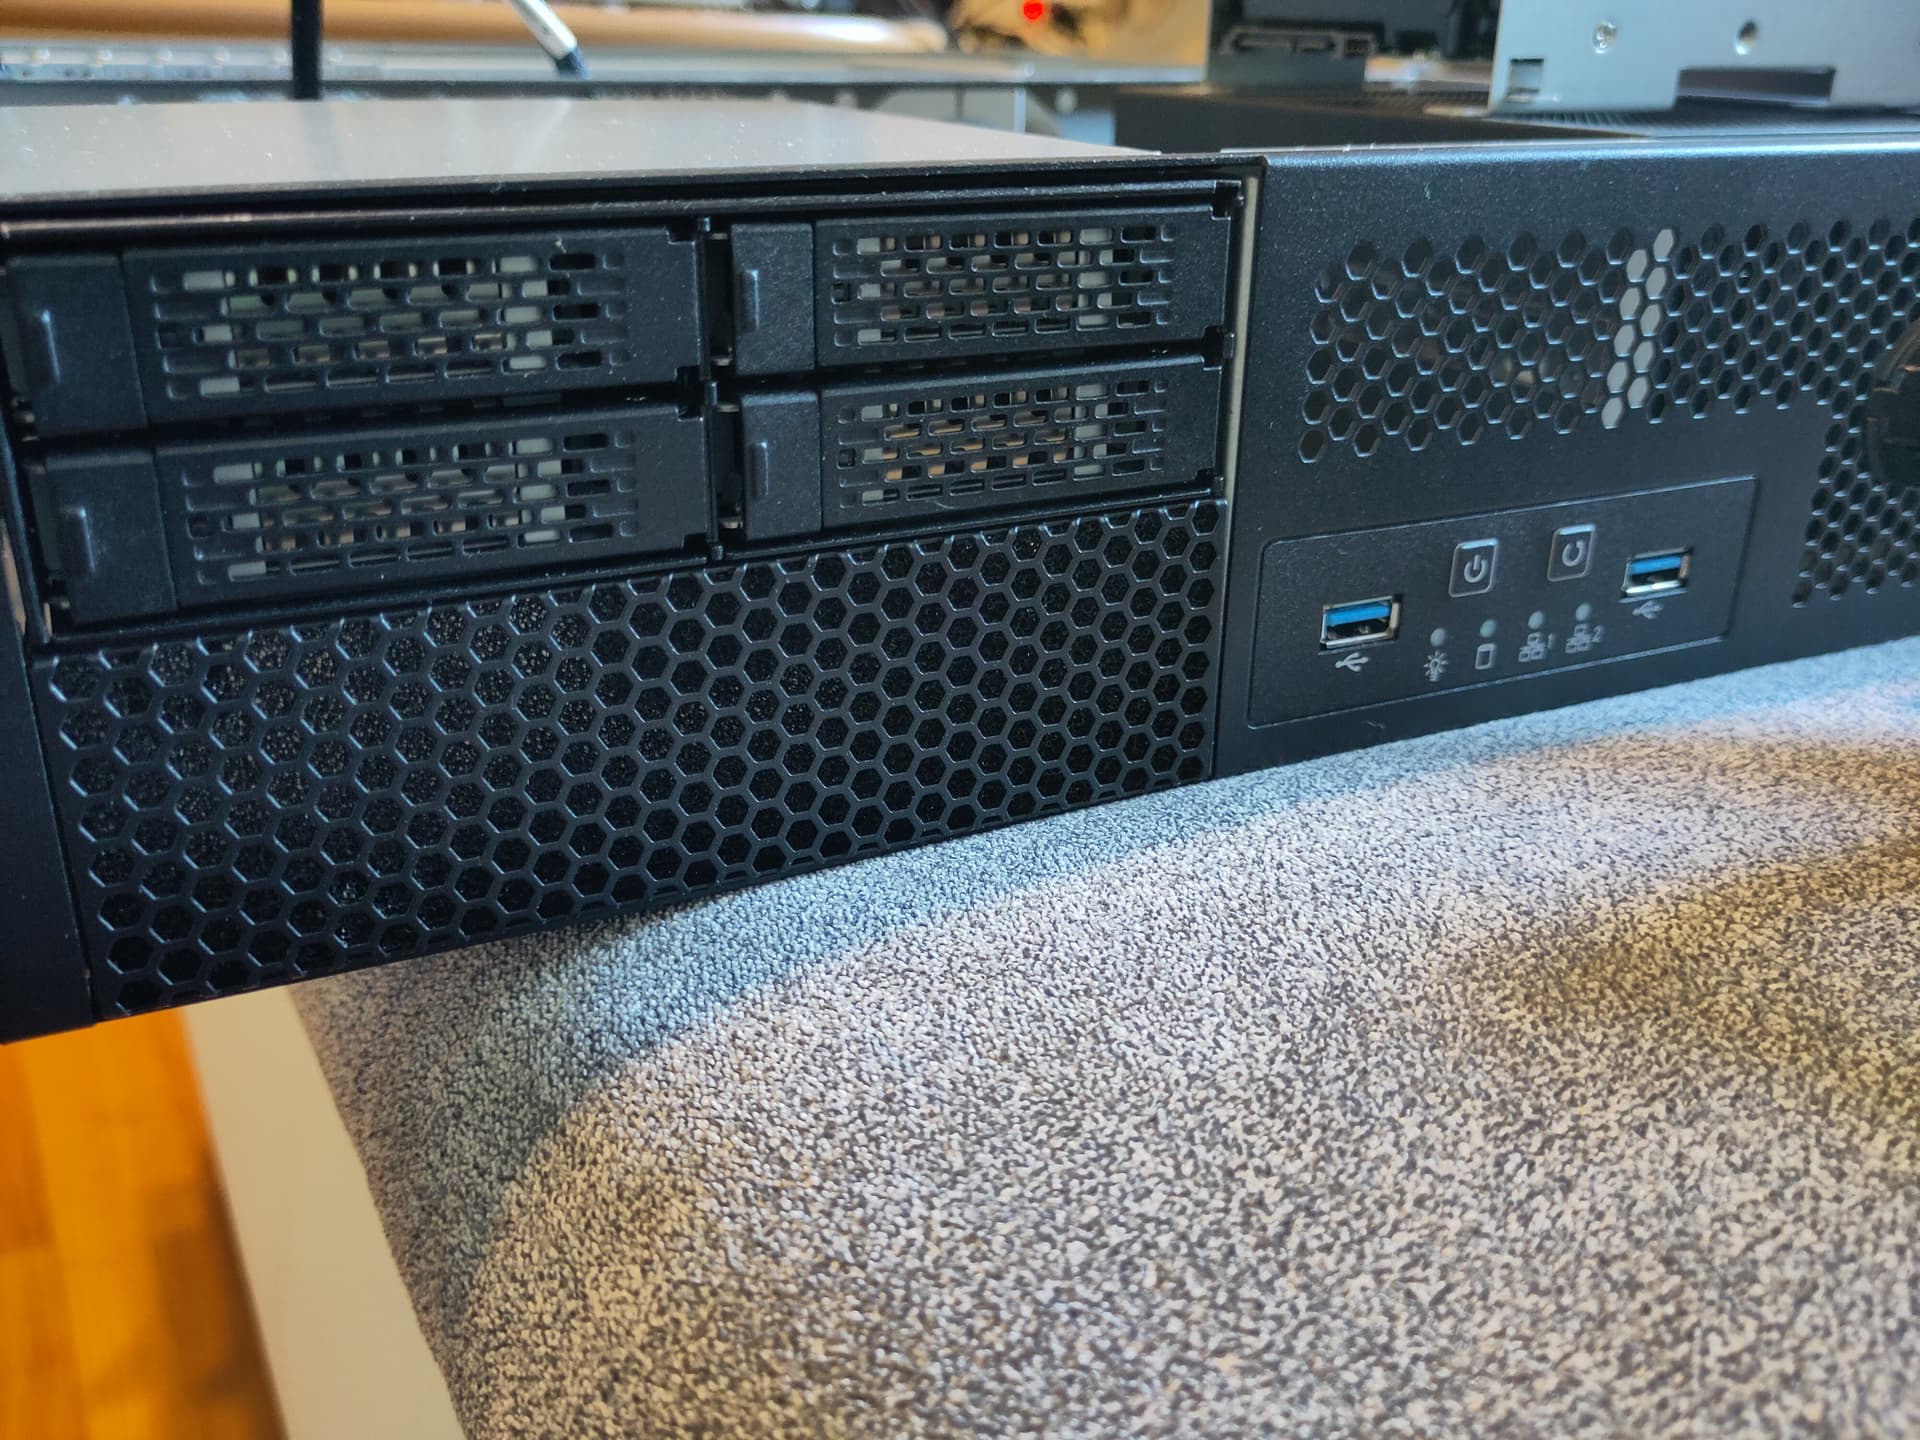
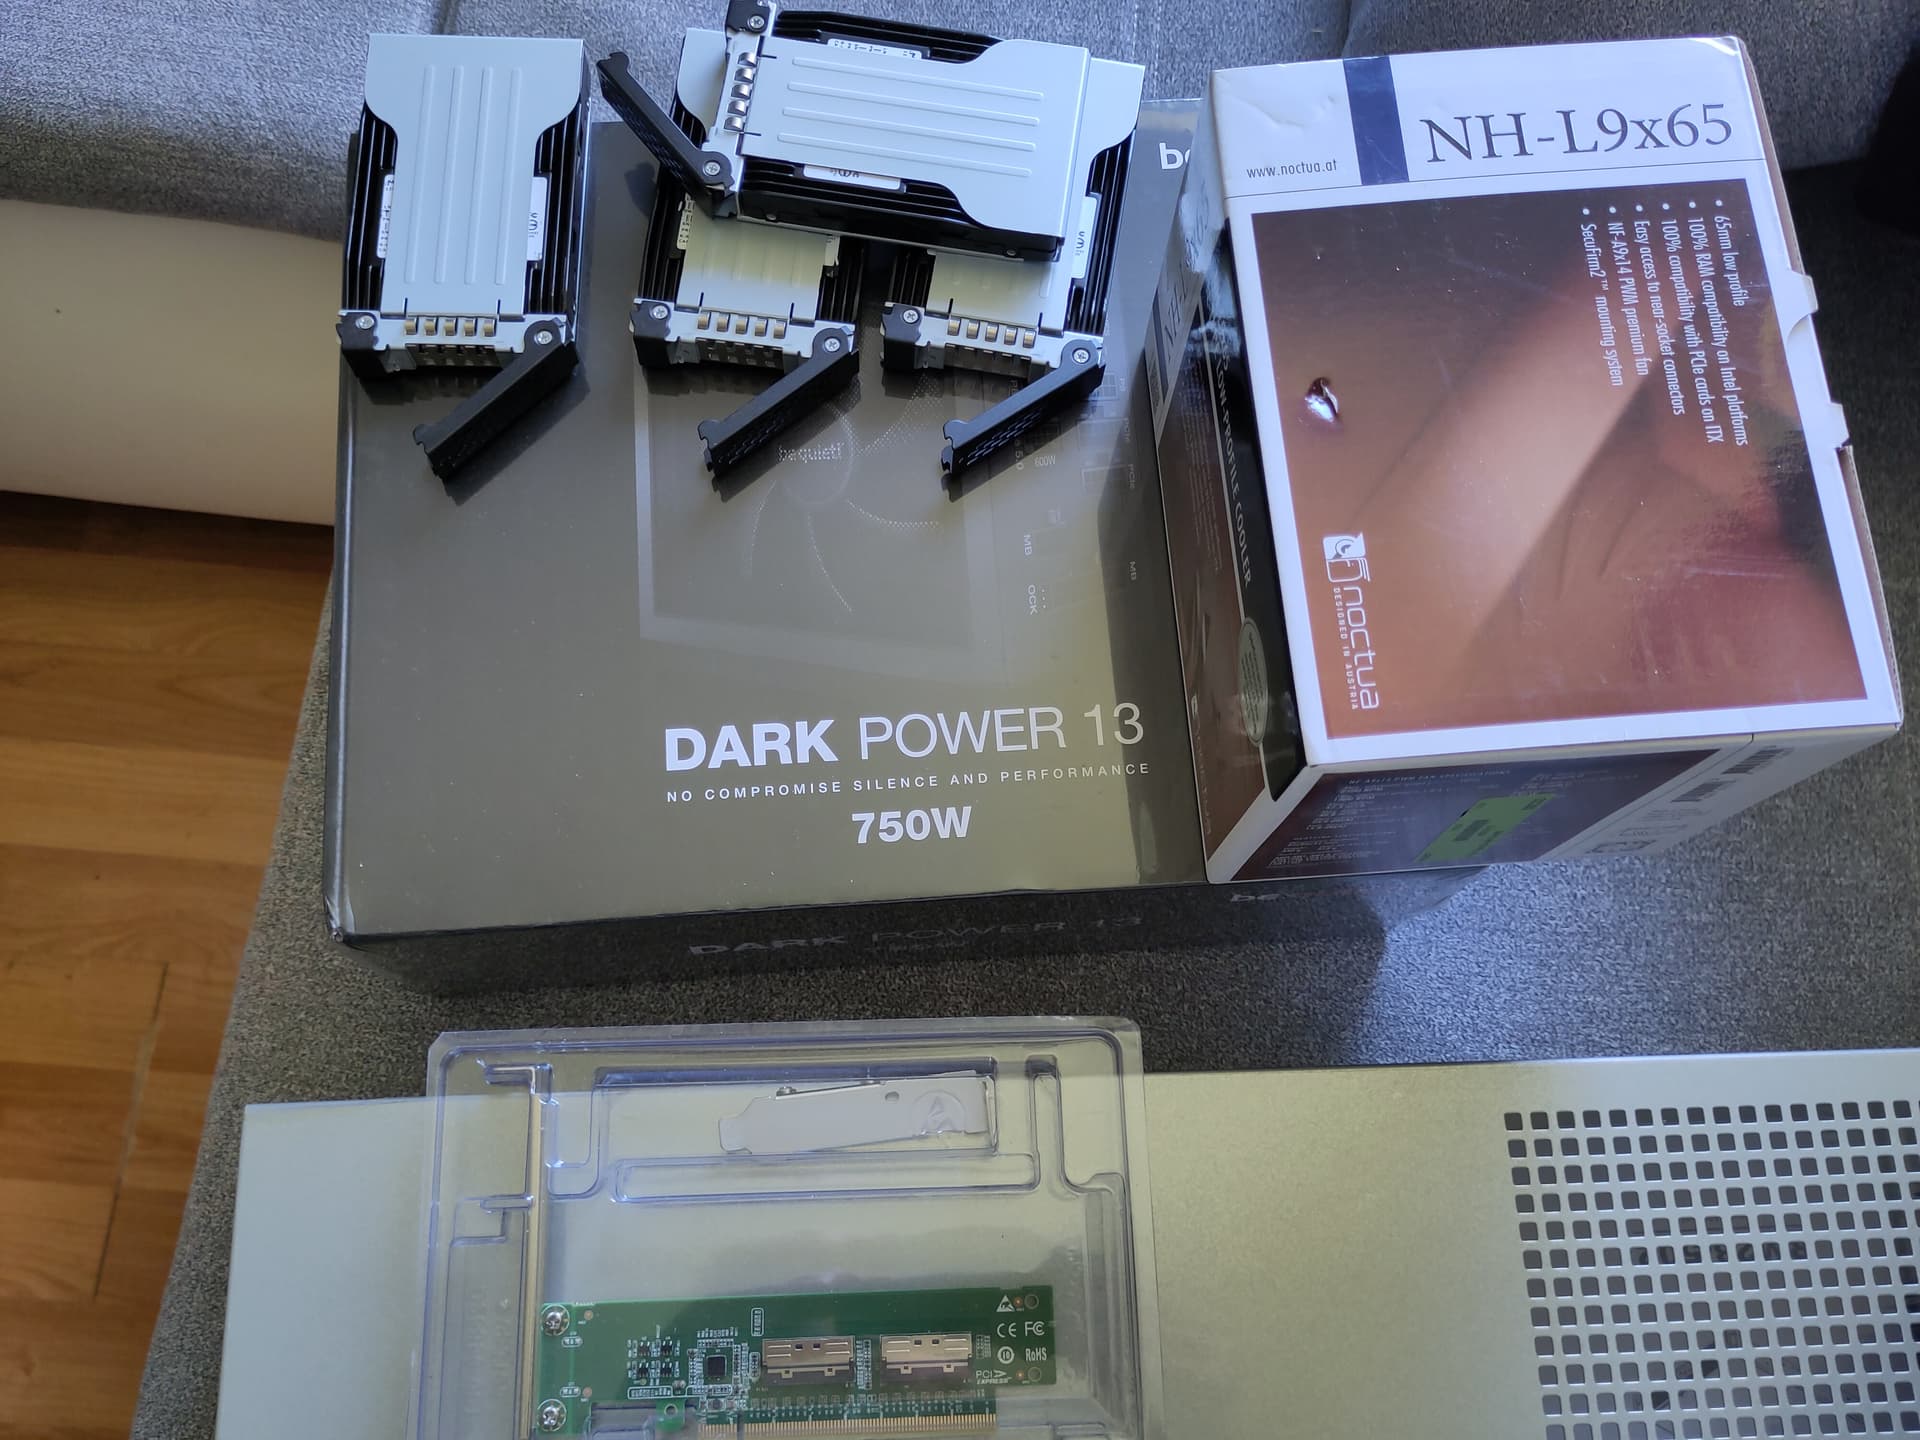
Bought an IcyDock Cage for 4x U.3 alongside 4x Micron 7400 (prices are outta control, got new 7400s for 65€/TB) and MCIO PCIe card + cables.
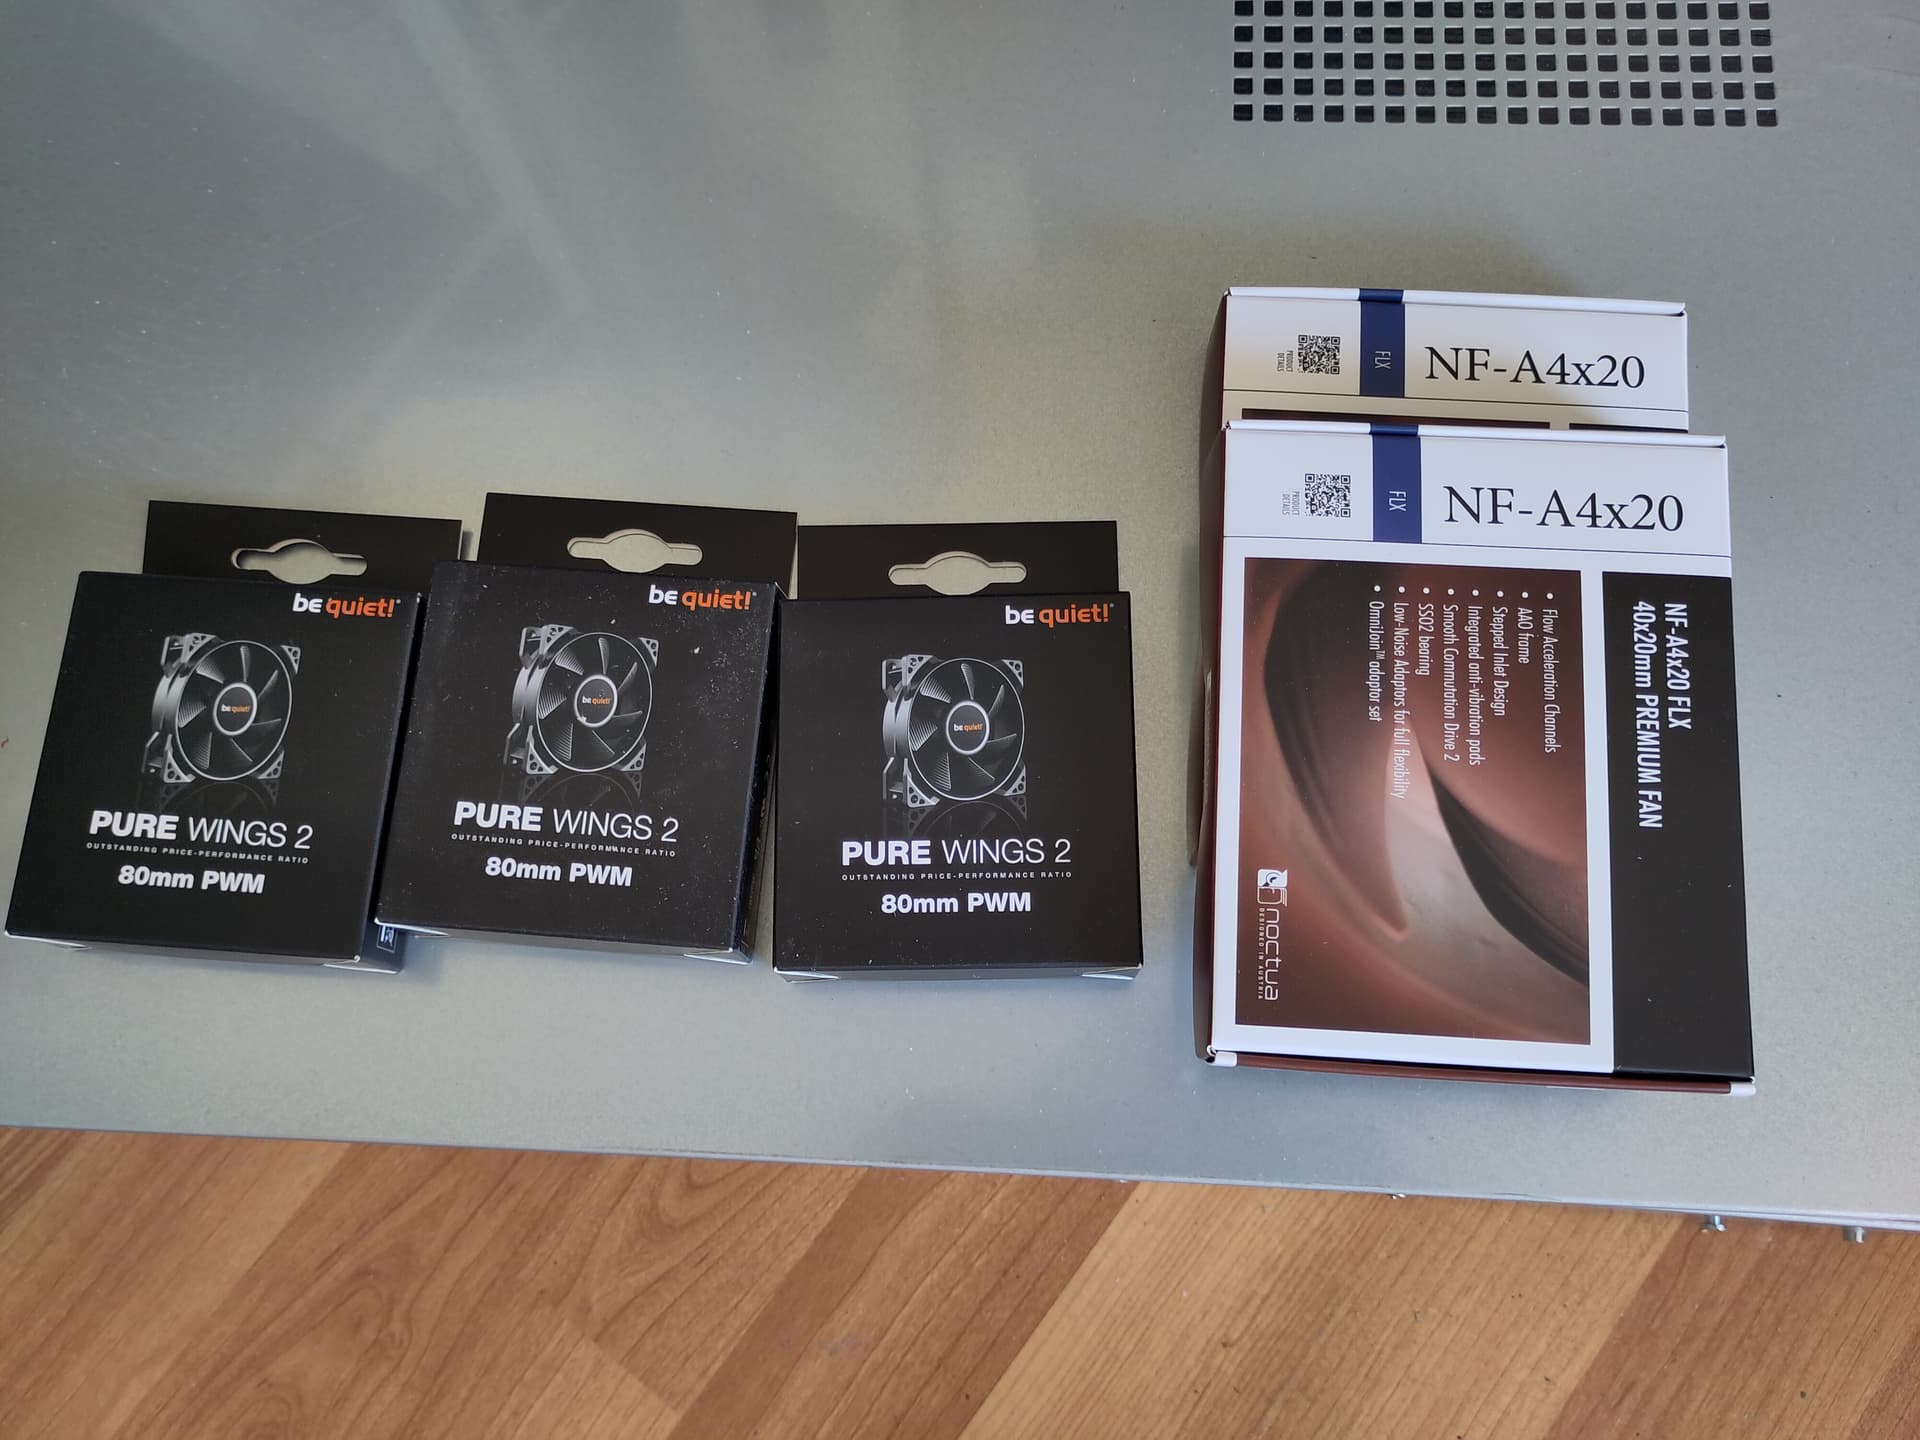
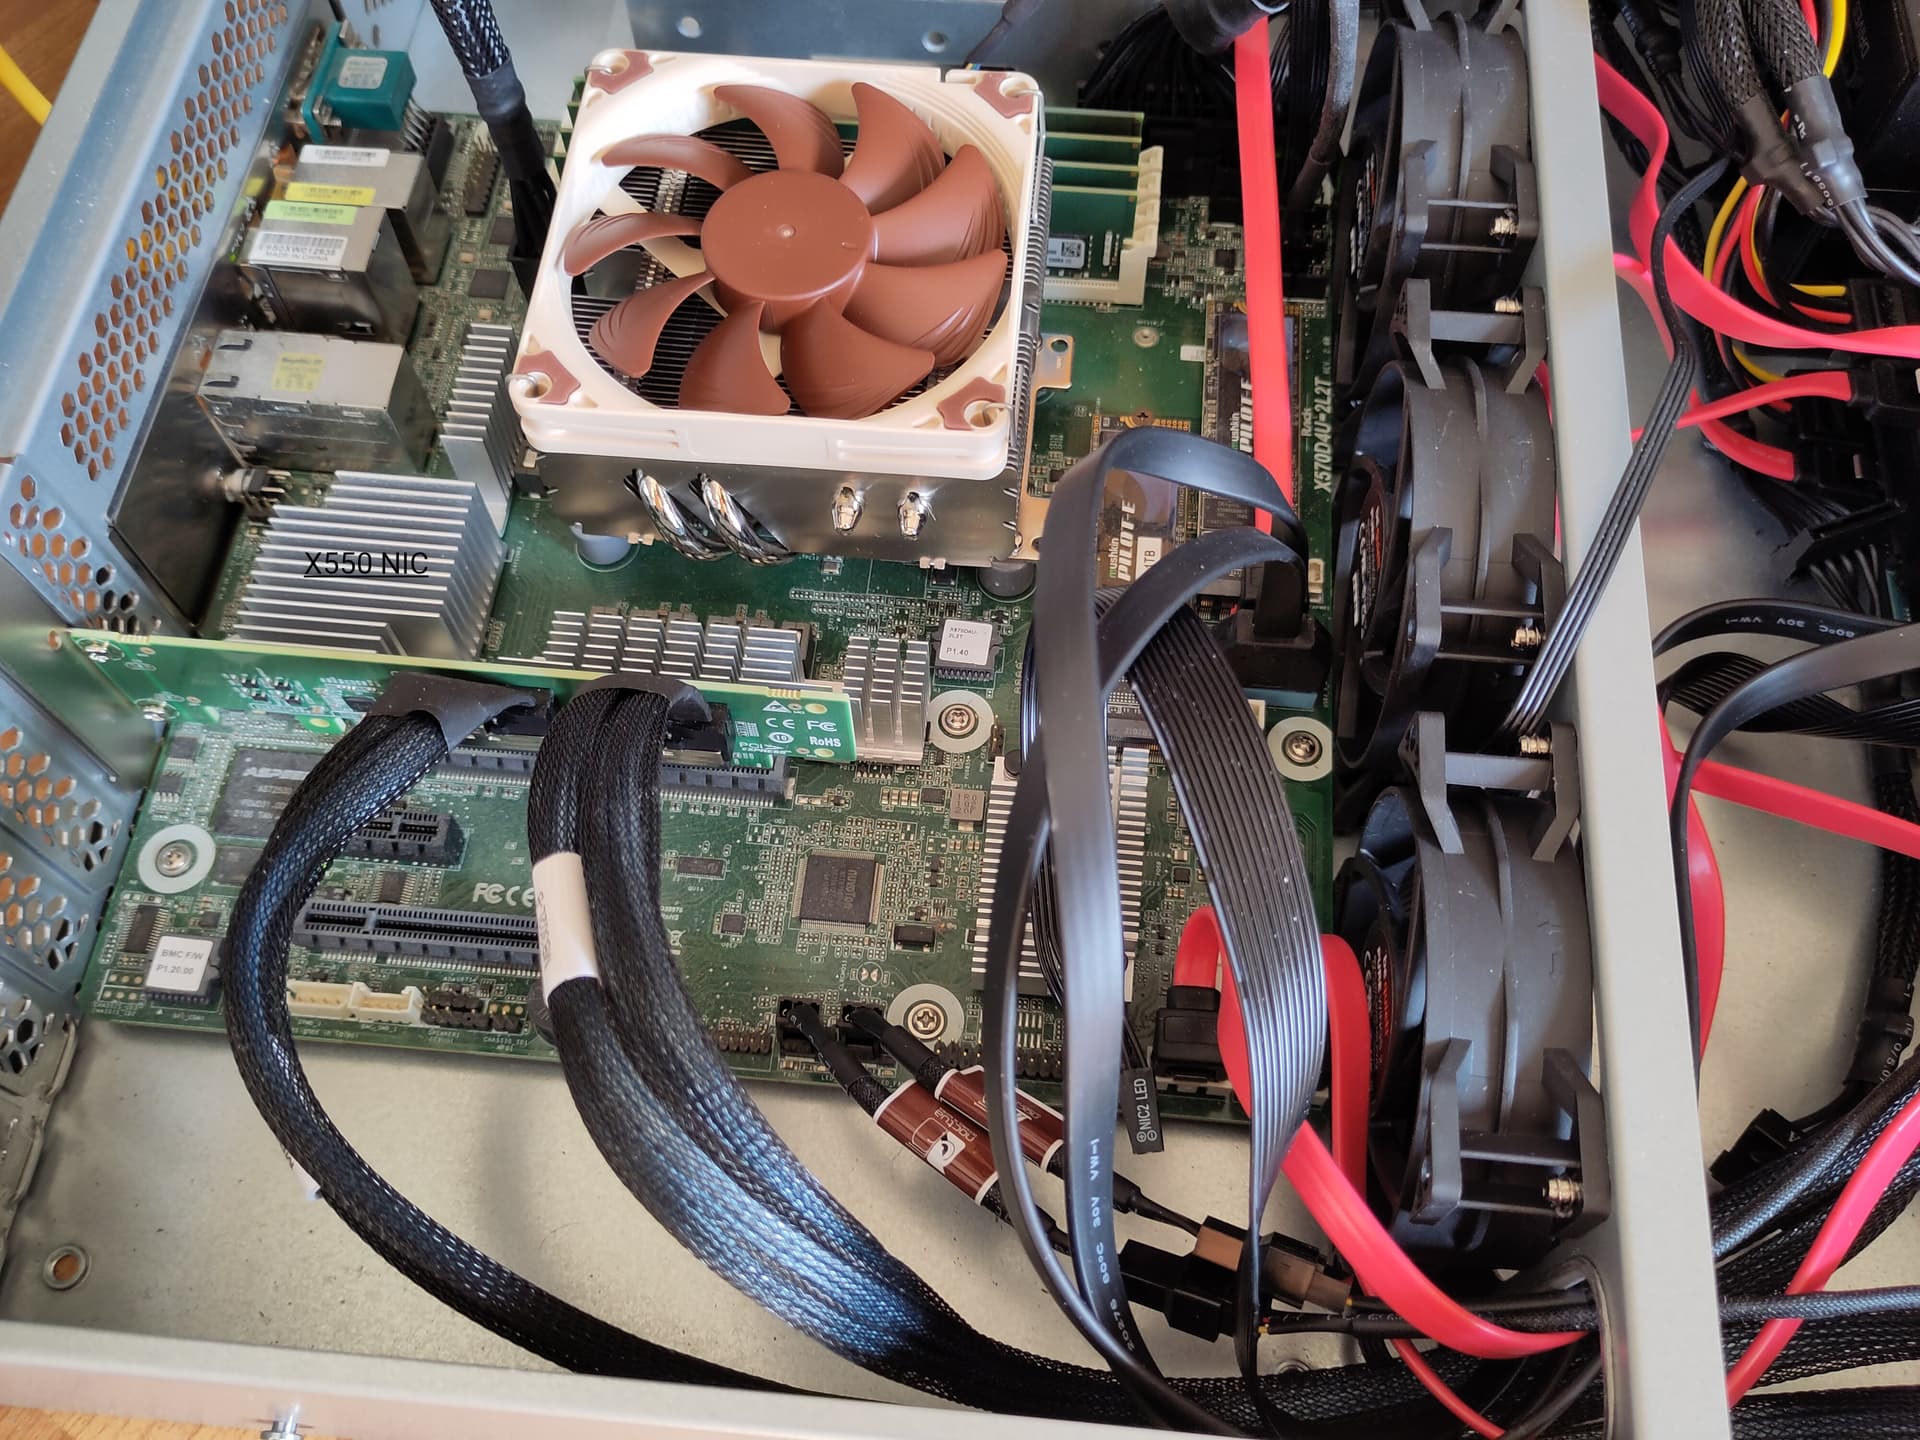
PSU gets replaced with Be Quiet Titanium one and got a low profile Noctua with 65mm height so it fits into 2U without need for vacuum cleaner-style 8k RPM cooling.

Here some pics from the upgrades:

Will post progress. Can’t wait to get my server back up and running. And see if those expensive MCIO cables were worth it.

9 Likes
  • Stripped the old case from any stuff, about to transplate the board into new chassis.

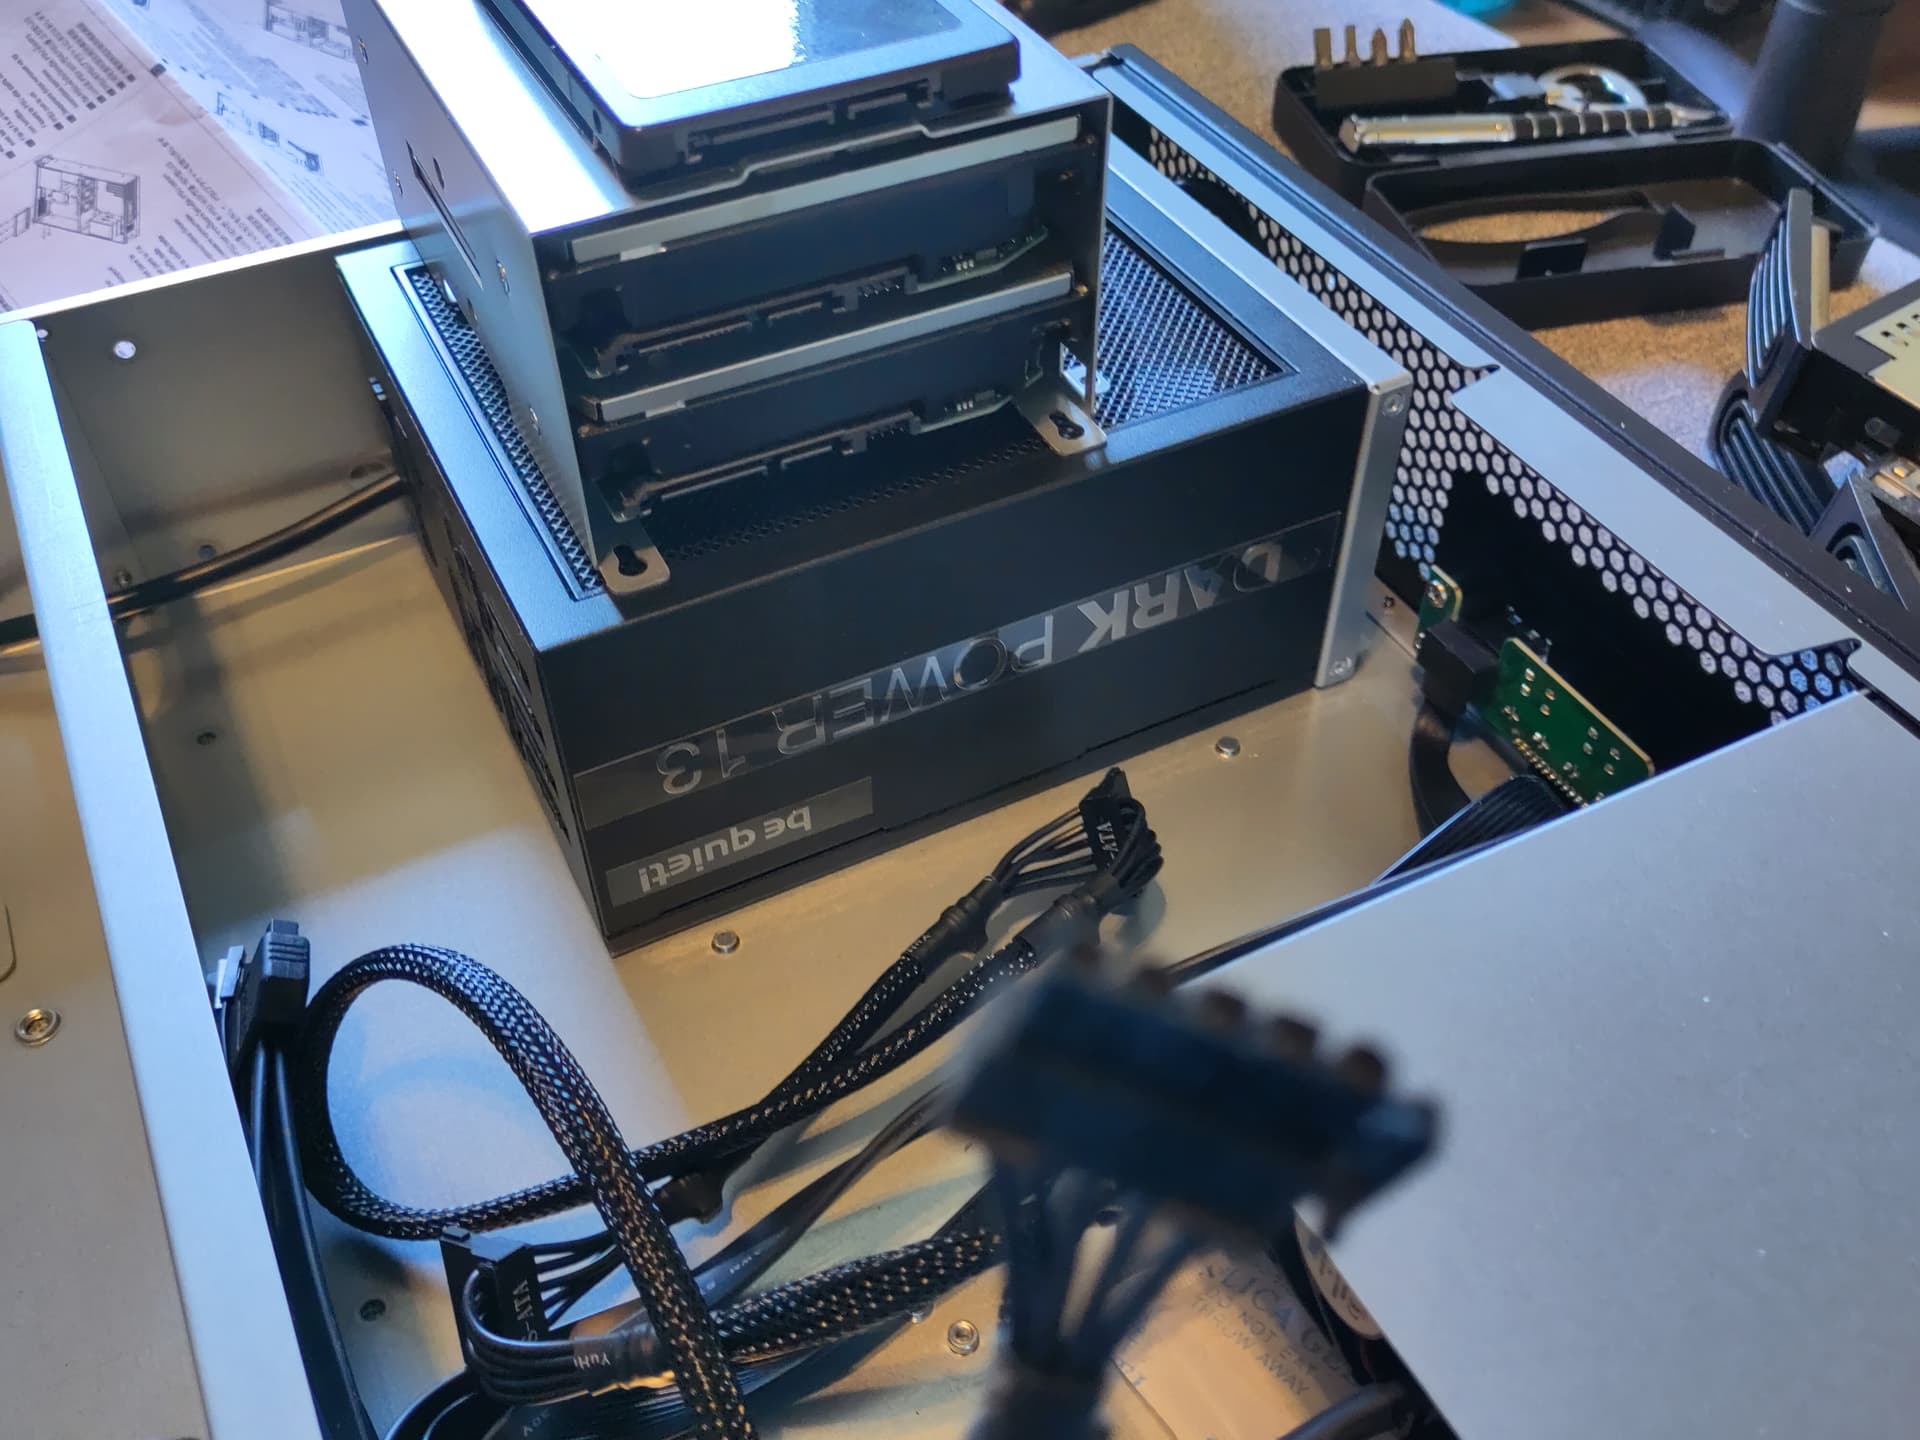
  • Installed PSU in the front bracket (yeah, most 2U cases only can use ATX if it is mounted in the front). Not great engineering on Silverstones side to fixate PSU and bracket, encourages child labor.

  • Installed HDDs and SSDs into their respective front and internal brackets. internal HDDs are the biggest downside of the case in terms of features. Front PSU blocks two potential 5.25" bays which could have 3xHDD hotswap bays. 2U is a story of compromises. It’s fine to me.

  • Noticed that I didn’t order any 80mm case fans, so testing and closing the lid will have to wait until I get them delivered (ordered 2x Noctua 20mm fans too to replace IcyDock stock fans)


1 Like

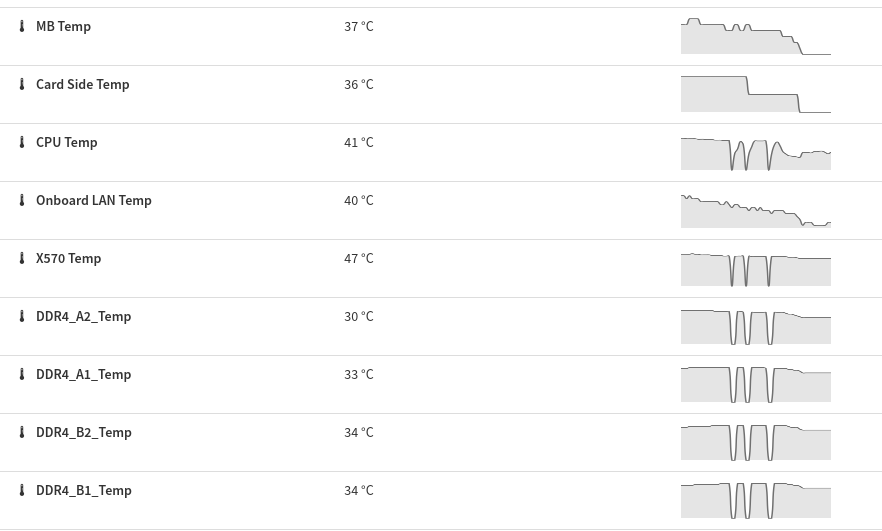
First test run was surprisingly smooth…I expected some things to not work. But even the 4x new NVMe connected via 2x MCIO 8i cables on a x16 card were automatically detected. Temps are fine, everything is running…

Now installing Proxmox and burning in and testing fio stuff. But have to lower the fan speeds after setting everything to high just in case.

2 Likes

Hardcore SYNC 4k blocksize with Queue depth of 1 on my new Micron 7400 drives.

fio --ioengine=libaio --filename=/dev/nvme2n1 --direct=1 --sync=1 --rw=write --bs=4K --numjobs=1 --iodepth=1 --runtime=60 --time_based --name=fio

IOPS=80.2k, BW=313MiB/s (328MB/s)(18.4GiB/60001msec); 0 zone resets

sequential reads clock in at 6718MiB/s. Pretty much standard PCIe 4.0 bandwidth. Writes are 2.1GiB/s. Everything pretty much in line with official Micron specs.

They may be last-gen SSDs, but with 80k IOPS on that sync-torture test, they pack a punch. All my consumer PCIe 4.0 drives I used for testing previously made like 1.5-2.5k IOPS. This cluster will never ever bottleneck on storage hardware.

System Power draw changed very favorably. Change from Gold to Titanium PSU, 4 less HDDs but 4 more Enterprise SSDs. Went from ~90W to ~70W idle. Didn’t check full load figures yet and 3x80mm fans are still missing. I didn’t expect that much savings tbh, but I’ll take it.

1 Like

Hey Exard3k,

this is a great idea. I didn’t know server mainboards for desktop CPUs existed in this form. Am i correct in assuming that with this board you can put in that 5900X and have the system boot up without the need of dedicated graphics card? That would be “ill”, at least from a technical standpoint :smiley:

1 Like

Welcome!

Thanks. Yeah, it just needs power and a network cable and you’re ready to go. You don’t even need a USB flash drive to install the OS. Just upload the .ISO via WebUI and tell BIOS to boot from “CD-ROM”. IPMI (basically on-board remote management) is a nice thing indeed. Asrock Rack and Supermicro both have boards for Core and Ryzen. Prices have gone up since I bought mine. Not cheap these days. With iGPUs now in most CPUs, headless server without IPMI is much easier now. Computer technically just needs CPU and memory, everything else is optional.
All I need is a browser to open the WebUI of the IPMI, Proxmox + other stuff running and some means to connect via SSH, be it Putty or linux terminal. And without GPU, you suddenly find yourself in a position with 20W less idle power and 16 freed up ultra-fast PCIe lanes that are just waiting for big networking or storage alternatives.
I will eventually add a GPU to the cluster for compute purposes and specific VM needs, but the HDMI/DP ports will share the same fate as the rear IO USB → will never see anything plugged into it.

Update on some stuff I tested yesterday:

  • Power:
    I ran some full load stuff with y-cruncher (tough AVX2 code and memory-heavy), keeping all drives busy and running full bandwidth on both 2x1GbE and 1x10GbE. 145-150W at the wall. Idle bouncing between 67-72W. The CPU is running @65W TDP via ECO Mode, otherwise no BIOS or OS tweaking of power settings.
    The old Aspeed 2500 IPMI pulls 8-10W from the wall alone. That’s what I see when powered-down. There may be other MB/PSU things at work too. But majority is certainly the IPMI/BMC.

  • Drives:
    U.3 drives get HOT. I switched off the fans to check smartctl temps for a single U.3. Even idle , temps were slowly creeping to >60°C. Factory HIGH temp is 70°C. You NEED airflow for these
    things. The IcyDock Cage is built very sturdy and because all-metal, spreads heat across the entire cage and the holding bracket very very well, I love the engineering.
    I’m gonna replace the stock fans with Noctua 20mm on Monday and will try to connect those fans to the board fan headers, so I can control fan speeds via IPMI. Stock fans on LOW are “noisy” and on HIGH it’s datacenter mode.

  • CPU Cooler: The Noctua L9x65 has the lowest rating on Noctuas scale and compatibility for 5900x and 5900 stated “yeah, can’t really handle it”. But testing so far shows that the cooler can handle y-cruncher workload at non-audible RPMs with CPU @65W TDP. It’s fine and I’m really happy about it.

  • Will wait with further testing and installs until monday to install 3x80mm case fan row. The on-board x550 Intel NIC gets really hot without airflow on current open setup. Board relies on typical server air flow and uses passive heat sinks and X550 NIC and x570 chipset need it.

Nice to hear it seems to work as it should! From the video it looks like the cables are IcyDock MB302L-B? And the MCIO adapter looks like it might be this Shinreal one?

Do you have AER enabled to monitor bus errors?

1 Like

Indeed. With all the talks about signal integrity, bad cables I’ve seen in my research (here and elsewhere), I went with MCIO (designed for Gen5 NVMe in mind, not for some 12-24G SAS cables and controllers) and validated IcyDock cables. I like their approach to include fitting and validated cables, although at a hefty premium, but buying a bad cable and getting another is even more expensive.

Photo confirms it is the same MCIO card. Same Shinreal label. I see that we are men with good taste for good hardware! :slight_smile:

I bought it from a french company that has a bunch of U.2/3 stuff in stock. Couldn’t find any other fitting card in the EU. MCIO is still very new, especially in retail channels, and availability and product range isn’t at (mini)SAS/OCUlink-level yet.

No, I didn’t go that deep yet. So far I was mostly interested in getting stuff to run and whether performance numbers match the expectations, let it run hours to check temps and stability, stress test on the drives, etc.

I did notice that smartd reports some error entries in the Proxmox syslog after each boot. I didn’t go down the nvme-cli and hexadecimal code rabbit hole yet. Doesn’t seem like it is interrupting or hampering operations on first sight. And no LBA errors or sth very obvious in SMART readings.
I will dig deeper into BIOS settings and error readings in the coming days. So far I don’t see anything of critical importance, might as well be some outdated firmware on the drives or that “quirky” board of mine.

In the end, all the drives are backed by Ceph, with CoW, periodic scrubbing and the whole paranoia mode of data integrity that doesn’t trust any hardware or firmware to begin with. And Ceph elevates that to the node/host level, not to individual drives or controllers.

I made sure my stuff and operations are cared for. Doesn’t mean I ignore obvious problems in the process :wink:

1 Like

Are you planning to run workloads on the cluster nodes themselves, or purely for storage? I’m interested to see the performance over the 25G connection, please posts some tests when you get around to that!

@zibbp Welcome to L1T!

I’m going for a HCI approach with both compute (VMs, kubernetes, legacy LXC) and storage (Ceph OSDs, Monitors and MDS) running on each node. With Proxmox and SDN, I may pick up on the more network-side of HCI, or FRR and switchless cluster network…we’ll see. That’s the part I’m the least familiar with. But the entire thing is also made to do new things and learn and to be an evolving project.

I also have to account for VMs in need of passthroughs and a (probably virtualized cause hobby and $$$) replication cluster for async RBD-mirroring, so nodes will be heterogeneous in config.

Second node I will order and build in the coming weeks, while 3rd node and 25GbE networking will happen “in 2025”. Until then I use my existing 10GBase-T home network I currently have. And proper HA isn’t really happening until then, because running 2 nodes on a single machine isn’t HA :wink:

So don’t expect network and Ceph latency tuning from this thread in the near term. Although my usual workload is IOPS and latency sensitive and I will certainly get that 4k BS IOD=1 write latency as low as possible.

edit: Shooting for min_size=2 with two-way replication on the NVMe and probably 2+1 or 4+2 EC on the HDDs.

2 Likes

Some updates on my progress:

  • Fans: Have arrived. Noctua 40mm are solid. 30% RPM (on board headers, can control via IPMI), NVMe running at 35-40°C under intense load. can’t hear much from them, HDDs next to them are way louder. I highly recommend the Noctua-swap for IcyDock products. 40mm Noctua aren’t cheap, but you get what you payed for.
    80mm cheapskate Be Quiet! fans…do their job. Nothing to write home about.

Only problem I’m facing is there isn’t sufficient airflow to reach the on-board Intel 10Gbit NIC and it overheats. No fan headers left and the NIC heatsink is sandwitched between hot air exhaust from CPU and the IO shield (basically behind the CPU if you look from front to back)…100% (2300) RPM on the 80mm won’t solve that and I doubt 3k RPM fans would be an improvement. Bad board layout. Had to disable the NIC in BIOS for the time being :frowning:
40mm fan on top of heatsink could solve that, but no fan header. self-made shroud to direct airflow around the CPU to the NIC heatsink could do it…or ripping out the IO shield and hope exhaust redirects more towards that heatsink.
5900x CPU runs at 70-80°C now. Not great, but stable even under sustained all-core Ceph+y-cruncher load. Occasional spikes into 82-83°C on 1-2 core full boost…“all within spec” as AMD likes to say.

  • Proxmox and Ceph, drives and Power:
    Got software and VMs up and running, also made a virtual Rocky Linux test cluster with one NVMe as passthrough per VM. Substantial improvement in performance. I’ve seen as much as 6GB/s sequential reads and 40k write IOPS with all defaults and no tweaks on anything.
    Did some power tweaking and I’m now at 57W-115W depending on load.
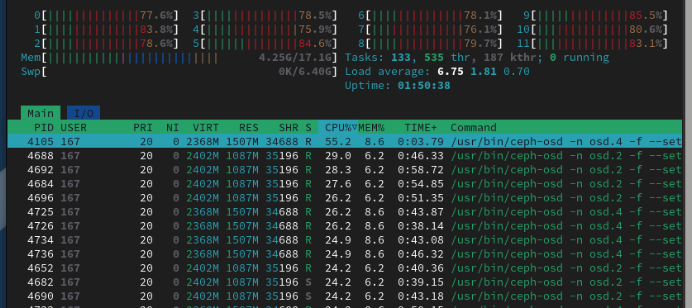
    On full sequential write workload, Ceph uses 2-4 full threads per NVMe (load average was up to 4.6 with 8 assigned cores). Insanity :smiley:
    I have block storage (RBD) up and running on my workstation, but that 1Gbit network is a huge bottleneck atm. But doesn’t feel less snappy than my SMB share from TrueNAS (using Dolphin) Time to get 25GbE earlier than intended.

All just some VMs atm, so no real latency between nodes. But also less CPU horsepower and drives. Ceph scales with the amount of nodes and OSDs (drives) after all. Will be interesting to see how numbers change with more bare metal but also more network latency. But I think I can break the 10GB/s barrier (at the client) easily with 3 nodes, IOPS will be a different beast.

The real difference is the PLP the U.3 have. Allows for fast sync (Ceph syncs everything)/always). I made a test cluster before with passthrough of consumer NVMe drives…I got 100-300 IOPS. Now I get 40k. At least that’s more than ZFS, because the drop of bitterness with Ceph is…you can’t beat ZFS on single user Random IO performance with a cluster, no matter what.

  • Future plans: Haven’t decided on board and CPU yet. But will be a 2U pure I/O-machine (4xU3+2xHDD), EPYC4005 series just got released…found a nice cheap AsRock Rack board (without overheating on-board NICs :wink: ). Will decide within 2 weeks on what exactly is the best for the stuff I want.
    And 3rd Node will be 4U cause I need some space and slots for AI, GPU, more HDD bays and stuff…probably low-spec EPYC Siena. I want smart home, inferencing, tinkering stuff with AI at some point, and maybe some Gaming VM, but not now. So this stuff is optional atm. Priority is getting stuff working for everyday use.

edit: Oh and @homeserver78 I enabled AER in BIOS and Proxmox throws an internal error on NVMe device passthroughs along with kernel messages in syslog. VMs won’t start at all. Disabling AER will solve this. It obviously won’t solve the errors. Not sure what to do. Runs smooth with AER disabled. Ignorance is strength?

2 Likes

I guess you can either troubleshoot it or ignore it? :slight_smile: Sorry, I don’t know what else to say! lol

I actually bought the wrong fans! I ordered A4x20 FLX instead of the PWM variant. So I reconnected the 40mm fans to the IcyDock Backplane with the low-noise adapter. If you can’t control the fan speed, it really doesn’t matter where you plug them in :slight_smile:
Also allowed me to use a spare 40mm fan on the (now) free header, to cool the on-board NIC. I’m back to 10Gbit networking again.

I set up VMs and containers for everyday use and my desktop and other stuff now has access to CephFS and block devices.

  • Benchmarks:
    Did some dolphin and fio stuff with 10G networking, measured at my desktop mounting a ext4 formatted RBD (ceph block device, like iSCSI LUN):
    Sequential writes: solid 1.1GiB/s
    Sequential reads: 850MiB/s (not sure why yet), folders with 50k files drop down to ~350MiB/s
    random 4k reads QD=1 (fio) = 1.8k IOPS
    same with 4k random writes QD=1 (fio) = 800 IOPS

Doesn’t look too shabby by Ceph/Cluster standards. Using all defaults, so there still are many best-practice parameters not touched yet.

Oh and be careful with intense random writes, Ceph will totally take all your CPU cycles. fio flags were16 threads and QD=32, results in this kind of VM utilization and 6k IOPS (12 cores, 2x NVMe to feed):
ceph12core

I narrowed down my shopping list now.

  • Build and Parts for 2nd Node:
    • CPU: Ryzen 7900 (king of threads/€? and 65W TDP requirement)
    • Board: AsRock Rack EPYC4000D4U (Made a thread about it,looks like it’s the best that fits)
    • 2x Micron 32GB ECC UDIMM
    • Noctua LH-L9x65 CPU cooler
    • Silverstone RM203-502
    • Be Quiet Dark Power 13 750W Titanium PSU
    • IcyDock 4xU.3 bay + 2x MCIO8i → OCulink cables
    • ConnectX-4 25Gbit NIC

Along with 2xHDD I have (really have to fully migrate my ZFS pool before doing that, too lazy) and I probably order two more U.3 and the fans needed.

Feel free to comment on parts and build, always good to hear from other angles/perspectives. Intention was high-performance NVMe Ceph + headroom for virtualization via Proxmox while keeping costs and power bill low for this kind of platform.

Still not full HA and I will still have to run a Rocky VM for Ceph.

Transitioning to SFP and 25Gbit is another matter I have to face (and pay for) at some point. DACs and connecting the nodes is the least problem there. (Mikrotik) Switch and 2x >3m optical cables might be required.

I ignore it for the time being. Particularly because the drives won’t see passthrough in the long term and remain bare metal. Scrubs so far were all fine…so there is no rampant data corruption by jank cabling going on. But I keep monitoring this.

1 Like

Started ordering stuff…

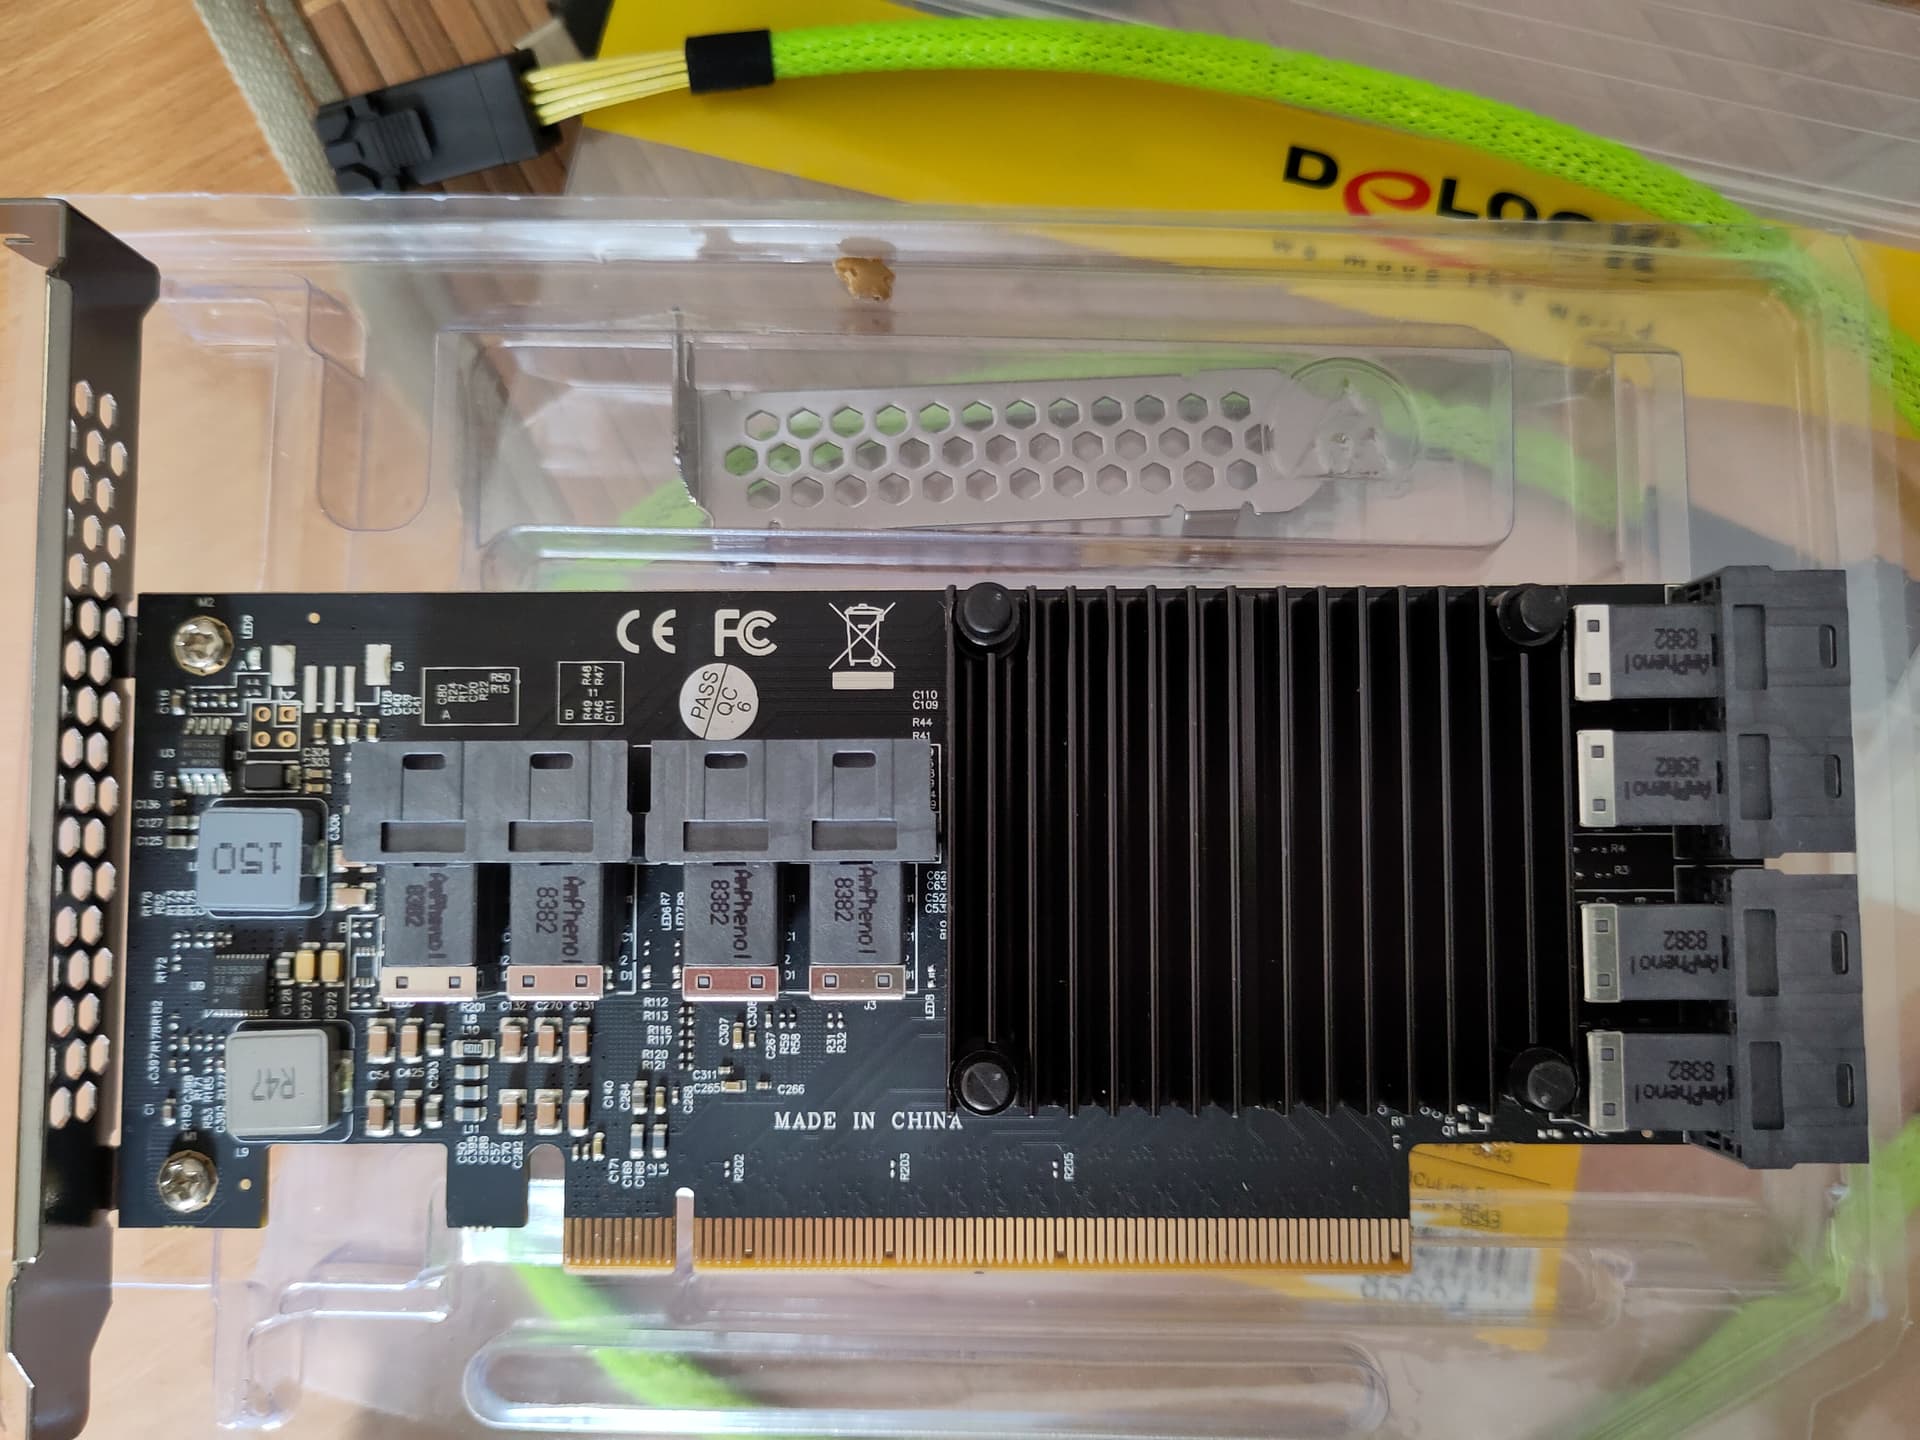
With the anticipated 25Gbit Networking, I had to get a PCIe3 PLX switch card to use with one x8 slot alongside the PCIe3 x8 NIC that’s coming. x16 bifurcation card just doesn’t work that well if you need 8 lanes for a NIC too.
That x8/x8 MUX on my board really was worth the money and comes in handy now.

Will tinker a bit tomorrow and if everything works as intended, I can use the MCIO stuff I previously had for the new node. But with the tall- AND low-profile bracket, it certainly won’t fail because I miss the bracket (SCNR @martona)

Really nice looking black PCB…too bad I won’t see it too often. And I like the holed-bracket to still retain airflow. Just doesn’t make sense with a full steel bracket, blocking air flow that’s passing just over that passive heatsink anyway.

1 Like

Nice!

That looks like a baby version of this bad boy:

No, that’s just a dumb adapter using BIOS bifurcation, albeit with some special Retimer magic. I had this before, but with just 8 lanes and 4+ NVMe waiting for connection, you need a PCIe/Packet switch. And this stuff is really expensive for Gen4 and 5, like 10x expensive.

Yeah, so is the one I linked - it’s handmade German engineering for 240 euros, no switch included. It’s like yours, just PCIe 5 and configurable lane layout.

Broadcom having a monopoly on these switches means ridiculous prices (+$800) for dogshit tech (+40W).

No (again). The card you linked is a PCIe retimer: 16 lanes in, 16 lanes out, requires bifurcation support. Exard3k’s card is a PCIe switch: (up to) 16 lanes in, 32 lanes out, does not use bifurcation. They are not the same.

1 Like

Kinda glad I came here to check out some other CEPH builds. Glad I am not the only one that uses it.

Are you using NVME for cache or no? Also what made you chose CEPH over ZFS, BTTRFS ect?

I currently have one myself and I am trying to get away from my 3 dual C612 servers that are running CEPH also over 10GBE. I am not mad at it by any stretch, but deff looking to lessen the footprint a bit for sure. I use a SMB gateway for mine that is open (I put steam games and video files and sometimes music for DJing on mine).

*** DISCLAIMER ***

  • I ORDERED STUFF; EXPECT NEXT Pictures in a week, the damn 80mm Noctua/BeQuiet fans weren’t in stock or were EOL!

I don’t have HDDs in use for Ceph OSDs atm. First, because my ZFS pool is still on 4 of them, so I don’t use DB/WAL. Until I’m fully confident in Ceph and my setup is (mostly) complete, I keep using my ZFS pool. ZFS just works and I can always rely on it. The HDDs may end up as a RBD/CephFS mirror as a backup. Or just OSDs for special HDD pools for bulk data. Not decided on that yet. But certainly with an SSD for DB/WAL disk to speed things up. SLOG and special vdev for metadata in ZFS is just too good to not use it. And DB/WAL is the Ceph equivalent of that. “Free” IOPS :slight_smile:

I use all of them and will continue to do so. I think they all have their special use case. For desktop, I prefer BTRFS. Proxmox runs on ZFS and RBDs. Laptop runs ZFS (Ubuntu).
I don’t think you can beat ZFS on a single server setup. But you can’t cluster ZFS and it isn’t designed for it. That’s where Ceph comes into play.

Ceph is the new kid in the family and I’m still learning and tinkering. But so far it’s been a blast to work with. ZFS can be a deep rabbit hole, but Ceph is a cluster of rabbit holes.

I found Ceph when browsing SUSE enterprise stuff, particularly digging into Rancher (ironically they discontinued Ceph, probably because RedHat/IBM shifting the landscape and ecosystem).
Then checked YT and Ceph documentation. And a month after that I wanted to build a 3-node cluster. Even coming from a ZFS “background”, Ceph has a lot going for it and shares many of the great magic things we love in ZFS. But also offers so much more, but also sacrifices a lot I’m so used to with ZFS.
I miss superfast compression, IOPS and ARC, ARC and ARC again…I knew this beforehand. You can’t compete with ZFS on performance. But with modern NVMe drives, Ceph is surprisingly fast. Enterprise NVMe are the main storage for the cluster. Fate of HDDs, see above.

And I still use a single server with VMs to virtualize a cluster. Next week the second node will be assembled. 12 more cores, 80GB/s more memory bandwidth and 3 more OSDs.

But I already setup all my block and file storage for my home network. It’s not ZFS, but it ain’t slow either. I’m certainly not disappointed. But those Enterprise NVMe aren’t cheap either.

So far, I just used RBD and CephFS as I only have Linux machines running at home. Mounting the stuff is just as easy as iSCSI and SMB.

Gas-guzzling old Xeons?..sturdy, but expensive to run. I decided to go with 65W TDP consumer CPU platform to keep power consumption low, while also having enough lanes for several (Enterprise with PLP) NVMe and HDDs.
But I’m sure your Xeons can handle a couple of HDD OSDs just fine. Writing to NVMes at NVMe speed is where the CPU is melting in Ceph. Even my 12-core Ryzen will go nuts on writes. Ceph likes CPU time, and will use all the cores you throw at it when you write at high speeds :wink:

10GbE is a good thing. Ceph talks a lot and cluster communication and everything Ceph does needs bandwidth or latency. 10G is good to have. 1G is probably fine for the usual chatter, but the cluster probably falls apart and marks nodes or OSDs as OUT on a 1G network as soon as there are backfills or any other amount of load. I even had to change parameters for clock skew between nodes. Clusters hate high latencies.

Many others just consolidate their servers into a single new one. And with stuff like Minisforum MS-01 and Thunderbolt, you can build clusters for very cheap and low power.
But Ceph wants Enterprise drives with PLP, so this wasn’t my approach. M.2 Enterprise drives are mostly end of life or really expensive and MS-01 can only use 1x U.2 and only a 7mm height one.

I want this to be a performance-oriented NVMe cluster (by Ceph standards) that is not for tinkering and setting up, but for actual use for all my stuff (from VMs over filesharing to steam library and Kubernetes) and the things to come. And learning a lot of new stuff of course.

Ceph has a Windows driver so you can use CephFS in Windows too. Same for RBD. So iSCSI and SMB are only needed for devices that need it. Better to talk directly to the cluster instead of using a Gateway to translate stuff.

Will update here once DHL delivers the nice hardware I ordered. Will also post performance and general experience I encounter with used hardware and how I learn Ceph and get more stuff running.

Clusters were inaccessible to mainstream for a long time. Today, we can all do it. Even If it’s just 3x Raspberry Pis. It won’t be for everyone, but it’s damn amazing, fascinating and doesn’t have to be slow if you put thought (and money) into it.
But a single server is the most rational choice to make for a homelab. Cheaper, faster, less power.
5 Likes