I was up all night burning some GPU oil and cranked out a new Qwen3-235B-A22B 106.830 GiB (3.903 BPW) GGUF with exclusive ik_llama.cpp fork quants and announced the release of ubergarm/Qwen3-235B-A22B-mix-IQ3_K on r/LocalLLaMA.
This model is the perfect size to max out what is possible on a high end AM5 / LG 1700 gaming rig with 24GB VRAM and 2x48GB DDR5 DIMMs.
I benchmarked it on my 3090TI FE 24GB VRAM + AMD 9950X 96GB RAM home rig and was very happy with the speed across the entire 32k context length. The developer, ik, may be making improvements to how the ik_llama.cpp fork’s GQA (grouped query attention) FA (flash attention) implementation and speed up token generation even more.
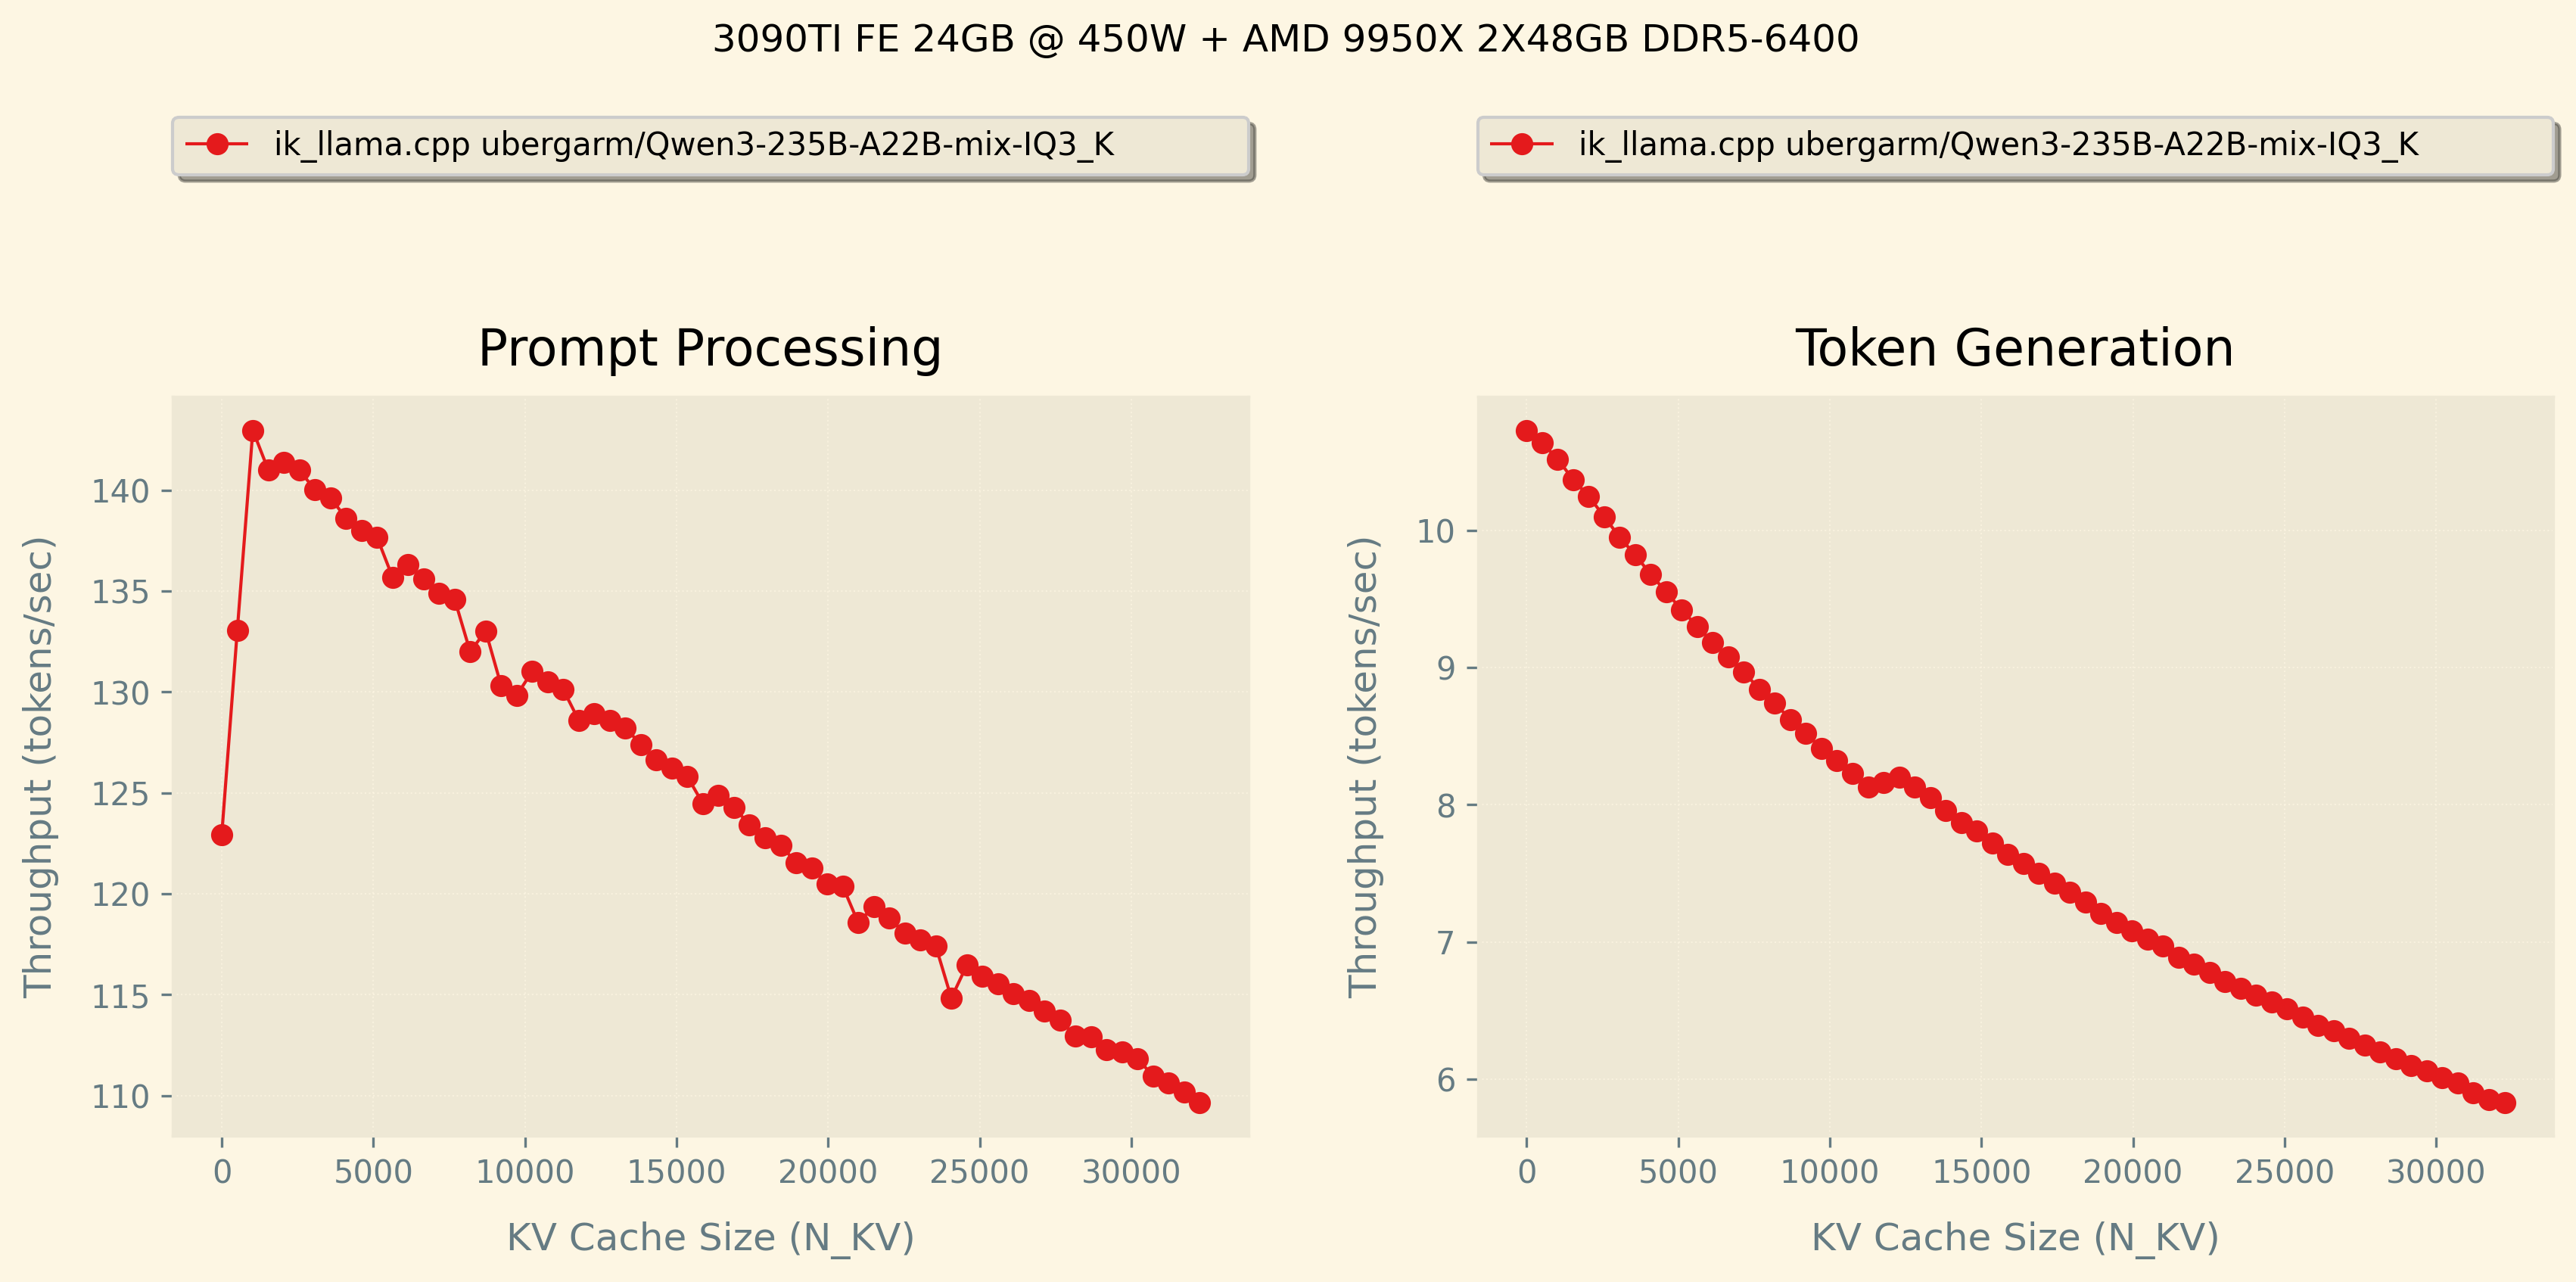
Note that this quant only works on ik_llama.cpp fork. If you want to run on mainline llama.cpp, ollama, lm studio, or koboldcpp etc then check out bartowski’s quants or unsloth or mradermacher. I’ve been working with bartowski to compare quantization quality across some of these models and still learning how best to do comparisons e.g. perplexity, kl-divergence, benchmarking, etc.
I’m amazed how fast this stuff is still moving and very excited to see what DeepSeek-R2 will bring!