For those who are looking to have a backup for disks with data that do not change often look into snapraid as secondary backup option.
2 Likes
Ok, the verdict is in!
Western Digital 4TB WD4000FYYZ , drives as well as 4TB Hitachi HUS724040ALE640 (Ultrastar 7K4000 , 3TB Hitachi HUA723030ALA641 7K3000, they all have low power cycle counts, however now after being used for a number of years in Chia Farm, they have (roughly) 65K to 105K Power-On Hours.
After a full read and full write surface test, the trend is clear.. Hitachi wins for long term reliability! Although I do not know the history of the drives, as I purchased them used.
Edit; did not have the drives perform an ‘Extended SMART test’. That is superior to chkdsk /r , or HDDDscan read test. On todo list.
SMART extended test: Check yo self before yo wreck yo self.
Software full read: Let me see you do it.
Very few of the Western digitals tested without bad sectors or pending bad sector, versus Hitachi the opposite.
Seagate Constellation 4TB drives are trash! Almost to all of them have bad sectors.
Very cool, thanks for sharing @wendell, I have a hodgepodge of used sata 3tb’s in my Aoostar nas. I pray to the storage gods that prices will normalize soon but I doubt that happens this year.
Your self-built case always makes me smile
The most heavy duty case ever. 
1 Like
Nice build. I ran into the same zfs issues with different size drives. My datahorder cluster is a 2 node Ceph cluster. It’s slow, but lets me use 10-28TB drives in one pool and auto expands and shrinks the pool when I add or remove drives. I only turn on the cluster now and then to dump data to it, so the power bill is not an issue with 2 R710 + PowerVaults and 30 drives.
So I experimented with the Eaton controlled outlet power strips. I put together a little script that wakes the server at midnight and shuts it down in 4 hours if no active transfer. So power usage while backups are running only is pretty cool for making it make more sense.
In that case wed average less than 1000 watts a day for daily backups or 2000ish for twice weekly backups
2 Likes
Same here. Only under HA and NodeRed. I change a switch to “Ceph On” in HA and a NodeRed flow kicks some smart plugs on, then pings each server and waits until each server comes online. Then it SSH into the monitor server and runs the commands to bring up the cluster.
Since this is my long term storage cluster, I manually copy files to it depending on what I want to store. Some backups go to it too for longer term storage.
Changing the HA switch to “Ceph Off” causes NodeRed to SSH into the monitor server and stop the cluster, then SSH into each server and shuts them down. Then kills the power at the smart plug.
2 Likes
This seems like a usecase for my old idea for my buddy. Have the source NAS run a cron job that reached out and power on the remote via IPMI, ping/health checks it once a min till it’s up, kicks off the replication, waits 15 min after its done, then issue a safe shutdown and the cycle repeats.
This sound like a very intelligent strategy to deploy. It can save a lot of money without impacting the end user. In 10 years I hope the follow up solution will be a mirrored pair of Kioxia LC9 246 TB drives consuming 25 watt each bought at 5 euro/TB.
I do not fully understand these numbers. Are you staying under 1000 Wh/day? Is it 1000 watts under the hours the server is powered on?
I see the premise of this video in the context that storage has had a sharp increase in cost. Now we need to help find new ways for people to keep affording this hobby. When the peasants can’t afford bread and are starving, it is not helpful to advise them to eat cake.
2 Likes
Yeah it’s really not “stressed” even if the nic is fully saturated for the time it takes to backup.
What confuses me is where do you get old drives like these? Used to be I could get pretty decent deals on refurbished drives of this class on Amazon or eBay and co, but now those are just gone. The same 6TB drives I got for $55 each years ago cost more than they used to. I was going to go all out on 6TB and get like 8 old HGST drives for relatively cheap but they just can’t be found for good prices anymore and idk what to do.
Wendell showed in the video these drives came from old stock saved from years ago. Here’s where older home-labbers/data-hoarders have an advantage as they usually have a stack of old, no longer used drives stashed away from previous iterations of their storage pool(s).
1 Like
Na, I get that, I am just turbo jaded by my numbers vs what others complain about, similar for fan noise.
I would assume hoarding and/or retired project items that did not become hand-me-downs.
yep, I have a stash of 26 4T SAS disks from a proxmox ve + ceph 4 node PoC for home Prod and it was meh, so I took all the drives and stacked them in a room I don’t use, that and 8 960G? U.2 NVMes, 8 sata doms, some other asorted crap, I think I still have 20-24 samsung spinpoint 2TB drives from my very first FreeNAS build ~2008-2011 ish
Getting back to the video, what’s this “software stuff” (YouTube 18:05 mins) you (Wendell) talk about doing whereby you’re reading the whole file into memory and hence allowing the drive to spin down?
Somehow using a RAM drive to load and unload media files? Thx.
Thats part of ZFS and ARC, you may have to add a zfs tunable like vfs.zfs.l2arc_noprefetch iirc
```
By default the L2ARC does not attempt to cache prefetched/streaming workloads, on the assumption that most data of this type is sequential and the combined throughput of your pool disks exceeds the throughput of the L2ARC devices, and therefore, this workload is best left for the pool disks to serve. This is usually the case. If you believe otherwise (number of L2ARC devices X their max throughput > number of pool disks X their max throughput, or you are not doing large amounts of sequential access), then this can be toggled with the following sysctl:
vfs.zfs.l2arc_noprefetch
The default value of 1 does not allow caching of streaming and/or sequential workloads, and will not read from L2ARC when prefetching blocks. Switching it to 0 will allow prefetched/streaming reads to be cached, and may significantly improve performance if you are storing many small files in a large directory hierarchy (since many metadata blocks are read via the prefetcher and would ordinarily always be read from pool disks).
The default throttling of loading the L2ARC device is 8 Mbytes/sec, on the assumption that the L2ARC is warming up from a random read workload from spinning disks, for which 8 Mbytes/sec is usually more than the spinning disks can provide. For example, at a 4 Kbyte I/O size, this is 2048 random disk IOPS, which may take at least 20 pool disks to drive. Should the L2ARC throttling be increased from 8 Mbytes, it would make no difference in many configurations, which cannot provide more random IOPS. The downside of increasing the throttling is CPU consumption: the L2ARC periodically scans the ARC to find buffers to cache, based on the throttling size. If you increase the throttling but the pool disks cannot keep up, you burn CPU needlessly. In extreme cases of tuning, this can consume an entire CPU for the ARC scan.
```
https://wiki.freebsd.org/ZFSTuningGuide#:~:text=vfs.zfs.l2arc_noprefetch

For a lot, a smaller disk array might suit e.g. this EMC DAE Disk Array Expansion SAS KTN-STL3. This is more like $100. I use mine as a long term archive for CFD data which is only occasionally acessed when im actively working on a paper . This data is backed up on LTO4 . My archive (3TB and 6TB SAS) is just plain JBOD and its kept switched off unless its being accessed which preserves disk life and costs.
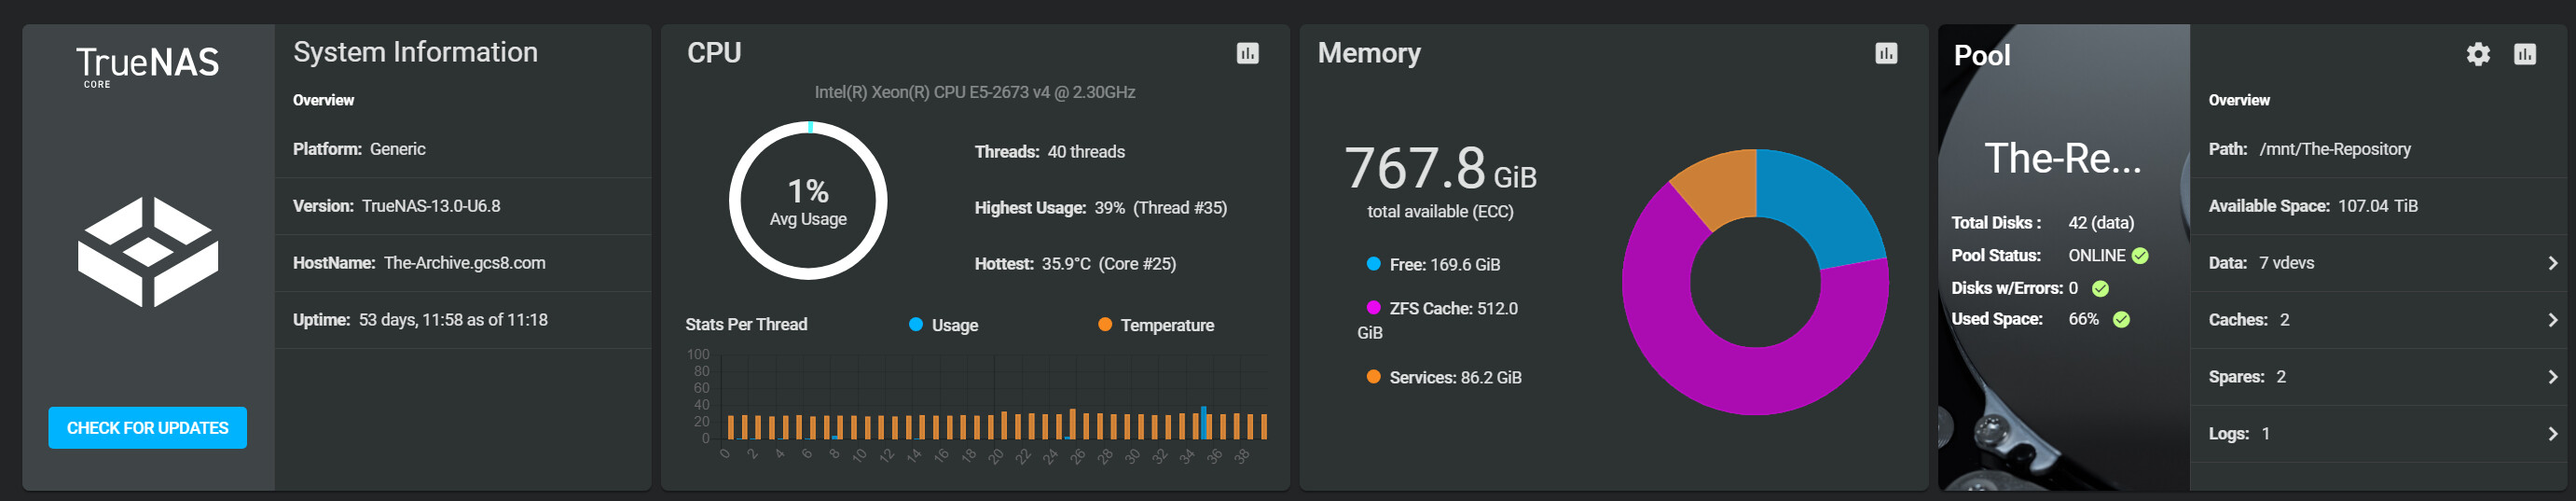
is that 48GB memory on a 250TB+ pool?