Looking to upgrade my homelab for agentic use. Want to get the biggest model I can fit to practically replace everything I use Claude for right now, which tbh, isn’t much.
Currently, the Homelab is pretty weak in this regard. It’s got a i7-7700, 32GB of DDR4 and a 10GB 3080. From cursory research, this will land me in the ~25b range, at best. I want to push this to 35b+ comfortably
Budget: $700
What upgrade should I get to push my model capabilities to the limit?
For home-lab use I’d be looking for anything Nvidia or AMD in the 16-24GB VRAM size.
24 GB if possible as that seems to be where a bunch of reasonably powerful models have targeted due to the 3090 being the previous gold standard for home user/hobbyist LLM use.
Nvidia preferred but don’t sleep on AMD if it is just for personal use. My 7900XTX has been great so far, caveat being that you need to be running a really current/rolling release Linux distribution and software for decent Vulkan LLM support.
If speed isn’t an issue (e.g., non-interactive agentic tool use), you can also run on CPU but its at the point now where you may be able to find a second-hand GPU with 24 GB for less money than the additional DRAM would cost for your machine.
If you’re considering multiple cards -VRAM Bandwidth is king, for same cost try to get the card with the most memory bandwidth.
That said, you can probably get started with some of the new smaller models:
gamma4:12b-it-qat : 7.2 GB
ornith:9b : 5.6 GB
will both fit in your current GPU and whilst not claude level by any stretch will at least let you experiment without something totally trash until you get more capable hardware.
I think the best model you can realistically run at good enough speed for agentic stuff is Qwen3.8 27b. So the goal here is running that at the best quant + context you can muster.
You didn’t mention how many PCIe slots you have but for the purpose of this recommendation they need to run at at least 8x and I’m going to assume you have two or three. I’m also assuming your PSU can handle whatever you buy or isn’t part of the budget.
For the simplest path here I would say get a used 20gb 3080. It will pair well with your existing card and you should be able to run a Q6-ish quant of Qwen3.8 27b with decent context. IMO this is your best option.
Someone mentioned a 3090 but the extra 4gb isn’t worth the premium at the moment. If you want to stretch your budget like this I would instead try selling your current 10gb 3080 and buying a pair of 20gb 3080s. Or maybe even a pair of V100s.
Also mentioned a 32gb V100 is also a reasonable choice but it’s not going to pair super well with your 3080 and being out of support you’re committing to some tinkering and running linux. On the other hand it’s the most VRAM you’re going to get for $700 and even if it bottlenecks your 3080 a bit we’re now talking Q8 full context Qwen3.8 27b.
Sidenote
Never quantize KV cache, it isn’t worth the degradation. Either use less context with stuff like compaction or go to a lower quant model.
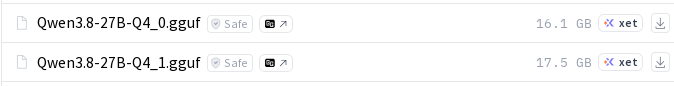
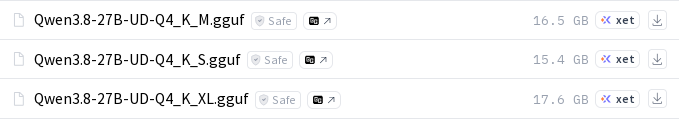
The Unsloth Q4 dynamic quantized 27B is 19 gigs. A 20 gig 3080 literally would have one gigabyte left and that’s assuming you aren’t going to use vision. So you would need a pair of the cards at minimum and then you’d always have all of your KV cache on another GPU which means you’d always be bottlenecked by the PCIe bandwidth.
You really need 24 gigs minimum if you want to run any smarter model that can do a gentic coding effectively. There are a few MoE projects that have done pretty well when it comes to web development stuff but you will still be compromising on speed because you would not be able to fit the entire thing into any one cards video memory.
I recently took a look at the 20 Gig 3080s myself, and I just don’t think they are worth it. Buying the AMD V620 is a much better purchase at around the same price, because you’re getting 32 gigs of video memory, and even though the performance is not as high as the 3080, you are able to run way more models, and you can definitely buy two of them for $1,000 and really expand out the context, even again, at the cost of your PCI-E bandwidth.
Also, it’s important to point out that a V100 doesn’t even support flash attention and has limited support for speculative decoding, especially with the new D flash and such. Additionally, you are not running a Q8 version of the 27B model in 32 gigs of video memory, especially with full context. You won’t even fit a proper Q8 model in 32 gigs. You can fit it in 42 gigs, but not with full context. I have a W7900, and I cannot run a Q8 with full context. I can run a Q4 with full context, but not Q8.
Krasis allows you to run models larger than the VRAM you have at Q4 on Ampere gen Nvidia cards and later if you have enough system RAM to keep the quantised model in memory:
I’m not sure if you just missed it in both his and my post but he already has a 10gb 3080 and is spending an additional 700$. Meaning 30gb total.
Dflash with Deepseek V4 works fine on my M40s so… yeah.
No one ever said this.
So did you understand he had a 10gb card he was keeping the whole time or not? are you just attacking a strawman because I said you shouldn’t quantize KV cache?
Nobody is attacking any strawman nonsense . I’m not sure where you got your pants at a bunch here. But 30 total gigs of video memory isn’t enough to really do anything. And in the first place, you’re not going to run Q6 which is what was mentioned.
So, as a person who literally uses these models every single day, I’m pretty well aware of how much memory they use and their KV cache.
Even in Q4 you cannot run full context at 30GB total. 75k Context is like 9.8GB and MTP is 2.11GB.
He should have his current card modded to 20GB as well in order for it to be a useful setup.
considering your system ram limitations i think definitely aim for using qwen3.8-27B and work backwards from there - but you need to be able to have access to a fair bit of context imo 180k ++ with agentic workloads especially if you are using something like hermes which chews up a lot of context at the get-go (im sure a lot of people are ok with going lower but it is less set and forget the closer to 262k the better).
it might be worth seeing how the lower quants perform (i actually think the model quantizes pretty well) and calculating your minimum vram with that quant and 200-250k context. you might find you are actually after 40-48gb vram - then perhaps you might need a 2 step plan to get 2x 20gb gpus. it might involve selling or modding your 3080.
on my home server i use an rtx 3090 with 2x 5060ti’s (56gb vram) that allows Q6 max context (262k) and head room, at Q8 i think it was about 222k. I also tried a Q4 on my separate 7900xtx for a quick try and i think it was about 90k context at q8 KV cache. that might give a bit of an idea on the vram needs vs context.
a gpu is not needed, ai will infact run on your cpu… im game if anyone wants to play ai benchmarks on cpus, ai degeneration drag racing it will be called…
The UDQ4K XL is 19GB after you include the 1GB MMPROJ file for vision. So nice work in doing your best to try to make me look like I don’t know what I’m talking about, only to prove me correct.
Here’s the list of files, since you seem to not know how to read or do math. I know it’s hard for certain people, especially those who are so far behind others and really spend the time to put other people down and tell them that they don’t know what they’re doing, even when they’re trying to help out other people. So you can take this self-own and maybe think about your actions before you post again. Overall, the models that you linked prove me correct. Not only is the MMPROJ required in order to actually use all of the models’ capabilities, because all vision will be disabled without the additional 900 plus megabyte file, but to enable MTP requires another roughly two gigs of scratch space in VRAM. So when you boot the XL model, which is the one you actually want to use if you want full accuracy, you will be looking at essentially 21 gigs on model load before any work has been done.
Yes, but AI on a CPU is quite slow, especially because memory speeds are very low in comparison to that of GPUs. So even a slow GPU is faster than most fast CPUs. The only time that this is different is if you are talking about a EPYC server, especially dual CPUs with 16 channels of DDR4 or 12 channels DDR5, then the perspective changes a bit, but again, that’s not normal kind of hardware.
I mean, at no point does the OP say he needs vision and as he is asking to “push my model capabilities to the limit” including optional extra(s) on the largest quant seems… disingenuous? desperate? bad faith? All of the above?
And referring to the huggingface repo you explicitly reference first as “the models that you linked prove me correct” is interesting. It seems to belie that you don’t actually know these sizes as well as you proclaim.
Ultimately though I think the real issue here is a narc injury. You’ve made being an expert on LLMs part of your personality
so someone showing that your wrong is unacceptable. It explains all these personal attacks about how I can’t read or don’t know what I’m doing and why you’re still seething about it over a week later. You gotta let it go man. Being wrong about something in the fastest changing field of our time (maybe ever) isn’t a big deal.