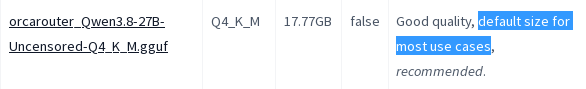
I just read your useless reply yesterday, as I haven’t been on the forum in a week. I saw how you really felt like you knew what you were talking about, even though you didn’t. If you want to push the model to the limits, you need one that actually is going to give you real responses. And you also want one that has good performance, so at 17.6 gigs plus two-ish gigs for MTP overhead, he’s already basically at 20 gigs even if he disables vision.
However, disabling vision is far from pushing it to the limit. It’s eliminating 50% of the model’s capabilities right off the bat. Want to analyze a PDF? You can’t. Want to take a look at an image? You can’t. Want to help translate a screenshot? You can’t. Want to have it look over some documents? You can’t. I mean, half of everything you do with a model like this would involve vision, especially when you get into the context of computer use bots like Open Claw needs vision. Plenty of accelerated applications require vision. So saying you’re pushing it to the limit and then not including vision. So you could save one extra gig on context on a model that already isn’t really efficient in terms of context, memory usage, pretty much a joke.
That’s just the reality. At 19+GB he can’t get any good size context out of it. Every smaller quant below that will have divergence, and you’re definitely not pushing it to the limit. Now he could run a Q2, i-matrix quant, and max out his whole context, but as far as actual usable performance to get the job done with the right answer, you don’t want to go under that XL quant.
It seems you’ve made trolling forums with not very useful information part of your personality. I suggest you get a new hobby.
You’ve convinced me so I formally apologize. And to be clear I was specifically wrong about:
-No one would ever forego MTP speed up for more context or a better quant.
-No one has a use case that doesn’t require vision so it’s not actually optional. The default llama-cpp webui can’t import PDFs as text and thinking back that time I vibe-coded some things in turnstone using DSv4 flash 0731 was probably just a day-dream.
-MCP for browsers is simply a myth and the only way to use a browser with an LLM is via vision + openclaw.
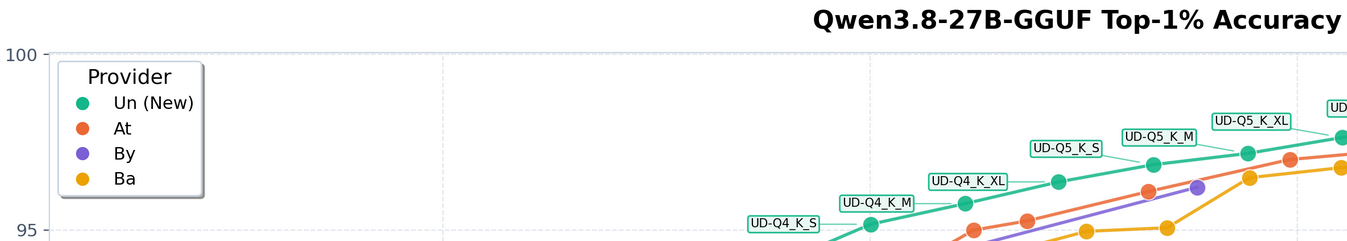
-You’re completely correct about the XL quant. Everyone knows there is a such precipitous drop in quality from Q4_K_XL to Q4_K_M such that Q4_K_M is unusable, as you can see here:
-I am functionally retarded. Unable to read, write, do basic arithmetic, write useful replies, keep up with new developments, etc.
-I am unable to follow a conversation thread for any amount of time. For example you say “he’s already basically at 20 gigs if he disabled vision” and “At 19+GB he can’t get any good size context out of it”. Yet literally none of the options discussed -that I can remember, at least- result in anywhere near 20gb of vram. So clearly I’ve lost the plot due to my many, many disabilities.
With all that off my chest (feels good!) I would like to again sincerely apologize for my failings and further offer any reparations your ego sees fit to impose upon me.
Thanks for admitting it. It is truly hard for people to admit their massive failures in every way, but it does seem like at least through the help of outside sources that you were able to grasp the context of this conversation now finally and realize how incorrect you were.
I do hope you apply the same logic and due diligence to future posts so that other people don’t have to read pointless diatribes about things that you don’t understand.
We should all be here to share knowledge and help each other, rather than have pointless arguments about things that don’t help the OP.
Neither of you were particularly respectful and I lost all fucks for this post the moment you two started a dick measuring contest. Sought help elsewhere… Even if you are right, no one wants to listen to someone talk to them the way you did and I am very surprised that @V100_guy even gave you a response, let alone an extremely mature one, after some of the things you said.
You could both stand to be more respectful and you could certainly try talking to people at their level instead of from a high horse. Not everyone knows everything and teaching from a position of condescension is just as bad as being wrong, if you ask me.
I think you could be a big positive influence on the LLM community as well. In particular I think you should talk to bartowski and tell him that Q4_K_M is unusable. I’d do it myself but I’m just a lowly worm, lacking any of your immense izzat.
Honestly, I would put almost the entire $700 into VRAM rather than upgrading the CPU/platform. A used RTX 3090 24GB would be my first choice if you can find one within budget. It’s a huge jump from the 3080’s 10GB and is enough to make 30–35B Q4 models genuinely practical.
Your i7-7700 and 32GB RAM aren’t ideal, but for inference the GPU memory is the bigger limitation. I would keep the current system for now, drop in the 3090, and upgrade the CPU/RAM later. Just make sure your PSU and case airflow can handle the 3090’s power draw.
I could, but there is no point. I just use Unsloth Dynamic Quants and so do most other people. Which is why they have taken over the downloads on HF by such a large margin. Because they deliver what other Quants don’t.
I have a stupid question: why not an Intel B60? they can be had for $650 new. I know the a 3090 would be significantly faster but they seem to be going for at least $1,000 and they’re 5 years old. If it’s for a single user, running llama.cpp it should be plenty fast? also way lower power usage.
To be clear I think there’s something I’m missing here as to why it’s not a good option and I want someone to tell me why I’m wrong
The age of a gaming GPU is irrelevant, it hasn’t been ragged 24/7 in an overheated server for 5 years, it’s overwhelmingly likely to have been sat in an air-conditioned room, idled for most of its life and under load for 10hrs/week; the 3090 is fundamentally better in every respect compared with the B60. Software support, ecosystem support, speed…there isn’t a single respect in which the B60 wins. And then you’ve got the fact that their software support for Arc only extends as far as the next generation’s release (ie they abandoned Alchemist the second they released Battlemage) - their track record is terrible, made worse by the fact that it’s such a fast-moving sector.
If $650 is your budget, then you’d probably even be better off getting a V100 32GB or MI50.
The OP says he already has a 3080 10gb and wants to spend 700$. If he doesn’t get an nvidia card he’s then he’s mixing manufacturers which is a headache. That’s one of the reasons I suggested a 20gb 3080.
I doubt he’s reading this thread anymore anyway for… some reason.
Just as a thought experiment, because I’ve had a former coworker ask me a similar question for a $500-800 range, I’m leaning toward telling him a 5060 ti 16gb (if you can still find it in that range) is probably the best for a beginner, an RTX 3080 20gb mod if you’re feeling brave and ok with rolling the dice on it, or a V100 if they’re good with CUDA 13 leaving them behind. Is this a fair assessment (at least as of October 2026)?
Look at the Intel ARC B60 as well, it’s $650-750 so just at the top of that range. I haven’t used one myself so I can’t personally vouch for it. I do have two 5060 Tis at work though, so I can confirm that 16GB VRAM is nice, but for a single card 24GB would just be so much nicer. You could fit a bigger quant of Qwen3.8-27B at full context window, which is about the best local model you can get right now. And if you have enough system RAM then the trimmed coder version (non-coding weights surgically removed) of Qwen3.8-Flash-Next can run on a 24GB card with Strata: https://stratallm.org/. I’m running the 3-bit quant of the full model on ~60GB RAM and the two 5060 Tis (so 32GB VRAM), it’s really nice. Not only smarter than the 27B dense, it actually runs way faster too.
I’d say that depends on what they already have; There is not a great deal anything with less than 32GB RAM could do in the sense of SOTA open-weight LLMs. On the other hand, recent Intel and AMD iGPUs have substantial support in llama.cpp and its forks and derivatives, and already give usable performance.
A recent GPU with at least 16GB VRAM from any of the big three should at least speed up prompt processing and give usable if slow token generation performance with RAM offload, and there are specialized quantizations which fit a 27B model entirely into that 16GB, so long as that same GPU does not have to drive the display at the same time, with what is claimed to be little performance loss.