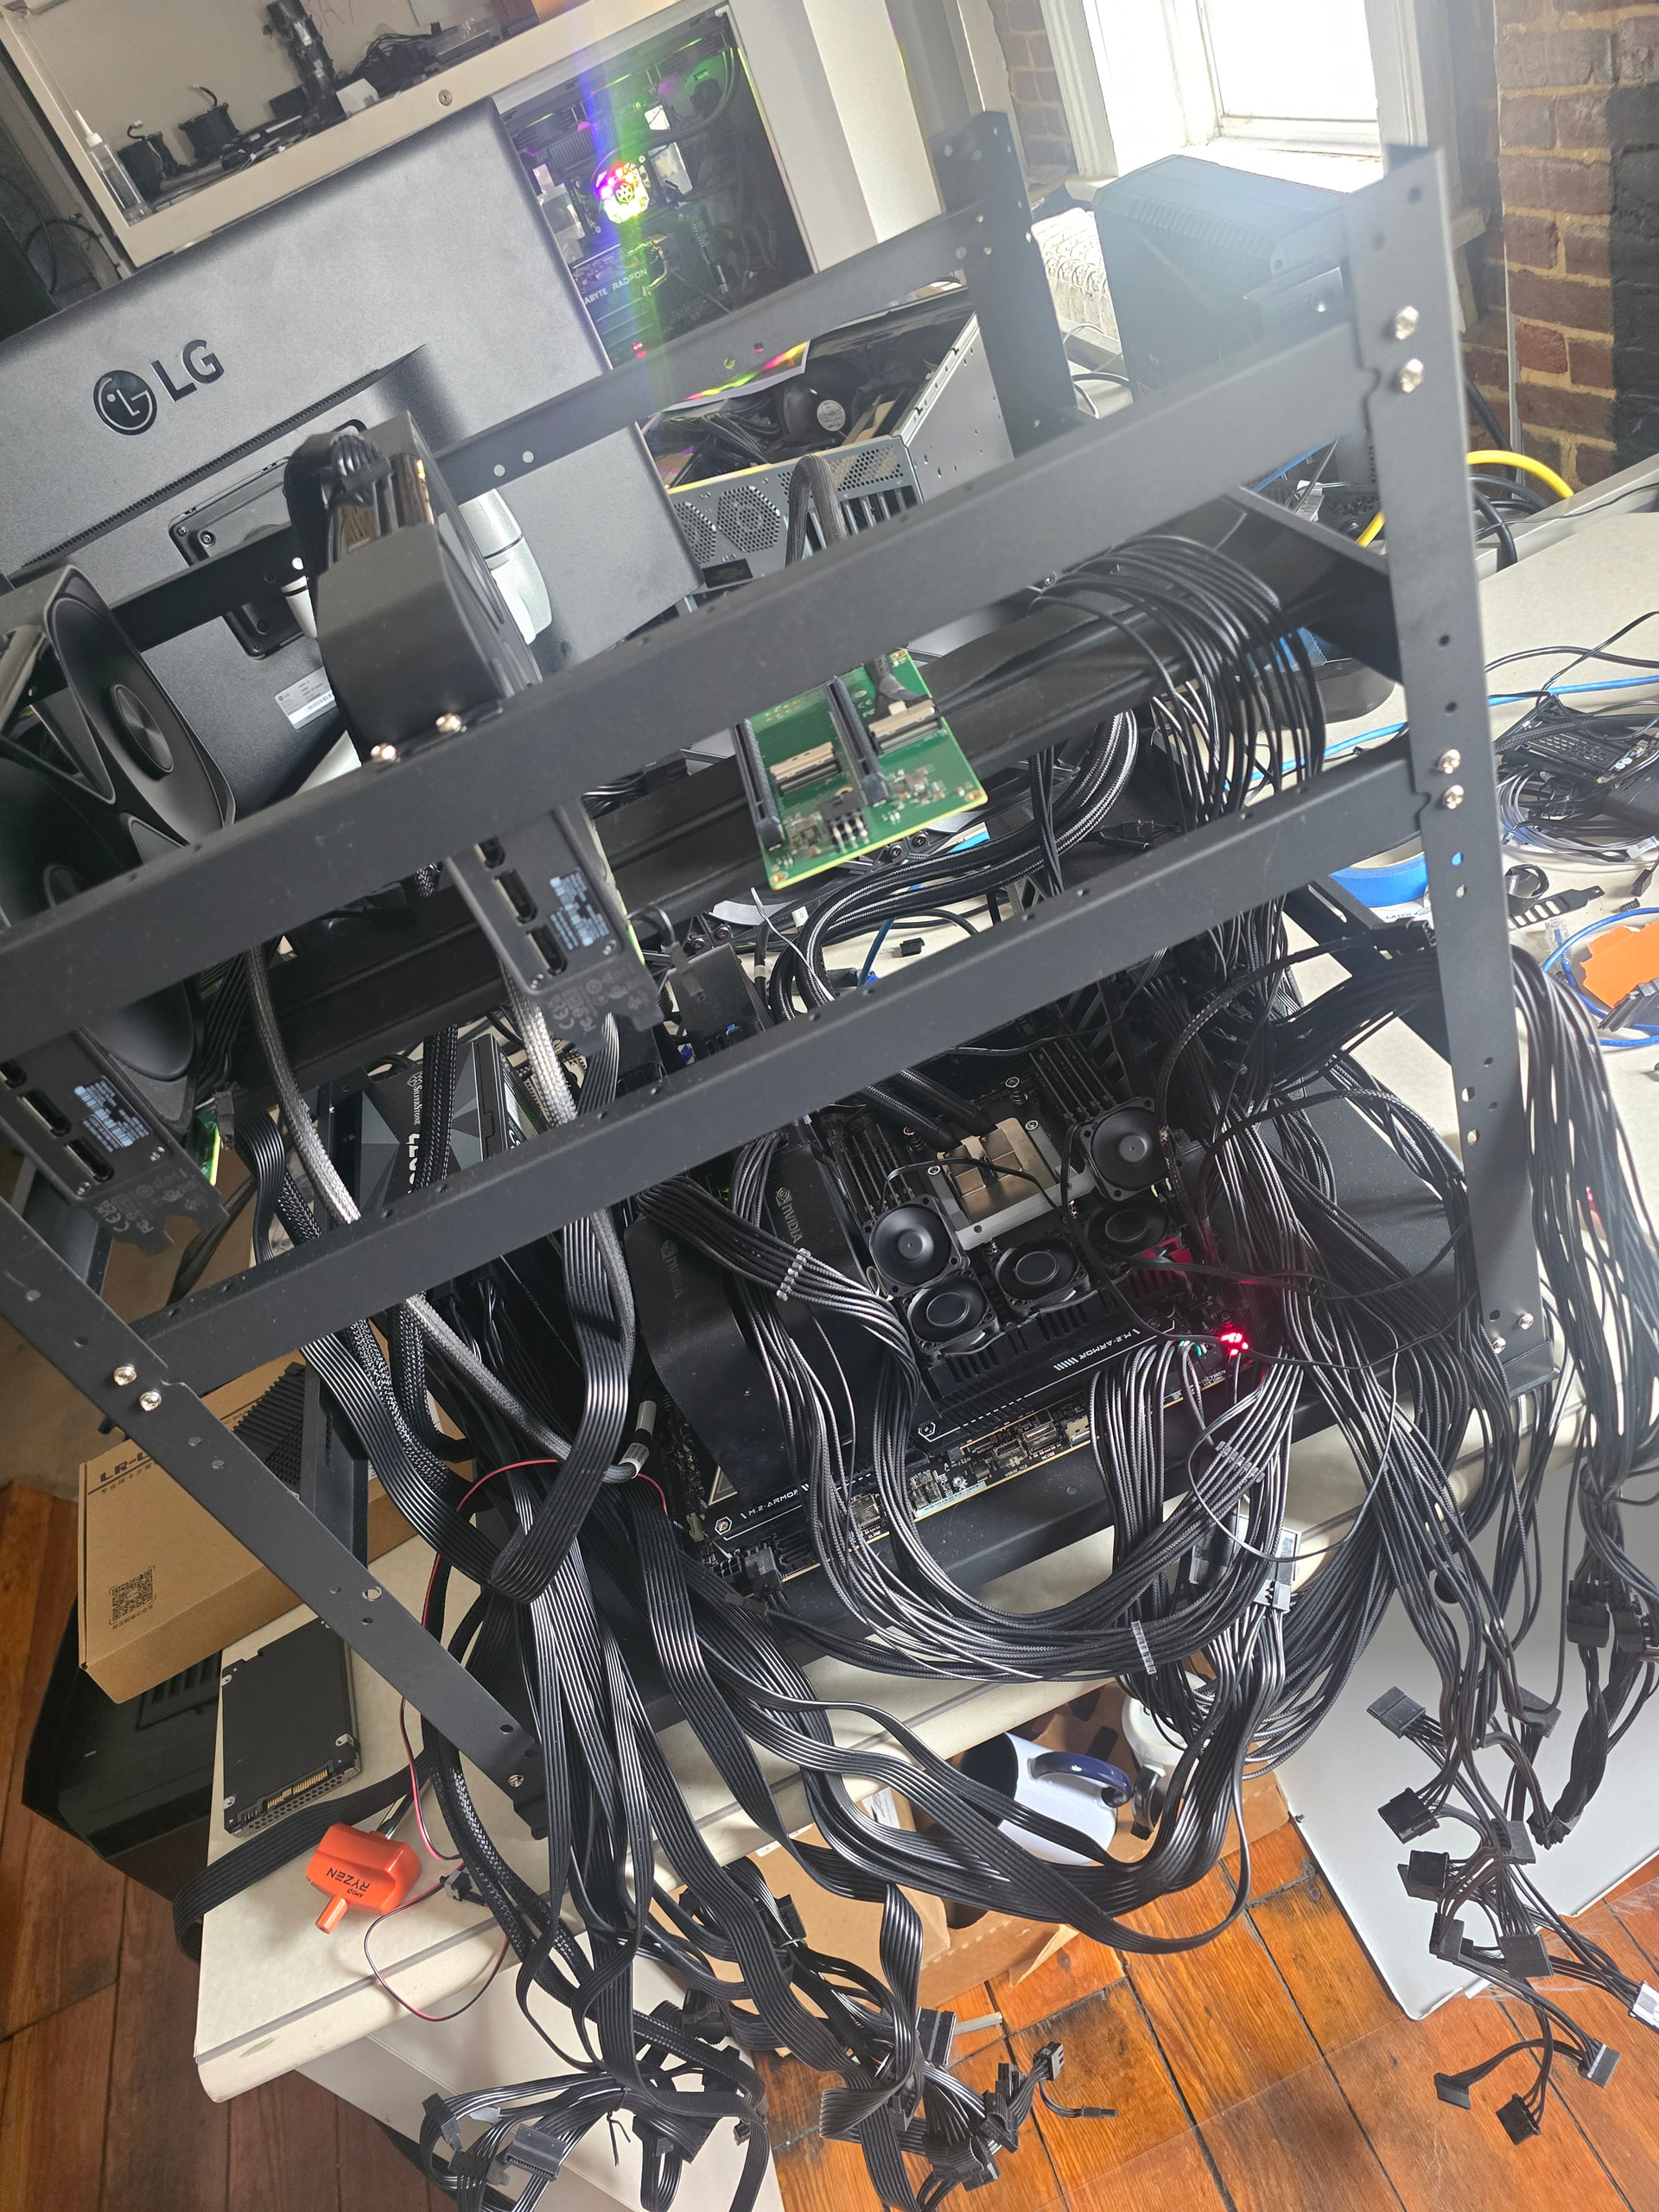
Hi all, first post here. I’m looking for help diagnosing a PCIe platform/link stability issue on WRX90/TR5 with dual GPUs. This is idle-only and appears correlated with links sitting at Gen1 x16 at idle. Devices come back after reboot (not permanently missing).
Platform
OS: Ubuntu 24.04.4 LTS
Kernel: 6.17.0-14-generic
CPU: AMD Ryzen Threadripper PRO 9985WX (64C/128T)
Motherboard: ASUS Pro WS WRX90E-SAGE SE (Rev 1.xx)
BIOS: 1317 (dated 02/03/2026), issue also occurred on 1203
PSU2 (Seasonic Prime TX-1600): both GPUs via native 12V-2x6
PSUs synced via ADD2PSU
Different branch circuits for PSU1/PSU2
Symptom summary
Happens only at idle (not observed under load so far)
GPUs at idle show:
GPU0: P8, Gen1 x16 (max Gen5)
GPU1: P8, Gen1 x16 (max Gen5)
After event, one or both GPUs can fall off bus; reboot restores normal enumeration
Repro history (timestamps local, MST -07:00)
2026-02-16 12:30:08: DPC on 20:01.1, then Xid 79 on GPU 21 (line 0)
2026-02-21 15:09:23: DPC on 20:01.1, then Xid 79 on GPU 21 (line 0)
2026-02-22 13:43:42: DPC on both 10:01.1 + 20:01.1, then Xid 79 on both GPUs (11 (line 0) + 21 (line 0)), then Xid 154 on both, then failed retrain/recovery on both root ports
No change in link policy/state at the root port after switching default -> performance:
LnkCtl: ASPM Disabled (before and after)
L1SubCtl1: PCI-PM_L1.2- PCI-PM_L1.1- ASPM_L1.2- ASPM_L1.1- (before and after)
I also see this pattern on both GPU root ports / endpoints:
Root ports (10:01.1, 20:01.1): ASPM disabled
GPUs (11:00.0, 21:00.0): ASPM disabled
Links currently at 2.5GT/s x16 (downgraded)
Takeaway
At least on this platform/firmware combo, ASPM policy changes are not moving these links.
So the idle Gen1/2.5GT/s downshift + DPC/AER/Xid79 issue appears independent of ASPM toggles.
Was experiencing very similar issues with latest Win10: multiple PCIe AER errors (only at boot) on my 4090 card. I even had the GPU “fall of the bus” at least once and the board got stuck at QCode 79 for a day before I shook it loose (not sure how except through sheer determination).
Upgrade to Win11 25H2 corrected all errors… never happened again. All BIOS versions exhibited the same issue (and I started on initial release back in Jan 2025) which led me to conclude it was software/OS related.
Ubuntu 24 is older than TR PRO 7000-series. My best recommendation is moving to Ubuntu 26.04 and seeing what shakes out. That’s about all I can offer.
Yes.
Advanced → Onboard Devices Configuration → PCIE Link Speed → PCIE Speed Control: Disabled (Control the PCIE speed mode for power optimization. This option allows user to choose between an optimized power consumption and performance-oriented power settings of a PCIe or M.2 slot.)
Alternatively, you can enable this (I believe it is disabled by default) and manually set the desired link speed minimum (GEN4, GEN5, etc.) for the PCIe slots and/or M.2 slots individually. Consult the manual to identify the correct PCIe slots for installed cards and set them to GEN5 for testing.
Also, my understanding is this should do the same (except managed by CPU SMU):
Advanced → AMD CBS → SMU Common Options →
Pcie Speed Controller: Enabled
PCIE Speed PMM Control: Static Target Link Speed (GEN5)
possible residue/film contamination (I vape; possible PG/VG deposition) on slot/contacts
I also changed BIOS Power Profile Selection to Maximum I/O Performance Mode, but based on behavior I think that is less likely to be the primary fix versus contact cleaning.
Preventive actions taken:
ordered PCIe male/female dust guards/covers to reduce future contamination risk and an extra batch of 99% IPA patches.
Given prior symptoms (BadTLP correctable bursts escalating to DPC/Xid79), this now looks consistent with intermittent contact/signal-integrity degradation rather than a persistent firmware/driver defect. In otherwards, it was my own damn fault, lol.
I’ll continue monitoring, but at this point the issue appears resolved.
Wendell, where did you get that open air case? I need one myself but having a hard time finding a decent open case. That is a beast of a setup, I thought my setup was a monster, lol
For your awareness, this setting simply prioritizes SOC over cores when running up against a processor power budget limit. If you’ve enabled PBO advanced on this board and unlocked to board limits this will never be a concern. High Performance Mode (prioritizes cores over SOC) and Maximum I/O Performance Mode will be the same in all regards.
Just for any future users who might stumble across this thread and have the same problem, the typical troubleshooting steps in order are:
Clean pcie ports, ensure cards are well seated.
Reinstall drivers.
If it’s enterprise hardware under warranty and it’s important skip the rest and get a replacement.
Ensure power cables are well seated and your PSU isn’t faulty.
Roll back drivers.
Disable ASPM
Take apart GPU, ensure there are no suspicious looking soldering issues with the GPU die (sounds odd but a surprising common issue) and VRMs & it has solid contact with the cooler
I run into this multiple times per day on clusters with tens of thousands of GPUs. We immediately swap out the node but these are the required steps before it’s sent back to the manufacturer. It’s less frequent with SXM modules but still pops up. Unless the GPU is failing these almost always fix it.
I wonder about your PSU configuration. Have you connected the MB to both PSUs, as specified by ASUS? I don’t know much about your ADD2PSU sync, but the GPUs are still connected to PSU1 via the PCIe bus (and can draw some 75W from there). In any case, the “galvanic connection” seems unclear to me, and ASUS says that you absolutely need two identical power supplies for a dual PSU connection…
I ensured that the power is on the same leg –common ground–. PSU1 powers the MOBO while PSU2 powers the GPU’s. I do not use the link cable as I’m managing the power myself rather than sending them both through the MOBO. With one GPU I’m 100% stable.
I’m still getting the errors and working with ASUS support –more than likely RMA–.
P.S.
I dropped the power of the GPUs down to 300 each and ran on a single 1600 PSU, same issues.
I’m currently in the process of opening an RMA. At this point I have worked through the standard troubleshooting steps, including cleaning and reseating the PCIe slots/cards, reinstalling and testing drivers, checking power seating and PSU behavior, disabling ASPM-related behavior, and collecting both pre-reboot and post-reboot failure evidence. The only step I have not performed is disassembling the GPU itself, since the cards are still under warranty.
Based on the logs and repeated captures, I have narrowed this down to a PCIe root-complex / slot-path / link-integrity issue rather than a simple software-only problem. The clearest captured events show root-port DPC/AER containment on the GPU PCIe paths first, followed by the GPUs falling off the bus and then the expected NVIDIA/UVM/GSP fallout.
Update: I may have finally found the real trigger, and it is a lot less glamorous than “mystery dead workstation board.”
The failure pattern changed a lot once I got disciplined about one-variable-at-a-time testing.
What I had been seeing:
repeated dual-GPU failures
PCIe root-port DPC/AER first in some events
then Xid 79 / GPU fallen off the bus
then NV_ERR_GPU_IS_LOST / Xid 154 fallout
sometimes recovery attempts down to 2.5 GT/s and failed AER recovery
What changed:
I swapped from dual PSU to single PSU only, with no reseat, no cleanup, no cable reroute, same ports, same loads
before that, I was topping out around 12 hours
on single PSU, I got damn near 30 hours continuous under the same workloads
That pointed me hard at power topology, not the board.
Then I found the kicker:
my “dedicated” 20A circuit is not actually clean. The kitchen garbage disposal is on it. When the disposal is used, it interrupts power to the workstation. In the earlier configuration it would knock the GPUs out first; on the single-PSU setup it can take down the whole system.
That also explains why the failure rate suddenly got worse recently: my sister has been staying over, so the disposal has been getting used more often.
So at this point the leading suspect is upstream branch-circuit power disturbance, not the motherboard.
Separate rant: ASUS support’s response was embarrassing for a workstation-class product. I sent logs and a real event sequence, and their reply was basically: “The motherboard only support Windows 11, please install Windows and it should work.”
That is not even consistent with ASUS’s own materials for this board:
the public tech specs list Windows 11 and Windows 10 64-bit
the support download page includes an “Others” OS category
ASUS’s Linux status report includes the Pro WS WRX90E-SAGE SE with Linux validation entries
So no, this is not a “Windows-only board,” and that reply was canned nonsense, not support.
Current status:
I still need to get the workstation onto a truly separate clean circuit and retest
but right now the evidence points much harder at power quality / branch-circuit issues than at a bad board
Honestly, I’d much rather have a circuit problem than an RMA on a WRX90 box loaded with dual Blackwells.
Edit: It is the switch on the circuit and not the disposal itself. I removed everything accept my system from the circuit, so it is now clean. Testing to continue.
I’m having what looks like a similar issue also happen to be on a dual PSU. I have 6 GPUs running on mine so a single PSU isn’t an option. Presently i have two silverstone 2500. My issue arrives more often than not after long periods of down time and during hard ramp ups from a prompt. I have a cronjob that occurs at 0400 when nothing is really going on in the house and everyone is asleep and this has triggered it at least a few times.
The system can run fine for over a week, but has suffered multiple complete platform hard-freezes with no useful final logs. No Xid, no AER fatal, no MCE, no panic, no kdump/vmcore. The machine simply stops responding and requires a physical reset.
The crashes seem correlated with multi-GPU llama.cpp workloads after the GPUs have been idle long enough for the PCIe links to downshift though I think i’ve seen it occur at the point of a downshift too, not just an upshift.
I’ve put a ton of effort into tracking this down and im about 99% sure its occurring when the cards negotiate from PCI 1 to 5 and or 5 back to 1. Im now testing if it occurs while i’m in PCI 4.
System
Motherboard: ASUS Pro WS WRX90E-SAGE SE
CPU: Threadripper Pro 9975WX
RAM: 192 GB DDR5 RDIMM ECC
GPUs:
5× NVIDIA RTX PRO 6000 Blackwell Max-Q Workstation Edition, 96 GB each
Same experience I had. I reported a bug that was confirmed by their engineers and got asked in every subsequent email what I even need the features for. Did not get a resolution for over a year, don’t even have the board anymore. ASRock had the same issue and send me a fixed BIOS within a week for a mainboard that was $300 less.
If you are still around, was that the final issue in the end? I sometimes forget the issues that arise with 120V power but I will make a note in my head about it for the next time I am trying the help someone from the US.