Will 6 cores be enough to run a homelab and local AI agents at the same time?

Hi everyone, this is my first time posting here, so please let me know if I’ve left out anything important or missed something obvious.

Planning to get into homelabbing and local AI, mainly to get hands-on experience for my cybersecurity career. Trying to avoid buying new RAM (DDR5) given how expensive it is in Australia right now, so hoping to just use my current PC as my homelab rather than build something new.

Current specs: Ryzen 5 7600 (6 cores, 12 threads), 32GB RAM, 7900 GRE. Motherboard is a AsRock B650M PG Riptide WiFi.

The plan: add an AMD R9700 AI Pro (ASRock variant) and pass both GPUs through to a dedicated AI VM using proxmox. The R9700 would sit in the main x16 slot, and the 7900 GRE in the secondary slot, which is physically x16 but only wired for x4. I’m planning to run two separate models, one on each GPU, not splitting a single large model across both. All inference happens on the GPUs.

Planned VMs:

  • Docker VM hosting 15-20 lightweight containers

  • A Linux VM for cyber security practice, with a few target VMs alongside it

  • AI VM with both GPUs passed through, around 3 cores and 8-12GB RAM allocated, running 4-5 agents

What I’m unsure about:

  1. I’m especially worried 3 cores/6 threads won’t be enough for 4-5 concurrent agents, even though the GPUs are doing all the actual inference work. Would the CPU still end up being a bottleneck just from orchestrating the agents and tool calling?

  2. More broadly, would 6 cores and 32GB hold up running all of this together, the VMs, Docker containers, and AI agents at the same time?

  3. Would an 850W PSU handle both GPUs running at once, or would I need to power-limit one or both to be safe?

  4. Does anyone know how the R9700 performs under concurrent users or concurrent agent requests? Curious if it scales decently or falls off a cliff past a certain point.

  5. If anyone owns the ASRock R9700 specifically, how loud does it get under load? This system sits about a meter from where I work, so I want to know how loud it’ll actually be.

Basically just trying to figure out if this setup is even realistic for what I want to do, or if I’m underestimating how much this is going to strain a 6-core CPU.

The alternative I’m considering is building a separate machine instead, something like an i7-14700K or a 5950X with 64GB RAM , DDR4 isnt as expensive as DDR5 so its not that expensive , but its still decent chunk of money, and I don’t want to spend it, then later realize I didn’t actually need to, and end up with two PCs sitting around, which isn’t exactly ideal.

Another option is to just convert my current PC into the homelab as-is, and wait until RAM prices come down (Black Friday ?) or Zen 6 for Ryzen launches before upgrading properly.

So out of all three, converting now as-is, building a separate DDR4 machine now, or converting now and upgrading later, I’d love to know which one makes the most sense. Appreciate any input, genuinely trying to spend this well rather than regret it later.Thanks in advance :slight_smile:

Depends how patient you are but i would suggest that yes, 6 cores will be enough to get started.

For both GPUs though:

850w will be extremely borderline.

Not because of the system sustained total power draw, but most modern GPUs have large transient spikes in power load and 850w is the recommended size for one of those GPUs from memory, not two.

You can give it a go and see how it fares, but i’d suggest that if anything is going to be under stress its your PSU. Will you even have enough 8 pins on the PSU to power both?

Symptom of transient spikes taking things out will be sudden power off/reboot of your machine if the PSU hits overcurrent protection and shuts down momentarily.

This will depend on how your PSU handles overcurrent.

edit:

GPU/PSU - typos

2 Likes

So the setup can work, but you may run into some issues, especially with two different sets of drivers installed in the same OS, and running multiple VMs with Proxmox that the GPU’s pass-through can also be complex. Not to say that it’s wrong, and it’s definitely doable, but you are going down a more complicated path, which you may not need to go down, depending on what you are trying to actually do.

I can tell you that 8-12 gigs of RAM is not going to cut it for 3-4 agents with two different GPUs, totaling 52 gigs of VRAM. Right now I have a single W7900 and a W7500 for driving my screens, and running a single 30 gig model with 200k context will often increase my RAM usage by more than 20 gigabytes. When you are talking about running multiple agents, each agent can easily consume a couple gigs of memory, and it really depends on what you want that agents do in the first place. So I think you need to sit down on the side on what your goal is, before just throwing hardware at your current PC and hoping for the best.

If you do build a dedicated AI machine, you should definitely look towards a 5900S or 5950S with 64 gigs of RAM at a minimum.

The key is you need more RAM than VRAM, especially when the different model is running on your GPU. It also tends to copy the KV cache around maybe her optimization purposes. I don’t know. I just know that it definitely uses memory even with 100% of the model layers are being offloaded to the GPU.

Are you offloading any layers to the CPU in your cases?

I’ve had the opposite experience where I have only marginal single digit % shifts in CPU and RAM consumption on my host LLM inference systems. There’s more of an impact at model load time but once it’s loaded entirely into VRAM I’ve found there’s no bottlenecks on the CPU/RAM side to the point where I’m paring down available resources because it’s not necessary. I’m also not swapping models so it’s only a minor inconvenience at load time which is becoming less and less.

No I don’t offload any layers to the CPU on any of my machines. I might need to offload a few now with GLM5.3-Flash or DeepSeekv4.1-Flash.. but that is in my server.

Should be fine, depending on what you have the agents doing. Actual inference pins one core per GPU at 100%, so you only need 2 for 2 GPUs, so having 4-6 threads available for that VM would be fine.

The bigger issue would be RAM, what are you planning to run inference with and are there prebuilt kernels and the like for your GPUs? I run 64GB RAM on my GPU passthrough box at work (host is a 7950X, 96GB RAM, dual 5060 Tis), because I was getting OOM errors when building vLLM and some other chunky compile tasks. If you don’t have to compile things then you should be fine with way less RAM. Though with llama.cpp I’m still sitting at 29GB used. I’ll reboot that machine quick and see if it’s just caching stuff or actually does need that much on a fresh boot.

The other RAM complication is that Proxmox can’t use RAM as a ballooning device on PCIe passthrough VMs. For memory management reasons it has to allocate all the assigned RAM on boot, so it can’t shuffle that around between VMs if one were to have a RAM usage spike while others were idling.

Six cores, twelve threads you say?

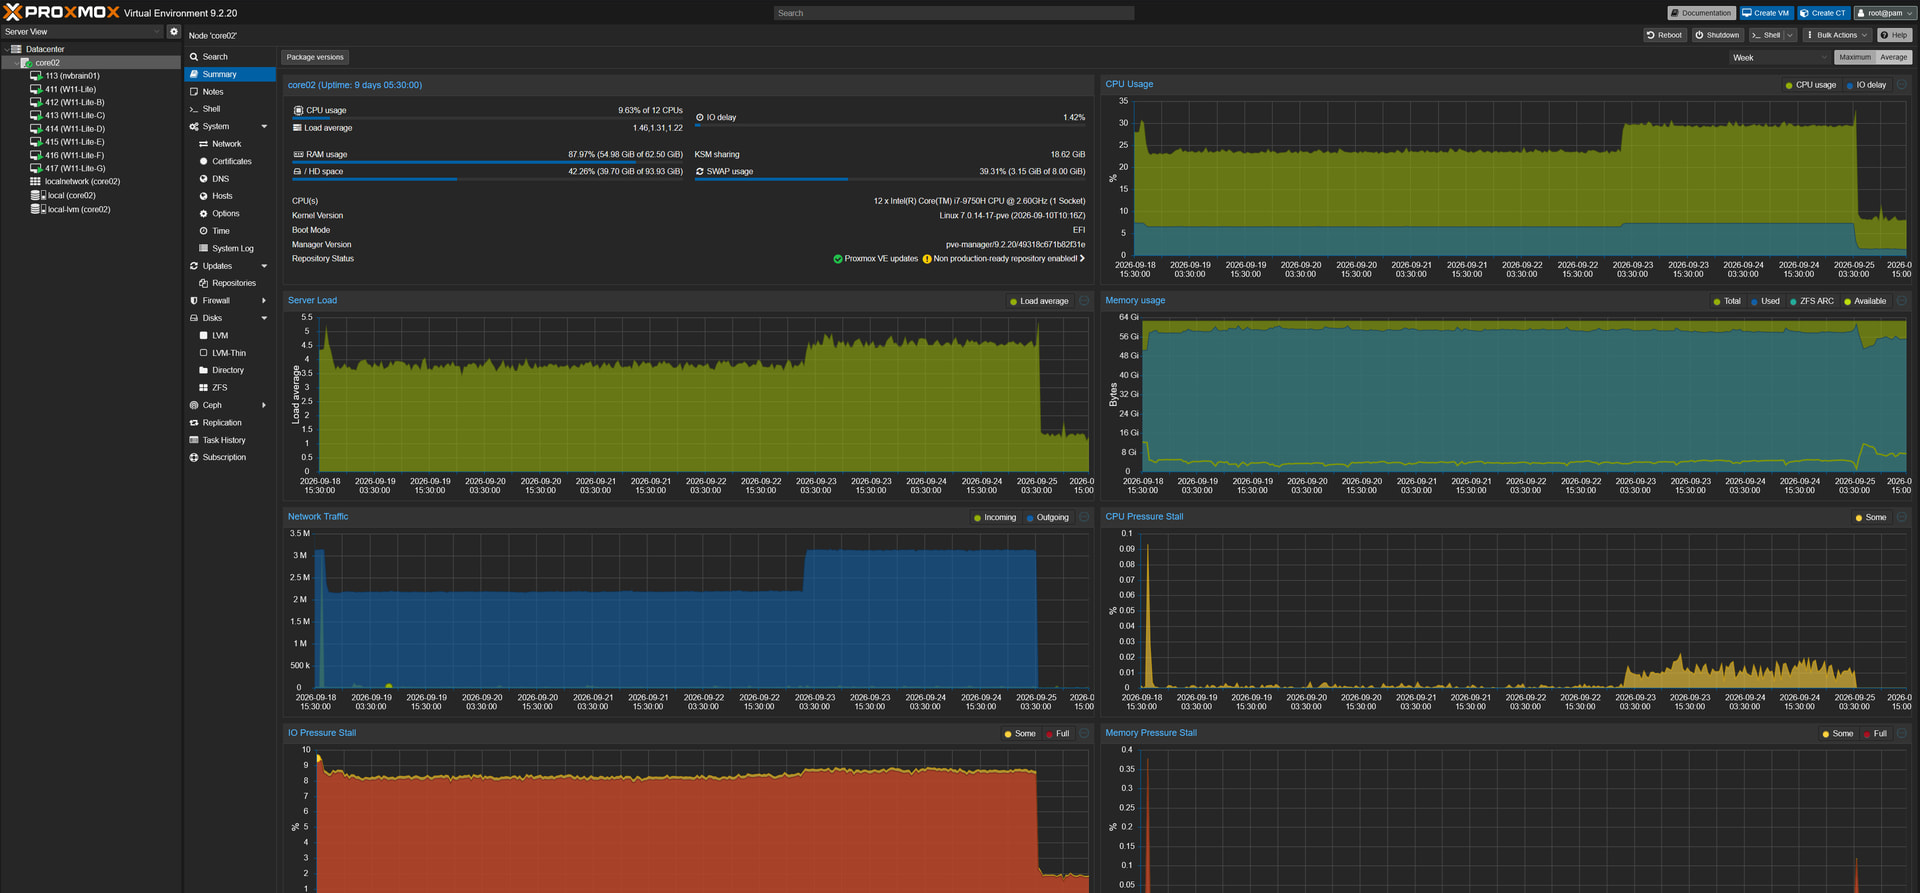
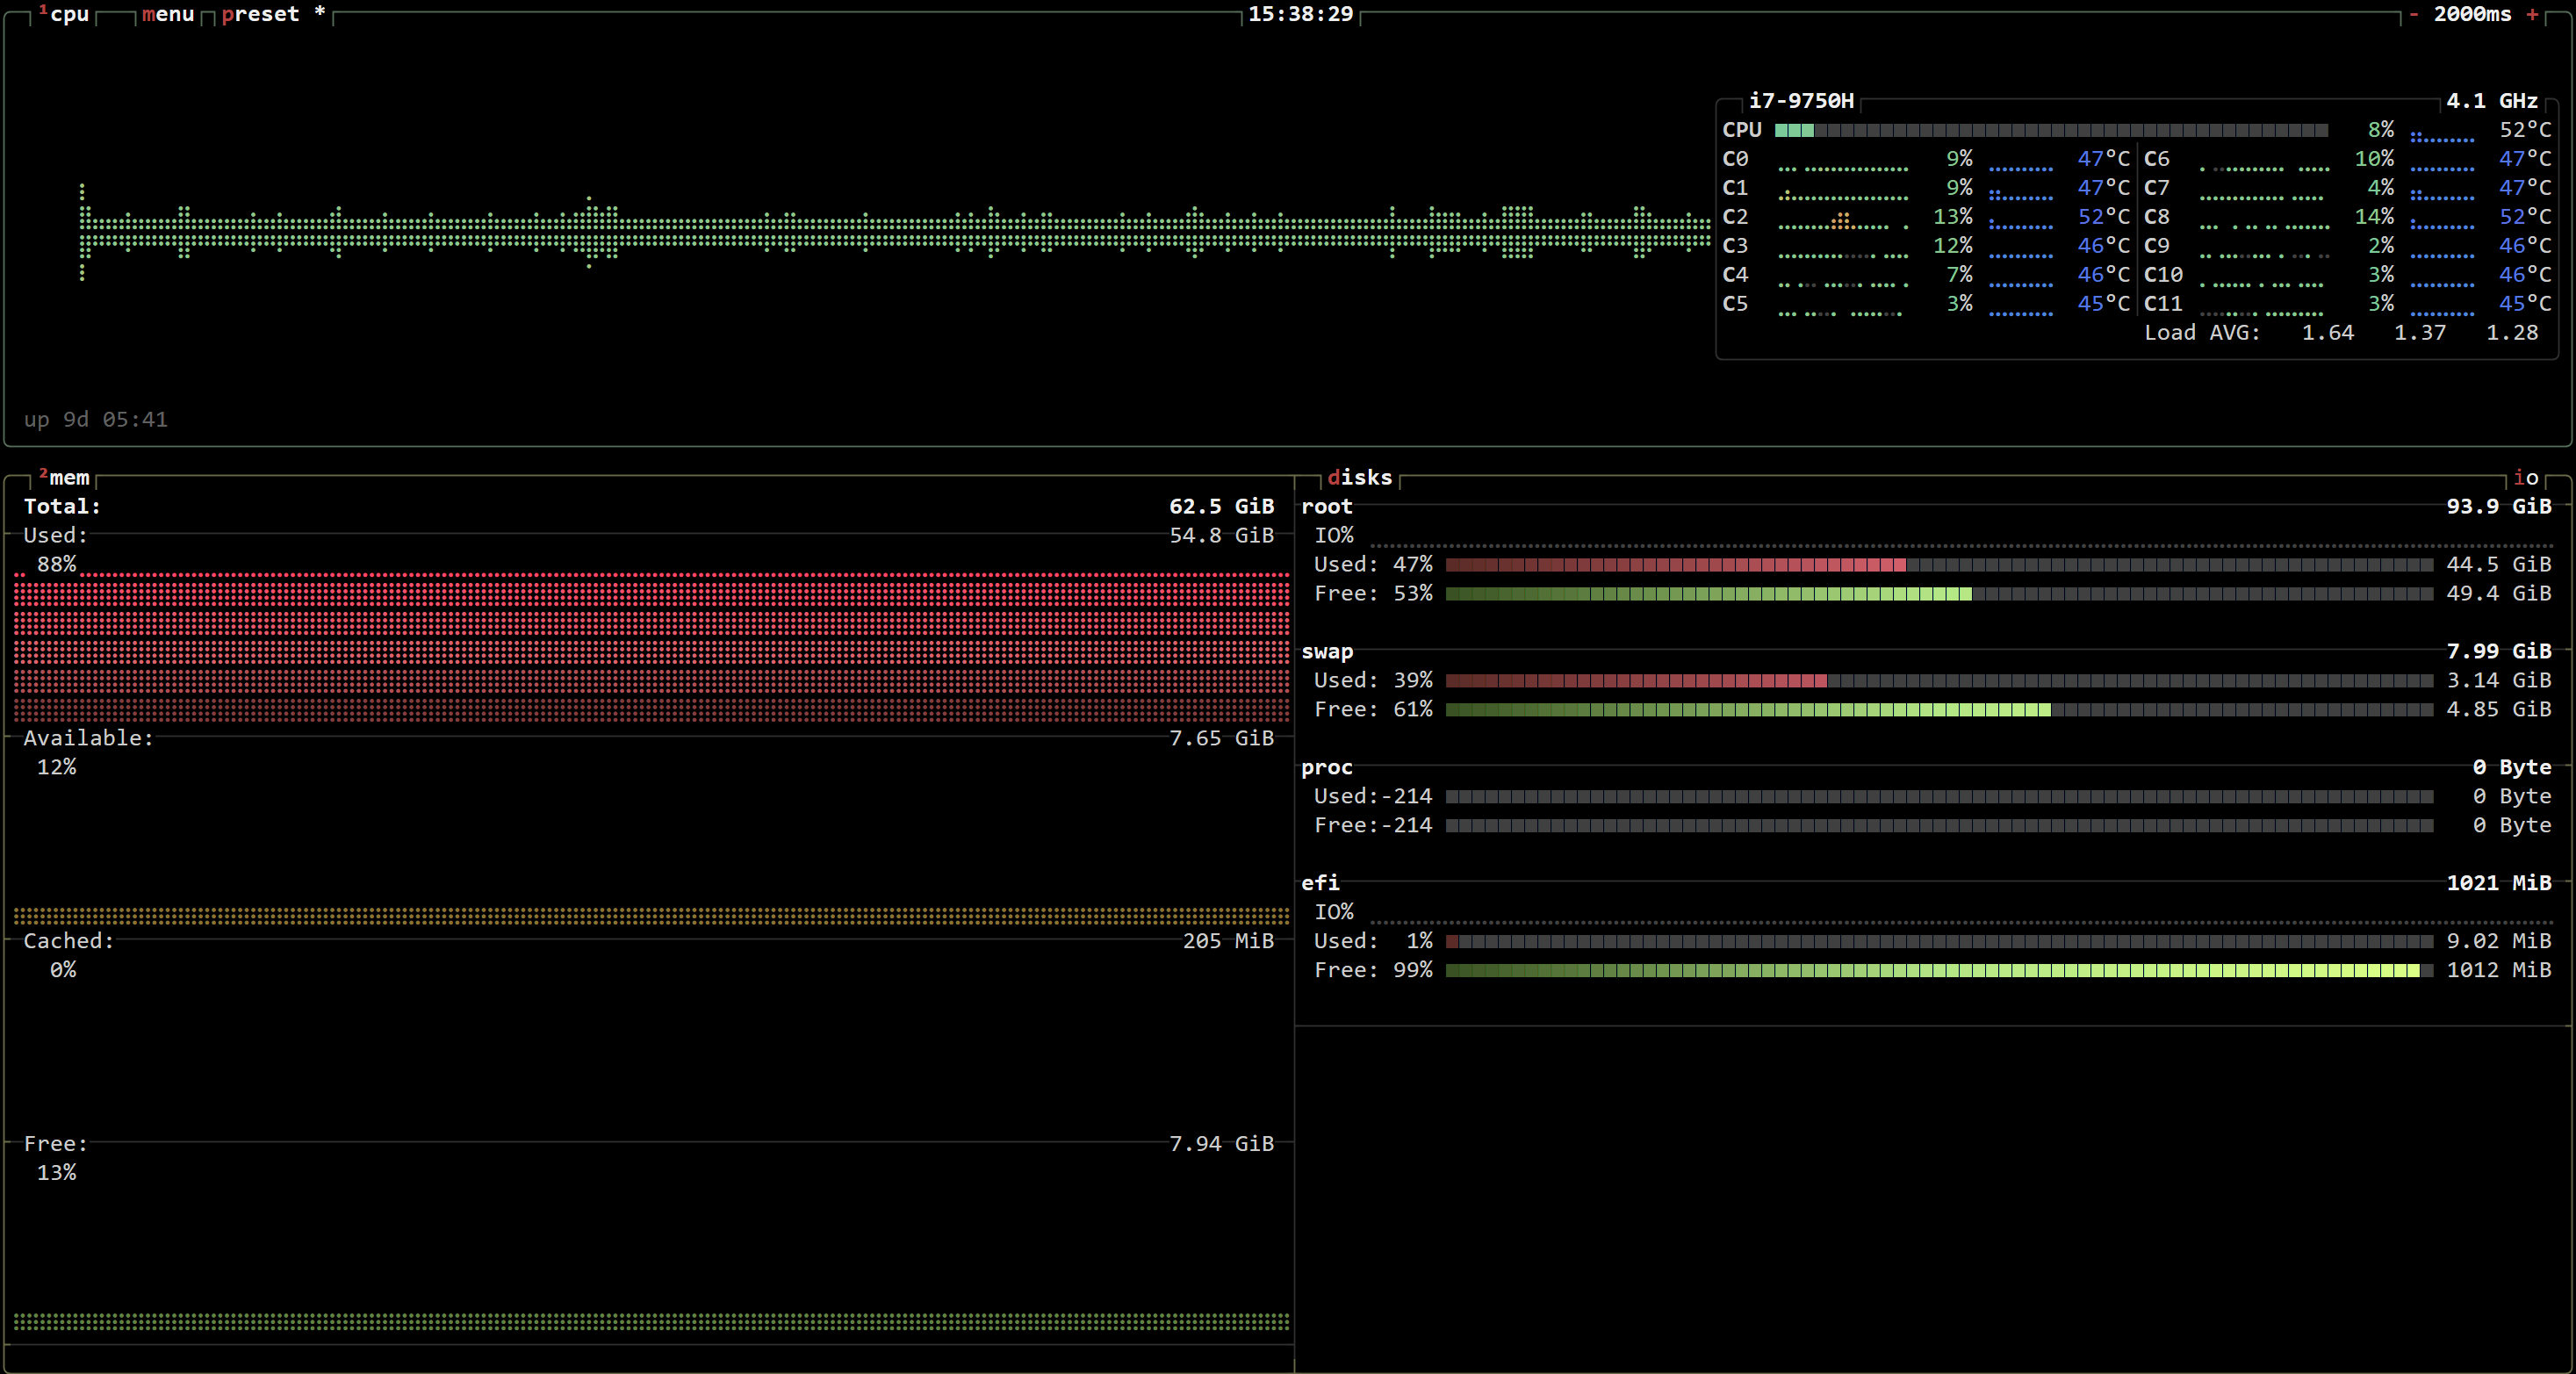
Here’s a little experiment I’ve had running for over a week on a i7-9750H, 6 cores, 12 threads. The CPU is about four years older than your AMD. Oh, and 64Gb DDR4 3200.

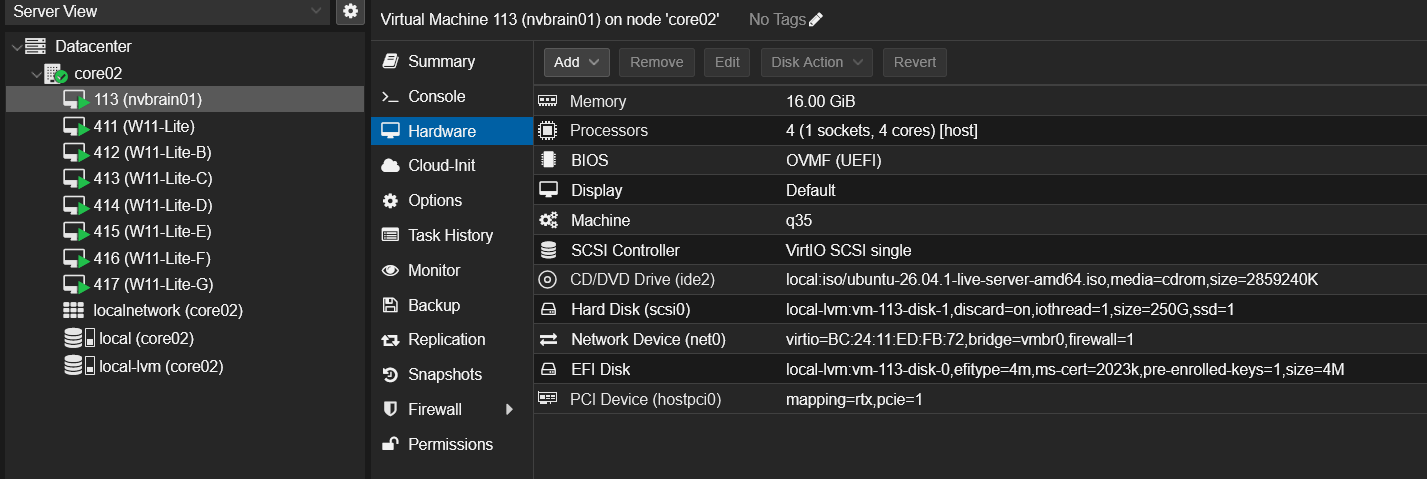
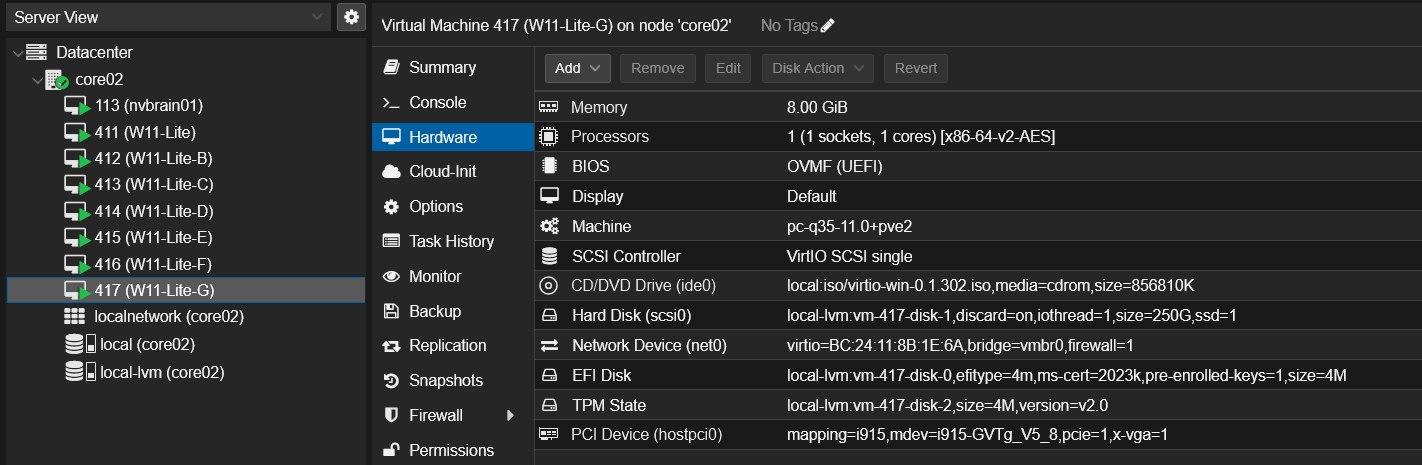
It’s hosting a VM with 16gb, 4 (host) cores and a RTX A2000 12Gb passed through to Ubuntu 26.04 and llama.cpp .. and then seven more VM’s of Win11 Enterprise IoT with 8gb, single core, and the i915 iGPU split (mdev) into seven (one per VM) running the Heaven benchmark.

Eight VMs total.

I can’t speak to your power envelope and usage case, but the raw bones will likely get it done.

1 Like

That is pretty cool!