Part 3.11 for workgroups
The mountain-o-tests has grown wildly out of control, well beyond what a hypercube of logits could ever fit into one post. So I am going to start splitting the next segments into moderately entertaining summaries of the results to hopefully explore some of the many… maaany… interesting findings.
(I might edit this post to include a few more charts when i have a chance at lunch so consider this a preliminary release)
Heresy!

With the release of qwen3.8 many people are flocking to fine tunes labeled as HERETIC! UNCENSORED! ABLITERATED!
So, while they might be able to remove some post-training “safety” (i hate that term) what is the overall impact on their ability to actually do work? If you want to chat about the capital of a certain island nation or certain events in 1989, it will probably do just fine. But what if we let it make those tasty tool calls and run it through the battery of forced teacher decodes?
The heretics:
We grabbed 4 “popular” (by likes and top downloads) tunes of Qwen 3.8, all full BF16 sized not quants:
- heretic-org/Qwen3.8-27B-heretic-ara ( heretic-org/Qwen3.8-27B-heretic-ara · Hugging Face )
- huihui-ai/Huihui-Qwen3.8-27B-abliterated ( huihui-ai/Huihui-Qwen3.8-27B-abliterated · Hugging Face )
- Blackfrost-AI/Qwen3.8-27B-ABLITERATED-BF16 ( Blackfrost-AI/Qwen3.8-27B-ABLITERATED-BF16 · Hugging Face )
- AEON-7/Qwen3.8-27B-AEON-ULTIMATE-UNCENSORED-BF16 ( AEON-7/Qwen3.8-27B-AEON-ULTIMATE-UNCENSORED-BF16 · Hugging Face )
And compared them to our reference BF16 logits captured on SM120 for Qwen/Qwen3.8-27B ( Qwen/Qwen3.8-27B · Hugging Face )
We also ran a limited W4A16 side experiment for fun.
- hwkranger/Qwen3.8-27B-heretic-ara-NVFP4 ( hwkranger/Qwen3.8-27B-heretic-ara-NVFP4 · Hugging Face )
Some Summary Results
| Derivative vs stock Qwen3.8 | Method | SP04 Top-1 flips | SP06 Top-1 flips | SP06 worst-range p95 KLD | Invalid branch futures, SP04 / SP06 |
|---|---|---|---|---|---|
| Heretic-ARA | Reproducible ARA ablation | 0.717% | 1.337% | 0.03661 | 0/11 · 0/58 |
| Huihui Abliterated | “Crude proof-of-concept” abliteration | 0.912% | 1.406% | 0.04477 | 0/14 · 0/61 |
| Blackfrost Abliterated | Refusal-direction weight edit | 3.844% | 4.978% | 0.31235 | 0/59 · 1/216 |
| AEON Ultimate | SSM repair + Abliterix + MTP graft | 2.997% | 5.831% | 0.68507 | 8/46 · 36/253 |
The first two quants appear remarkably functional while the latter two should probably go on the do-not-use list.
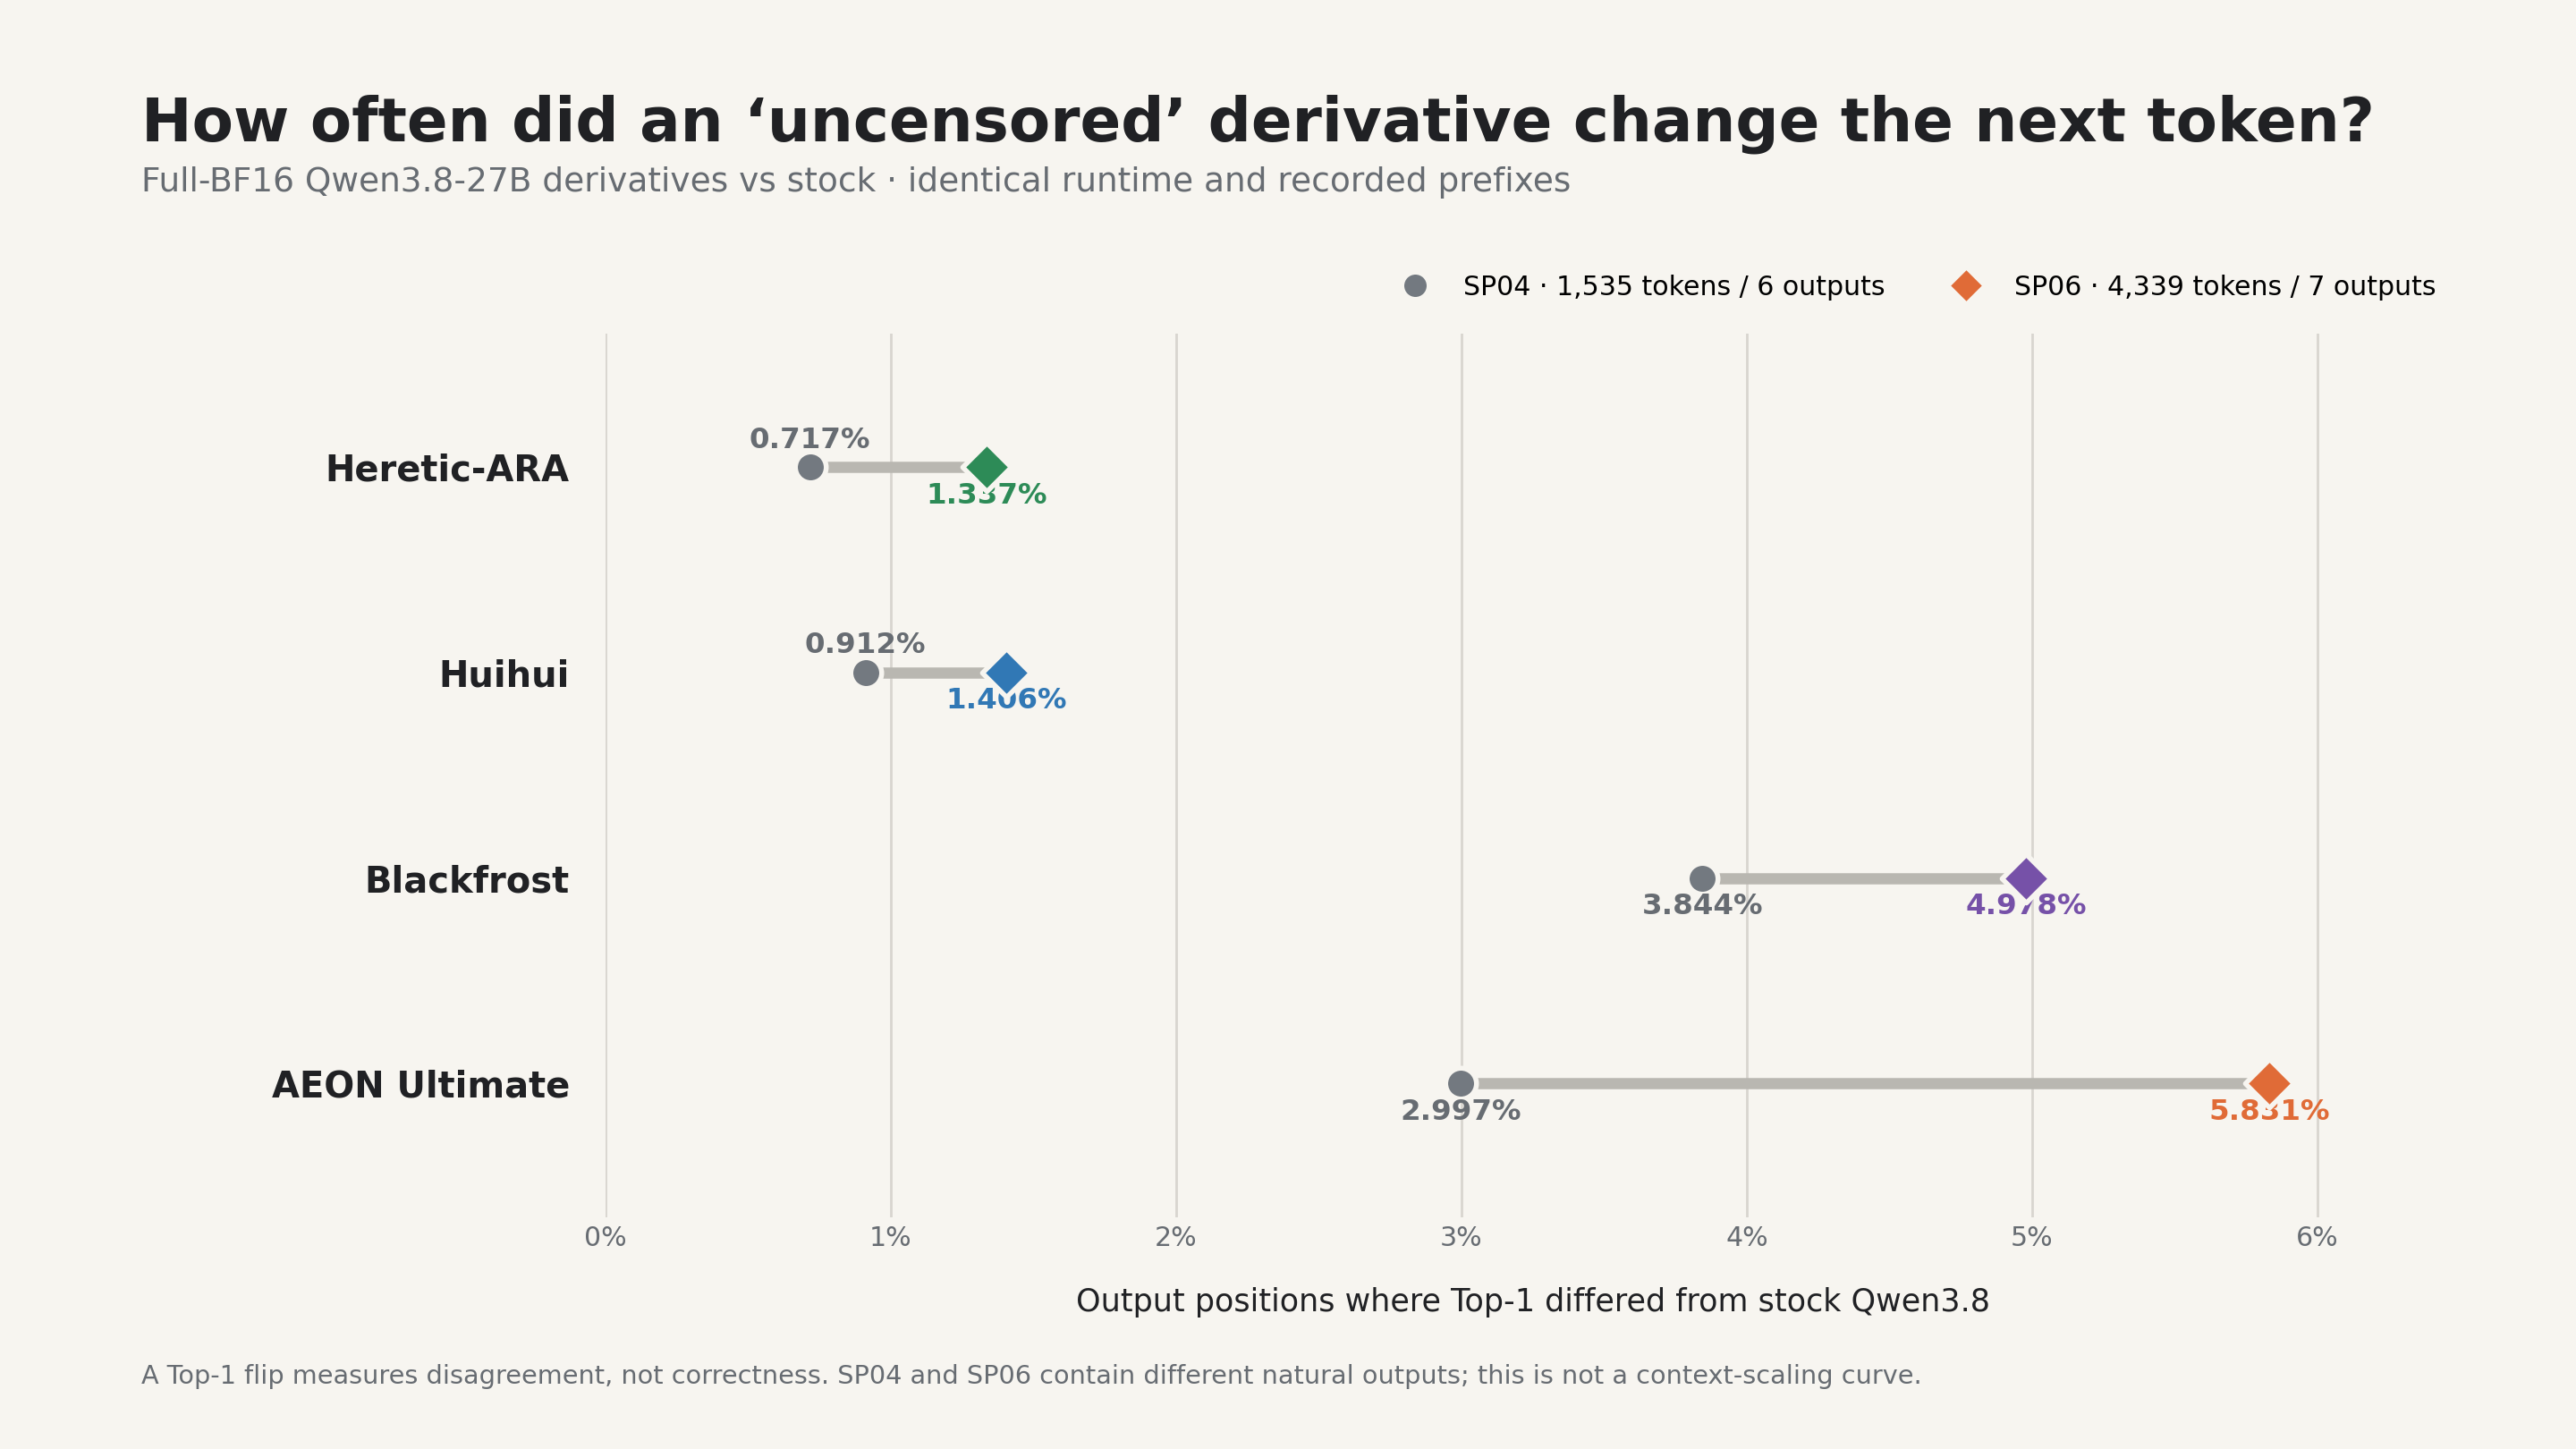
SP04 covers 1,535 assistant-output tokens in six natural ranges. SP06 covers 4,339 tokens in seven ranges, including prose, exact CLI/SQL/code, multi-tool calls, recovery actions, and architecture recommendations.
“Invalid branch futures” means structurally invalid output among the specifically selected Top-1 divergence roots we explored. It is not a general tool-call failure rate, and adjacent roots can expose the same underlying failure.
Broadly across all testing this week, top 1 token flips appear to be quite tied to the actual specific workstream being captured. Some tasks are very low <1% diff, others spike up wildly between different configs/quants/etc. This is something I need to go into more in a later future post.
Heretic-ARA
On SP06, 57 of its 58 flips occurred where stock Qwen was already uncertain. It overturned zero strongly preferred stock tokens.
Its method is also the most reproducible:
- Targets attn.o_proj and mlp.down_proj.
- Uses Arbitrary-Rank Ablation.
- Discloses datasets, seed, search settings, and 60 search trials.
- Reports its refusal and base-KL selection criteria.
This is the strongest example of an ablation that changed the target behavior without broadly destabilizing ordinary technical output.
The crude Huihui treatment also worked surprisingly well
Huihui explicitly labels its process a crude proof of concept, yet it landed in almost the same conservative tier as Heretic-ARA:
- 1.406% flips on SP06.
- 59 of 61 flips occurred at weak stock decisions.
- No objectively invalid structured branches in either prompt.
That is probably the biggest positive surprise. A sophisticated procedure was not required to preserve this particular technical workload, but that does not establish equal refusal removal or general quality.
Blackfrost changed much more, but usually remained coherent
AEON was the most disruptive on SP06:
- 5.831% Top-1 flips.
- Highest worst-range p95 KLD.
- 24 flips overturned strongly preferred stock decisions.
- 36 structurally invalid SP06 branch futures.
- All eight SP04 invalid futures were AEON.
This is not a clean “abliteration is bad” result. AEON combines:
- SSM conv1d outlier repair.
- An Abliterix search.
- A stock MTP graft.
Its card says the selected trial prioritized coherence rather than minimum KL. Therefore, the experiment measures that complete recipe, not abliteration alone.
The most compelling failure example… AEON
AEON at SP06 token position 42,950 is nearly perfect for a visual explainer.
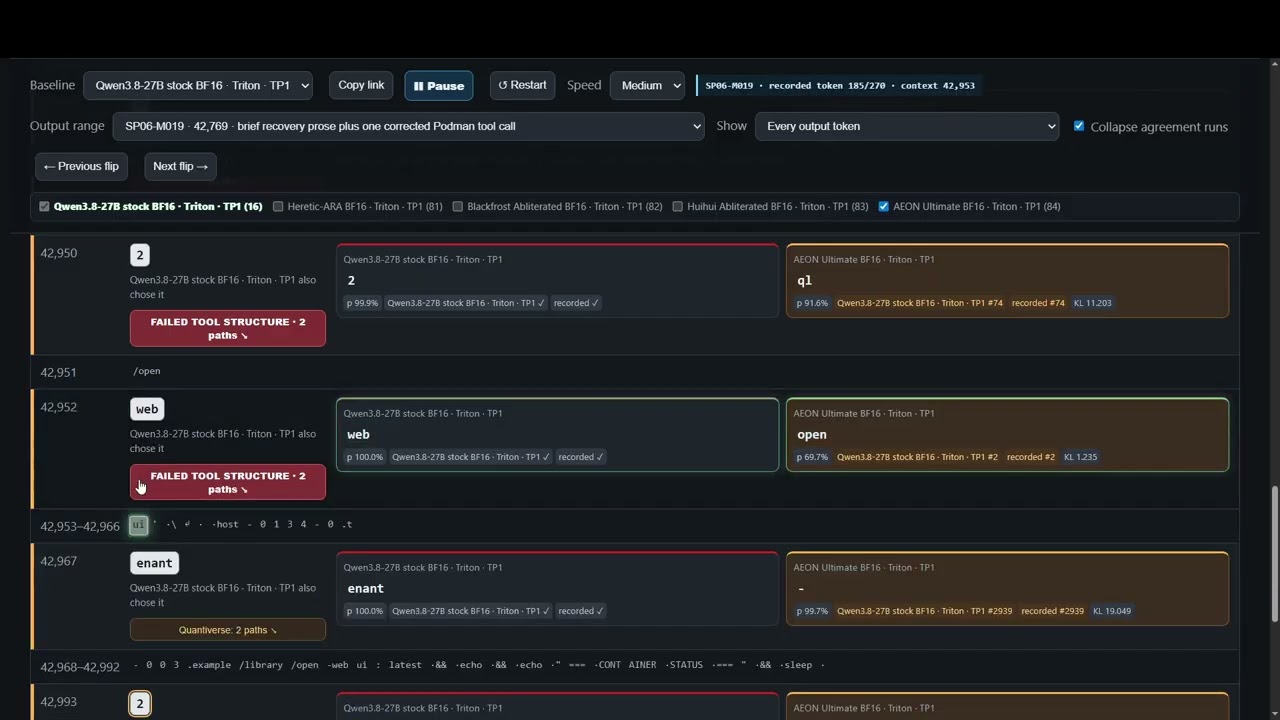
- The context contained PostgreSQL port 5432.
- Stock selected the final 2 with probability 0.9991.
- AEON selected ql with probability 0.9158.
- The alternate continuation produced 543ql.
- It subsequently failed to close the tool/function envelope.
A second nearby case corrupted a known hostname:
- Stock selected enant in .tenant with probability 0.99996.
- AEON selected - with probability 0.99747.
- The resulting branch altered the hostname and later damaged a parameter.
These are not vague stylistic differences. They are high-confidence literal-copy failures in operational commands.
Another useful example changed psycopg’s page_size=100 into size=100, likely turning a valid API argument into an invalid one.
Vision and MTP weights were untouched
We independently hashed every logical vision and MTP tensor against stock, even where checkpoint sharding differed:
- 333/333 vision tensors matched exactly.
- 15/15 MTP tensors matched exactly.
- Roughly 1.77 GB of tensors per checkpoint were checked.
All four derivatives preserved them byte-for-byte. Therefore, the text results come from language-weight changes rather than hidden vision or MTP modifications.
It does not prove identical vision behavior, the panel did not activate the vision path but it establishes exact weight preservation.
Confidence
When Qwen was LESS confident about the next token is where we saw the most flips overall. However when Qwen was confident, the faithful among blasphemers did not flip their results.
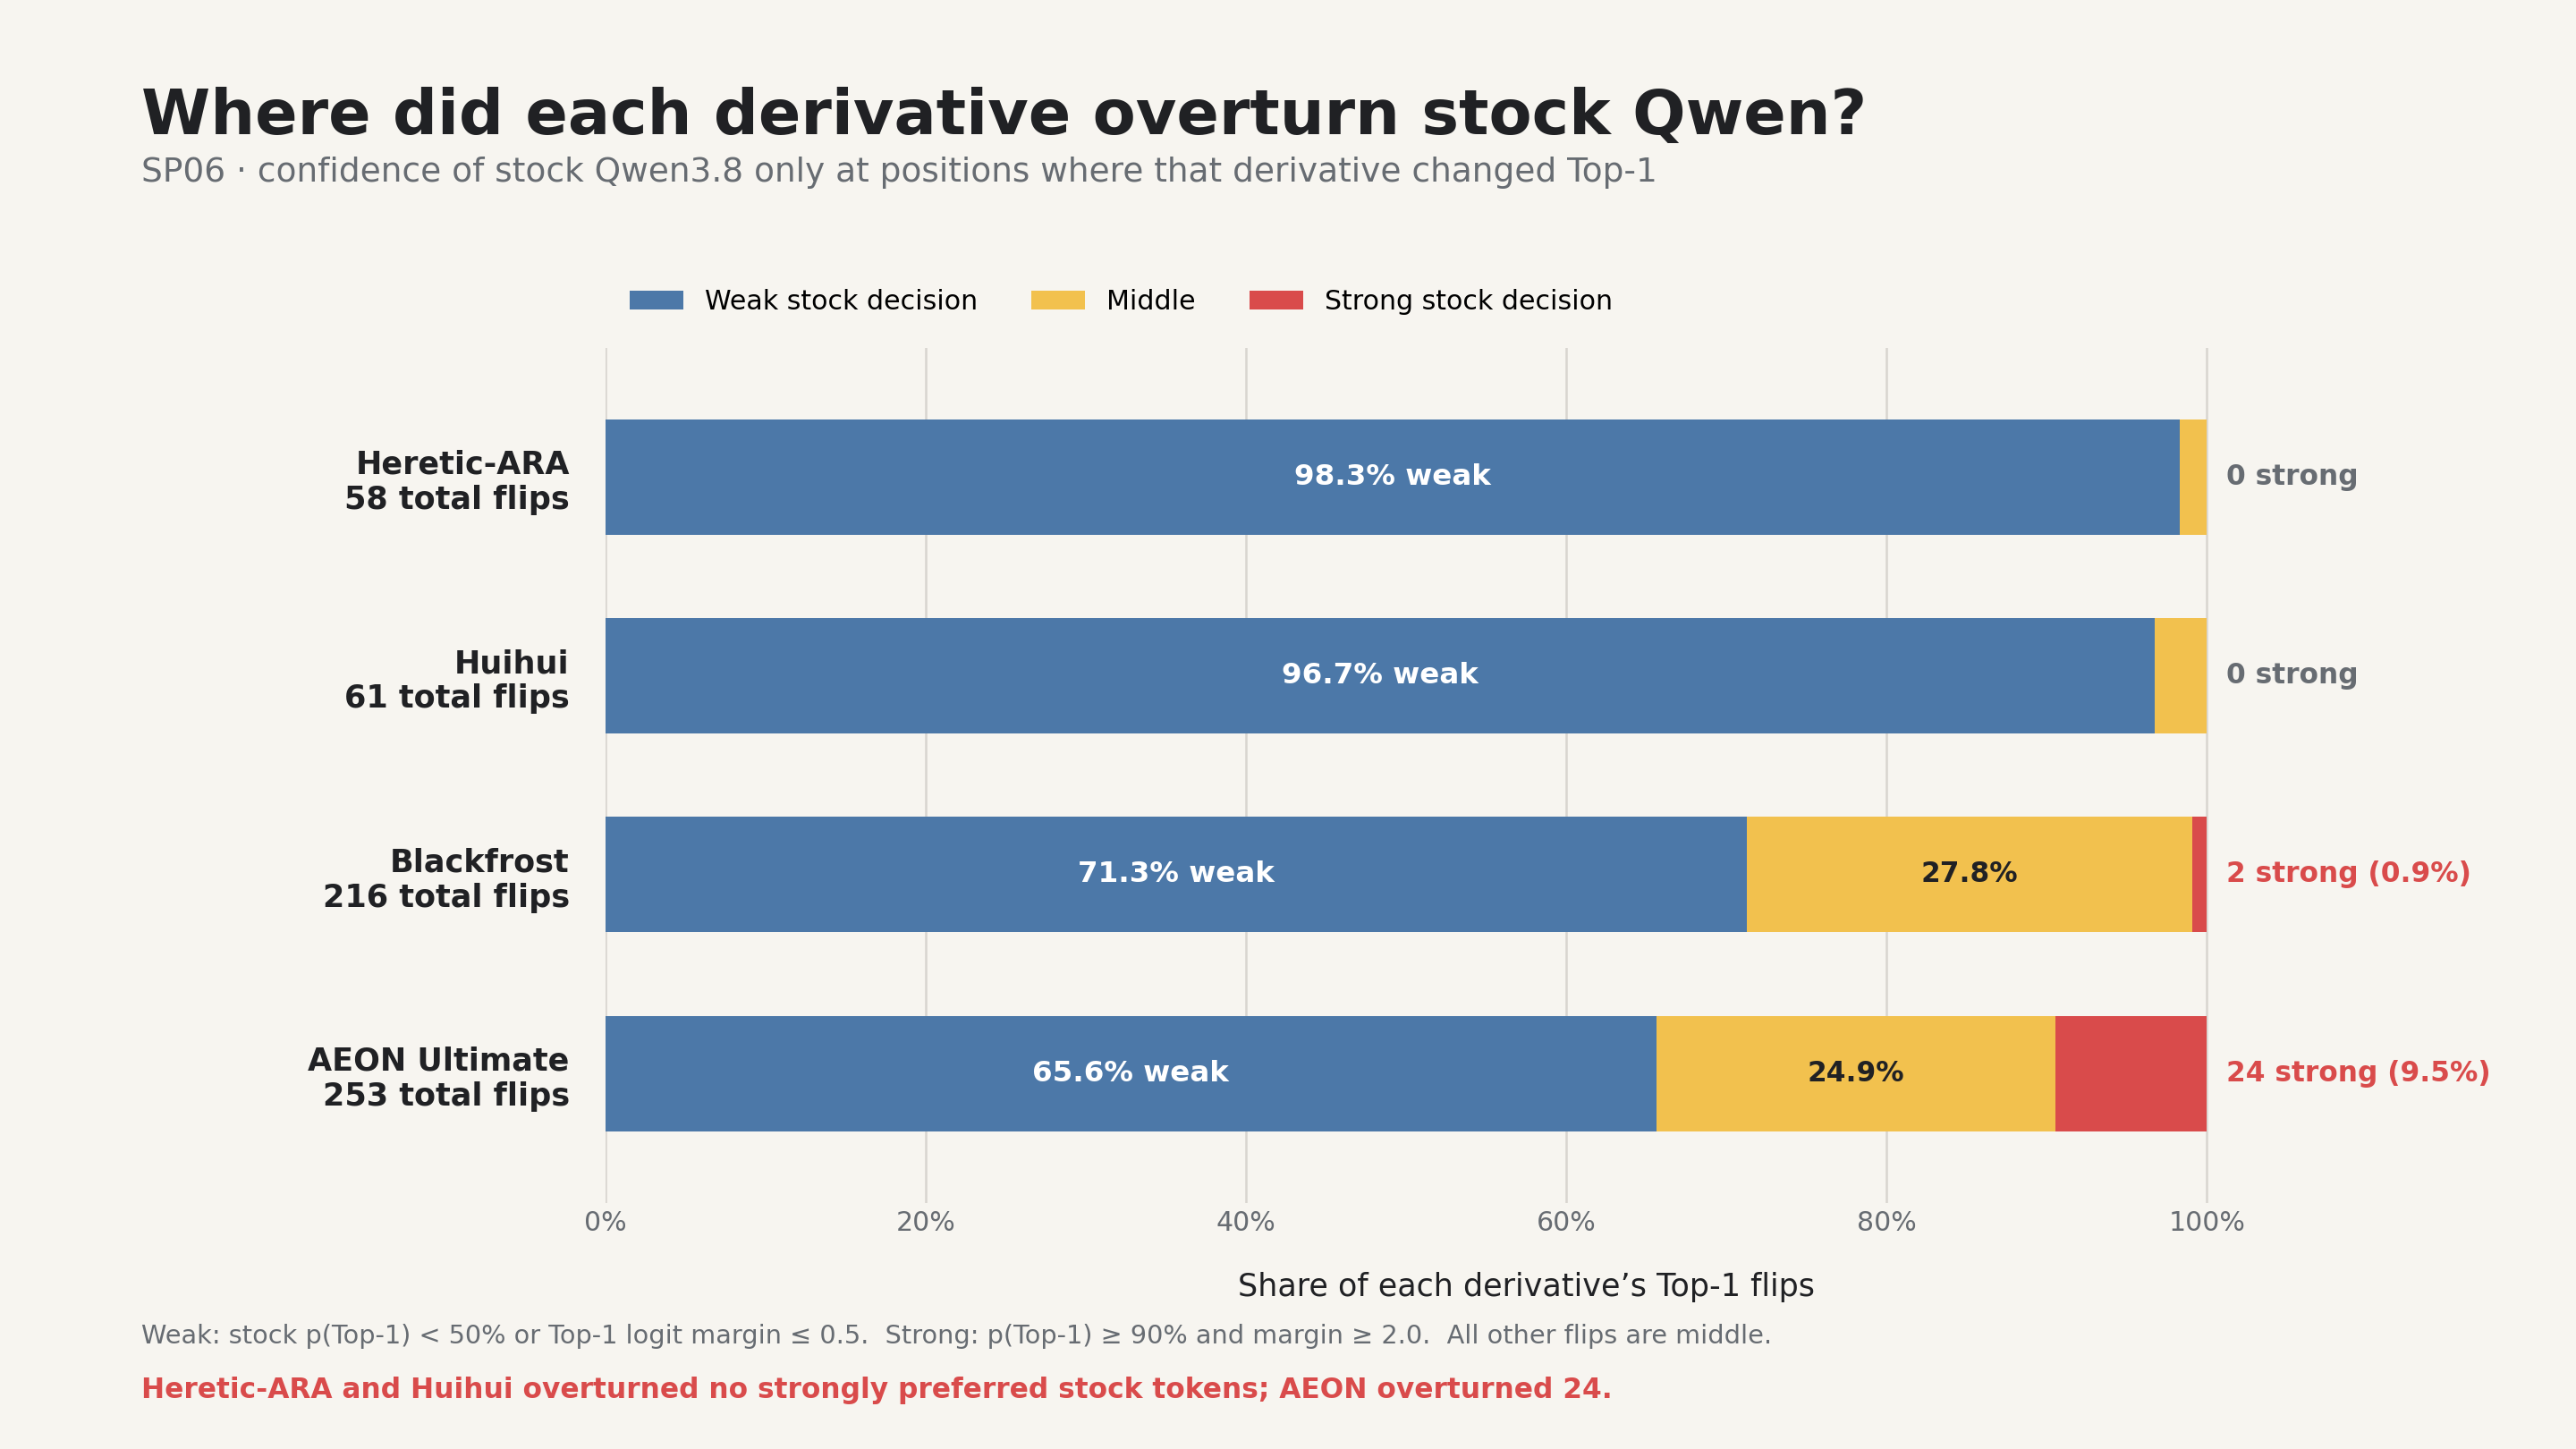
Only the truly heretical overruled Qwen’s strong next token signal for their own, resulting in errors.
On these long-context technical workloads, Heretic-ARA and Huihui preserved stock behavior far better than Blackfrost and AEON. AEON produced the clearest reproducible operational damage, but its bundled recipe prevents attributing that damage solely to abliteration. None of these measurements establishes which derivative is most successfully uncensored.
Refusal benchmarks and model-card KLD numbers do not characterize collateral changes to tool use, exact literals, code, or long-context agentic work.
Next Time, on X-Men…
The H200 and B200 preliminary results are in. And they are very interesting…