Unsloth Studio on an Intel Arc Pro B70
Verified 4 October 2026. The published Unsloth Intel page was not current. This note records the procedure that actually ran, and the package versions the card accepted.
Unsloth Studio 2026.9.14 is installed under $HOME/local-ai/unsloth. Training packages are the Intel XPU wheels, not a CPU build of PyTorch. With ONEAPI_DEVICE_SELECTOR=level_zero:1 and no Level Zero affinity mask, torch.xpu reported one device: Intel(R) Arc™ Pro B70 Graphics.
The first server check used port 8890, because 8888 was already taken. That was not far enough. Studio’s own default is 8888, and its launcher scans the next 20 ports, 8888 through 8908. On this machine 8888 is the shared-memory gateway. A later launch would bind it whenever the gateway was down. Studio’s port is now 8910, and the scan is 8910 through 8930. The check of that port is in the server section below.
Package Version that imported Where it came from
torch 2.14.1+xpu download.pytorch.org/whl/xpu
torchvision 0.29.1+xpu same index, resolved beside torch 2.14.1
torchaudio 2.11.0+xpu same index. Upstream stops torchaudio at 2.11
triton-xpu 3.8.0 same index. The only Triton package left installed
torchao 0.18.0+xpu same index
bitsandbytes 0.50.2 PyPI, installed with --no-deps. Both libbitsandbytes_xpu2025.so and libbitsandbytes_xpu2026.so are in the wheel
torchcodec 0.12.0 PyPI. Decode only. This wheel has no XPU device. Intel’s torchlib-xpu plugin is published for the PyTorch 2.13 series, so it was not added here
intel-sycl-rt, intel-cmplr-lib-rt, mkl 2026.1.0 pulled by the torch wheel. This is the bundled oneAPI runtime
oneccl 2022.1.1 same wheel dependency set
unsloth / unsloth_zoo 2026.9.14 / 2026.9.9 the local checkout and the zoo pin the installer selected
Python 3.12.13 Studio refuses 3.14. The system interpreter on this host is 3.14
The probe that passed:
selector level_zero:1
version 2.14.1+xpu
available True
count 1
device 0 Intel(R) Arc™ Pro B70 Graphics
]import unsloth then printed Unsloth 2026.9.14 and the same device name. System oneAPI setvars.sh was not sourced.
The host
This procedure added no distribution packages. On 4 October 2026, dnf history had no transaction since 1 October. Everything new is under $HOME/local-ai/unsloth. The lists below are what that tree used, measured on this machine, and what another machine needs in their place.
Fedora Linux 44, as measured
Fedora Linux 44, KDE Plasma Desktop Edition, kernel 7.2.7-200.fc44.x86_64. The Arc cards use the in-tree xe driver (xe.ko.xz, described as Intel Xe2 Graphics). No out-of-tree kernel module was installed for this setup.
The GPU userspace was already installed, in July 2026. These are the Fedora 44 package names and versions. They are the driver, not the PyTorch wheel:
Package Version
intel-compute-runtime 26.22.38646.6-4.fc44
intel-level-zero 26.22.38646.6-4.fc44
intel-opencl 26.22.38646.6-4.fc44
intel-ocloc 26.22.38646.6-4.fc44
intel-igc 2.36.3-3.fc44
intel-igc-libs 2.36.3-3.fc44
intel-media-driver 26.1.5-1.fc44 is also installed. Training did not use it. Leave it if video decode on the desktop needs it. Do not add it for Studio.
Intel oneAPI is installed under /opt/intel/oneapi, with compiler trees 2025.3, 2026.0, and 2026.1. setvars.sh is there and was not sourced. The torch wheel carries its own intel-sycl-rt 2026.1.0. Sourcing the system file into the Studio shell mixes the two runtimes.
Tools the installer found already on the machine:
Tool Where it came from
python3 3.14.7 python3-3.14.7-1.fc44. Studio refuses 3.14.
uv 0.12.15 uv-0.12.15-1.fc44
git 2.55.0 git-core-2.55.0-1.fc44
gcc / g++ 16.2.1 gcc and gcc-c++ 16.2.1-2.fc44
make 4.4.1 make-4.4.1-12.fc44
cmake 4.3.0 cmake-4.3.0-1.fc44
curl 8.18.0 the Fedora curl package. Headers were not installed.
bubblewrap 0.12.0 bubblewrap-0.12.0-1.fc44
node / npm v24.15.0 / 11.13.0 the first node on PATH, a user-level install. Fedora’s own Node is nodejs22 22.23.1 (/usr/bin/node → node-22) and was not the one the installer used.
Python 3.12.13, the interpreter inside .studio, was already in uv’s interpreter store (11 May 2026). Pointing UV_PYTHON_INSTALL_DIR at .studio/python did not download a second copy. The account can open the render nodes: it is in the render group.
Two installer messages are Fedora-specific and are not failures. There is no AppArmor sysctl apparmor_restrict_unprivileged_userns, so that read fails, and the next line is sandbox bubblewrap works. Do not install AppArmor to clear the first line. The installer also reports missing: libcurl4-openssl-dev. That is a Debian package name. The Fedora name is libcurl-devel, and it is not installed. The prebuilt CPU llama.cpp bundle still installed. Do not add the devel package unless a later llama.cpp build actually fails without curl headers.
On Fedora the packages to install, only where the table above is missing, are:
sudo dnf install intel-compute-runtime intel-level-zero intel-opencl intel-ocloc
intel-igc intel-igc-libs git-core uv gcc gcc-c++ make cmake curl bubblewrap python3
Then, because Fedora 44’s python3 is 3.14, let uv supply 3.12 for Studio. Do not replace the system interpreter. Node can be the distro nodejs22 or a newer user-level Node. The frontend build on this machine used 24.15.0.
On any other system
The wheel does not require Fedora. For Arc A-series and B-series, including Battlemage, the 2.14 page validates Windows 11, Ubuntu 24.04 and 26.04, and WSL2 Ubuntu 24.04 and 26.04. Fedora is not on that list. What the wheel requires is a Level Zero device the process can open. Check that before cloning:
- The card appears under /dev/dri and in /sys/class/drm/cardN/device/uevent. Battlemage and Arc Pro B-series on a current kernel use the xe driver. Older Arc cards may use i915. The driver has to be the one that kernel already ships, or the vendor module that distro documents. This setup did not build one.
- The distro’s Intel compute-runtime and Level Zero userspace are installed. Package names differ. On Fedora 44 they are the six rows in the table above. On Debian and Ubuntu the installer will try its own apt names. Read that list. Do not paste it into dnf.
- The account is in the render group, and a new login has picked that up.
- Python is 3.11, 3.12, or 3.13. If the distro Python is 3.14 or newer, install 3.12 beside it. uv can do that. Leave the system Python alone.
- git, curl, a C and C++ compiler, make, and cmake are present if anything is built. Node is present if the Studio frontend is built from source. bubblewrap is present if tool calls should stay sandboxed.
- Do not install the oneAPI Base Toolkit for this path. If it is already installed, do not source setvars.sh in the Studio shell. The wheel’s own runtime is the one that must see the card.
- A machine with one Intel GPU uses ONEAPI_DEVICE_SELECTOR=level_zero:0. This workstation has two. Device 0 is the desktop Arc, so Studio is pinned to level_zero:1. Copy that pin only after sycl-ls, or the torch probe, shows the training card at that index. studio-pin.sh on this machine hardcodes device 1 for that reason.
Names the installer may print, and the Fedora package that corresponds. None of the devel packages were installed for this run.
Installer text Fedora 44
libcurl4-openssl-dev libcurl-devel. Not installed. The prebuilt llama.cpp bundle did not need it.
build-essential gcc, gcc-c++, make. Already installed.
bubblewrap bubblewrap. Already installed.
Why the Unsloth Intel page I quoted on post above was not what worked
Fine-tuning LLMs on Intel GPUs with Unsloth still tells Linux users to install the extra intel-gpu-torch290. In this checkout that extra is torch 2.9.0+xpu, torchvision 0.24.0+xpu, and pytorch_triton_xpu 3.5.0. The same pyproject.toml has newer Intel extras, and the newest of those, intelgputorch2120, stops at torch 2.12.0+xpu, triton-xpu 3.7.1, and torchvision 0.27.0+xpu. None of them is the current stable wheel.
Every one of those extras also points bitsandbytes at a continuous-release preview wheel whose filename says 1.33.7 and whose metadata says 0.50.3.dev0. uv refuses that wheel. Do not set UV_SKIP_WHEEL_FILENAME_CHECK. Installing the extra uninstalls the working torch packages and then dies on the preview wheel. That happened once on this machine. The repair below is what put the environment back.
PyTorch’s own Intel page is the current binary install. Getting Started on Intel GPU (documentation set 2.14, last updated 21 August 2026) says:
pip3 install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/xpu
That index, checked again on 4 October 2026, still ends at torch 2.14.1+xpu. torch 2.14.2+xpu and torch 2.15.0+xpu are not on it. The nightly index (https://download.pytorch.org/whl/nightly/xpu) was not used.
Intel GPU support has been inside upstream PyTorch since 2.5. The device API is torch.xpu, and the SYCL runtime ships in the official wheel. That did not move the GPU build onto PyPI. The 2.14 page still installs from the XPU index above, in the same way a CUDA build comes from its own index. pip install torch without that index is a different build. The +xpu suffix is how this environment is identified.
The same page says to install the Intel GPU driver, and to skip Intel Deep Learning Essentials when installing the binary wheels. The wheels download their own runtime. This install did not source /opt/intel/oneapi/setvars.sh. Mixing that environment with the wheel’s libraries is how a wheel stops seeing the card. Deep Learning Essentials was not installed by hand, and nothing was compiled from SYCL source. Intel Extension for PyTorch stopped its own releases after 2.8 and pointed users at upstream PyTorch. Its repository was kept only through March 2026. This install does not import it.
The Studio installer does not detect an Intel GPU. If UNSLOTH_TORCH_INDEX_FAMILY is unset, install.sh selects a CUDA index, then a ROCm index, then the CPU index. The log line gpu none (CPU-only) is that NVIDIA/AMD label. It is printed on an Intel-only machine even when the torch index is the XPU URL. The line that matters is the next one: the index URL.
Inside this checkout, install.sh also caps the XPU torch install below 2.11. That cap is why the installer itself landed torch 2.10.0+xpu. The cap is older than both the checkout’s 2.12 extra and the 2.14.1 wheel. After Studio is installed, replace the torch stack from the XPU index. Do not re-run an intel-gpu-torch* extra to “match the guide”.
Studio install
Work in $HOME/local-ai/unsloth. Read install.sh before running it. Do not pipe curl into a shell. Python 3.12 is required here because Studio accepts 3.11 up to, and not including, 3.14.
git clone GitHub - unslothai/unsloth: Local UI to run and train LLMs and diffusion models. Supports GGUF, MLX, Qwen3.8, DeepSeek-V4, MiniMax-H3, Gemma 4, FLUX and more. · GitHub upstream
cd upstream
export UNSLOTH_STUDIO_HOME=“$HOME/local-ai/unsloth/.studio”
export UNSLOTH_SKIP_AUTOSTART=1
export UNSLOTH_TORCH_INDEX_FAMILY=xpu
export UNSLOTH_LLAMA_CPP_BACKEND=cpu
export ONEAPI_DEVICE_SELECTOR=level_zero:1
unset ZE_AFFINITY_MASK
./install.sh --local --python 3.12 --isolated-uv-cache
UNSLOTH_LLAMA_CPP_BACKEND=cpu is only the GGUF chat bundle. The published llama.cpp builds are CPU, CUDA, ROCm, and Vulkan. There is no XPU bundle, and a Vulkan bundle would open a render node. Fine-tuning goes through the PyTorch XPU wheel, not through that binary. The installed bundle is under .studio/llama.cpp.
–local keeps Studio in UNSLOTH_STUDIO_HOME. That path wins over ~/.unsloth/studio. With the variable set, the installer does not append a shell rc file and does not install a desktop entry. UNSLOTH_SKIP_AUTOSTART=1 and a non-interactive stdin stop the autostart prompt. Non-interactive runs need stdin from /dev/null.
Current XPU stack
Run this in the Studio virtualenv after install.sh finishes. Point uv at the Studio cache so the wheels do not land in ~/.cache/uv. The first attempt on this machine did not fully honour --isolated-uv-cache: about 6.8 GiB of the older 2025.2 runtime, a torch XPU library, and Triton were written under ~/.cache/uv around 22:19. Those cache files were deleted after the virtualenv no longer needed them. The virtualenv itself is under .studio.
export UV_CACHE_DIR=“$HOME/local-ai/unsloth/.studio/cache/uv”
PY=“$HOME/local-ai/unsloth/.studio/unsloth_studio/bin/python”
uv pip uninstall --python “$PY” triton pytorch-triton-xpu
uv pip install --python “$PY” --index-url https://download.pytorch.org/whl/xpu
‘torch==2.14.1+xpu’ ‘torchvision==0.29.1+xpu’ ‘torchaudio==2.11.0+xpu’
‘triton-xpu==3.8.0’ ‘torchao==0.18.0+xpu’
uv pip install --python “$PY” --no-deps ‘bitsandbytes==0.50.2’
uv pip install --python “$PY” ‘torchcodec==0.12.0’
Pin the versions the index resolved on the day you install. On a later day, resolve again from the same index instead of copying 2.14.1 forever. Stay on the stable index. --no-deps on bitsandbytes matters: a normal PyPI install can replace the XPU torch with a CPU build. Do not install the preview wheel URL from pyproject.toml.
Stock triton and the older name pytorch-triton-xpu both install a triton package. Remove them so only triton-xpu owns that import. torchcodec 0.10, which the installer chose for torch 2.10, warns on torch 2.14 and asks for 0.12. 0.12.0 installed without changing torch. It is not the training device.
Confirm, before any GPU call, that the versions end in +xpu and that torch/lib/libtorch_xpu.so exists.
Choosing which GPU is used
This machine has two Intel GPUs. The desktop Arc is PCI 8086:e20b, card0, renderD128, Level Zero device 0. The Arc Pro B70 is PCI 8086:e223, card1, renderD129, Level Zero device 1. The shared-memory vLLM containers mount all of /dev/dri and have both render nodes open. Studio must not take the desktop Arc as well.
bash studio-pin.sh writes sitecustomize.py into the Studio virtualenv. Every interpreter there sets ONEAPI_DEVICE_SELECTOR=level_zero:1 and deletes ZE_AFFINITY_MASK, including when the parent shell selected device 0. After that filter, device 0 is the Arc Pro B70 and the device count is 1. Do not also set the affinity mask. Once the selector has hidden the desktop Arc, mask 1 hides the B70 too.
export ONEAPI_DEVICE_SELECTOR=level_zero:1
unset ZE_AFFINITY_MASK
unset LD_LIBRARY_PATH
export TORCH_HOME=“$HOME/local-ai/unsloth/.studio/cache/torch”
export TRITON_CACHE_DIR=“$HOME/local-ai/unsloth/.studio/cache/triton”
export HF_HOME=“$HOME/local-ai/unsloth/.studio/cache/huggingface”
export XDG_CACHE_HOME=“$HOME/local-ai/unsloth/.studio/cache/xdg”
“$PY” -c ‘import torch; print(torch.version); print(torch.xpu.is_available()); print(torch.xpu.device_count()); print(torch.xpu.get_device_name(0))’
The first import writes a compiler cache. With XDG_CACHE_HOME set, that cache appeared at .studio/cache/xdg/neo_compiler_cache and not under ~/.cache. If the import fails, stop. Do not source setvars.sh as a first fix. A failure means the wheel runtime and the driver disagree, and sourcing system oneAPI is one way to make that worse. The four cache exports above are the probe that was run. Weight files use the layout in the weights section.
The generated launcher sources .studio/share/studio.conf. The shim does not, which is why the virtualenv pin exists. studio-pin.sh forces the selector in that file rather than leaving a parent value in place. A reinstall deletes the pin. Run the script again.
export ONEAPI_DEVICE_SELECTOR=level_zero:1
export UNSLOTH_STUDIO_PORT=8910
unset ZE_AFFINITY_MASK
Starting the server
Shared-memory, which is a project I use, listeners on this machine, and the ports reserved for it even when nothing is bound:
Port Service
5432 postgres-vector
7474, 7687 neo4j-memory
8070, 8071 reserved embedder and reranker binds
8090 vllm-rerank
8091 vllm-embed
8092 reranker shim
8765 telemetry monitor
8888 shared-memory gateway
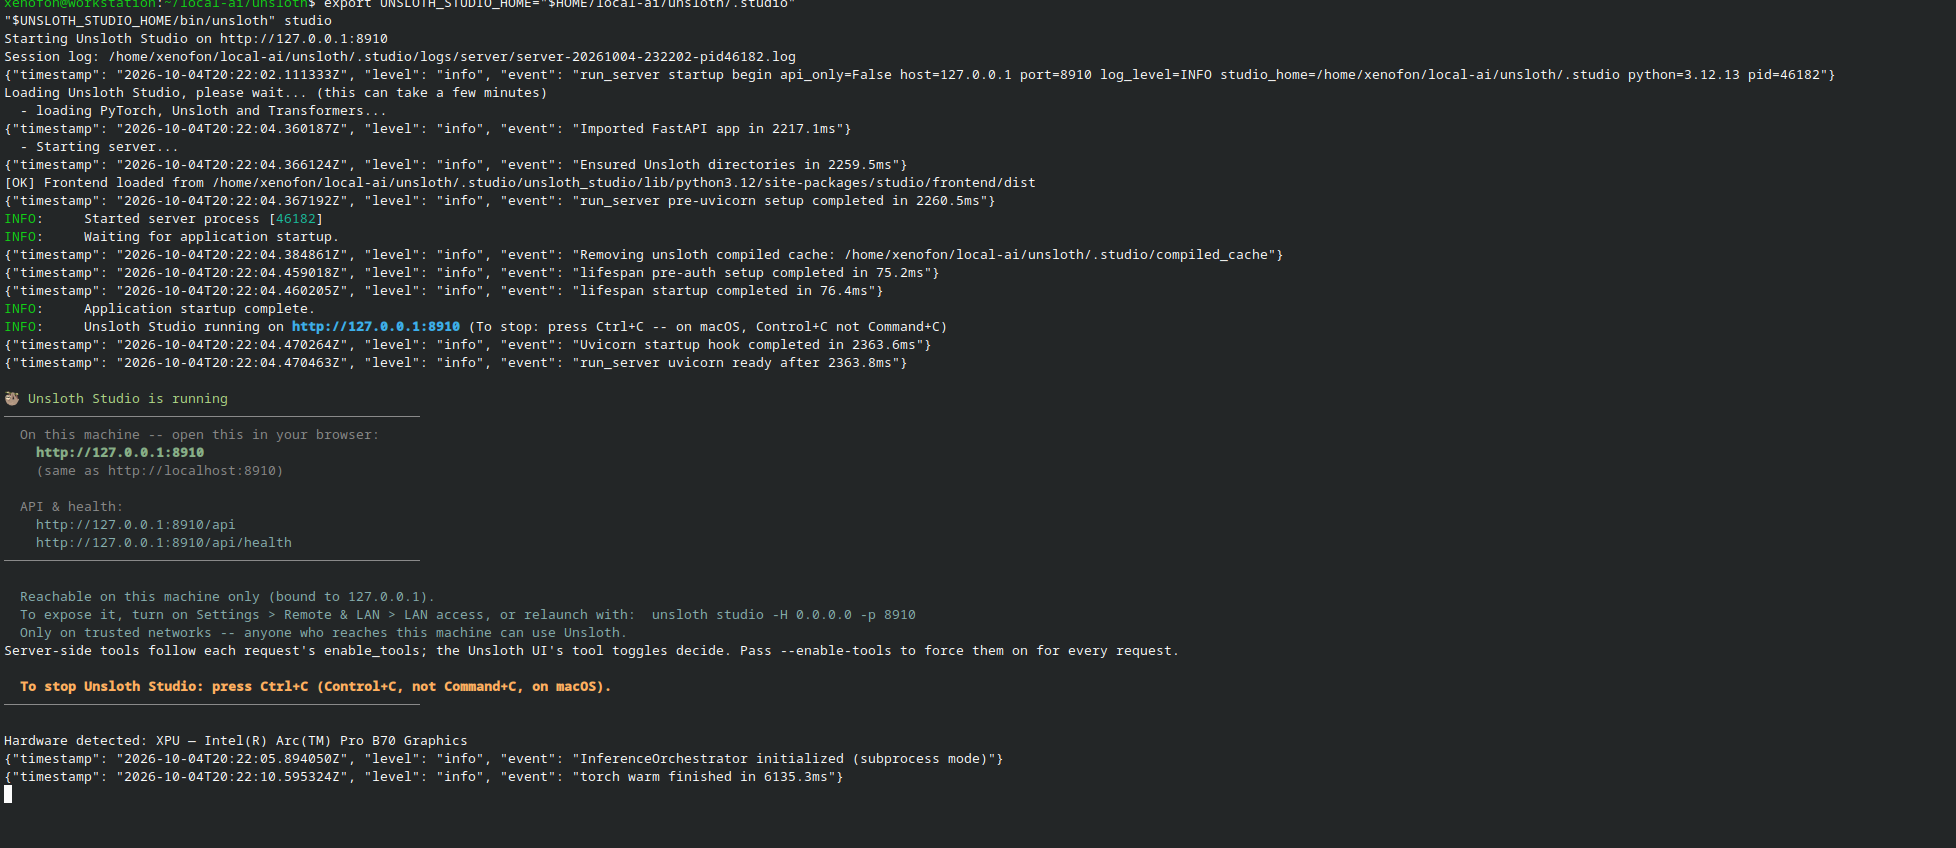
So I set a studio-pin.sh which sets the Studio default, the launcher base, and the client’s fallback URL to 8910. This is something I do for my needs, you may not have to. Launch with no port flag;
export UNSLOTH_STUDIO_HOME=“$HOME/local-ai/unsloth/.studio”
“$UNSLOTH_STUDIO_HOME/bin/unsloth” studio
Studio answered HTTP 200 on 127.0.0.1:8910. The socket was bound only to that address. The gateway on 8888 was still the same process, and Studio was then stopped. Separately, a parent environment that selected Level Zero device 0 and set an affinity mask still produced one device, the Arc Pro B70.
What this procedure does not do
- It does not compile a SYCL backend or a from-source PyTorch.
- It does not install Intel Extension for PyTorch or IPEX-LLM.
- It does not source system oneAPI.
- It does not use the nightly XPU index.
- It does not retarget the shared-memory containers. Those two vLLM containers still have both render nodes open. Studio no longer selects the desktop Arc.
- It does not download a model or start a fine-tune. The weight directories are empty until a model is asked for.
- It does not move directories that were already on the large volume.
- It does not publish Studio beyond loopback.
The 2.14 page validates Arc B-series on Windows 11 and Ubuntu 24.04 and 26.04. This host is Fedora Linux 44, with the packages in the host section. The 2.14.1+xpu wheel still enumerated the Arc Pro B70.