Not sure where to put this. Still new. FYI i could not get this version to run effectively on dual sparks. Claude Code and Codex said there wasnt enough room for KVM. Just to save you all a few hours of time. Im installing it for use with Hermes Agen on an old Dell XPS with Ubuntu.
LT
2 Likes
I wish I had 4 sparks, but it’ll probably still only be ~10t/s. Anyone got it running on 4 sparks? and if so what speed?
1 Like
That is way too tight even on Q1. Just not worth it. You should consider minimax m3 which would comfortably fit on there at q3.
1 Like
Apparently the answer was 30t/ and concurrency 4 at aggregate 60t/s for nvfp4 glm5.2 full not reap.
I got reap going 60t/s on 4x6000s
3 Likes
How did you fit nvfp4 on 4x600s? There is 47x10gb files. Are you offloading? Can’t if your getting 60t/s. Does it not load every single file?
Oh nm, i assume you used more cards on the FUL NVFp4
Testing “GitHub - JustVugg/colibri: Run GLM-5.2 (744B MoE) on a 25GB-RAM consumer machine — pure C, zero deps, experts streamed from disk. Tiny engine, immense model. 🐦 · GitHub”
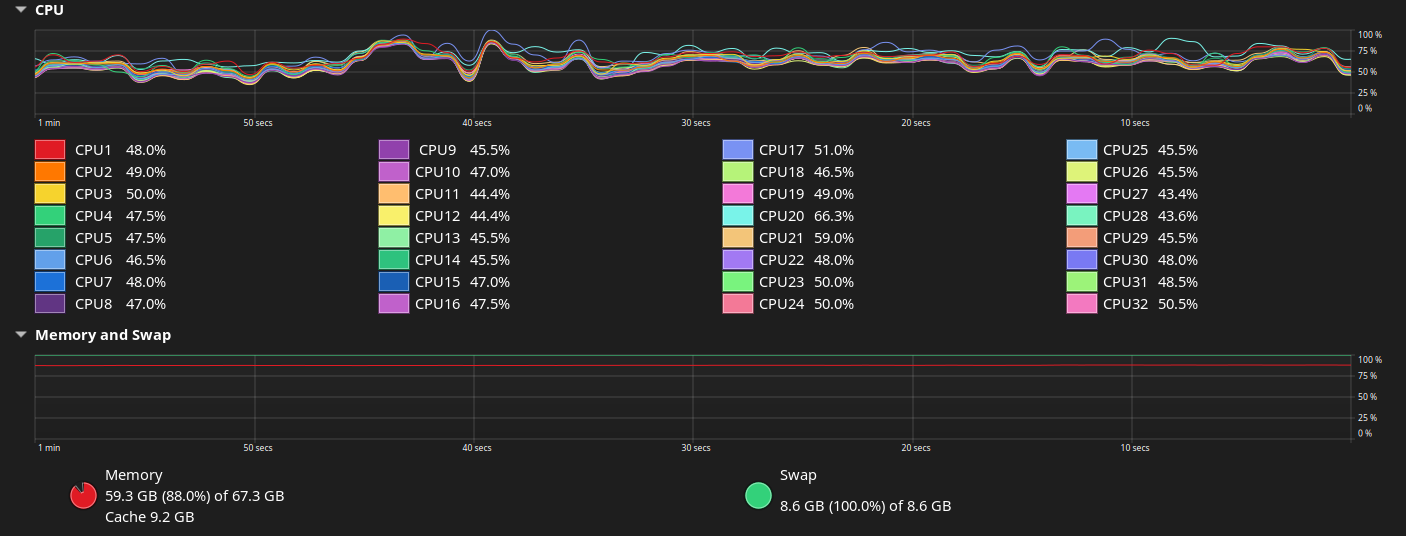
370GB quant loaded in RAM, as a subagent, single tasker
EDIT: Not optimized to remian at 9.9GB, quickly decided to use over 30GB of RAM on a long response prompt.