Ryzen AI Halo - USB4 Clustering with RDMA - Testing Notes

Since you’re here — I ran OdinLink-Five on two Strix Halo boxes (EVO-X3 + ProArt PX13, Ubuntu 26.04, kernel 7.0.0-29, one USB4 cable) and it worked well once running: +20–26 % tokens/sec on vLLM TP=2 over TCP-over-Thunderbolt, across gemma-4-E2B, gemma-4-12B and Qwen3.6-35B-A3B. RCCL loaded the plugin straight from NCCL_NET_PLUGIN and reported Using network ODL_TB5. It also coexisted cleanly with thunderbolt-net the whole time — bound as a separate XDomain service, and our IP link never dropped a packet across ~10 load/unload cycles.

Four things that cost me time getting there, in case they’re useful:

1. The documented module parameter doesn’t exist. README and INSTALL say ring_size=; the code exposes odl_ring_size (plain module_param, no _named alias — unlike loopback). Passing the documented name gives unknown parameter 'ring_size' ignored and silently keeps the 4096 default, which wants a 16 MiB coherent DMA allocation. Ubuntu ships CmaTotal: 0, so probe dies:

odl_tb5: failed to alloc TX DMA buf 0 (16777216 bytes)
odl_tb5: DMA buf alloc failed for index 0: -12
odl_tb5 0-2.1: probe with driver odl_tb5 failed with error -12

odl_ring_size=1024 probes first try. This one makes the driver look completely broken on a stock distro — a module_param_named(ring_size, ...) alias, or an -ENOMEM fallback to a smaller ring, would save the next person a long evening.

2. The rdma-core provider can’t load on current distros. It builds libodl_tb5-rdmav34.so, but libibverbs loads providers matching its own ABI — rdma-core 61 wants rdmav59. The failure is quiet unless you look:

libibverbs: Warning: couldn't load driver 'libodl_tb5-rdmav59.so': cannot open shared object file

Also no /etc/libibverbs.d/*.driver is shipped, so even with a matching ABI nothing would find it. Building the provider through rdma-core’s own rdma_provider() macro gets the right ABI automatically on whatever host it’s built against.

3. loopback=1 doesn’t work — the advertised no-hardware path. With loopback=1 and no peer, SEND ioctl, odl_tb5_open() and RCCL listen() all fail with EINVAL (3 of the suite’s tests). The same binaries pass every one of those against a real peer, so it’s specific to loopback. GET_PEER also reports speed=0 Gb/s there vs a correct 20 Gb/s with hardware.

4. Plugin symbol versions are stale. RCCL logs ncclOsDlsym(ncclNetPlugin_v11/v10/v9/v8) failed: undefined symbol before falling back to an older plugin ABI that works. Fine today, but it’ll break whenever RCCL drops the legacy entry point.

Minor: the RCCL plugin advertises speed=80000 regardless of link — on our TB4 cable GET_PEER correctly says 20 Gb/s, so the two disagree.

Happy to re-test any of this if you push changes.

I seem to be able to bring up the second lane in software, but it’s a bit baffling, as that gets us from 10 to 20 gigabit. In software it looks like to me like a mailbox setup.

It’s interesting you say it’s grandfathered because og tb3 was 2 lanes required (one tx one rx) 20/20 and was advertised as 40g. Then it was also 40g 40/40 later when it went to 4 lanes. I think this was only for pcie/dp mode on 32gbps pcie bandwidth and they “forgot” about the host to host mailbox and never updated it.

Usb4 v2 and tb5 changed this part a fair bit and better bandwidth is more reachable there. The n5 max has the tb5 chipset in strix halo which is interesting and easier to get better perf out of.

Bottom line is I don’t think usb4/tb4 will ever be better than 20/20 and that’s bypassing thunderbolt_net

  • Node A: usb4_rdma0 (GUID …53) + usb4_rdma1 (…54), both ACTIVE/LinkUp
  • Node B: usb4_rdma0 (…53) + usb4_rdma6 (…54, domain=1 naming), both ACTIVE/LinkUp
  • GID idx 1 = IPv4-mapped ::ffff:0ac8:0201 (A) / ::ffff:0ac8:0202 (B) from ardma0
    (NOTE: with roce_netdev=ardma0 the mapped GID is at INDEX 1, not index 2 as with the old thunderbolt0 layout. perftest picks GID index 1.)

RESULTS (perftest 6.29, RC, -d usb4_rdma0/1/6, MTU 4096, eth-IP CM)

Single-rail ib_write_bw 1M (n=1000):

  • A->B usb4_rdma0: 15.84 Gb/s avg/peak
  • B->A usb4_rdma0: 16.61 Gb/s avg/peak (server=A, client=B → A’s eth IP)
  • A->B usb4_rdma1 (rail2; B side usb4_rdma6): 15.75 Gb/s avg (15.83 peak)
    ib_write_lat 2B (n=10000) A->B usb4_rdma0: avg 8.33us (min 7.39, 99% 9.98)
    CONCURRENT dual-rail (both rails at once, rail1 on -p 18516 to avoid port clash):
  • rail0 usb4_rdma0: 3.32 Gb/s avg (9.24 peak) ← shares link with rail1
  • rail1 usb4_rdma1/6: 3.31 Gb/s avg (7.82 peak)
  • AGGREGATE ~16.6 Gb/s concurrent (vs 7.82-9.24 single) → both rails share the same 1-lane 20Gb/s link; no additive bandwidth, as expected with 1 cable.

So this is bypassing thunderbolt_net but we’re still in that 15-20 gigabit territory because host-mode appears not to be designed to do more than 20 gigabit each way on a single usb4 cable just generically in host mode NOT with the thunderbolt_net limitation by itself.

Module load config for 2 rails (verified; also in cont. 15)

sudo ip link set thunderbolt0 down # frees NHI hop 1
sudo modprobe -r rdma_ucm thunderbolt_ibverbs
sudo modprobe thunderbolt_ibverbs profile=linux_perf bind_services=1
allocate_rings=1 start_rings=1 negotiate_native=1 enable_tunnels=1
register_verbs=1 roce_netdev=ardma0

It should be. Plain data transfer for host-2-host / cross domain and everything else is pure software, like the USB4Net ethernet emulation.

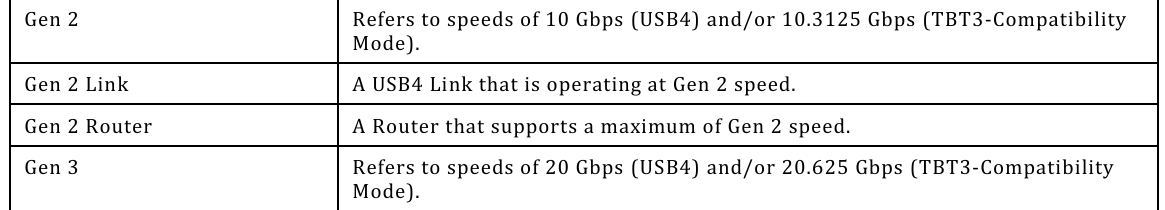
This gets tricky, as TB3 specs are not public, we only have Intel’s marketing statements. But I would bet, that single-lane operation for normal host-device situations was also never allowed for TB3 certification. The 20G speeds that were the minimum certifiable TB3 speed where using setup with Gen 2 speeds (10Gbps per lane) with dual lanes. Same as the minimum valid USB4 controller. They start with 10G per bidirectional lane for “20Gbps” connections. And upgrade to 20 Gbps per lane (Gen 3) for “40 Gbps” connections. Because your single-lane limit is different from the normal differences between 20G and 40G connections.

image

That is how Gen 2 connections can be made with lesser cables (which - fun fact - actually includes Gen 1 / “USB 5Gbps” cables as well). So if you start using such a cable for cross-domain links with your systems you should notice that there would be a max. bandwidth of 10Gbps in each direction.

The “grandfathered in” would be because TB1 had no bonding. The 2 lanes operated independently. That’s why it only fit 4xHBR1 DP tunnels (~8.6 Gbps), but 2 of them in total. Only with TB2 came bonding and room to fit a single 4xHBR2 (17.3 Gbps) DP tunnel. That’s why USB4 still has those 2 “lane adapters” per port, that were originally conceived to operate independently.

USB4 already removed that independent operation of TB1 explicitly. If lanes cannot be bonded, Lane 1 must be disabled so that nobody ever has to deal with distributing data across 2 separate lanes (other then the hardware, but that is internal. When bonded, all data gets sent to lane adapter 0 and it internally uses both lanes).

But for historical reasons and compatibility to TB3 we just need to start out with establishing 2 separate single-lane links and will then bond them together with an opportunity to fail bonding and fall back to single-lane operation.

So normal host-device operation is always dual lane. It just can happen at either Gen 2 or Gen 3 speeds.

Cross-domain usage is the only place where USB4 allows a controller that is required to support bonded dual lane operation with a device to only support single-lane.

For Gen 4 all of this was redesigned to allow it to adjust how many wire-pairs are dedicated to each direction on the fly and without interruption. So there is no more explicit bonding phase and no possibility for a controller to connect lanes but refuse bonding. So that exception for cross-domain uses is also gone.

I don’t remember ever seeing TB3 or USB4 be advertised with the sum of the bandwidths in both directions. There just were 2 speed grades 20Gbps and 40Gbps. But every "label” bandwidth number always assumes dual-lanes.

Overheads are giant, especially with the ethernet emulation. And it seems only very specific USB4 controllers can do dual-lane for cross-domain. But on reddit we saw a few people report > 20G iperf speeds with some Intel-CPU-integrated USB4 controllers. Like here: my proxmox cluster · GitHub , where they report ~27 Gbps in iperf3 off of a single USB4 networking connection.

It just seems that the AMD controllers and older external Intel controllers do not support that and thus fall back to that “grandfathered in” single-lane operation for cross-domain connections. And that is what is limiting to 20G max on top of everything else. Intel’s tbtools will show the link config and lanes for any kind of connection, even cross-domain ones that boltctl likes to hide.

I sadly, don’t have 2 Intel systems of the appropriate generations to reproduce this, but I have seen those > 20G numbers reported multiple times with different setups of multiple Intel systems of 11th gen or newer with those CPU-integrated controllers.

Maybe that is so fast, that then you would hit the wall of that mailbox system even with all the other advancements of replacing USB4net ethernet emulation. But still 40G cross-domain links are feasible when the controllers on both sides support it. It just was never mandated and never documented in any place I could find which controllers can do that…

I can also confirm usb4v2 is universally working fine at 80/80 (with overhead) with the emulated infiniband verbs.

One of the first amd minisforum to have thunderbolt skipped amds usb4 and out a thunderbolt chipset, rev3, in their hardware. That’s one that seems to be able to do 27-33gigabit host to host but not via thinderbolt_net ?

In my own testing it looked like AMDs own USB4 controllers might also have some bottlenecks in sending direction (of that mailbox), or the software side setup is very suboptimal. Because between a 12th gen USB4 controller and Strix Point I am seeing iperf3 bandwidths of up to 18 Gbit/s completely out of the box, sending from 12th gen to Strix Point. But in the other direction its WAY slower.

In this, the receiving side is currently running Windows but I tried in the past, and it just seems AMD’s USB4 controller is tx bandwidth limited. Or at least with the mailbox setup that linux chooses.

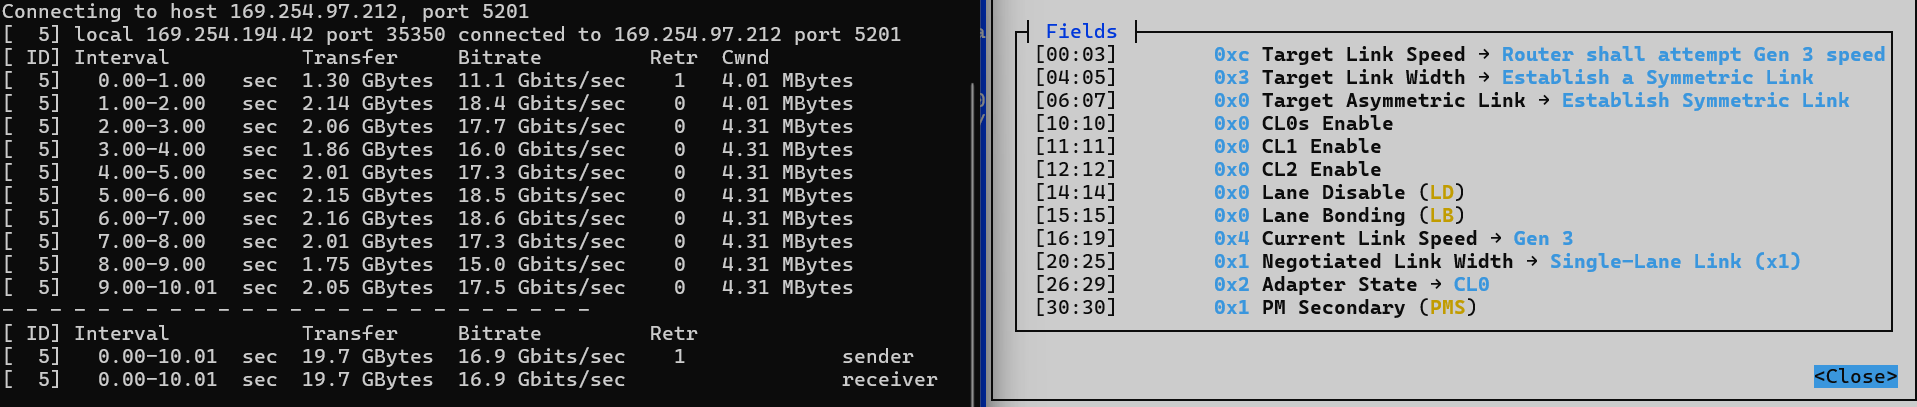
Screenshot also shows that this is still on a Gen 3x1 (so single lane) link, so with a max. USB4 bandwidth of 20G in each direction. So unless we hit other bottlenecks as well, finding a combination that does go dual lane should be able to do more…

Sadly boltctl and Windows’ debug tools hide the link config of cross-domain links, even though it is there and available…

Edit: I have now used the tbtrace utility and I can see the 12th gen host switching from “establish 2 single-lane links” to “establish symmetric link” and then polling the resulting state for 70% of my trace log. But then then it rechecks the interdomain-properties with the other side and finally gives up and issues a lane-disable for the 2nd lane. So its just trying and waiting and since it does not happen, we stay on 20G on a single lane.

1 Like

Hey, since you have worked on this, what happened to 8 lane mode? That was a thing since the USBC connector was double sided.

Ethernet shows significant asymmetry; I didn’t have time to investigate that but it’s not super unexpected either given NIC/driver differences.

@wendell This is likely the result of some form of power savings. At least it was in my case - before sorting out power saving settings my latency was asymmetric. After changing that Ethernet over USB network cards connection average ping 0.578ms → 0.145ms in both directions.

I was testing different ways to connect two PCs with minimal latency for a project of mine (-sm split for MoE LLMs on llama.cpp). My main focus was elsewhere, so I’ve got just avg latency for ping -c 120, probably should have also noted mdev.

3 test networks:

A - PC1 → RTL8153 1GbE (USB) → Unmanaged Switch(GS305) → RTL8153 1GbE (USB) → PC2 over Cat6 cable

B - PC1 → RTL8125 2.5GbE (built-in) → RTL8125 2.5GbE (built-in) → PC2 over Cat6 cable

C - PC1 → ConnectX-3 (pcie) → ConnectX-3 (m.2 → pcie adapter) → PC2 over DAC cable

Results (in ms):

A B C
base 0.578 2.268 0.355
+ disabled c-states 0.239 1.471 0.070
+ disabled EEE 0.156 2.798 EEE not supported
+ disabled aspm 0.145 0.083 0.052

I don’t remember if disabling Energy Efficient Ethernet caused latency spike for RTL8125 , or if it was an artifact of large mdev (which was large until aspm was disabled).

I’m still in the process of testing RoCE and Soft-RoCE, but it looks like in my case choosing between TCP and RDMA provides much smaller benefit then optimizing power settings.

My ‘tuning’ commands - changing power settings does not require restart, so it can be used by a custom service to enable power saving mode if pc is idle to make energy bill happier.

# disable EEE
ethtool --set-eee eno1 eee off

# disable aspm
echo performance | sudo tee /sys/module/pcie_aspm/parameters/policy
for dev in /sys/bus/pci/devices/*; do
    if [ -d "$dev/link" ]; then
        [ -f "$dev/link/l0s_aspm" ] && echo 0 | sudo tee "$dev/link/l0s_aspm" > /dev/null
        [ -f "$dev/link/l1_aspm" ]  && echo 0 | sudo tee "$dev/link/l1_aspm" > /dev/null
    fi
done
for dev in /sys/bus/usb/devices/*; do
    if [ -f "$dev/power/control" ]; then
        echo on | sudo tee "$dev/power/control" > /dev/null
    fi
done

# disable c-states
sudo  sh -c 'exec 3>/dev/cpu_dma_latency; printf "\x00\x00\x00\x00" >&3; sleep 9999'
1 Like

Thank you for your ethtool command ethtool --set-eee eno1 eee off, my link light was flapping on and off without it running the latest CachyOS.

Aaand, how fast one can turn out to be wrong…

I just rebooted with a new kernel update on my AlmaLinux system and now, I actually get a dual-lane connection from 12th gen Intel to AMD Strix Point (Strix Point still running Windows).

Highest bandwidth 12th gen → Strix Point: barely 22.7 Gbit/s, but > 20 Gbit/s.

Strix Point → 12th gen still at 11.7 Gbit/s max.

No idea what actually changed, I mainly rebooted to get the debug logging of the thunderbolt kernel modules on to get better logging of why and when it fails the bonding and now it works.

So, I am happily wrong: appearently, Strix Point CAN do dual lane inter-domain. It just seems super finicky, because this is the first time its working. Strix Halo controllers may be slightly different from the Strix Point ones, as they have UHBR20 support on Strix Halo, but only UHBR10 with Strix Point. Though unsure if that is a GPU-side limitation or an actual small difference in USB4 controller hardware.

I can also confirm, Windows will stick to the 20Gbit/s rating of the virtual network adapter, so that number sadly seems hardcoded and cannot be used to quickly figure out what connection config one got and if one is hitting software bottlenecks or hardware bottlenecks.

That is a new one for me, I have not heard anybody speak of anything like that.

Full-featured USB-C is designed to have 8 high speed conductors, but they are in those 4 differential pairs. And symmetric USB4 connections are using 2 wire-pairs in each direction. So that is already using all of them. Only the single-lane config would leave half of them unused.

If one goes the more crazy route of the now defunct VirtualLink from Nvidia, one can maybe repurpose the USB2 wire pairs for another 2 wire-pairs, but I am still not getting to 8 (Nvidia used this to put 2 USB3 wire-pairs onto those USB2 pins to keep all 4 high-speed wire-pairs available for full DP with 4 lanes).

But that is very much not standard, as a) the USB2 wires are not normally designed for those higher speeds and also because while the USB2 pins are symmetric and exist double, the conductors in a USB-C cable are not (socket needs to support both sets of USB2 wires, but is allowed to short both sets together or switch between them, the cable is only supposed to have the one wire-pair on the primary sides of its connectors and other side be unconnected).

So I do not know see, how 8 wire-pairs, let alone lanes in the USB sense (meaning bidirectional) are possible. If I had to guess, you only get to 8 “whatever” with some creative counting and throwing all different wire-types together. Or that was just the wire-count. But everything high-speed is done in differential pairs anyway…

The MS-S1 by minis forum has TB5 onboard you can get about 40/40, 66gbps is technically the “limit” or “peak” but I havn’t been able to reach it.

1 Like

TB5 has the ability to do 3 lanes in one direction and only 1 in the other, but this is reserved for DP only and video, you could find a way to hack it by sending fake data over the wire to trick the chip and cable but I doubt it will stick.

While DP is the most prominent case and current chips won’t have enough bandwidth on other things alone, it’s about the bandwidth reservation.

Also, it’s not the chip you need to trick, that decision is the connection managers. So just a change to the Linux driver, where you can actually see the threshold of reserved bandwidth for when it switches.

But also, the USB4 spec forbids asymmetric connections for inter-domain / host-to-host connections.

This looks interesting I have not had a chance to try it yet but I will today: Feat/write striping: Stripe one QP across all rails, and fix credit loss and ACK storms on native rails by neuhaus · Pull Request #78 · hellas-ai/thunderbolt-ibverbs · GitHub

I compiled the above pull request, My evo x2 to evo x3 USB4 link did not get any faster, I’m stuck at 10Gbps each direction, BUT it does seem to be much more reliable. Been running a day straight without dropping anything. Unfortunately I don’t have another usb4 port on the x3, I was kinda hoping that my single usb4 port would start utilizing all of its lanes.

Kernel 7.2.7-200.fc44.x86_64

You can get to 20/20 maybe but 40/40 is right out. Thunderbolt not 5 was never designed to actually match the spec on paper it turns out. I haven’t had much luck either even with the full infiniband conversion.