havent asked it about tianenmen square or the uyghurs yet though 
honestly my company pays for deepseek and glm 5-3 flash models through API and this feels right up there, even the token rate is similar
Hate to say it, but the speed and performance difference between llamaserver and vLLM is kind of nuts, its way more intelligent with prompt caching etc, i’ve barely had to wait a second even on large prompts
Ok you know what? stretch goal:
Lets see if i can make an mxfp4 quant from the orcarouter version and mash it into the clavviger engine: https://www.youtube.com/watch?v=hFDcoX7s6rE
OK well its doing ….something, i have a feeling this will take a while
[AA] first layer took 9m55s; estimating 7h56m for 48 layers → finishes ~00:38:46
[AA] layer 0: 1539 modules (1516 with stats), 2 stage(s), capture 100.6s recapture 85.8s quant 234.8s fwd#2 74.9s io-wait 0.0s, E-moved 0, micro-batch 4
[AA] PLE table: 128 mmap’d shards x 2500012 rows (torch.bfloat16), scale no, gathered on CPU
See you gents tommorow
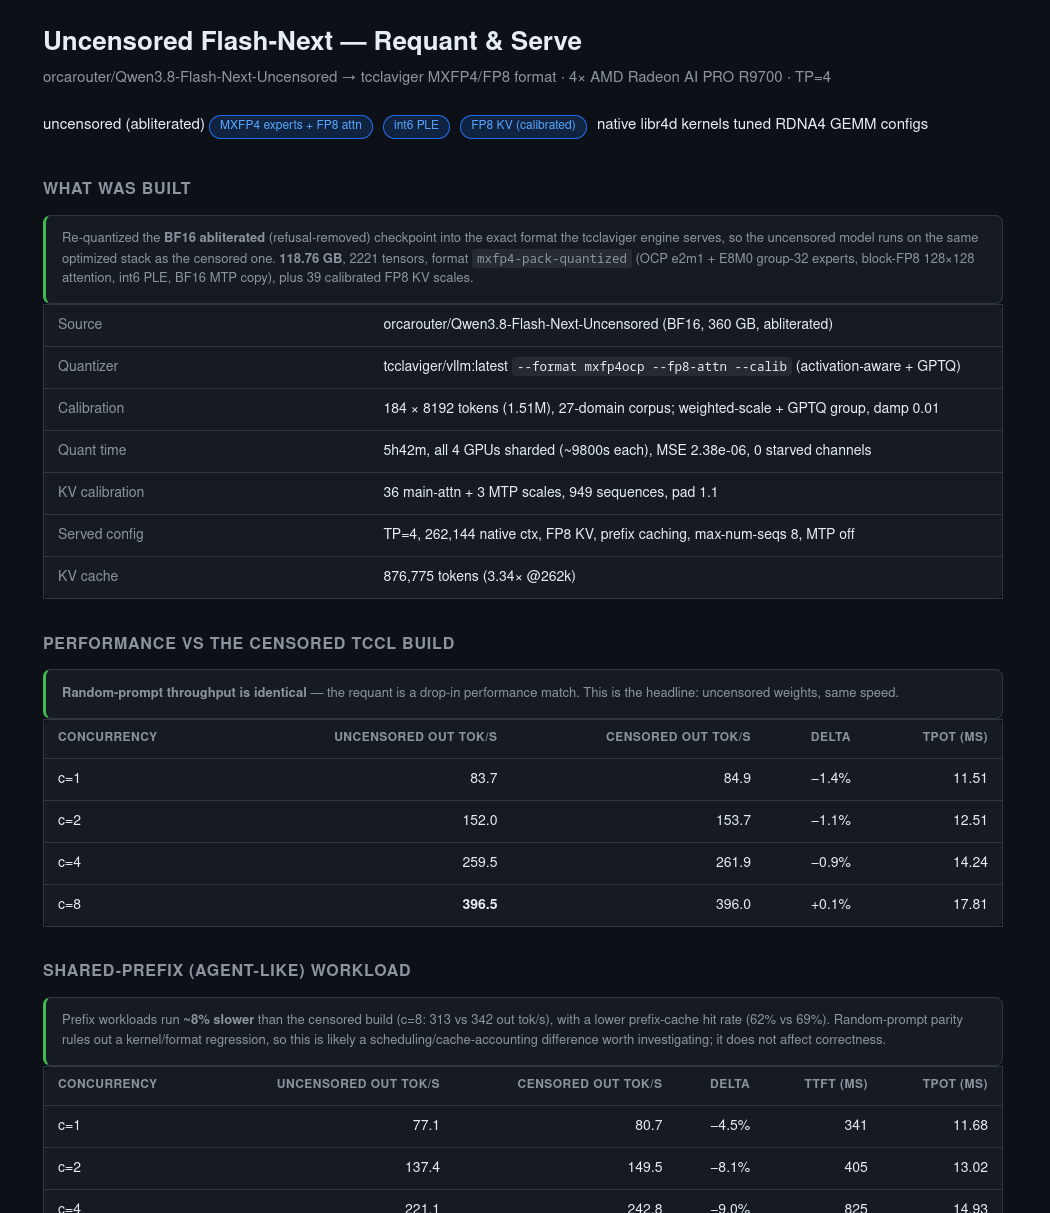
Stretchgoal accomplished XD, requanting isnt as hard as i though performance is near identical but now i can ask it about the uyghurs
I’m going to make a version of the qwen 3.8 27B next on mxfp4 using this engine too, i feel like i can finally use these cards to their true potential all of a sudden XD
If you install the ROCm Validation Suite, you can use the TransferBench tool to test the p2p speed GPU to GPU and GPU to CPU.
I didn’t have any issues getting p2p to work with Proxmox, but the speed was a lot lower than when running the same tests bare-metal.
Ah i know transferbench, thats how i know its still root-complex routing rather than the PCIE switch, now that VLLM and MXFP4 are sorted its my next target to fix 
1 Like
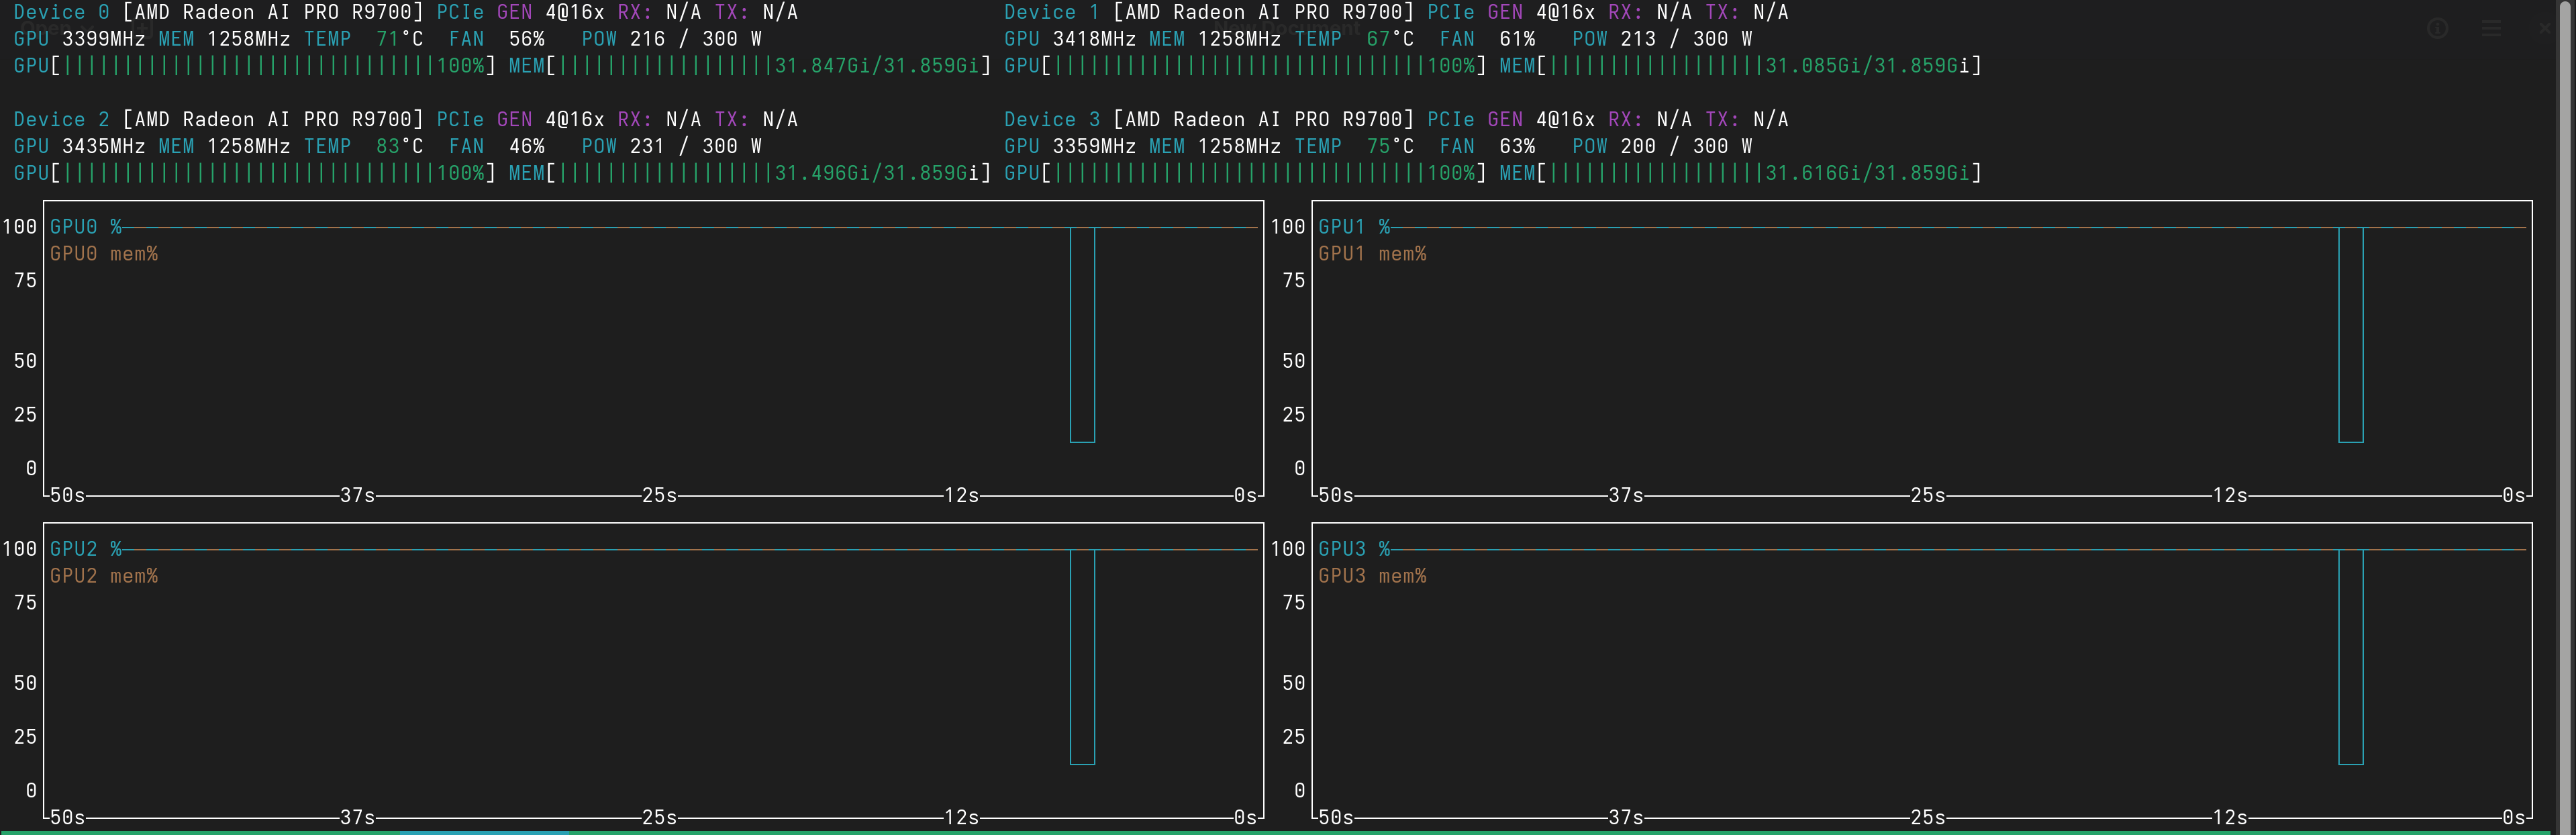
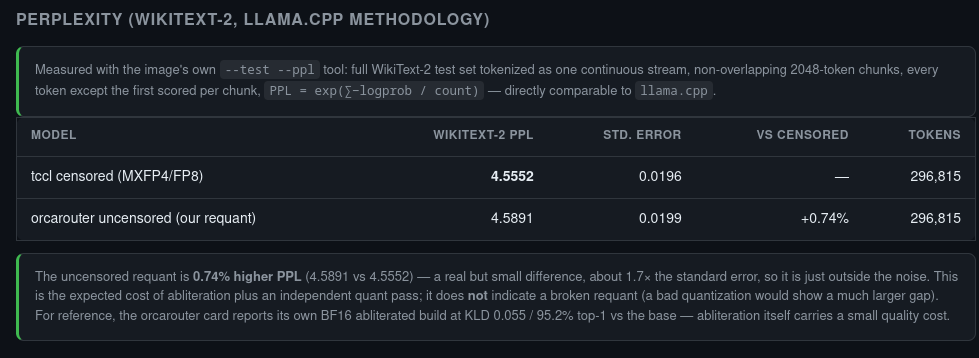
Chatterbox+WhisperLarge+qwen 3.8 flash next configured at C8 with an 850k shared context pool, I’m maxed to the hilt, Atleast i’m not leaving anything idle
AM4 ‘s bottlenecks really don’t bite as hard as i had initially thought if you plan around them properly
The AI Pro branding isn’t all bullshit it seems
Cool dropping –max-num-batched-tokens 8096 to 4096 gave me 300k extra context, did not know that, supposedly it makes large batches harder to prefill but i wonder why it afffects context cache so much?
@flockman
I’ve got this board (same switch chip)
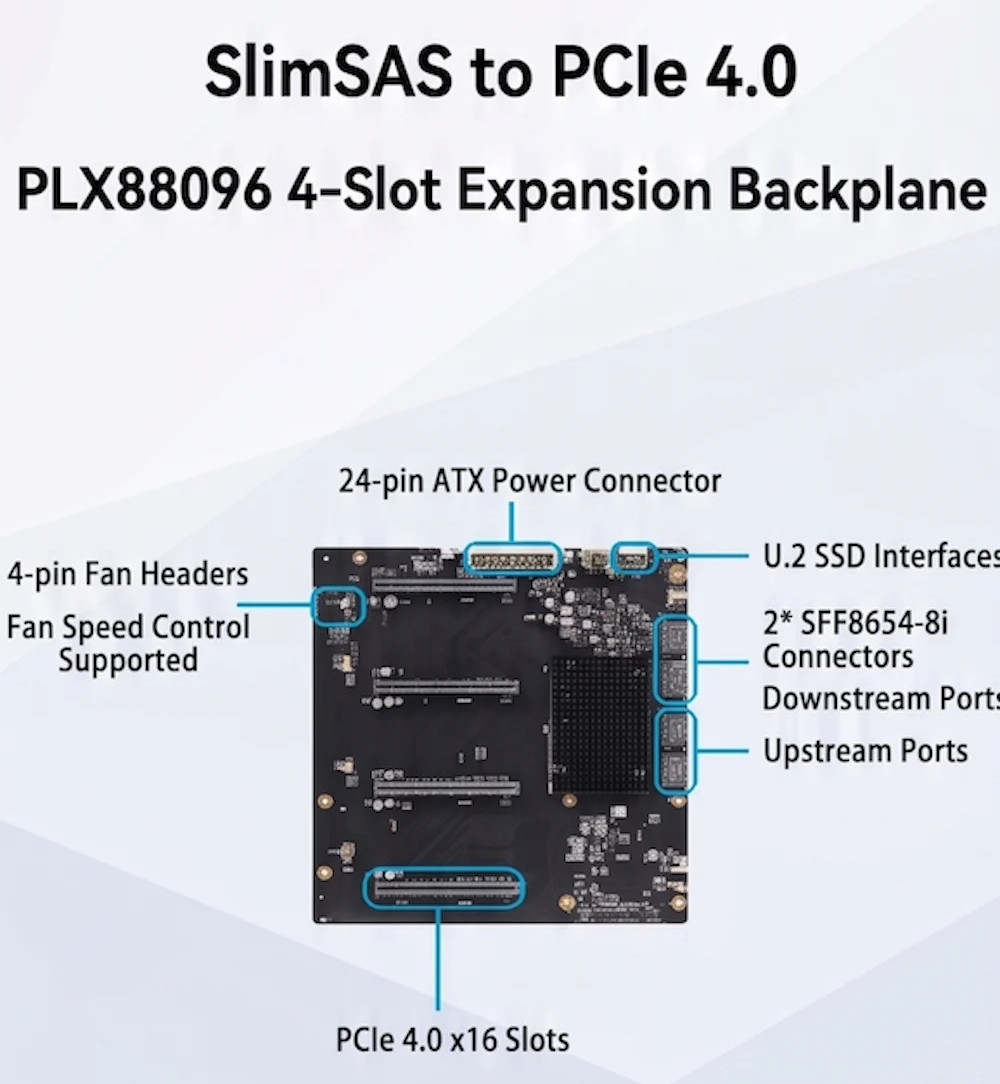
but GPUs (same like yours 2xR9700) are being downgraded to Gen3 speeds and stuck there.
(p2p works with acs quirk and kernel patched to make ReBAR usable, +30% pp and not much on tgt front compared to no p2p when on Gen3 host root ports)
Can you attach whole ‘lspci -vv’ output, please?
Are there any tips to make negotiate/force Gen4 speeds.
(host is Gen3 (difference from you), which is fine as long as it negotiates Gen4 for x8 NIC in switch slot, but for some reason it drops to Gen3 for GPUs).
I just posted a how to for radiance which may be of some value. It doesn’t need hardcore p2p bandwidth
I think clavviger VLLM actually is radiance behind the scenes
I’ll check it out thanks for the heads up
are you baremetal or behind Qemu?
proxlspcivv.txt (309.9 KB)
qemulspcivv.txt (57.0 KB)
I’ve attached my proxmox lspci for you and my qemu as seperate attachments
Also i was stuck at gen 3 for a bit as well, but a reboot and cold start cleared it and it hasnt popped back up since
most of my weirdness had to do with system heat buildup, so make sure theres a fan pointed at all the important bits
I’m going to try and see if i can get DFLASH working, mtp was kind of not worth it for qwen 3.8 flash-next but dflash looks like it might be
@flockman thanks for lspci dump, I’m so far bringing this up on bare metal, since i have spare rig for the toy.
Qwen 3.8 flash-next is a lot less toy-like than 27B was , whereas before it was mostly a home automation bot on 27B for me, i use the 180B for serious programming tasks, i can sick 8 subagents at 80-ish tk/s on them at decents contexts.
I think/hope you will be pleasantly surprised, i know i was XD