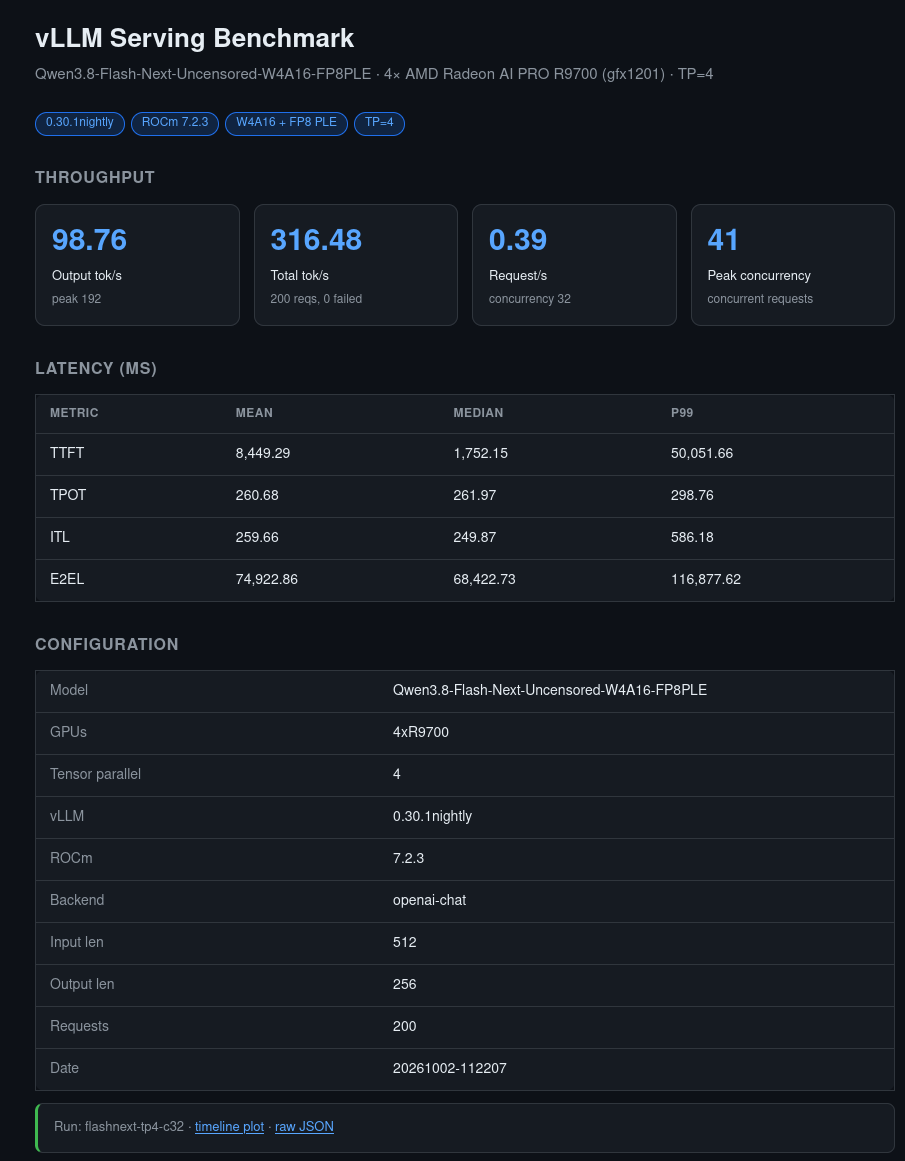
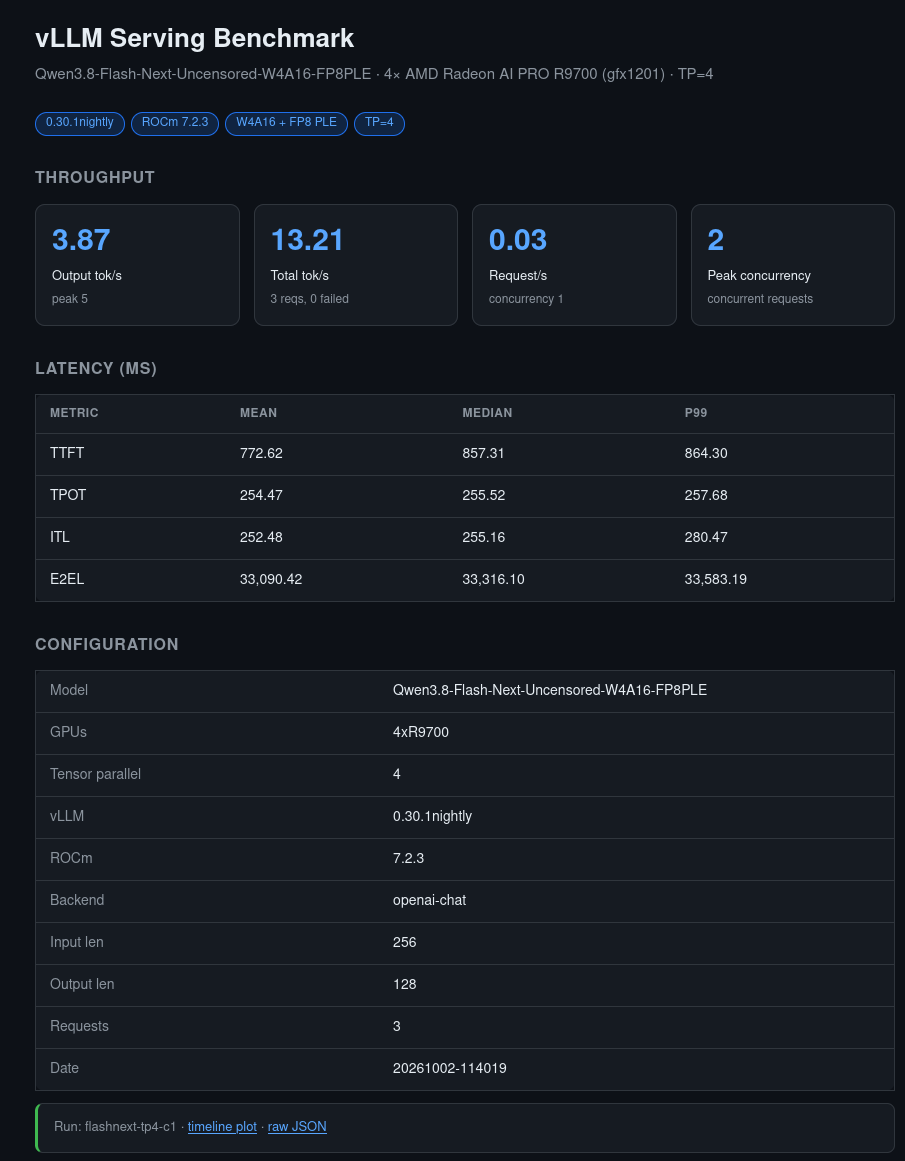
ok so i’m loaded to 82GB of host RAM and around 110GB of VRAM with a GPU kv cache of 500k,
it runs but theres some weirdness:
100 tk/s in concurrent which is …..fine and might be expected considering n-gram streaming from ram, however:
Single user drops to a paltry 4 tk/s, investigating further
turns out i had some debug flags enabled that caused the graphs to get rebuilt per token, I’m at 27.5 tg/s single and 300 tg/s concurrent now
Have you taken a look at tcclaviger/Qwen3.8-Flash-Next-MXFP4-FP8-GPTQ on huggingface? The big strength of the R9700 is FP8 matrix multiplication so you want to avoid W4A16, which is best for older Nvidia/AMD hardware.
thanks i’ll give that one a go, though i really do prefer my models uncensored and i didnt find any mxfp4 quants for that
don’t suppose i could use this one junafinity/Qwen-3.8-Flash-Next-Uncensored-MLX-MXFP4 · Hugging Face , whats the difference between MLX and just MXFP4 anyway?
That would probably work but you need an engine that can run that model while being optimized for gxf1201.
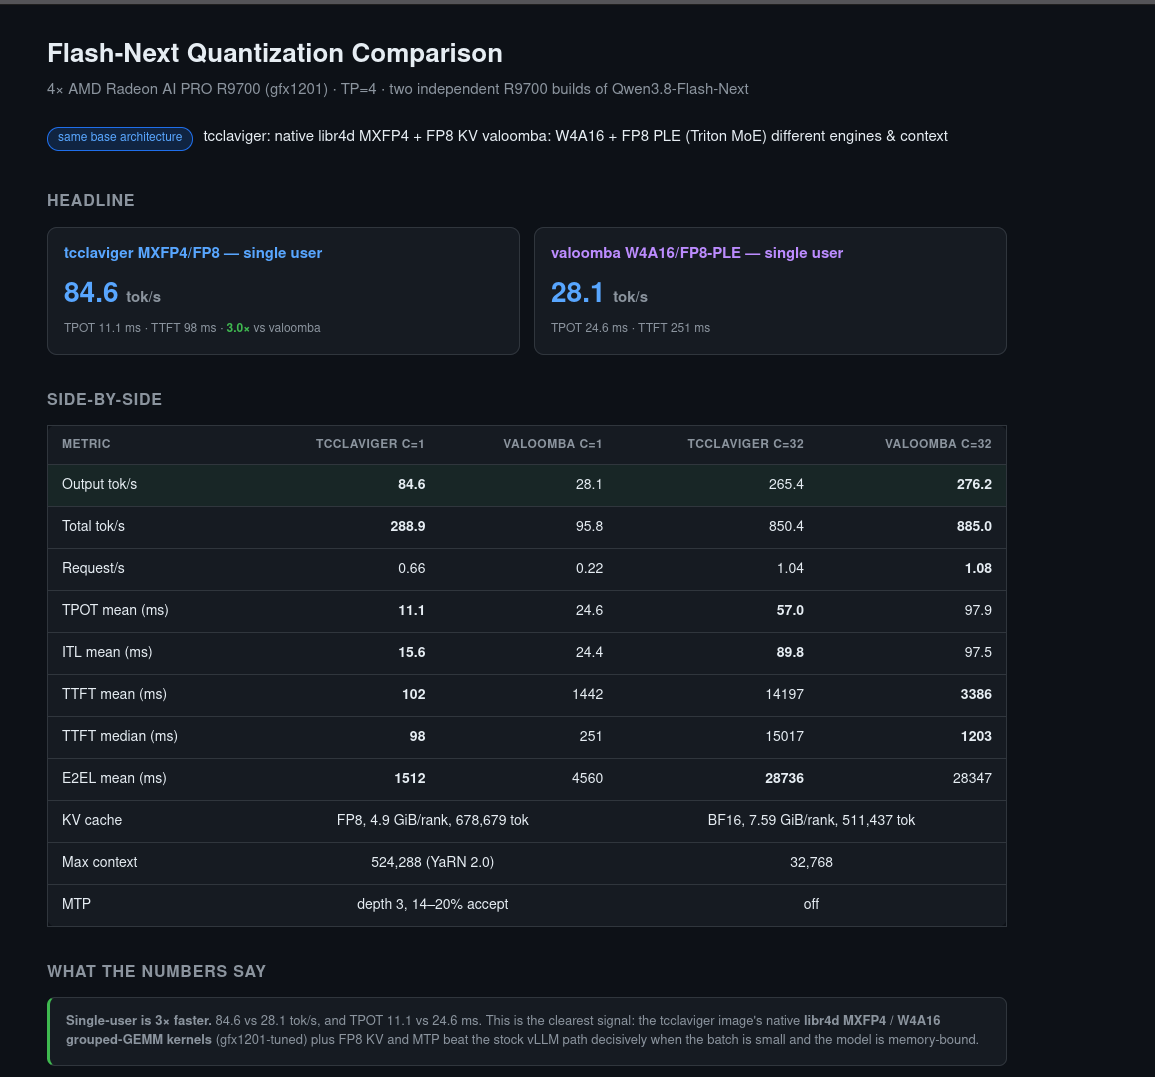
Heres my current Flash-next benches, MTP made things much worse
I have to admit vLLM is new to me, so its more involved to create a model for it than a GGUF?
Yeah why don’t you start with tcclaviger/Qwen3.8-Flash-Next-MXFP4-FP8-GPTQ just to see if it works, and then see if it’ll let you switch the model?
Oh just realized that screenshot you just sent was with tcclaviger/vllm:latest and still didn’t give good results, right? I doubt changing the model will make a big difference, but maybe you’ll get lucky.
Ah no that was with another uncensored version, claviger is coming up still
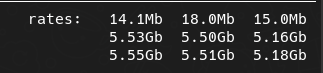
I do love my 8gb fiber  but at 120Gigs ittl take a while
ok its loading the model…..loaded…….benching…… it uses a lot less ram/VRAM, performance is good too at around 250-300/s ish, MTP drafting acceptance is low but the throughput isn’t materially worse for it,
also they added the fp8 kv cache that lets you basically double the context for a certain amount of VRAM usage
Single users is a whopping 3X improvement at 84 tk/s
they even enabled yarn for 0.5M single user support, MTP hurts more than it helps, going to disable that next
Oh man….. this puts me in a tough spot, take this obviously superior model thats censored or go back to an inferior model thats not…. Damn i wish this guy’d make a version of the orcarouter uncensored model of this
Thanks for suggesting this though, no idea i left this much on the table with int4
Man i’m getting 900K of max KV cache too and i still have about 12 GB of vram left over
I have no idea what your use-case is but I would do everything I could to make the censored model work. I use censored models and I very rarely run into issues. Eventually ( StillDeadcode/radiance - Codeberg.org ) will come out and it’ll probably be able to run any model way faster than anything else.
Yeah i’m going to try it for a while, honestly it mostly just comes down to a personal annoyance at the notion of censorship
still being able to have 8 concurrent agents at near 40 tk/s simultaneous at 64-256k context sizes is kind of nuts to have at home XD
yeah the censorship is lighter than imagined, you have to push it, I do hope someone can make the uncensored version of this on the same base still though, this container is straight up magic on AMD R9700, i’m getting single user in the high 80’s