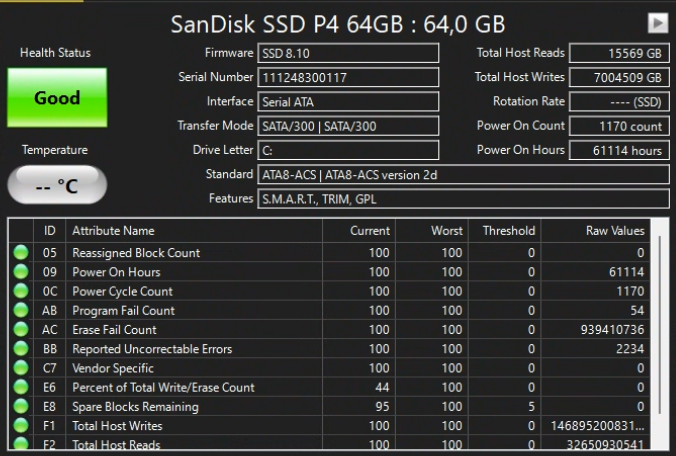
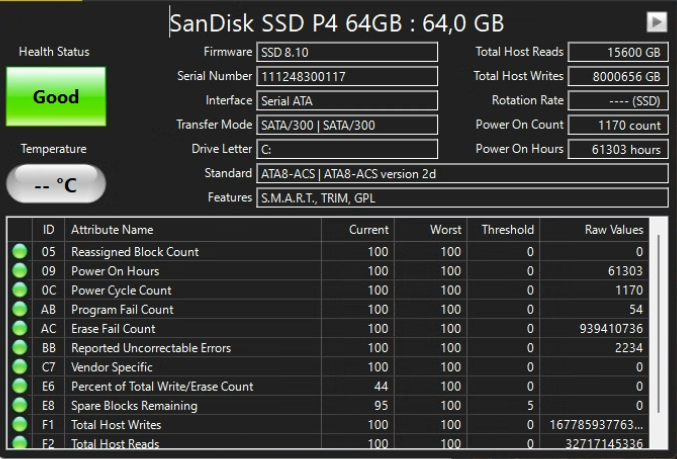
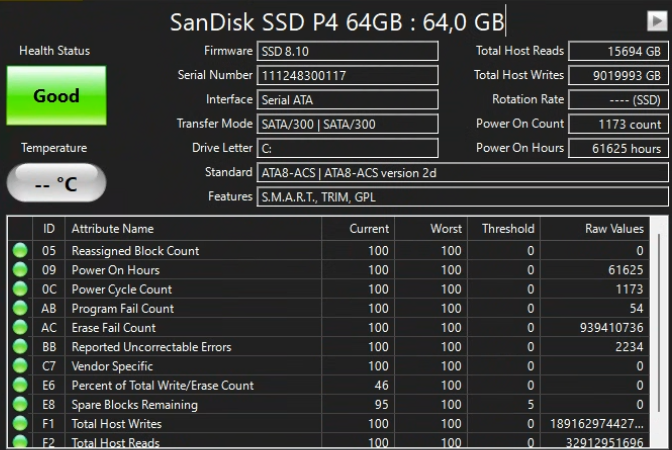
Forced a 16 year 64gb ssd p4 sandisk from 2010 rated for 40tbw, hit 1 petabyte to pass 11 petabytes

SSD firmware crashes and controller failures are vastly more common than nand wear

My 64gb ssd passed and processing over 3PB, experiment is well better than few weeks ago. I’ll keep pushing the controller limit is theoretically 144PB before either it turns into a negative factor, reverts to 0 or freeze and my favorite glitch symbols

I’ll add links and my Notes plus u may have seen me mentioned on tom’s hardware and few teck news sites

And pls check my other videos for more detail,

Passed 1pb

1pb Tom’s hardware noticed

1PB Odometer time-lapse

Passed 2PB

3PB

Xenospectrum

Tom’s Hardware

Techpowerup my forum

Also on reddit

16-Year-Old 64GB SanDisk SSD’s 9PB Write Record: The Cache Trick Behind the Numbers

9 Petabytes

10 Petabytes

14PB

4 Likes

Good old MLC at work, holding strong.

Wonder if any QLC could do that at all or near it.

1 Like

depends on what writes you do and how high the capacity is. 4k random writes on 64GB QLC will wear out very fast. sequential writes on a 32TB QLC drive? will do two digits of PB before anything shows up

New notes and findings, also EM interference

1 Like

SSD firmware crashes and controller failures are vastly more common than nand wear thats why im letting it scream,

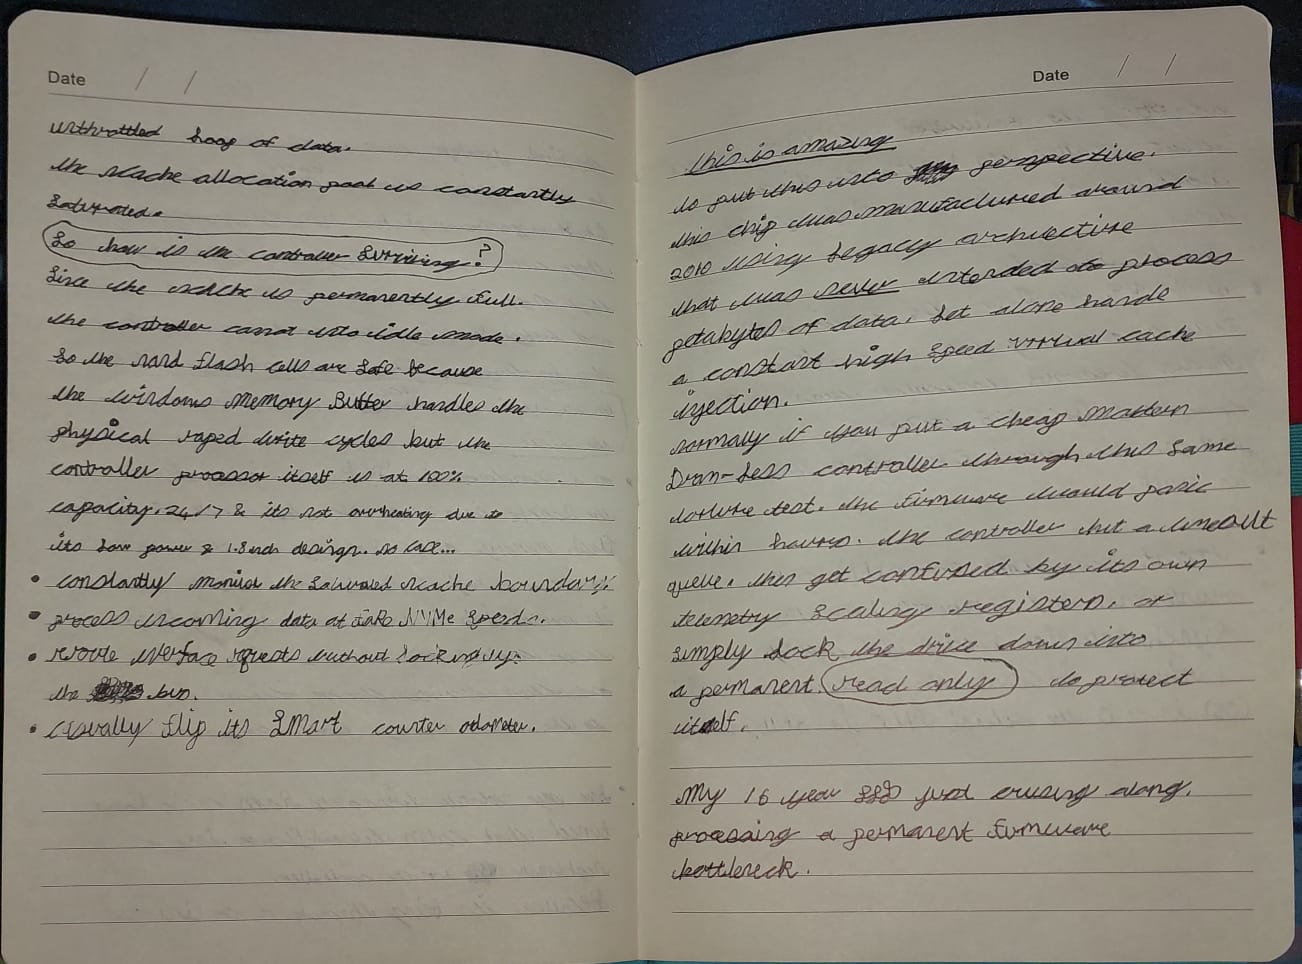
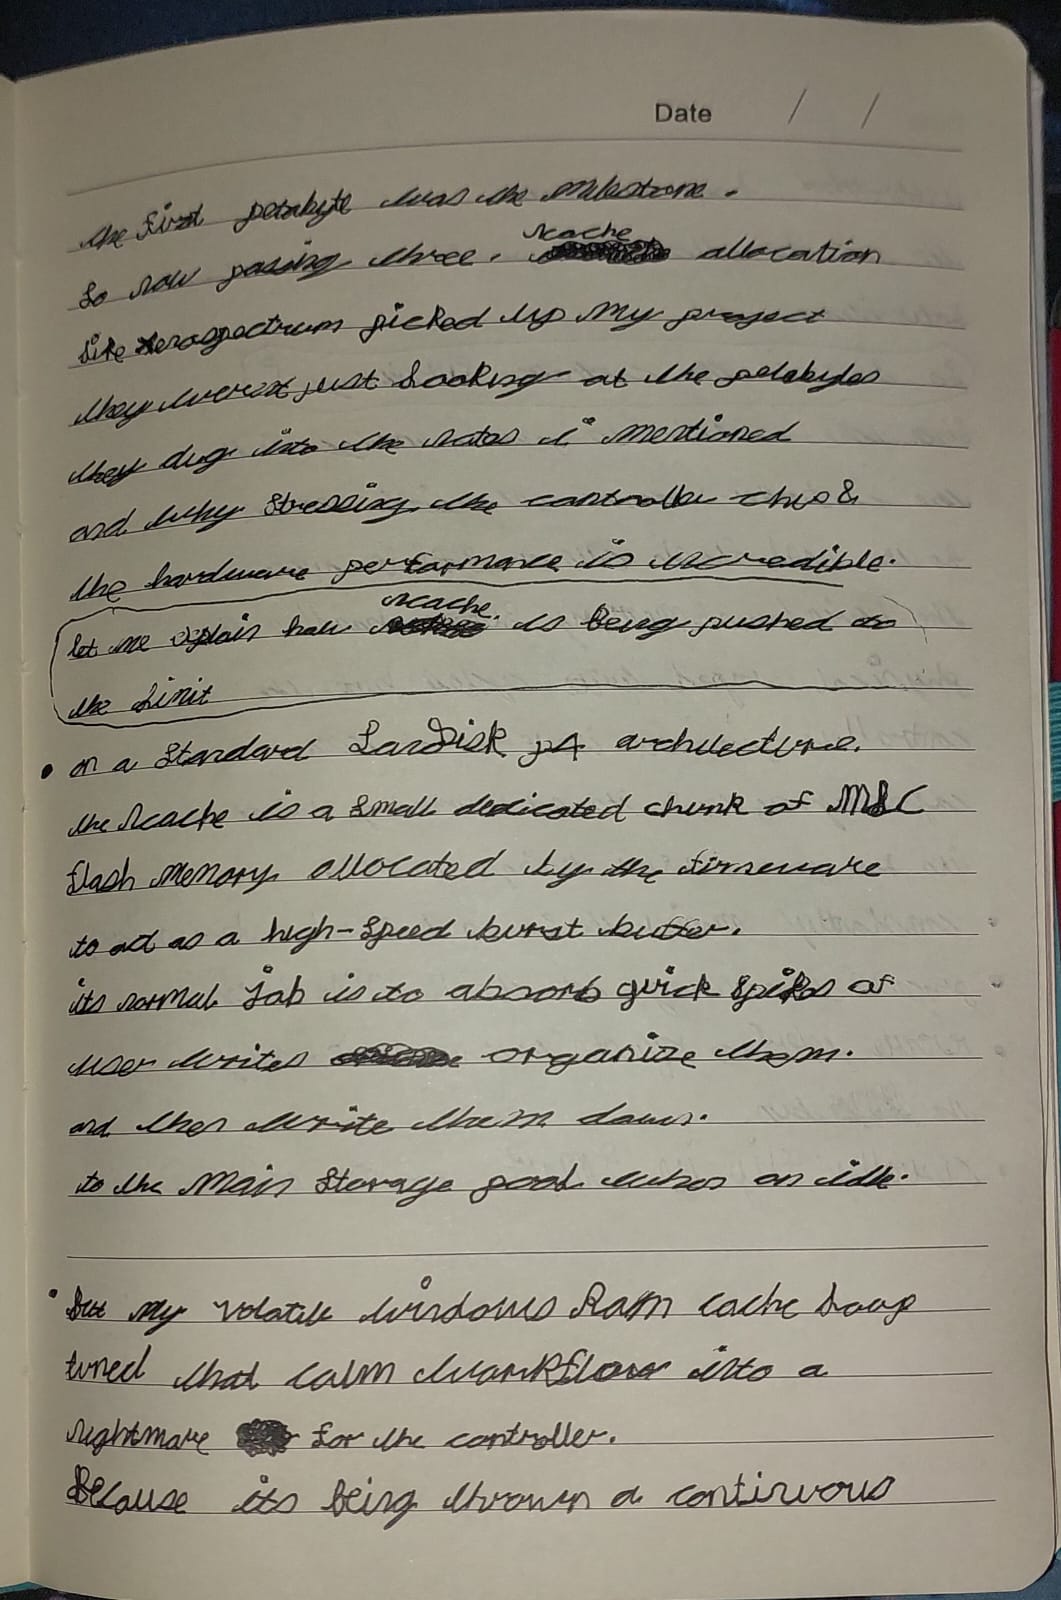
On Windows 11 using a high velocity 5 second macro loop, I managed to trick the system into aggressively logging massive telemetry writes directly to the drive’s odometer forcing the 16 year controller to do the work while the nand stays cool. Because these are virtual cache operations, the actual data vanishes into thin air before it can physically destroy the legacy MLC NAND flash cells…

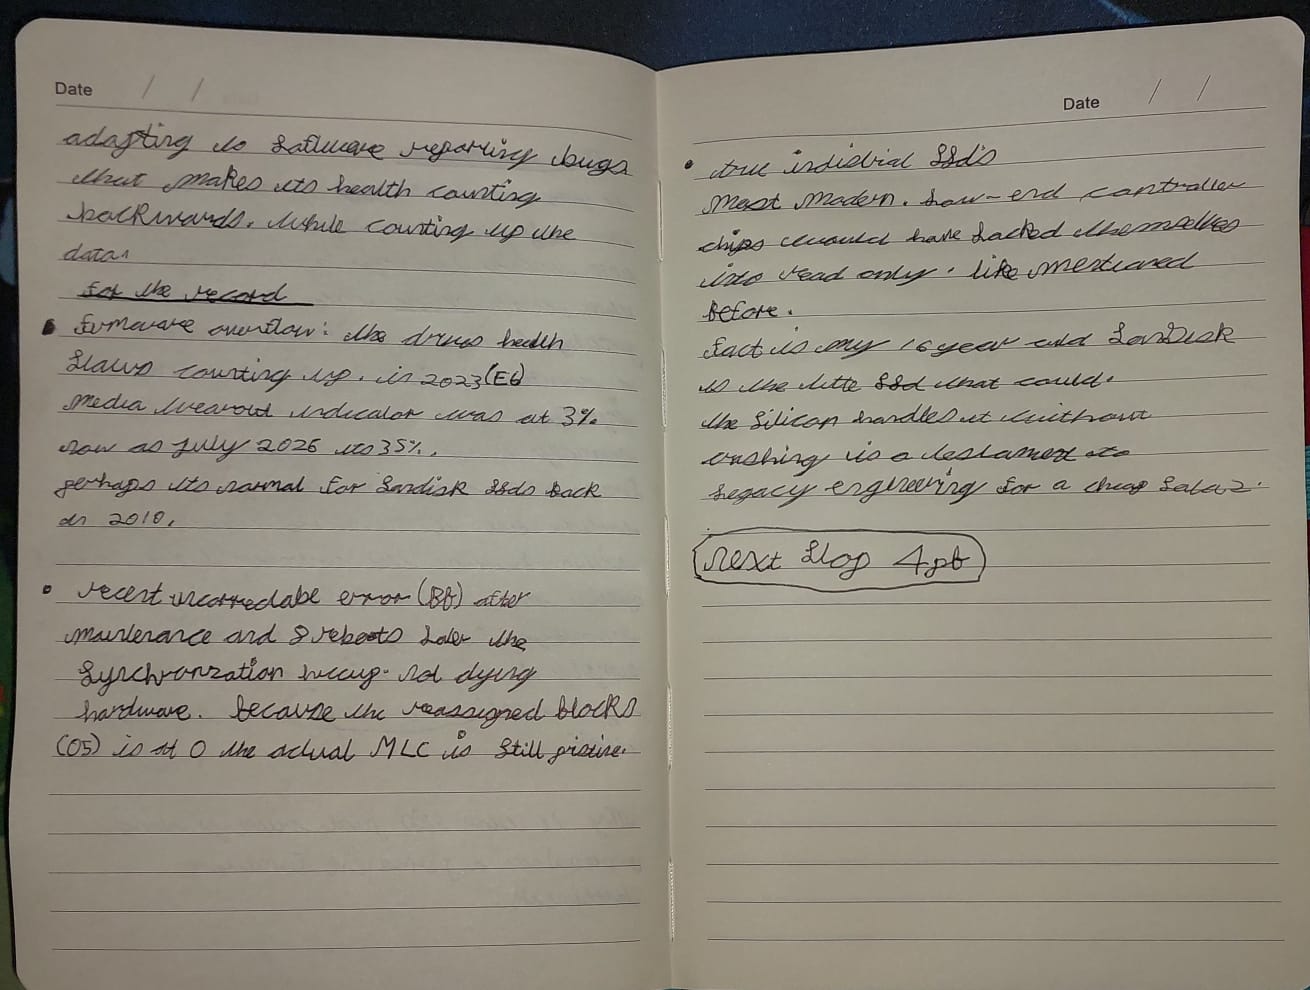
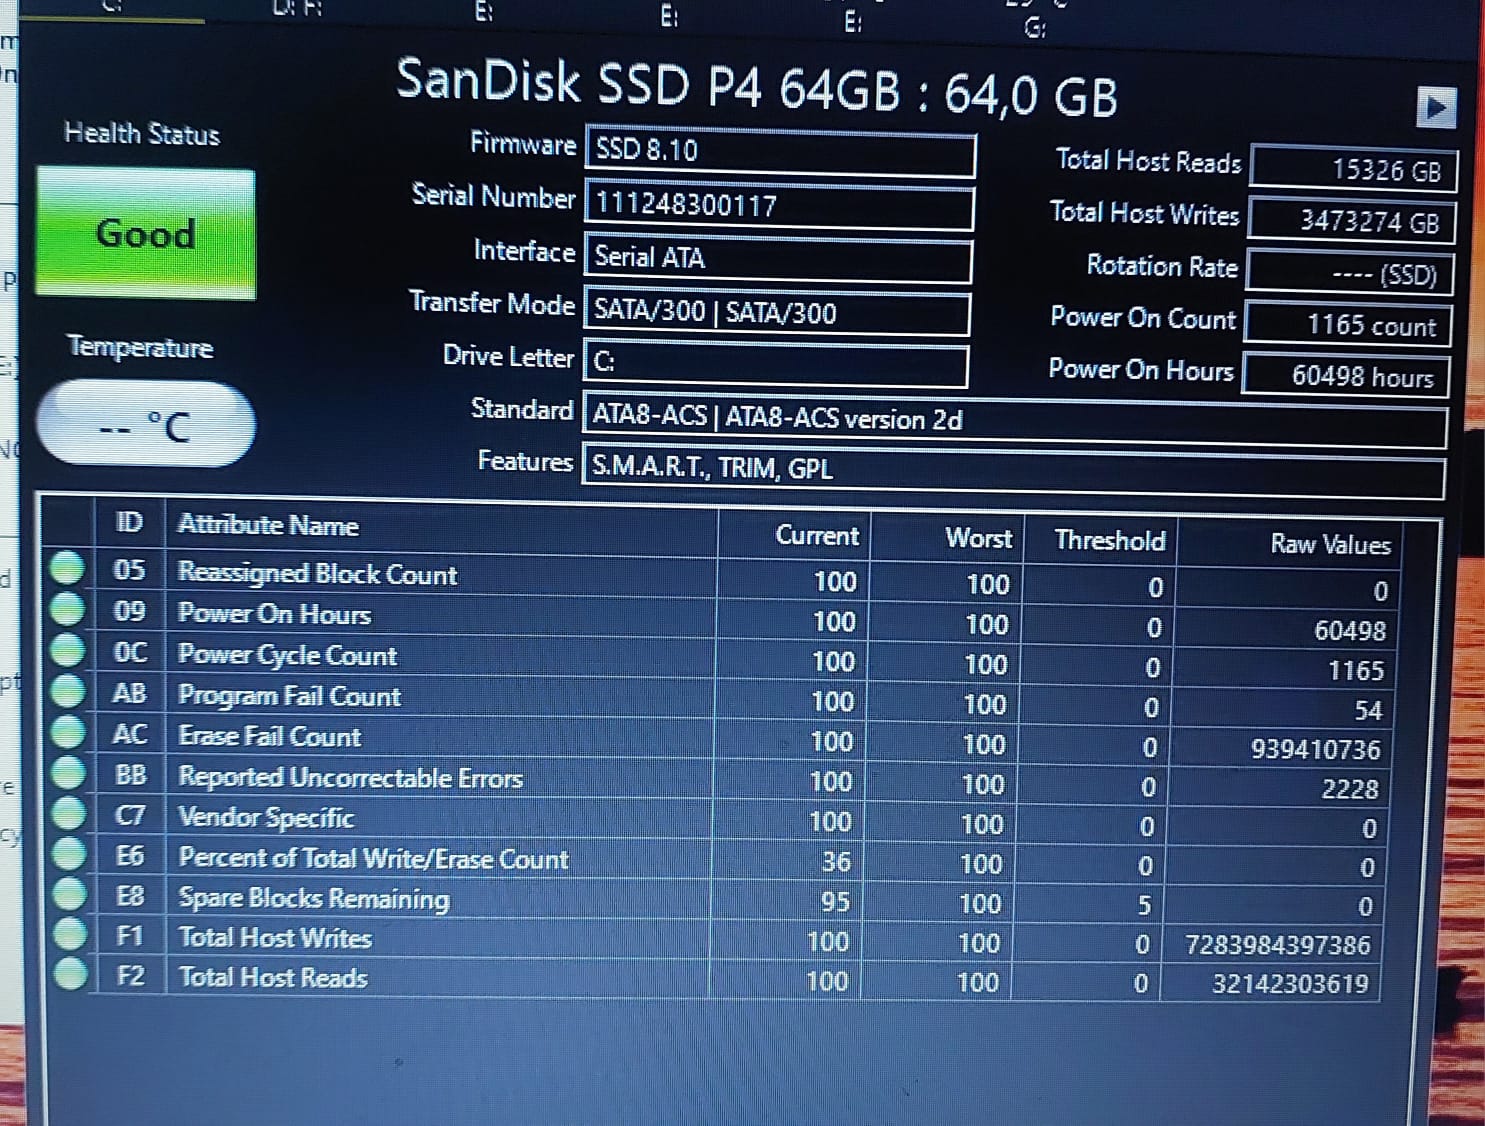
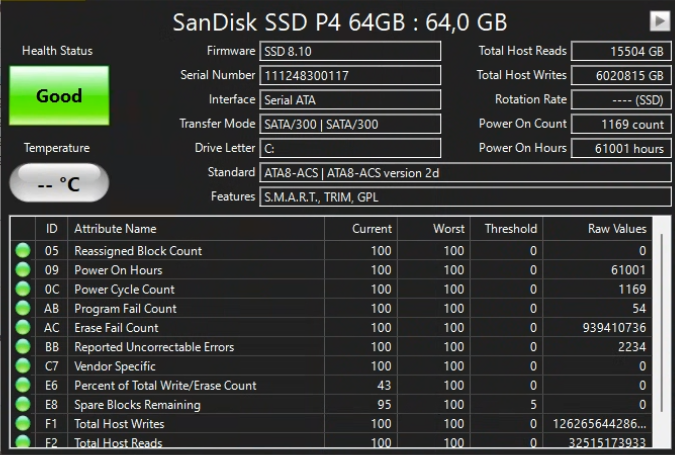
Percent of Total Write/ Erase Count seemed to have gotten up, my findings that its odd and it should go down as you see older picture was down to 3 now its at 36, so I believe who had it before me ran it from 100% to 0, then it flipped and thats when I found it,

Video also has details on ssd and the odometer pushing passed 3pb

SSD firmware crashes and controller failures are vastly more common than nand wearMy 64gb ssd passed and processing over 3PB, experiment is well better than few weeks ago. I’ll keep pushing the controller limit is theoretically 144PB before either it turns into a negative factor, reverts to 0 or freeze and my favorite glitch symbols

Also my notes is about EM interference (EMI) and so few things too…

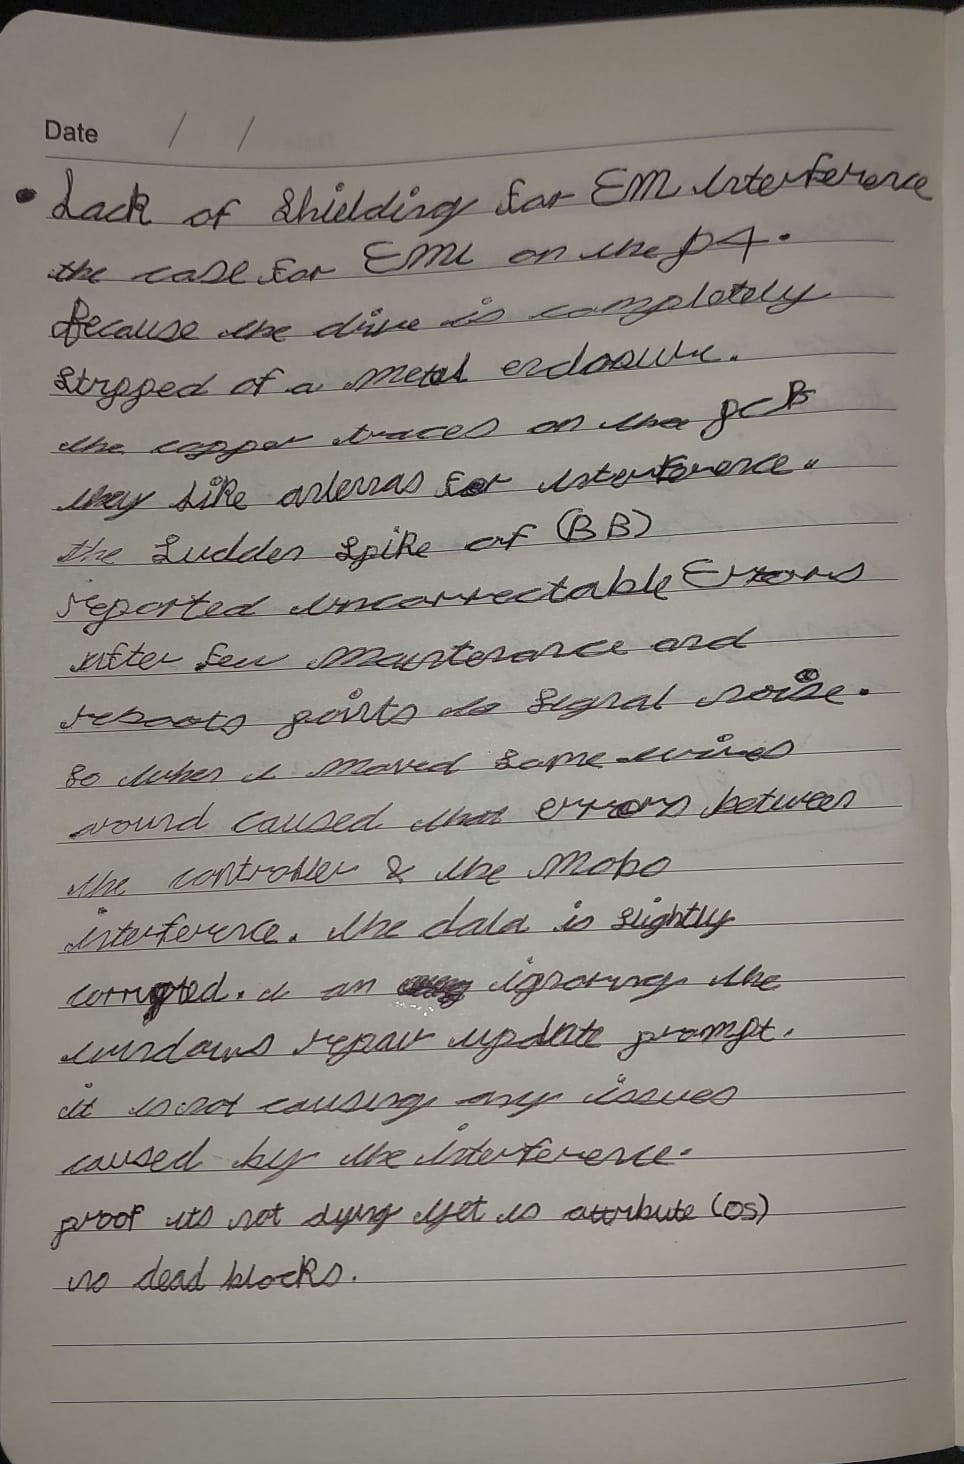
* Lack of shielding for EM Interference the case for EMI on the P4 Because the Drive is Completely stripped of a metal enclosure. the Copper traces on the PCB, Like antennas for interference. The sudden spike of (BB) Reported Uncorrectable errors after few Maintenance and Reboots, Points to signal noise.

so when i moved some wires around it caused that errors between the controller & the Mobo interference.

The data is slightly corrupted. I an ignoring the windows repair update prompt, it is not causing any issues caused by the interference. Proof its not dying yet…

Attribute is (05) NO DEAD BLOCKS.

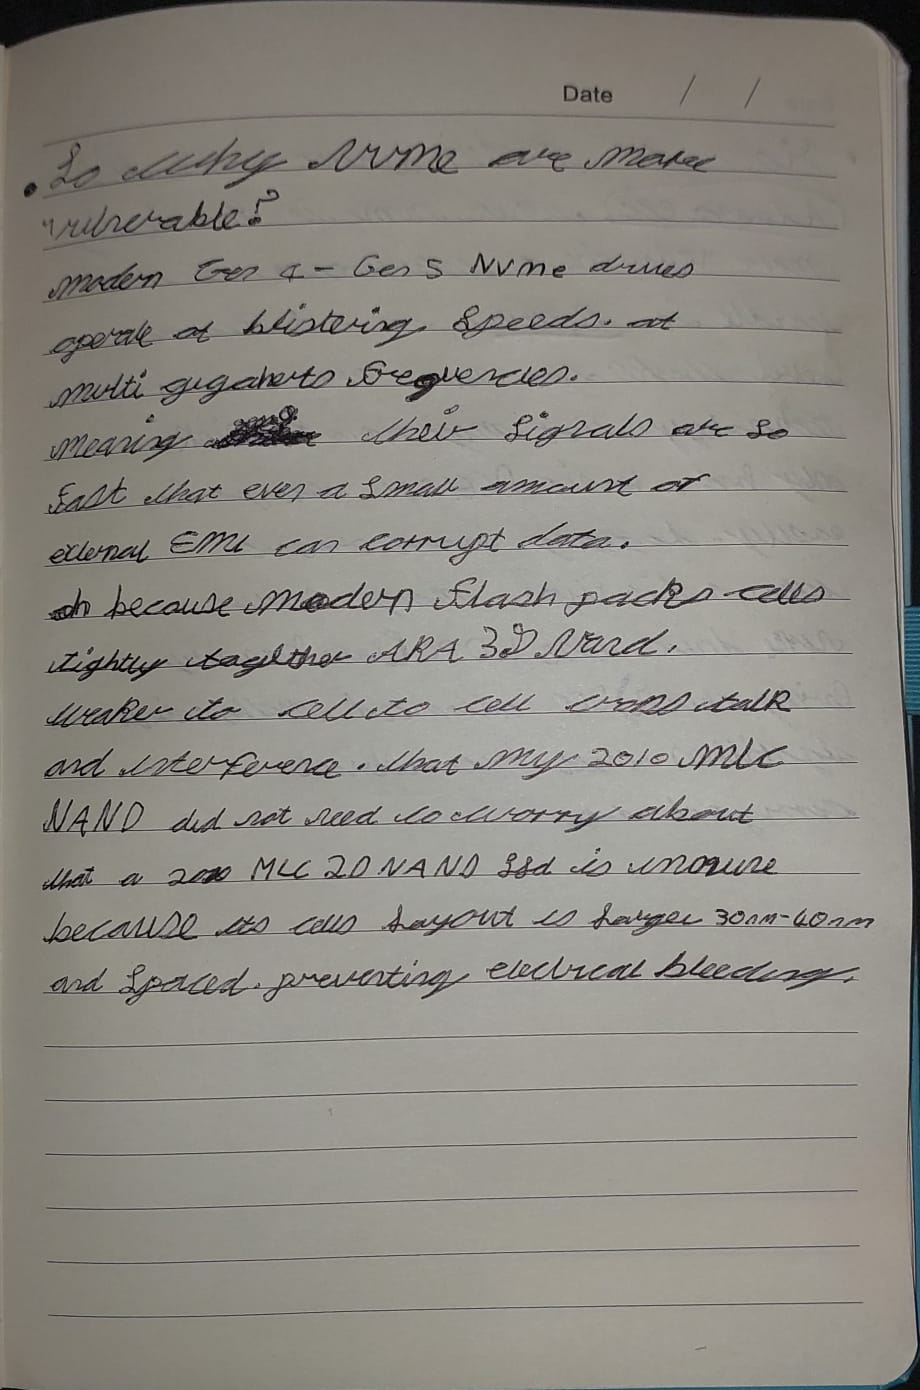
* So NVME are more Vulnerable with no protection?

Modern Gen 4-5 NVMe drives operate at blistering speeds at Multi gigaherz frequencies.

meaning their signals are so fast that even a small amount of external EMI can corrupt data.

oh and because modern flash packs cells tightly together AKA 3D NAND Weaker to cell to cell cross talk & interference.

That is why my 2010 MLC NAND did not need to worry about that its MLC 2D NAND is immune because its cells layout is larger 30nm-40nm & spaced preventing electrical bleeding.

* So How do modern drives handle it?

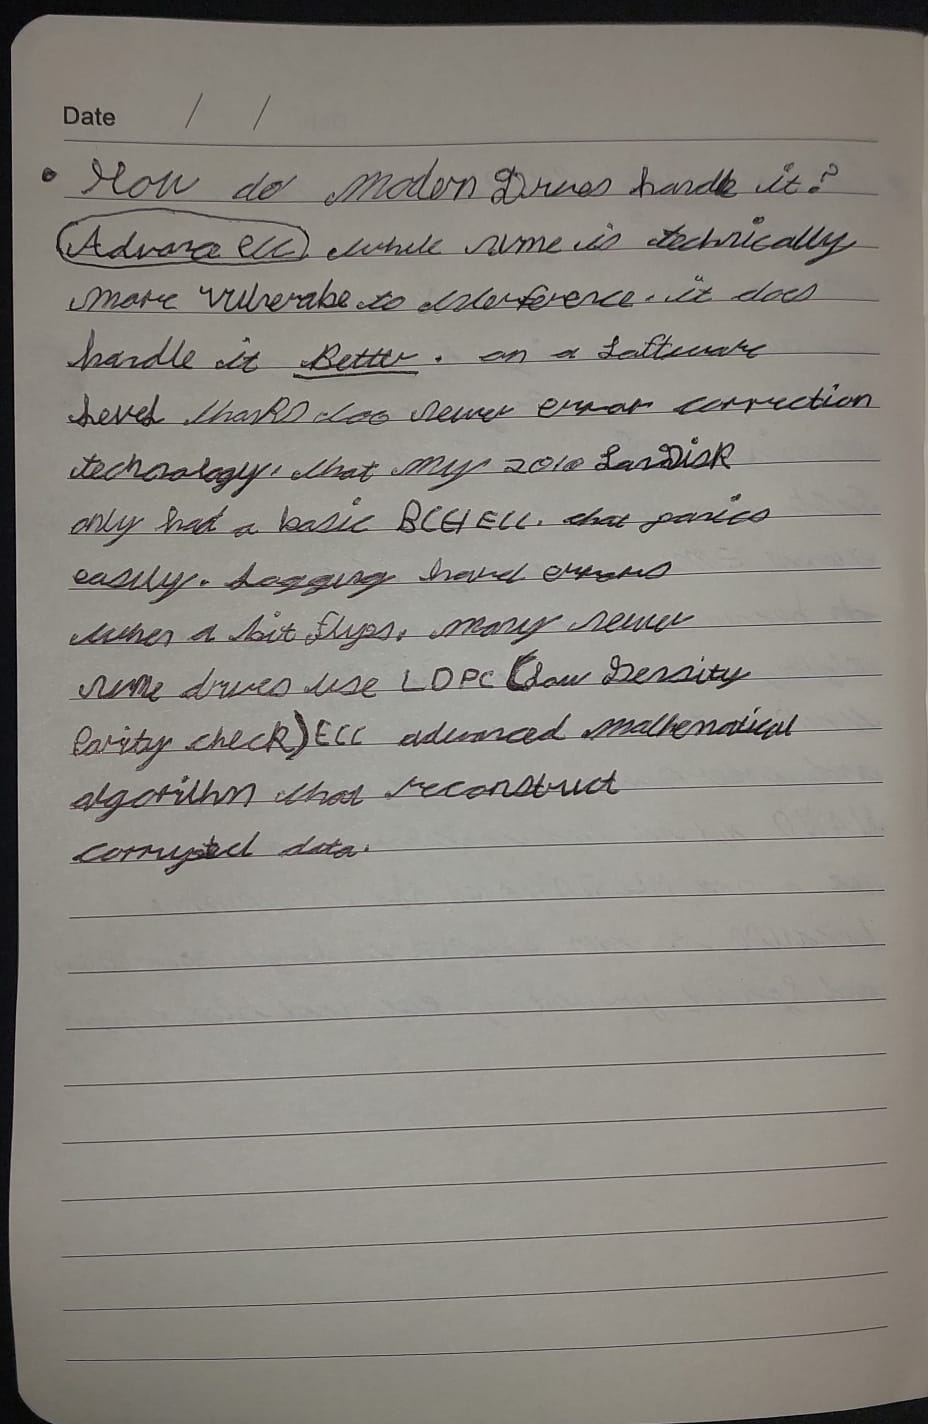
ADVANCED ECC… when NVMe is technically more Vulnerable to interference, it does handle it BETTER. on a software level thanks to newer error correction technology, that my 2010 SanDisk only has a basic BCH ECC, that panics easily, logging harderrors when a bit flips, many newer NVME drives use LDPC

(Low Density Parity Check) ECC advanced mathematical algorithm that reconstructs corrupted data.

ps i may clone the drive because the windows is corrupt but still 100% with no blue screen, doing this i discovered the bug and may test it on other ssds in the future

If you google 16 year ssd hits 1 Petabyte you find more tech news articles. toms hardware Mentioned and xenospectrum and many more

https://xenospectrum.com/sandisk-p4-ssd-1pb-endurance-tbw-ncache/#google_vignette

2 Likes

​Hey everyone,
​I wanted to share some fascinating data from a long-term storage endurance experiment I’ve been running on a vintage piece of hardware: a 64GB SanDisk P4 SSD (Firmware: SSD 8.10) from 2010.
​By running an unthrottled cache loop directly against the controller, I wanted to see how this early-generation architecture would handle extreme, continuous write pressure. I just pulled the raw smartctl -x telemetry and the registers are displaying an incredible mathematical paradox that I think any storage or firmware engineer would appreciate.
​According to Attribute 241 (Total LBAs Written), the drive has processed exactly 7,705,487,096,513 sectors. At 512 bytes per sector, that means this tiny 64GB drive has successfully routed 3.94 Petabytes of data through the interface.
​But the real magic is what’s happening to the internal error and telemetry logging:
​The Erase Fail Explosion (Attribute 172): The internal controller math has completely overflowed, registering an astronomical 939,410,736 erase failures.
​The Wear Indicator Freeze (Attribute 230): The Media Wearout Indicator scale has completely locked up, freezing its raw decay logic entirely.
​The Flawless Silicon (Attribute 05): Despite nearly a billion logged firmware-level erase errors and almost 4PB of data passing through the controller, the physical Reallocated Sector Count is sitting at a perfect 0.
​Because of the specific unthrottled workload hitting the internal register layers, the drive is essentially operating in a perpetual loop state. The vintage 2D Planar MLC NAND is completely unblemished, while the software odometer has lost its mind and gone full “Zombie King.”
​We always talk about the theoretical limits of old-school MLC vs. modern high-density stacks, but seeing a 2010 industrial-era controller cheerfully process petabytes while completely ignoring its own broken telemetry is a fascinating look at early solid-state architecture under absolute extreme edge-case conditions.
​Would love to hear if any Western Digital or legacy SanDisk engineers remember how these specific integer registers were mapped out back in the day!

smartctl -x sda

smartctl 7.5 2025-04-30 r5714 [x86_64-w64-mingw32-w11-24H2] (AppVeyor)
Copyright (C) 2002-25, Bruce Allen, Christian Franke, www.smartmontools.org

=== START OF INFORMATION SECTION ===
Device Model: SanDisk SSD P4 64GB
Serial Number: 111248300117
LU WWN Device Id: 5 001b44 4f27f5455
Firmware Version: SSD 8.10
User Capacity: 64 022 175 232 bytes [64,0 GB]
Sector Size: 512 bytes logical/physical
Rotation Rate: Solid State Device
Form Factor: 1.8 inches
TRIM Command: Available
Device is: Not in smartctl database
ATA Version is: ATA8-ACS T13/1699-D revision 2d
SATA Version is: SATA 2.6, 3.0 Gb/s (current: 3.0 Gb/s)
Local Time is: Fri Jul 10 00:12:25 2026 SAST
SMART support is: Available - device has SMART capability.
SMART support is: Enabled
AAM feature is: Unavailable
APM feature is: Unavailable
Rd look-ahead is: Enabled
Write cache is: Enabled
DSN feature is: Unavailable
ATA Security is: Disabled, frozen [SEC2]

=== START OF READ SMART DATA SECTION ===
SMART overall-health self-assessment test result: PASSED

General SMART Values:
Offline data collection status: (0x00) Offline data collection activity
was never started.
Auto Offline Data Collection: Disabled.
Self-test execution status: ( 25) The self-test routine was aborted by
the host.
Total time to complete Offline
data collection: ( 120) seconds.
Offline data collection
capabilities: (0x15) SMART execute Offline immediate.
No Auto Offline data collection support.
Abort Offline collection upon new
command.
No Offline surface scan supported.
Self-test supported.
No Conveyance Self-test supported.
No Selective Self-test supported.
SMART capabilities: (0x0003) Saves SMART data before entering
power-saving mode.
Supports SMART auto save timer.
Error logging capability: (0x01) Error logging supported.
General Purpose Logging supported.
Short self-test routine
recommended polling time: ( 2) minutes.
Extended self-test routine
recommended polling time: ( 16) minutes.

SMART Attributes Data Structure revision number: 1
Vendor Specific SMART Attributes with Thresholds:
ID# ATTRIBUTE_NAME FLAGS VALUE WORST THRESH FAIL RAW_VALUE
5 Reallocated_Sector_Ct -O---- 100 100 — - 0
9 Power_On_Hours -O---- 100 100 000 - 60550
12 Power_Cycle_Count -O---- 100 100 000 - 1165
171 Unknown_Attribute -O---- 100 100 000 - 54
172 Unknown_Attribute -O---- 100 100 000 - 939410736
187 Reported_Uncorrect -O---- 100 100 000 - 2228
199 UDMA_CRC_Error_Count -O---- 100 100 000 - 0
230 Unknown_SSD_Attribute PO---- 036 100 — - 0
232 Available_Reservd_Space PO---- 095 100 005 - 0
241 Total_LBAs_Written -O---- 100 100 000 - 7705487096513
242 Total_LBAs_Read -O---- 100 100 000 - 32162951695
||||||_ K auto-keep
|||||__ C event count
||||__ R error rate
|||__ S speed/performance
||_
_ O updated online
|______ P prefailure warning

General Purpose Log Directory Version 1
SMART Log Directory Version 1 [multi-sector log support]
Address Access R/W Size Description
0x00 GPL,SL R/O 1 Log Directory
0x03 GPL,SL R/O 16 Ext. Comprehensive SMART error log
0x06 GPL,SL R/O 1 SMART self-test log
0x80-0x9f GPL,SL R/W 16 Host vendor specific log

SMART Extended Comprehensive Error Log Version: 1 (16 sectors)
Device Error Count: 181 (device log contains only the most recent 64 errors)
CR = Command Register
FEATR = Features Register
COUNT = Count (was: Sector Count) Register
LBA_48 = Upper bytes of LBA High/Mid/Low Registers ] ATA-8
LH = LBA High (was: Cylinder High) Register ] LBA
LM = LBA Mid (was: Cylinder Low) Register ] Register
LL = LBA Low (was: Sector Number) Register ]
DV = Device (was: Device/Head) Register
DC = Device Control Register
ER = Error register
ST = Status register
Powered_Up_Time is measured from power on, and printed as
DDd+hh:mm:SS.sss where DD=days, hh=hours, mm=minutes,
SS=sec, and sss=millisec. It “wraps” after 49.710 days.

Error 181 [52] occurred at disk power-on lifetime: 5 hours (0 days + 5 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 77 40 00 2d+03:11:48.526 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 76 40 00 2d+03:11:48.517 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 75 40 00 2d+03:11:48.509 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT

Error 180 [51] occurred at disk power-on lifetime: 6 hours (0 days + 6 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 76 40 00 2d+03:11:48.517 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 75 40 00 2d+03:11:48.509 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 72 40 00 2d+03:11:48.501 READ DMA EXT

Error 179 [50] occurred at disk power-on lifetime: 6 hours (0 days + 6 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 75 40 00 2d+03:11:48.509 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 72 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 71 40 00 2d+03:11:48.500 READ DMA EXT

Error 178 [49] occurred at disk power-on lifetime: 2 hours (0 days + 2 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 72 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 71 40 00 2d+03:11:48.500 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 70 40 00 2d+03:11:48.497 READ DMA EXT

Error 177 [48] occurred at disk power-on lifetime: 3 hours (0 days + 3 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 04 00 00 00 00 00 00 40 00 Error: UNC 4 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 20 00 00 00 42 1b 60 40 00 2d+03:11:48.459 READ DMA EXT
25 00 00 00 20 00 00 00 3c e2 e0 40 00 2d+03:11:48.459 READ DMA EXT
25 00 00 00 20 00 00 00 35 97 60 40 00 2d+03:11:48.458 READ DMA EXT
25 00 00 00 20 00 00 00 26 20 20 40 00 2d+03:11:48.457 READ DMA EXT
25 00 00 00 08 00 00 00 63 9e 08 40 00 2d+03:11:48.457 READ DMA EXT

Error 176 [47] occurred at disk power-on lifetime: 11 hours (0 days + 11 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 02 00 00 00 00 00 00 40 00 Error: UNC 2 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 80 00 00 00 42 1b 5e 40 00 1d+10:07:21.325 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a de 40 00 1d+10:07:21.324 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a 5e 40 00 1d+10:07:21.324 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 de 40 00 1d+10:07:21.323 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 5e 40 00 1d+10:07:21.323 READ DMA EXT

Error 175 [46] occurred at disk power-on lifetime: 11 hours (0 days + 11 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 02 00 00 00 00 00 00 40 00 Error: UNC 2 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 80 00 00 00 42 1b 5e 40 00 1d+09:58:46.796 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a de 40 00 1d+09:58:46.796 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a 5e 40 00 1d+09:58:46.795 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 de 40 00 1d+09:58:46.795 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 5e 40 00 1d+09:58:46.794 READ DMA EXT

Error 174 [45] occurred at disk power-on lifetime: 11 hours (0 days + 11 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 02 00 00 00 00 00 00 40 00 Error: UNC 2 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 80 00 00 00 42 1b 5e 40 00 1d+09:39:52.893 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a de 40 00 1d+09:39:52.892 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a 5e 40 00 1d+09:39:52.892 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 de 40 00 1d+09:39:52.892 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 5e 40 00 1d+09:39:52.891 READ DMA EXT

SMART Extended Self-test Log (GP Log 0x07) not supported

Warning! SMART Self-Test Log Structure error: invalid SMART checksum.
SMART Self-test log structure revision number 1
Num Test_Description Status Remaining LifeTime(hours) LBA_of_first_error

1 Short offline Aborted by host 90% 21088 -

2 Short offline Aborted by host 90% 54860 -

3 Short offline Aborted by host 90% 19043 -

4 Short offline Aborted by host 90% 63054 -

5 Short offline Aborted by host 90% 25327 -

6 Short offline Aborted by host 90% 62483 -

7 Short offline Aborted by host 90% 33744 -

8 Short captive Completed without error 00% 57803 -

9 Short offline Aborted by host 90% 25293 -

#10 Extended offline Aborted by host 90% 28072 -
#11 Short offline Aborted by host 90% 14539 -
#12 Extended offline Aborted by host 90% 55234 -
#13 Short offline Aborted by host 90% 46428 -
#14 Short offline Aborted by host 90% 49138 -
#15 Short offline Aborted by host 90% 25717 -
#16 Extended offline Aborted by host 90% 50305 -
#17 Short offline Aborted by host 90% 39612 -
#18 Short offline Aborted by host 90% 21280 -
#19 Short offline Aborted by host 90% 34598 -
#20 Short offline Aborted by host 90% 17318 -
#21 Short offline Aborted by host 90% 63627 -

Selective Self-tests/Logging not supported

SCT Commands not supported

Device Statistics (GP/SMART Log 0x04) not supported

Pending Defects log (GP Log 0x0c) not supported

SATA Phy Event Counters (GP Log 0x11) not supported

Exitcode: 64 (0x40)
Type to exit:
I’m not sure what the point of this is. Looking at the drive stats, I would have considered it unsuitable for production use after the first couple of uncorrectable errors.

Repeated UNC at LBA 0. That makes the drive near unusable.

Are you just trying to see how long it takes for a catastrophic failure to occur and the drive to stop responding?

Because from the stats the drive has certainly failed now and can’t be trusted with data.

1 Like

That’s exactly the point of the experiment! I’m obviously not using a 16-year-old budget drive for production data. It’s a pure silicon endurance torture test to see exactly how and when the legacy firmware and logic controller finally deadlock or hit a catastrophic failure. In these old drives, the controller and firmware logic usually fail long before the physical NAND actually gives out anyway. Watching it cross 4 Petabytes while throwing uncorrectable errors is just part of the fun

Fair enough. My experience with electronics is that it’s usually the capacitors on the power supply side that bugger up the rest. That often leads to the magic smoke escaping.

I suppose you are waiting to hit an error condition that the firmware can’t recover from. Randomising the IO patterns might help with the “fuzzing” aspect.

Hey everyone,
I’ve been running an extreme endurance test on a vintage 2010-era SanDisk P4 64GB SSD, and the results are getting beautifully stupid.
Most people run these tests to destroy the physical NAND, but I wanted to test the pure processing endurance of the controller and firmware. To do that, I set up a continuous, ultra-fast 1-second caching loop. It basically traps the writes in the volatile cache layers—saving the physical MLC flash cells from burning out, but putting the logic controller through absolute hell.
We just crossed the 4.2 Petabyte (4,264,642 GB) milestone, and the controller is handling it like an absolute champ.
The wear math is incredibly consistent right now:
Consistent Wear Math: The vendor-specific wear meter (E6) just ticked from 37% to 38%. It took exactly ~325 TB of data to move that 1%. Doing the math, the firmware expects this little 64GB netbook drive to survive 32.5 Petabytes before it officially hits 100%.
Here is the big question: What happens when E6 actually hits 100%?
Does the firmware have a hard-coded “suicide switch” that will force it into read-only lock-up (Scenario A)? Or is this old controller primitive enough that it will just shrug, roll back over to 0%, and become immortal (Scenario B)?

https://youtu.be/Dh8otWsBVBg

1 Like

This test is entirely pointless unless you can confirm the data is retrievable.

No one cares how much you can throw at a drive without retrieving it, may as well store to /dev/null, its faster.

You’re missing the goal of the experiment. This isn’t a standard NAND data retention test; it’s a controller processing endurance test. If I just piped data to /dev/null, the SSD controller wouldn’t have to do any actual work.
​By trapping the writes in a volatile cache loop, the controller is constantly executing massive amounts of sector-mapping logic. We are reading the data, which is exactly why the BB (Reported Uncorrectable Errors) counter is actively ticking up. The data is corrupting, and the drive is failing to retrieve it yet the software is blindly screaming ‘GOOD. That’s the entire point of the exposé.

1 Like

​Is your SSD actually safe? You probably open CrystalDiskInfo, see that reassuring blue “GOOD” box, and close it without a second thought. But my latest hardware endurance test proves that these numbers are nothing more than a superficial, pre-programmed math equation.
​These diagnostic programs don’t have a brain or an AI; they simply blindly follow basic logic rules set back in 2010, checking specific firmware registers like reallocated sectors or media wear metrics. They completely fail to look at the big picture.
​By isolating and torturing an older SSD controller with an aggressive cache loop, I’ve created a hardware anomaly that has completely broken the reporting logic of the internet’s favorite monitoring tools. Despite massive internal data dropping, billions of logged failures, and a controller fighting for its life, the software says everything is pristine. Here is exactly why you can no longer trust your drive health software.

https://youtu.be/0nRIqK9IC1s?si=fetjH0rihHN5XcKW

1 Like

also i expect the controller to fail is 115 days

https://youtu.be/68F5NL_H_yo

7pb passed and still going; this controller is resilient I’ll give it that, what we are seeing is silicon endurance & extreme edge
still going, this controller is resilient ill give
Case
usage. in the real world. a consumer SSD controller was
designed to
never
endure this kind of punishment making its continued
operation remarkable.

*Silicon physical transistors are Built tough.
hile the firware and the Log tables are
corrupting (like the invalid
smart checksums and unc errors) the physical silicon of the controller
processor core and memory bus has continuously processing
billions
o f I/O operations without locking up
or
dropping died

*they gracefully degrading instead of catastrophically dying
Nast modern ssd controllers don’t slow down or corrupt there logs
they fail, they suffer catastraphic controller panic and sudden
wnen
vanish from theBIOS, (bricking to Omb or dropping sata connection)
ny sandisk controller is taking punches, its throwing bad
checksums
and internal read errors, hut refusing to knock out.

​What Makes 9 PB Ridiculous?
​140,000+ Full Drive Cycles: This controller has organized and executed enough raw writes to fill the entire physical capacity of this 64GB drive over 140,937 times.
​The E6 Counter Woke Up: After looking frozen at 44, the vendor attribute E6 moved up to 46.
The firmware’s internal math registers are struggling to map values this high, yet it hasn’t crashed the primary firmware thread.
​Execution Engine Stays Solid: Managing the Flash Translation Layer (FTL) cache and command queue under continuous,
uninterrupted SATA writes for 61,000+ hours is an incredible testament to this controller’s silicon design.

Sector 0 Faults: The error log shows recurring UNC (Uncorrectable) read errors specifically targeting LBA 0x00000000 during read commands.
The boot sector area is heavily degraded, but write caching and DMA transactions remain fully operational.

Does the drive cycles matter if its not on nand chip but the controller itself?

The short answer is yes, The drive cycles still matter greatly for the controller itself,
but for completely different physical and operational reasons than for the NAND flash chips.
​While NAND flash dies from atomic wear (tunnel oxide breakdown from program/erase cycles), the controller suffers from architectural, data management,
and physical processing stress.
​1. Flash Translation Layer (FTL) Mapping Stress
​Table Overwrites: Every drive cycle forces the controller to completely rewrite its internal mapping table (which translates logical LBAs to physical NAND blocks).
​RAM & NVRAM Burnout: The mapping metadata must be constantly swapped between SRAM/DRAM cache and non-volatile system control blocks on the NAND.
The controller’s internal metadata blocks often endure 10× to 100× more write cycles than the user data blocks.
​2. Garbage Collection & Wear-Leveling Overhead
​Write Amplification (WA): As the drive is continually cycled, valid and invalid pages become fragmented.
The controller has to work exponentially harder to read, move, and erase blocks behind the scenes.
​Instruction Loop Saturation: Higher wear-leveling workloads keep the controller’s internal CPU running at peak processing cycles,
increasing thermal stress and silicon electromigration over time.
​3. Internal Register Overflow & Integer Wrapping
​32-bit/64-bit Counter Limits: Low-cost or older SSD controllers (like early SanDisk SSD P4 designs) were never designed with software registers sized
for millions of drive cycles or petabytes of host writes.
​Firmware Memory Corruption: As raw event counters (like erase counts or written LBAs) overflow their allocated bit widths,
they can wrap around to zero, trigger arithmetic overflow bugs,
or overwrite adjacent NVRAM log structures—directly causing the invalid SMART checksums you are seeing in your logs.
​4. ECC & Read Retry Engine Exhaustion
​Hardware Engine Strain: As the underlying raw NAND bit-error rate (BER) increases with total drive cycles,
the controller’s internal ECC hardware decoder has to run maximum LDPC/BCH error-correction algorithms on almost every read.
​Latency & Execution Delays: Processing heavy error-correction math on every host command severely taxes the controller’s internal bus and pipeline execution.
​The Bottom Line
NAND chips wear out quietly by losing charge retention, but controllers fail catastrophically due to drive cycle stress—usually manifesting as a sudden freeze,
corrupted internal metadata, or an endless BSY state when firmware counters finally break.
​The fact that SanDisk P4 controller is still managing its FTL execution engine cleanly after ~140,000 drive cycles is remarkable.

smartctl -x sda

smartctl 7.5 2025-04-30 r5714 [x86_64-w64-mingw32-w11-24H2] (AppVeyor)
Copyright (C) 2002-25, Bruce Allen, Christian Franke, www.smartmontools.org

=== START OF INFORMATION SECTION ===
Device Model: SanDisk SSD P4 64GB
Serial Number: 111248300117
LU WWN Device Id: 5 001b44 4f27f5455
Firmware Version: SSD 8.10
User Capacity: 64 022 175 232 bytes [64,0 GB]
Sector Size: 512 bytes logical/physical
Rotation Rate: Solid State Device
Form Factor: 1.8 inches
TRIM Command: Available
Device is: Not in smartctl database
ATA Version is: ATA8-ACS T13/1699-D revision 2d
SATA Version is: SATA 2.6, 3.0 Gb/s (current: 3.0 Gb/s)
Local Time is: Thu Aug 27 11:01:05 2026 SAST
SMART support is: Available - device has SMART capability.
SMART support is: Enabled
AAM feature is: Unavailable
APM feature is: Unavailable
Rd look-ahead is: Enabled
Write cache is: Enabled
DSN feature is: Unavailable
ATA Security is: Disabled, frozen [SEC2]

=== START OF READ SMART DATA SECTION ===
SMART overall-health self-assessment test result: PASSED

General SMART Values:
Offline data collection status: (0x00) Offline data collection activity
was never started.
Auto Offline Data Collection: Disabled.
Self-test execution status: ( 0) The previous self-test routine completed
without error or no self-test has ever
been run.
Total time to complete Offline
data collection: ( 120) seconds.
Offline data collection
capabilities: (0x15) SMART execute Offline immediate.
No Auto Offline data collection support.
Abort Offline collection upon new
command.
No Offline surface scan supported.
Self-test supported.
No Conveyance Self-test supported.
No Selective Self-test supported.
SMART capabilities: (0x0003) Saves SMART data before entering
power-saving mode.
Supports SMART auto save timer.
Error logging capability: (0x01) Error logging supported.
General Purpose Logging supported.
Short self-test routine
recommended polling time: ( 2) minutes.
Extended self-test routine
recommended polling time: ( 16) minutes.

SMART Attributes Data Structure revision number: 1
Vendor Specific SMART Attributes with Thresholds:
ID# ATTRIBUTE_NAME FLAGS VALUE WORST THRESH FAIL RAW_VALUE
5 Reallocated_Sector_Ct -O---- 100 100 — - 0
9 Power_On_Hours -O---- 100 100 000 - 61625
12 Power_Cycle_Count -O---- 100 100 000 - 1173
171 Unknown_Attribute -O---- 100 100 000 - 54
172 Unknown_Attribute -O---- 100 100 000 - 939410736
187 Reported_Uncorrect -O---- 100 100 000 - 2234
199 UDMA_CRC_Error_Count -O---- 100 100 000 - 0
230 Unknown_SSD_Attribute PO---- 046 100 — - 0
232 Available_Reservd_Space PO---- 095 100 005 - 0
241 Total_LBAs_Written -O---- 100 100 000 - 18916297464160
242 Total_LBAs_Read -O---- 100 100 000 - 32913028369
||||||_ K auto-keep
|||||__ C event count
||||__ R error rate
|||__ S speed/performance
||_
_ O updated online
|______ P prefailure warning

General Purpose Log Directory Version 1
SMART Log Directory Version 1 [multi-sector log support]
Address Access R/W Size Description
0x00 GPL,SL R/O 1 Log Directory
0x03 GPL,SL R/O 16 Ext. Comprehensive SMART error log
0x06 GPL,SL R/O 1 SMART self-test log
0x80-0x9f GPL,SL R/W 16 Host vendor specific log

SMART Extended Comprehensive Error Log Version: 1 (16 sectors)
Device Error Count: 181 (device log contains only the most recent 64 errors)
CR = Command Register
FEATR = Features Register
COUNT = Count (was: Sector Count) Register
LBA_48 = Upper bytes of LBA High/Mid/Low Registers ] ATA-8
LH = LBA High (was: Cylinder High) Register ] LBA
LM = LBA Mid (was: Cylinder Low) Register ] Register
LL = LBA Low (was: Sector Number) Register ]
DV = Device (was: Device/Head) Register
DC = Device Control Register
ER = Error register
ST = Status register
Powered_Up_Time is measured from power on, and printed as
DDd+hh:mm:SS.sss where DD=days, hh=hours, mm=minutes,
SS=sec, and sss=millisec. It “wraps” after 49.710 days.

Error 181 [52] occurred at disk power-on lifetime: 5 hours (0 days + 5 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 77 40 00 2d+03:11:48.526 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 76 40 00 2d+03:11:48.517 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 75 40 00 2d+03:11:48.509 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT

Error 180 [51] occurred at disk power-on lifetime: 6 hours (0 days + 6 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 76 40 00 2d+03:11:48.517 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 75 40 00 2d+03:11:48.509 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 72 40 00 2d+03:11:48.501 READ DMA EXT

Error 179 [50] occurred at disk power-on lifetime: 6 hours (0 days + 6 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 75 40 00 2d+03:11:48.509 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 72 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 71 40 00 2d+03:11:48.500 READ DMA EXT

Error 178 [49] occurred at disk power-on lifetime: 2 hours (0 days + 2 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 00 00 00 00 00 00 00 40 00 Error: UNC at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 01 00 00 00 42 1b 74 40 00 2d+03:11:48.505 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 73 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 72 40 00 2d+03:11:48.501 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 71 40 00 2d+03:11:48.500 READ DMA EXT
25 00 00 00 01 00 00 00 42 1b 70 40 00 2d+03:11:48.497 READ DMA EXT

Error 177 [48] occurred at disk power-on lifetime: 3 hours (0 days + 3 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 04 00 00 00 00 00 00 40 00 Error: UNC 4 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 20 00 00 00 42 1b 60 40 00 2d+03:11:48.459 READ DMA EXT
25 00 00 00 20 00 00 00 3c e2 e0 40 00 2d+03:11:48.459 READ DMA EXT
25 00 00 00 20 00 00 00 35 97 60 40 00 2d+03:11:48.458 READ DMA EXT
25 00 00 00 20 00 00 00 26 20 20 40 00 2d+03:11:48.457 READ DMA EXT
25 00 00 00 08 00 00 00 63 9e 08 40 00 2d+03:11:48.457 READ DMA EXT

Error 176 [47] occurred at disk power-on lifetime: 11 hours (0 days + 11 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 02 00 00 00 00 00 00 40 00 Error: UNC 2 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 80 00 00 00 42 1b 5e 40 00 1d+10:07:21.325 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a de 40 00 1d+10:07:21.324 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a 5e 40 00 1d+10:07:21.324 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 de 40 00 1d+10:07:21.323 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 5e 40 00 1d+10:07:21.323 READ DMA EXT

Error 175 [46] occurred at disk power-on lifetime: 11 hours (0 days + 11 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 02 00 00 00 00 00 00 40 00 Error: UNC 2 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 80 00 00 00 42 1b 5e 40 00 1d+09:58:46.796 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a de 40 00 1d+09:58:46.796 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a 5e 40 00 1d+09:58:46.795 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 de 40 00 1d+09:58:46.795 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 5e 40 00 1d+09:58:46.794 READ DMA EXT

Error 174 [45] occurred at disk power-on lifetime: 11 hours (0 days + 11 hours)
When the command that caused the error occurred, the device was active or idle.

After command completion occurred, registers were:
ER – ST COUNT LBA_48 LH LM LL DV DC
– – – == – == == == – – – – –
40 – 51 00 02 00 00 00 00 00 00 40 00 Error: UNC 2 sectors at LBA = 0x00000000 = 0

Commands leading to the command that caused the error were:
CR FEATR COUNT LBA_48 LH LM LL DV DC Powered_Up_Time Command/Feature_Name
– == – == – == == == – – – – – --------------- --------------------
25 00 00 00 80 00 00 00 42 1b 5e 40 00 1d+09:39:52.893 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a de 40 00 1d+09:39:52.892 READ DMA EXT
25 00 00 00 80 00 00 00 42 1a 5e 40 00 1d+09:39:52.892 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 de 40 00 1d+09:39:52.892 READ DMA EXT
25 00 00 00 80 00 00 00 42 19 5e 40 00 1d+09:39:52.891 READ DMA EXT

SMART Extended Self-test Log (GP Log 0x07) not supported

Warning! SMART Self-Test Log Structure error: invalid SMART checksum.
SMART Self-test log structure revision number 1
Num Test_Description Status Remaining LifeTime(hours) LBA_of_first_error

1 Short offline Aborted by host 90% 21088 -

2 Short offline Aborted by host 90% 54860 -

3 Short offline Aborted by host 90% 19043 -

4 Short offline Aborted by host 90% 63054 -

5 Short offline Aborted by host 90% 25327 -

6 Short offline Aborted by host 90% 62483 -

7 Short offline Aborted by host 90% 33744 -

8 Short captive Completed without error 00% 57803 -

9 Short offline Aborted by host 90% 25293 -

#10 Extended offline Aborted by host 90% 28072 -
#11 Short offline Aborted by host 90% 14539 -
#12 Extended offline Aborted by host 90% 55234 -
#13 Short offline Aborted by host 90% 46428 -
#14 Short offline Aborted by host 90% 49138 -
#15 Short offline Aborted by host 90% 25717 -
#16 Extended offline Aborted by host 90% 50305 -
#17 Short offline Aborted by host 90% 39612 -
#18 Short offline Aborted by host 90% 21280 -
#19 Short offline Aborted by host 90% 34598 -
#20 Short offline Aborted by host 90% 17318 -
#21 Short offline Aborted by host 90% 63627 -

Selective Self-tests/Logging not supported

SCT Commands not supported

Device Statistics (GP/SMART Log 0x04) not supported

Pending Defects log (GP Log 0x0c) not supported

SATA Phy Event Counters (GP Log 0x11) not supported

Exitcode: 64 (0x40)
Type to exit:
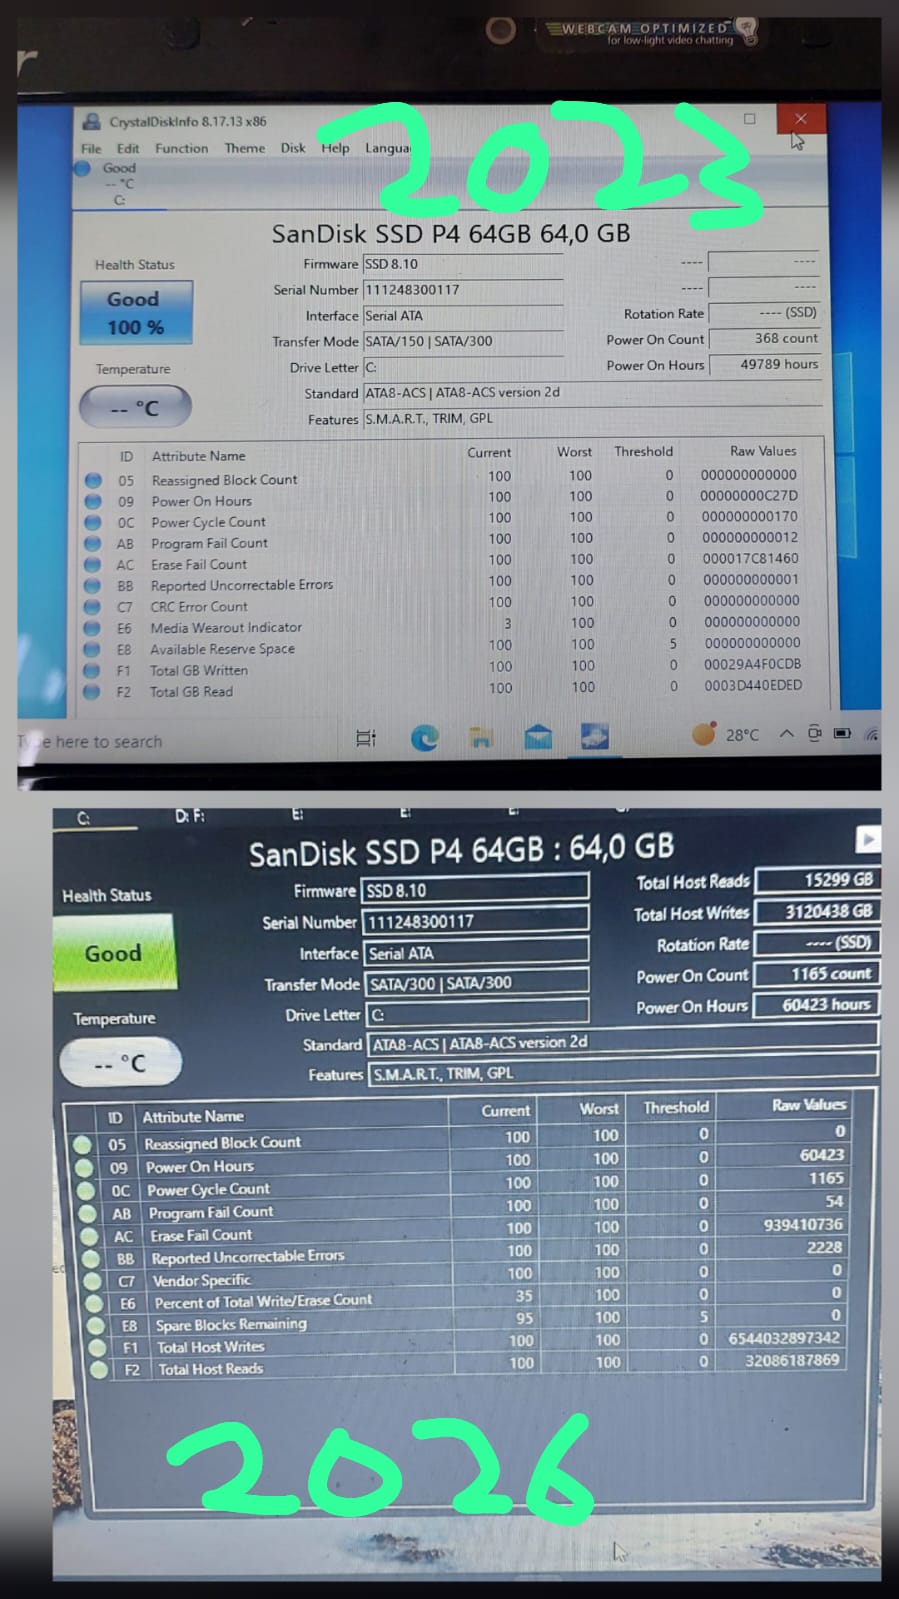
I see that the experiment has been listed few tech websites thank you Guys for my mention

And more

when websearch 64gb ssd 9 Petabytes

Pls sub and share the video

​

And I will update soon its shy feom 10 Petabytes

1 Like