CUDA 12.9 on Fedora 42 Guide including getting `cuda-samples` running

I have struggled getting Cuda, NVCC, and the cuda-samples project running on my computer, so I am writing this to help others.

Installing NVIDIA drivers

As someone that uses the professional CUDA blackwell cards, I am required to use the NVIDIA open kernel module. It works for both gaming and professional cards. I would advise you to use it as the closed source kernel module will eventually be deprecated.

sudo dnf install rpmfusion-nonfree-release # make sure rpmfusion non-free is enabled
sudo sh -c 'echo "%_with_kmod_nvidia_open 1" > /etc/rpm/macros.nvidia-kmod' # use the open modules when building the kernel modules
sudo dnf install akmod-nvidia xorg-x11-drv-nvidia xorg-x11-drv-nvidia-cuda xorg-x11-drv-nvidia-cuda-libs # install the fedora drivers and cuda libraries

DO NOT REBOOT UNTIL KERNEL MODULES HAVE BEEN COMPILED. You can simply look to see if they are running by calling ps aux | grep kmod. I personally run it with the watch command and wait until nothing but the issued watch commands are returned. watch -n 2 "ps aux | grep kmod"

More information can be found on the RPM Fusion NVIDIA how-to site

Reboot

Install Cuda 12.9

Instructions are based on the RPM Fusion CUDA page

sudo dnf config-manager addrepo --from-repofile=https://developer.download.nvidia.com/compute/cuda/repos/fedora41/$(uname -m)/cuda-fedora41.repo
sudo dnf clean all
sudo dnf config-manager setopt cuda-fedora41-$(uname -m).exclude=nvidia-driver,nvidia-modprobe,nvidia-persistenced,nvidia-settings,nvidia-libXNVCtrl,nvidia-xconfig
sudo dnf -y install cuda-toolkit # 12.9.0 at time of writing

Now comes the juicy part, installing the requirements to get the cuda-samples

Installing NVCC, compatible GCC

To compile cuda C/C++ code, you will need NVCC from the NVIDIA cuda fedora repo we added. We also need GCC 14 as Fedora 42 comes with version 15, which is too new.

sudo dnf install gcc14.x86_64 gcc14-c++.x86_64 cuda-nvcc-12-9

Now set the correct environment variables so that nvcc uses g++ 14 and cmake projects use the correct versions of GCC compilers:

export CUDAHOSTCXX=/usr/bin/g++-14
export CPATH=/usr/include/openmpi-x86_64:$CPATH
export PATH=$PATH:/usr/lib64/openmpi/bin
export CC=/usr/bin/gcc-14
export CXX=/usr/bin/g++-14
export NVCC_CCBIN=/usr/bin/g++-14
export CUDACXX=/usr/local/cuda-12.9/bin/nvcc

Finally we want to make sure that we have the libraries and includes folders added correct to the paths and that the nvcc binary is in our executable paths.

export LD_LIBRARY_PATH=/usr/local/cuda-12.9/targets/x86_64-linux/lib:$LD_LIBRARY_PATH
export CPATH=/usr/local/cuda-12.9/targets/x86_64-linux/include:$CPATH
export PATH=/usr/local/cuda-12.9/bin:$PATH

The dirty hack

/usr/local/cuda-12.9/targets/x86_64-linux/include/crt/math_functions.h have externel declaration functions to /usr/include/bits/mathcalls.h that are incompatible. So let’s fix that by editing /usr/local/cuda-12.9/targets/x86_64-linux/include/crt/math_functions.h. Here are a set of diffs of what I did :

  *
  * \note_accuracy_double
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 sinpi(double x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 sinpi(double x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_SINGLE
  * \brief Calculate the sine of the input argument
@@ -2576,7 +2576,7 @@
  *
  * \note_accuracy_single
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  sinpif(float x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  sinpif(float x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_DOUBLE
  * \brief Calculate the cosine of the input argument
@@ -2598,7 +2598,7 @@
  *
  * \note_accuracy_double
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 cospi(double x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 cospi(double x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_SINGLE
  * \brief Calculate the cosine of the input argument
@@ -2620,7 +2620,7 @@
  *
  * \note_accuracy_single
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  cospif(float x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  cospif(float x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_DOUBLE
  * \brief  Calculate the sine and cosine of the first input argument

Notice how we added noexcept (true) at the end of the sine and cosine commands, that’s what is need to make them compatible with the newer libraries.

And that is it folks. The rest is all about getting the cuda-samples working.

Getting cuda-samples working

Now, there are a few packages that you can install to help with the OpenGL, Vulkan, FreeImage and MPI demoes:

sudo dnf install freeglut freeglut-devel freeimage-devel openmpi openmpi-devel vulkan

To get MPI working, you want to add it’s binaries to your path

export PATH=$PATH:/usr/lib64/openmpi/bin

In a directory of your choice, clone the cuda-samples project

git clone https://github.com/NVIDIA/cuda-samples.git
cd cuda-samples

Now let’s get building:

# in the cuda-samples diretory
mkdir build
cd build
cmake -G Ninja -DCMAKE_BUILD_TYPE=Debug -DCMAKE_CUDA_ARCHITECTURES=native  .. # I prefer ninja over make
ninja -j30 # change the number to whatever you want, I have 32 threads available in my computer

Grab a cuppa tea and wait (or not). If all goes well, we should have projects we can now run. In the same build directory, let’s run two of my favorite examples

./Samples/2_Concepts_and_Techniques/MC_EstimatePiP/MC_EstimatePiP # simple monte-carlo algorithm for estimating Pi
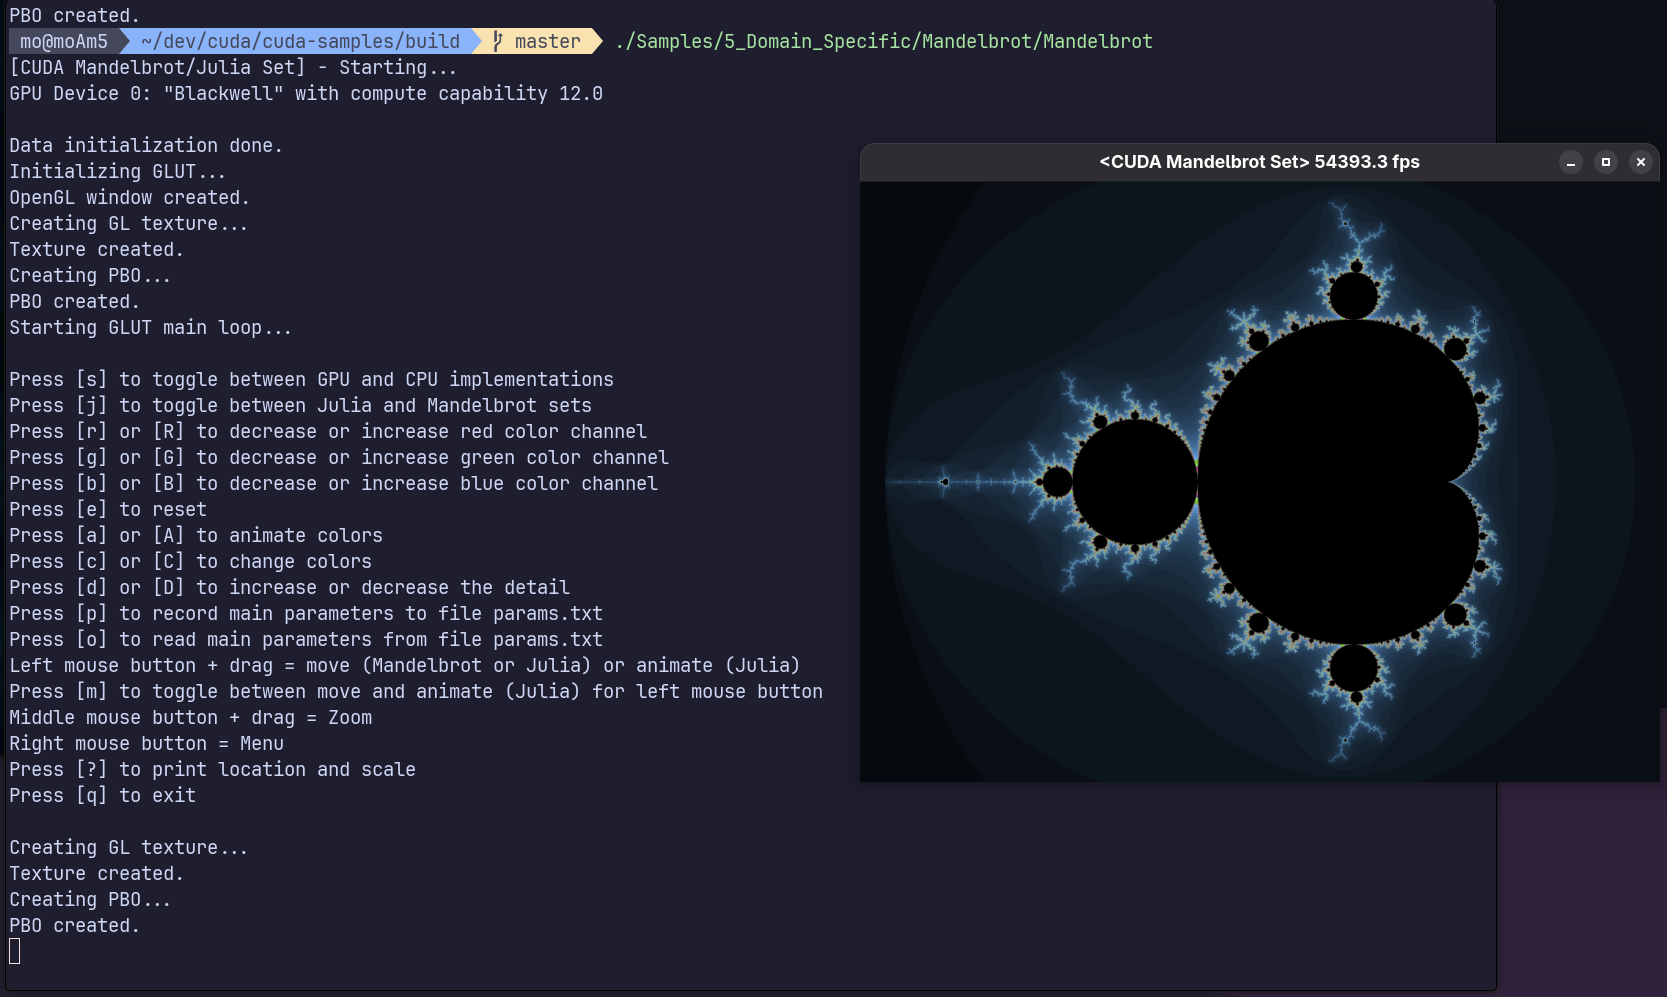
./Samples/5_Domain_Specific/Mandelbrot/Mandelbrot # tests OpenGL with CUDA, use `+` and `-` to zoom in and out
Happy hacking!

Note:

  • I am not a professional C++ developer, have not done it professionally in over a decade
  • My only CUDA real world experience was when I was at university and I used it to accelerate simulations that were written with OpenMP
  • If there is a better way let me know!
  • If you are not married to Fedora, just use Ubuntu. It’s far easier. For me, I want the newer packages, no Snapshot, and I work with RHEL at work so it’s closer to what I use there.

BONUS: Working inside CLion

Open the root project directory where the CMake with CLion. You will notice that cmake won’t initially work. That is because you need to add the environment variables we have above there:
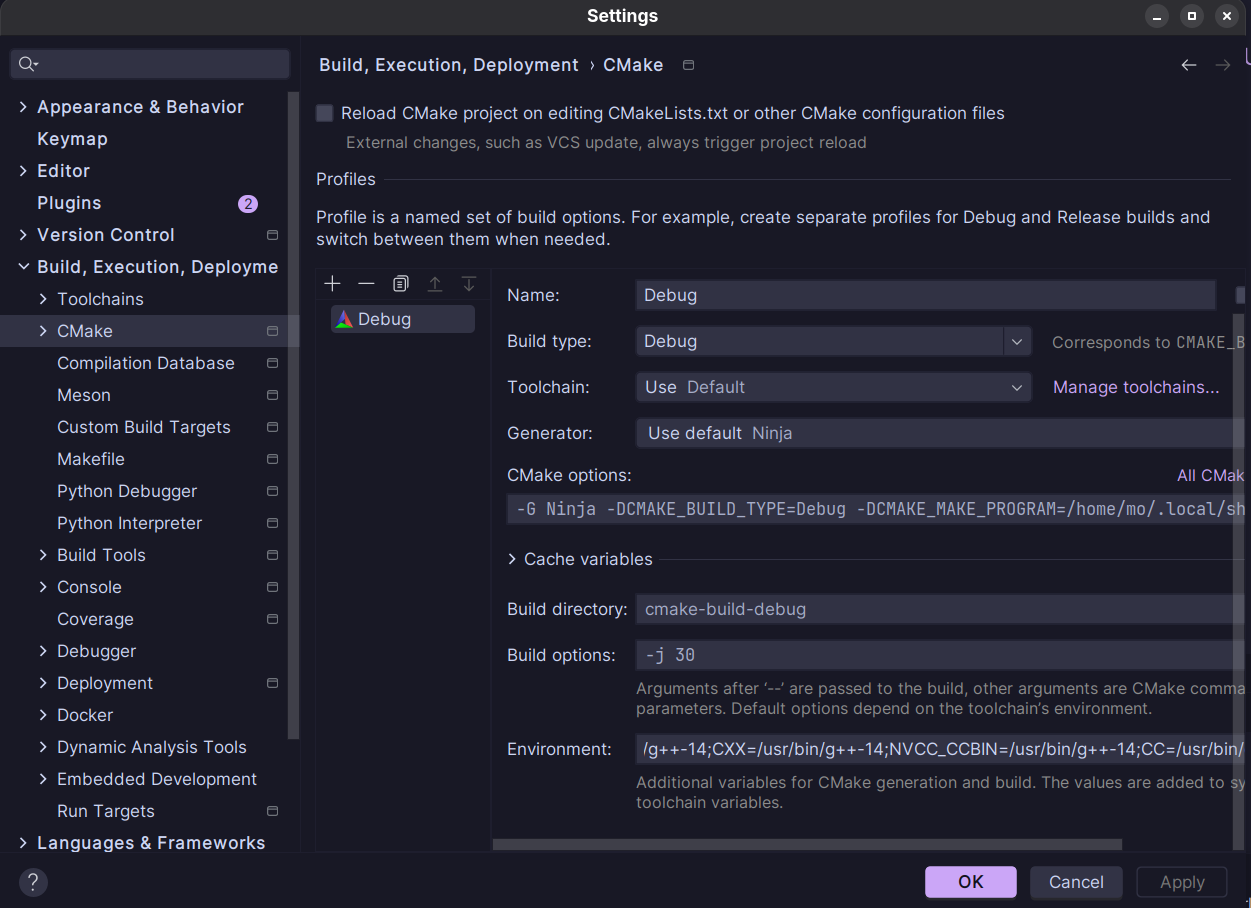
Go to Settings → Build, Execution, Deployment → CMake and add the following in Environment:

CUDAHOSTCXX=/usr/bin/g++-14;CXX=/usr/bin/g++-14;NVCC_CCBIN=/usr/bin/g++-14;CC=/usr/bin/gcc-14

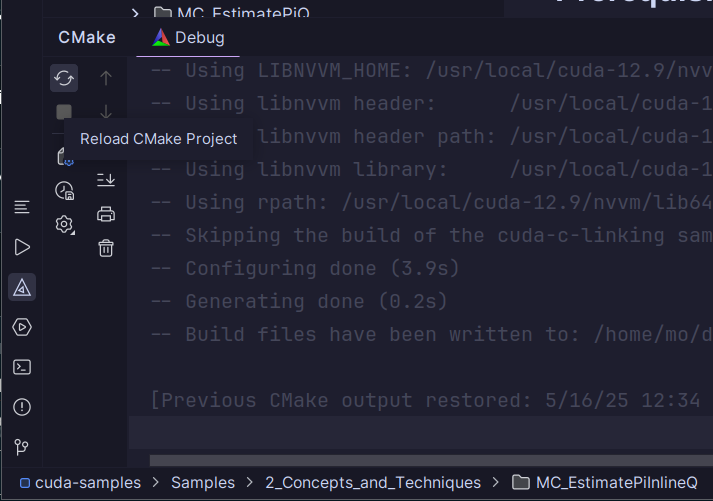
Then reload the CMake project, which you can easily do from the bottom left corner of the IDE
12 Likes

very nice, high fives

2 Likes

Excellent! A trivial correction was to remove the quotes here:
export CC=/usr/bin/gcc-14
export CXX=/usr/bin/g++-14

2 Likes

Thanks! I removed the quotes in the post.

1 Like

I really wish NVidia would update their compiler toolchain to accommodate this, it should a fairly trivial fix using preprocessor macros. This does work like a treat though. I sometimes symlink the gcc-14 and g+±14 executables into /usr/local/cuda-x/bin directory, since I think this is added to the head of the PATH when invoking nvcc.

1 Like

Almost all of this worked for me expect the patch for math_functions.h, it seems to be missing 1 function?

@@ -2553,7 +2553,7 @@
  *
  * \note_accuracy_double
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 sinpi(double x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 sinpi(double x) noexcept(true);
 /**
  * \ingroup CUDA_MATH_SINGLE
  * \brief Calculate the sine of the input argument 
@@ -2576,7 +2576,7 @@
  *
  * \note_accuracy_single
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  sinpif(float x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  sinpif(float x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_DOUBLE
  * \brief Calculate the cosine of the input argument 
@@ -2598,7 +2598,7 @@
  *
  * \note_accuracy_double
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 cospi(double x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ double                 cospi(double x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_SINGLE
  * \brief Calculate the cosine of the input argument 
@@ -2620,7 +2620,7 @@
  *
  * \note_accuracy_single
  */
-extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  cospif(float x);
+extern __DEVICE_FUNCTIONS_DECL__ __device_builtin__ float                  cospif(float x) noexcept (true);
 /**
  * \ingroup CUDA_MATH_DOUBLE
  * \brief  Calculate the sine and cosine of the first input argument 

Looking at it again, perhaps just the first line is missing?

1 Like

Hi, this is working like charm.

I got an error

CMake Error at CMakeLists.txt:5 (project):
  No CMAKE_CUDA_COMPILER could be found.

  Tell CMake where to find the compiler by setting either the environment
  variable "CUDACXX" or the CMake cache entry CMAKE_CUDA_COMPILER to the full
  path to the compiler, or to the compiler name if it is in the PATH.

You can simply fix it by:

export CUDACXX=/usr/local/cuda-12.9/bin/nvcc

Thanks a lot!

1 Like

Small correction about this. You do not need to specify to use the open-source driver, the nvidia-driver package is the open-source driver by default. But it is not documented on the slighly outdated RPM Fusion page about the driver install or CUDA.

Will try this out soon, thank you for the writeup.

I’m getting an error when trying this out:

CMake Error at /usr/share/cmake/Modules/FindPackageHandleStandardArgs.cmake:233 (message):
  Could NOT find OpenMP_CUDA (missing: OpenMP_CUDA_FLAGS
  OpenMP_CUDA_LIB_NAMES)
Call Stack (most recent call first):
  /usr/share/cmake/Modules/FindPackageHandleStandardArgs.cmake:603 (_FPHSA_FAILURE_MESSAGE)
  /usr/share/cmake/Modules/FindOpenMP.cmake:616 (find_package_handle_standard_args)
  Samples/0_Introduction/UnifiedMemoryStreams/CMakeLists.txt:32 (find_package)

I did exactly as instructed and also tried installing libopm-devel, but none of which have worked. Does anyone know what is causing this issue? Did I do something wrong?

I’m travelling right now, so not at my desktop, but you may have to go a step further and load the modules as Fedora gives you the ability to use and load multiple MPI implementations

source /etc/profile.d/modules.sh
module load mpi/openmpi-x86_64

EDIT: responding to the right post, hence the above deleted post

EDIT 2: this is a reply

CUDA 13 that’s just released now supports Clang 20 and GCC 15, will test it out at some point and report back, or make a new post.

Cuda samples builds out of the box with cuda 13.0 on fedora 42, without issues.

1 Like

I am already on CUDA 13.0 on Fedora 42, though instead of using the drivers from RPMFUSION I used to official drivers. The reason is that I want the compute drivers only and RPMFUSION only provides the display + compute drivers.

Here is the link to the NVIDIA documentation I followed.

After that you can install CUDA toolkit as described here.

And finally you can install the container toolkit as describes here.
https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html

One important note though, some software like Pytorch is not yet release for CUDA Toolkit 13.0. There is currently ongoing process to release it for that version but as of today 12.9 is the highest stable supported version.

P.S. If you have Secure Boot enables after the driver installation you should run sudo mokutil --import /var/lib/dkms/mok.pub to enroll the module key into the UEFI then reboot.

1 Like

Just to mention, pytorch nightly has some cu130 builds.


So at least those are usable.

Now if you use xformers, flash attention, sage etc you would have to build from source using this pytorch version.

I’m using the P2P driver on my case from here GitHub - aikitoria/open-gpu-kernel-modules: NVIDIA Linux open GPU with P2P support, as I have multiple GPUs and make it so the 3090/4090/5090 P2P work.

I.e.

pancho@fedora:~/cuda-samples/build/Samples/5_Domain_Specific/p2pBandwidthLatencyTest$ ./p2pBandwidthLatencyTest  
[P2P (Peer-to-Peer) GPU Bandwidth Latency Test]
Device: 0, NVIDIA GeForce RTX 5090, pciBusID: 1, pciDeviceID: 0, pciDomainID:0
Device: 1, NVIDIA GeForce RTX 5090, pciBusID: 3, pciDeviceID: 0, pciDomainID:0
Device=0 CAN Access Peer Device=1
Device=1 CAN Access Peer Device=0

***NOTE: In case a device doesn't have P2P access to other one, it falls back to normal memcopy procedure.
So you can see lesser Bandwidth (GB/s) and unstable Latency (us) in those cases.

P2P Connectivity Matrix
    D\D     0     1
    0       1     1
    1       1     1
Unidirectional P2P=Disabled Bandwidth Matrix (GB/s)
  D\D     0      1  
    0 1736.17  24.35  
    1  24.62 1771.60  
Unidirectional P2P=Enabled Bandwidth (P2P Writes) Matrix (GB/s)
  D\D     0      1  
    0 1741.98  28.38  
    1  28.67 1755.68  
Bidirectional P2P=Disabled Bandwidth Matrix (GB/s)
  D\D     0      1  
    0 1737.98  30.20  
    1  30.47 1769.44  
Bidirectional P2P=Enabled Bandwidth Matrix (GB/s)
  D\D     0      1  
    0 1751.59  52.19  
    1  55.94 1765.44  
P2P=Disabled Latency Matrix (us)
  GPU     0      1  
    0   2.08  14.38  
    1  14.65   2.10  

  CPU     0      1  
    0   1.75   4.67  
    1   4.66   1.63  
P2P=Enabled Latency (P2P Writes) Matrix (us)
  GPU     0      1  
    0   2.08   0.48  
    1   0.48   2.07  

  CPU     0      1  
    0   1.68   1.27  
    1   1.29   1.68

For version 13 of cuda in Fedora 43, following your advice, I had to add “noexcept (true);” to the functions:
extern double rsqrt (double __x) noexcept (true);
extern float rsqrtf (float __x) noexcept (true);
And everything worked!

Yup, same here. CUDA 13 is meant to support GCC 15. I still find it weird that we still have some of these issues where we have to fix external linking in header files.