Okay! Finally able to close the loop on this and post results.

-
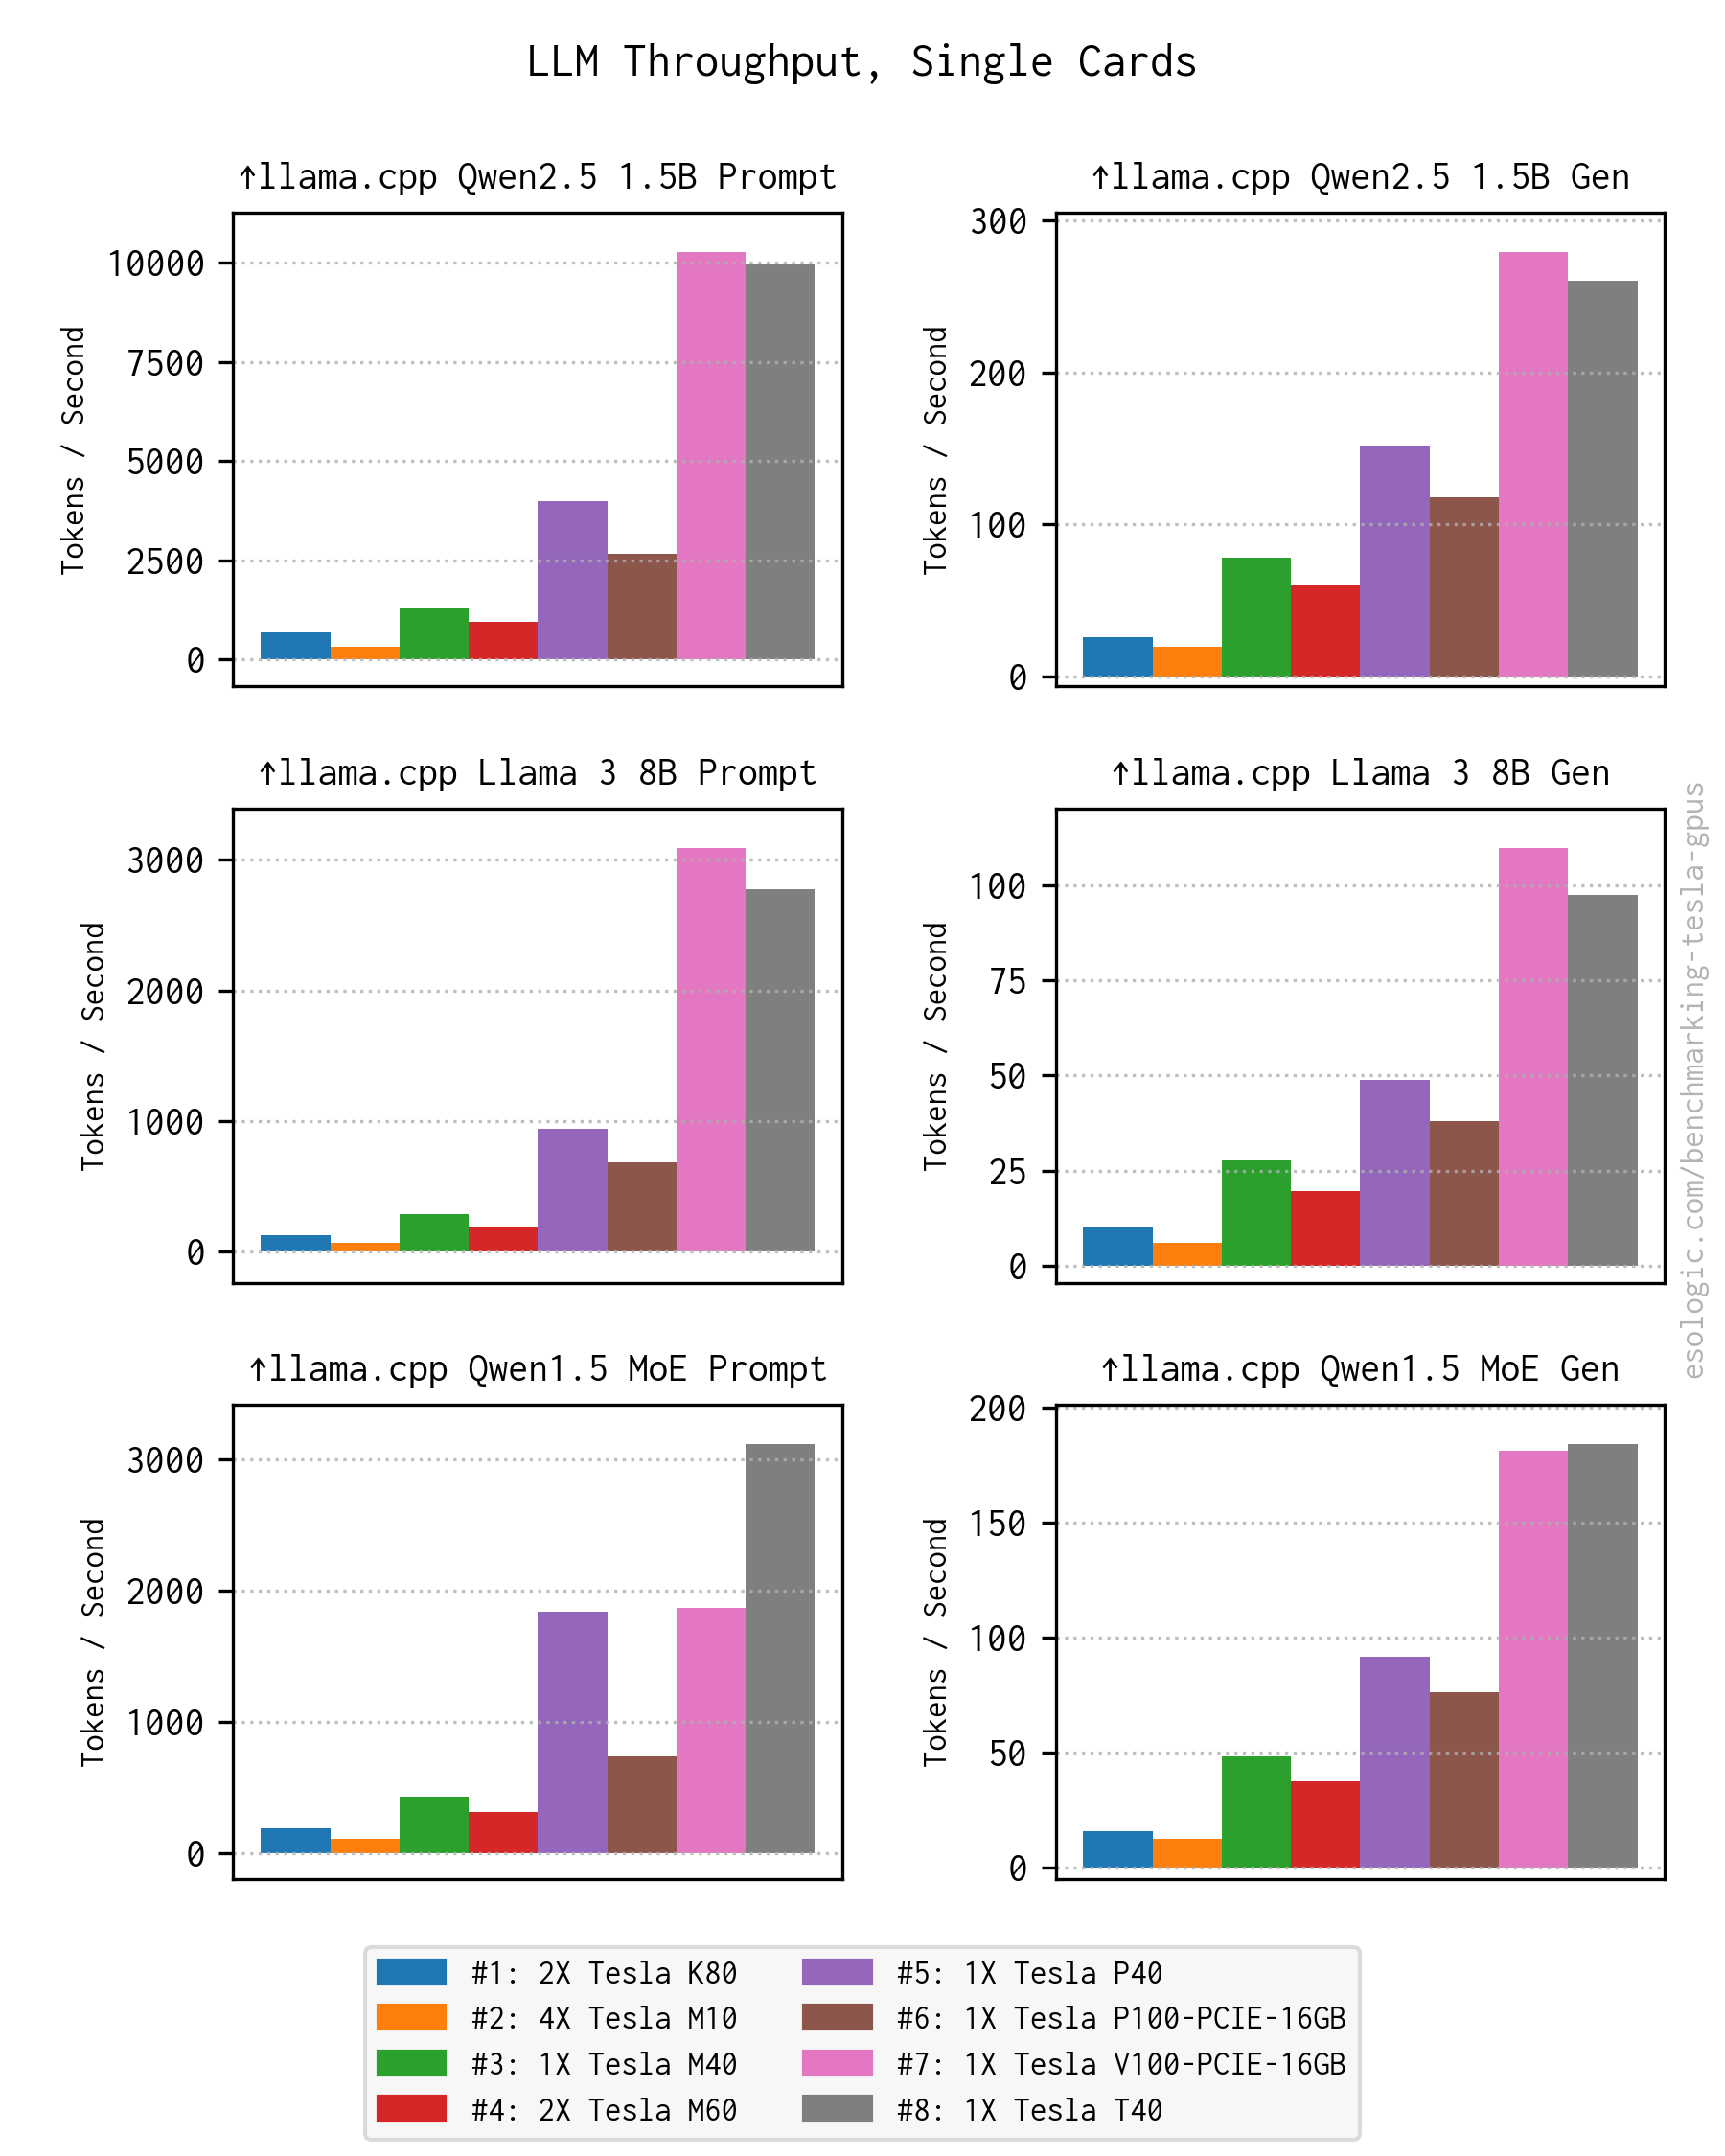
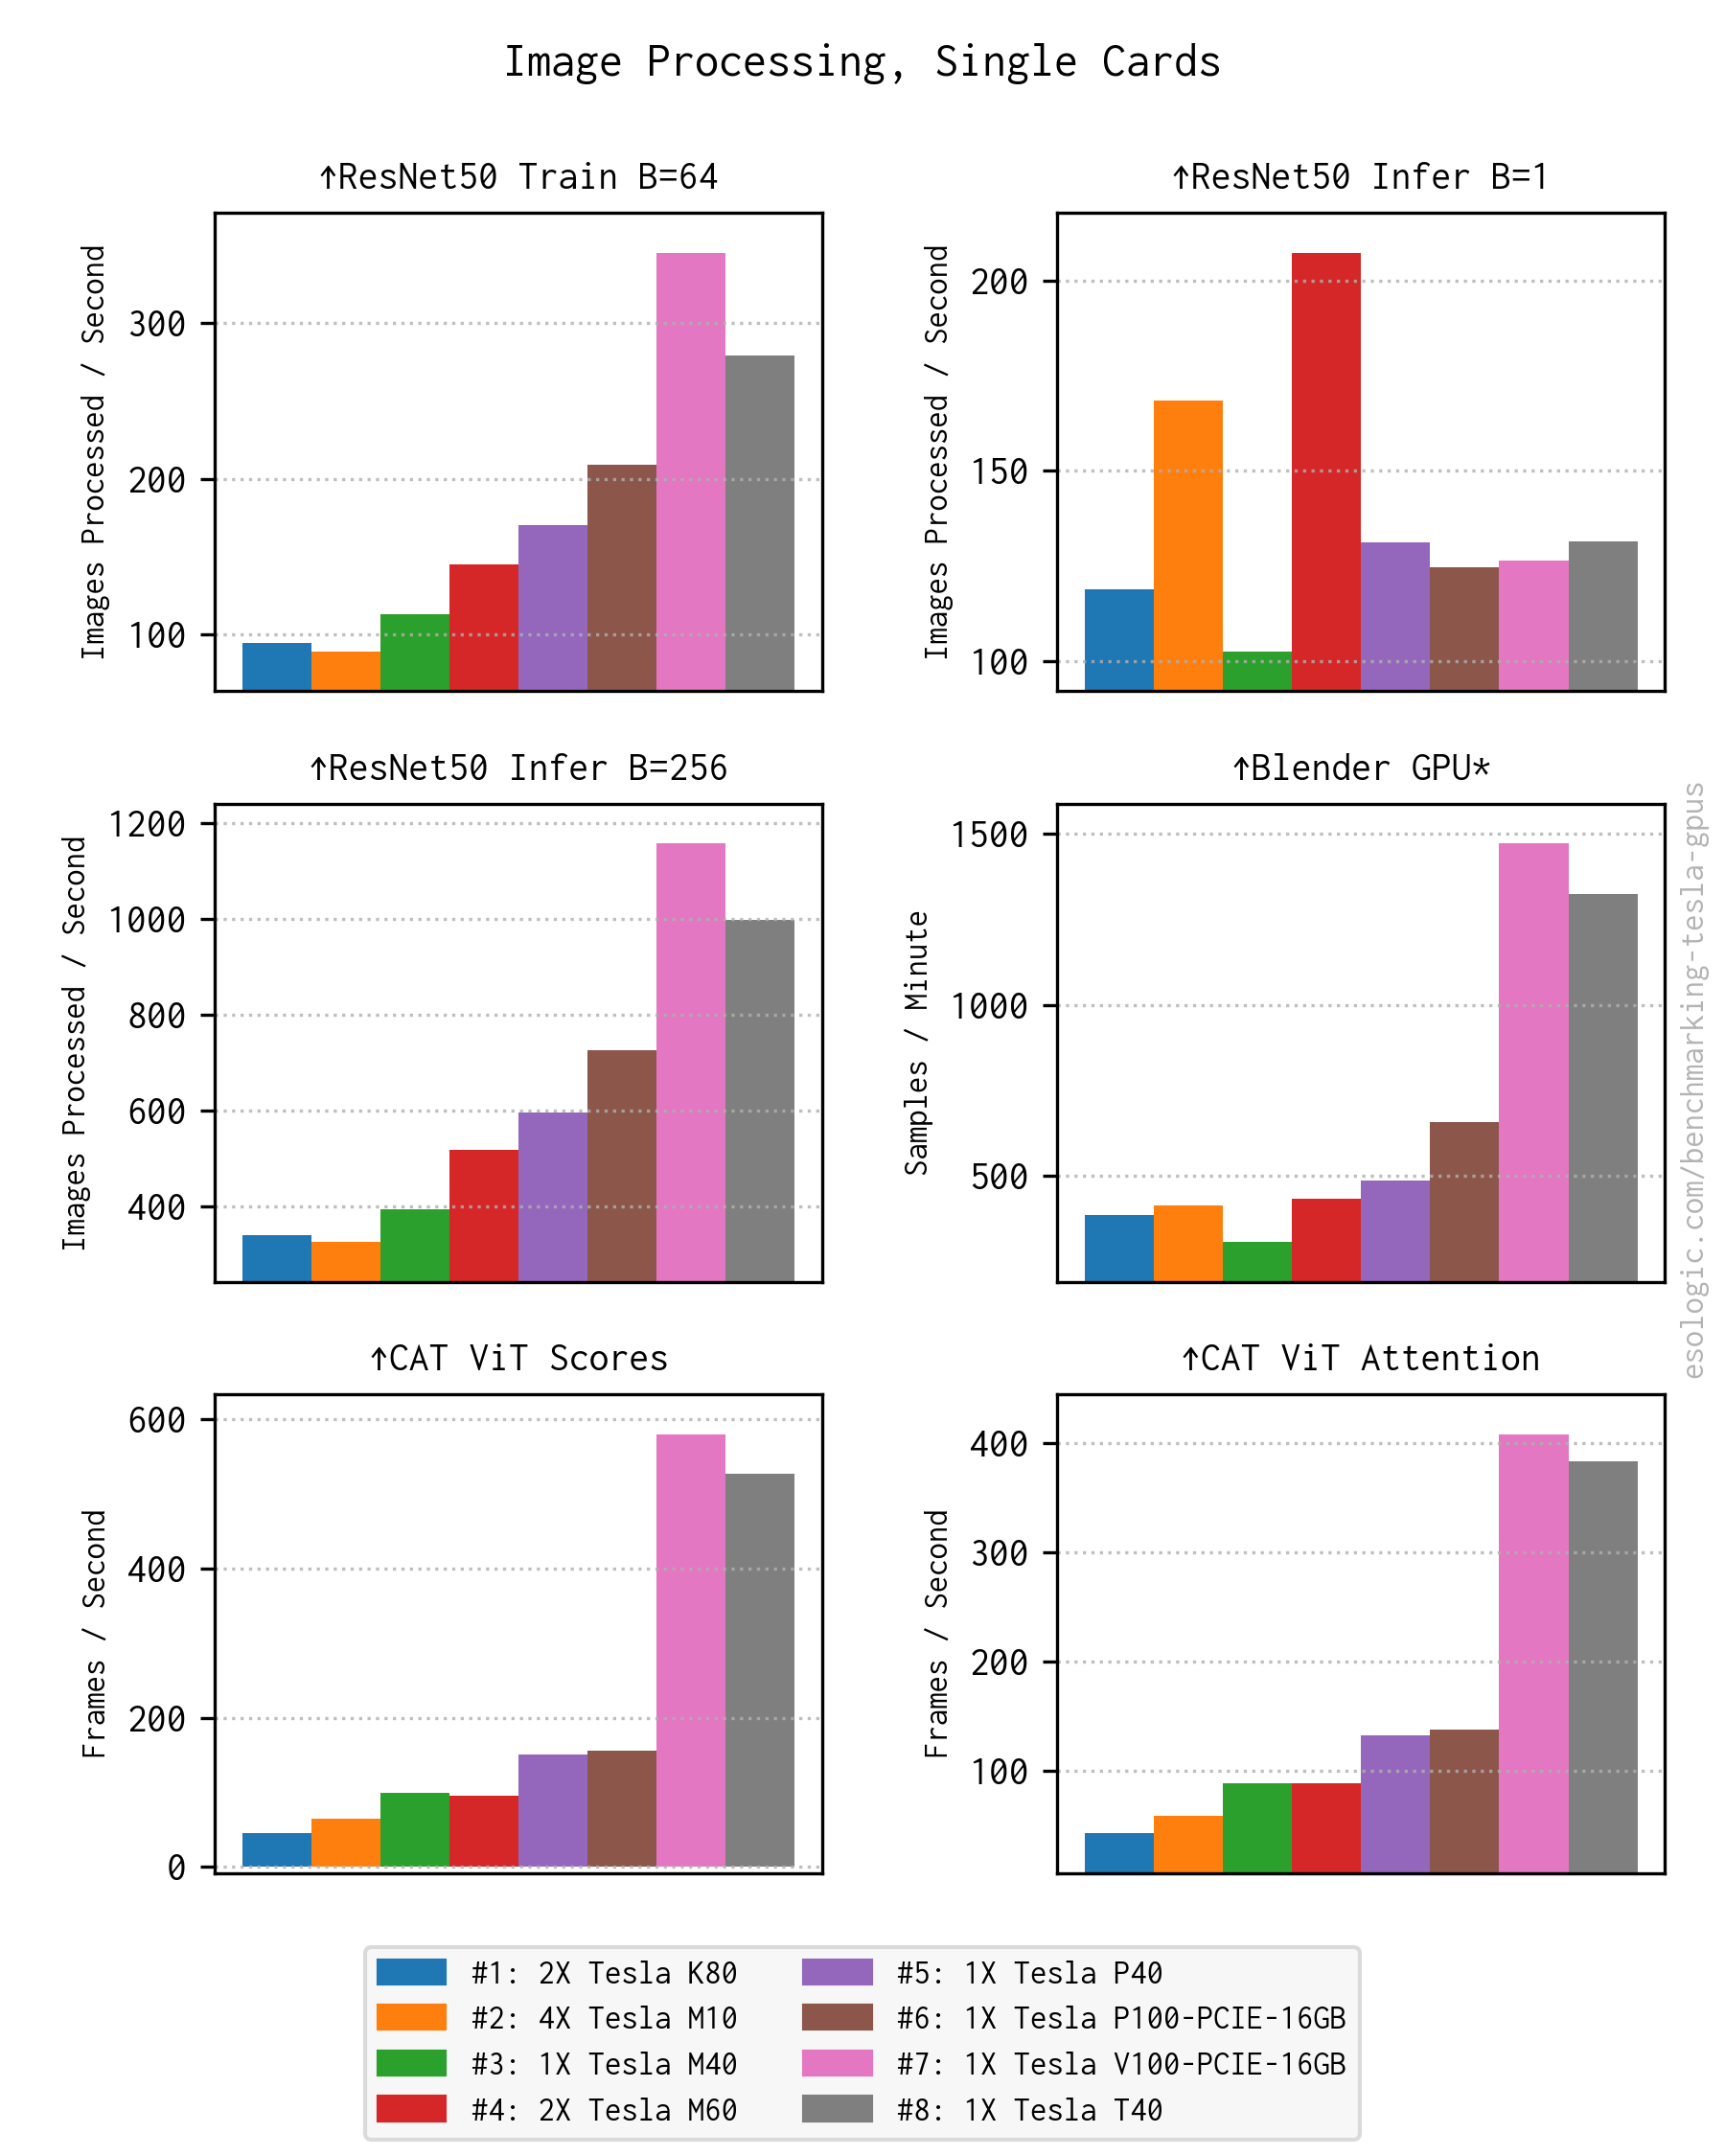
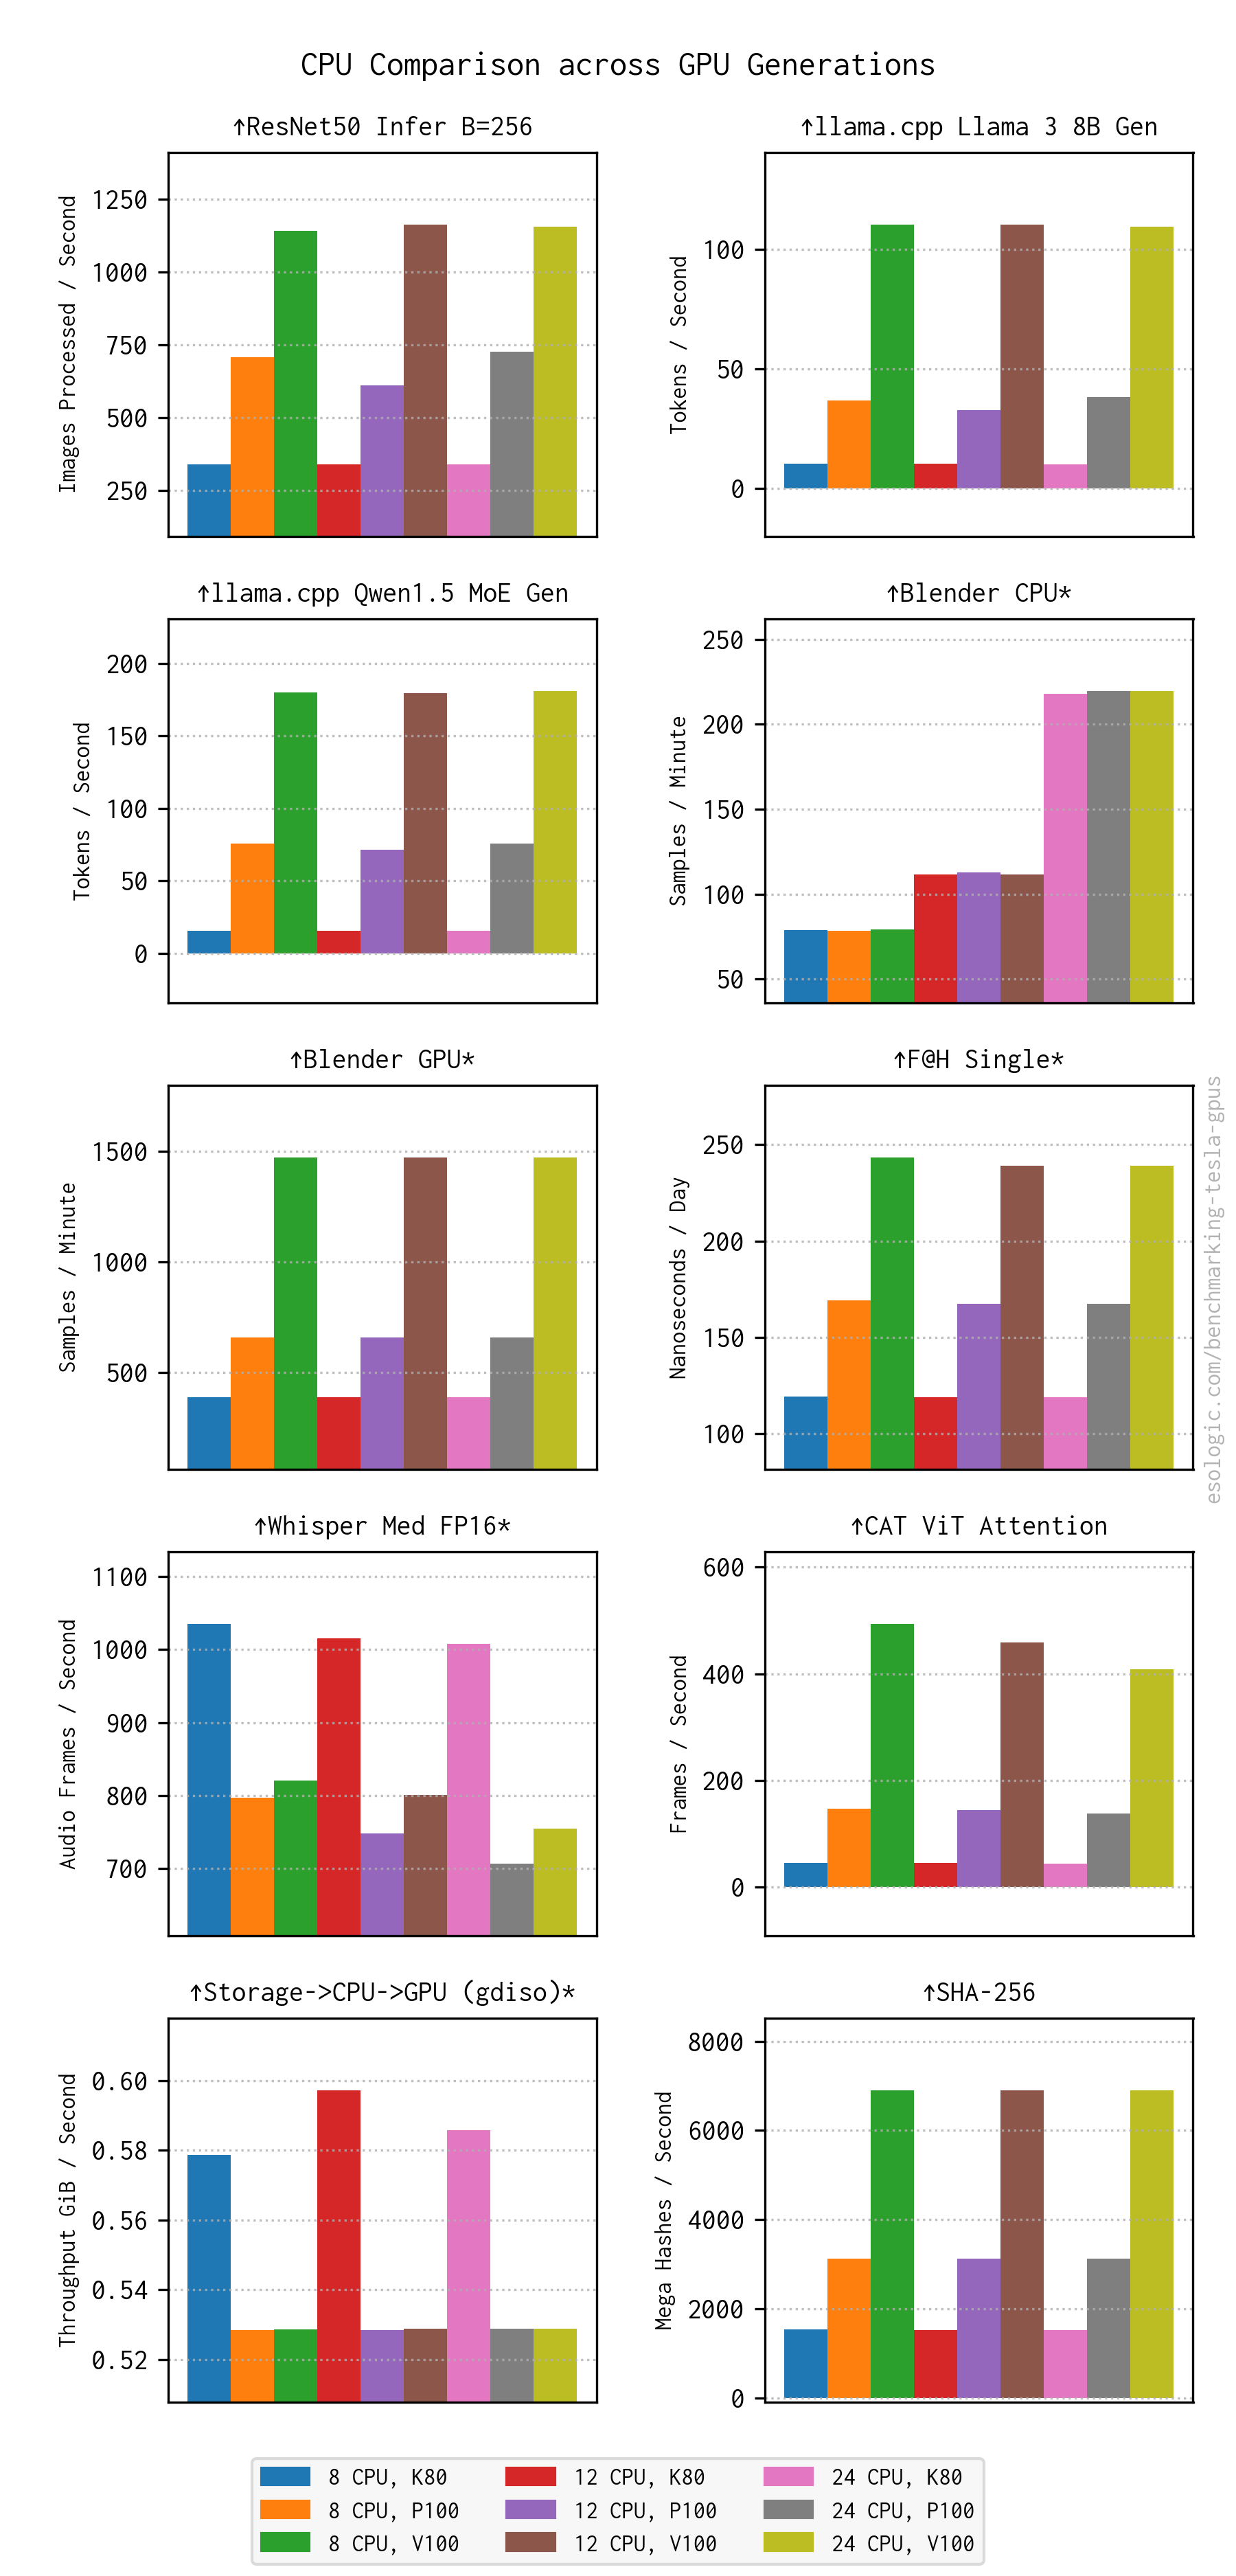
The V100 is the Sweet Spot: The V100 (16GB) surprised me. Its performance hangs right up there with the much more expensive T40 and was a big improvement over the incrementally improving previous generations.
-
P40 > P100 for LLMs: The community consensus holds true here. If you specifically want to run Large Language Models, with Pascal, use P40.
-
M60 is a Whisper Beast: If you have a ton of audio transcription to do, the M60 is shockingly capable (beating even V100) and can be had for only $50.
-
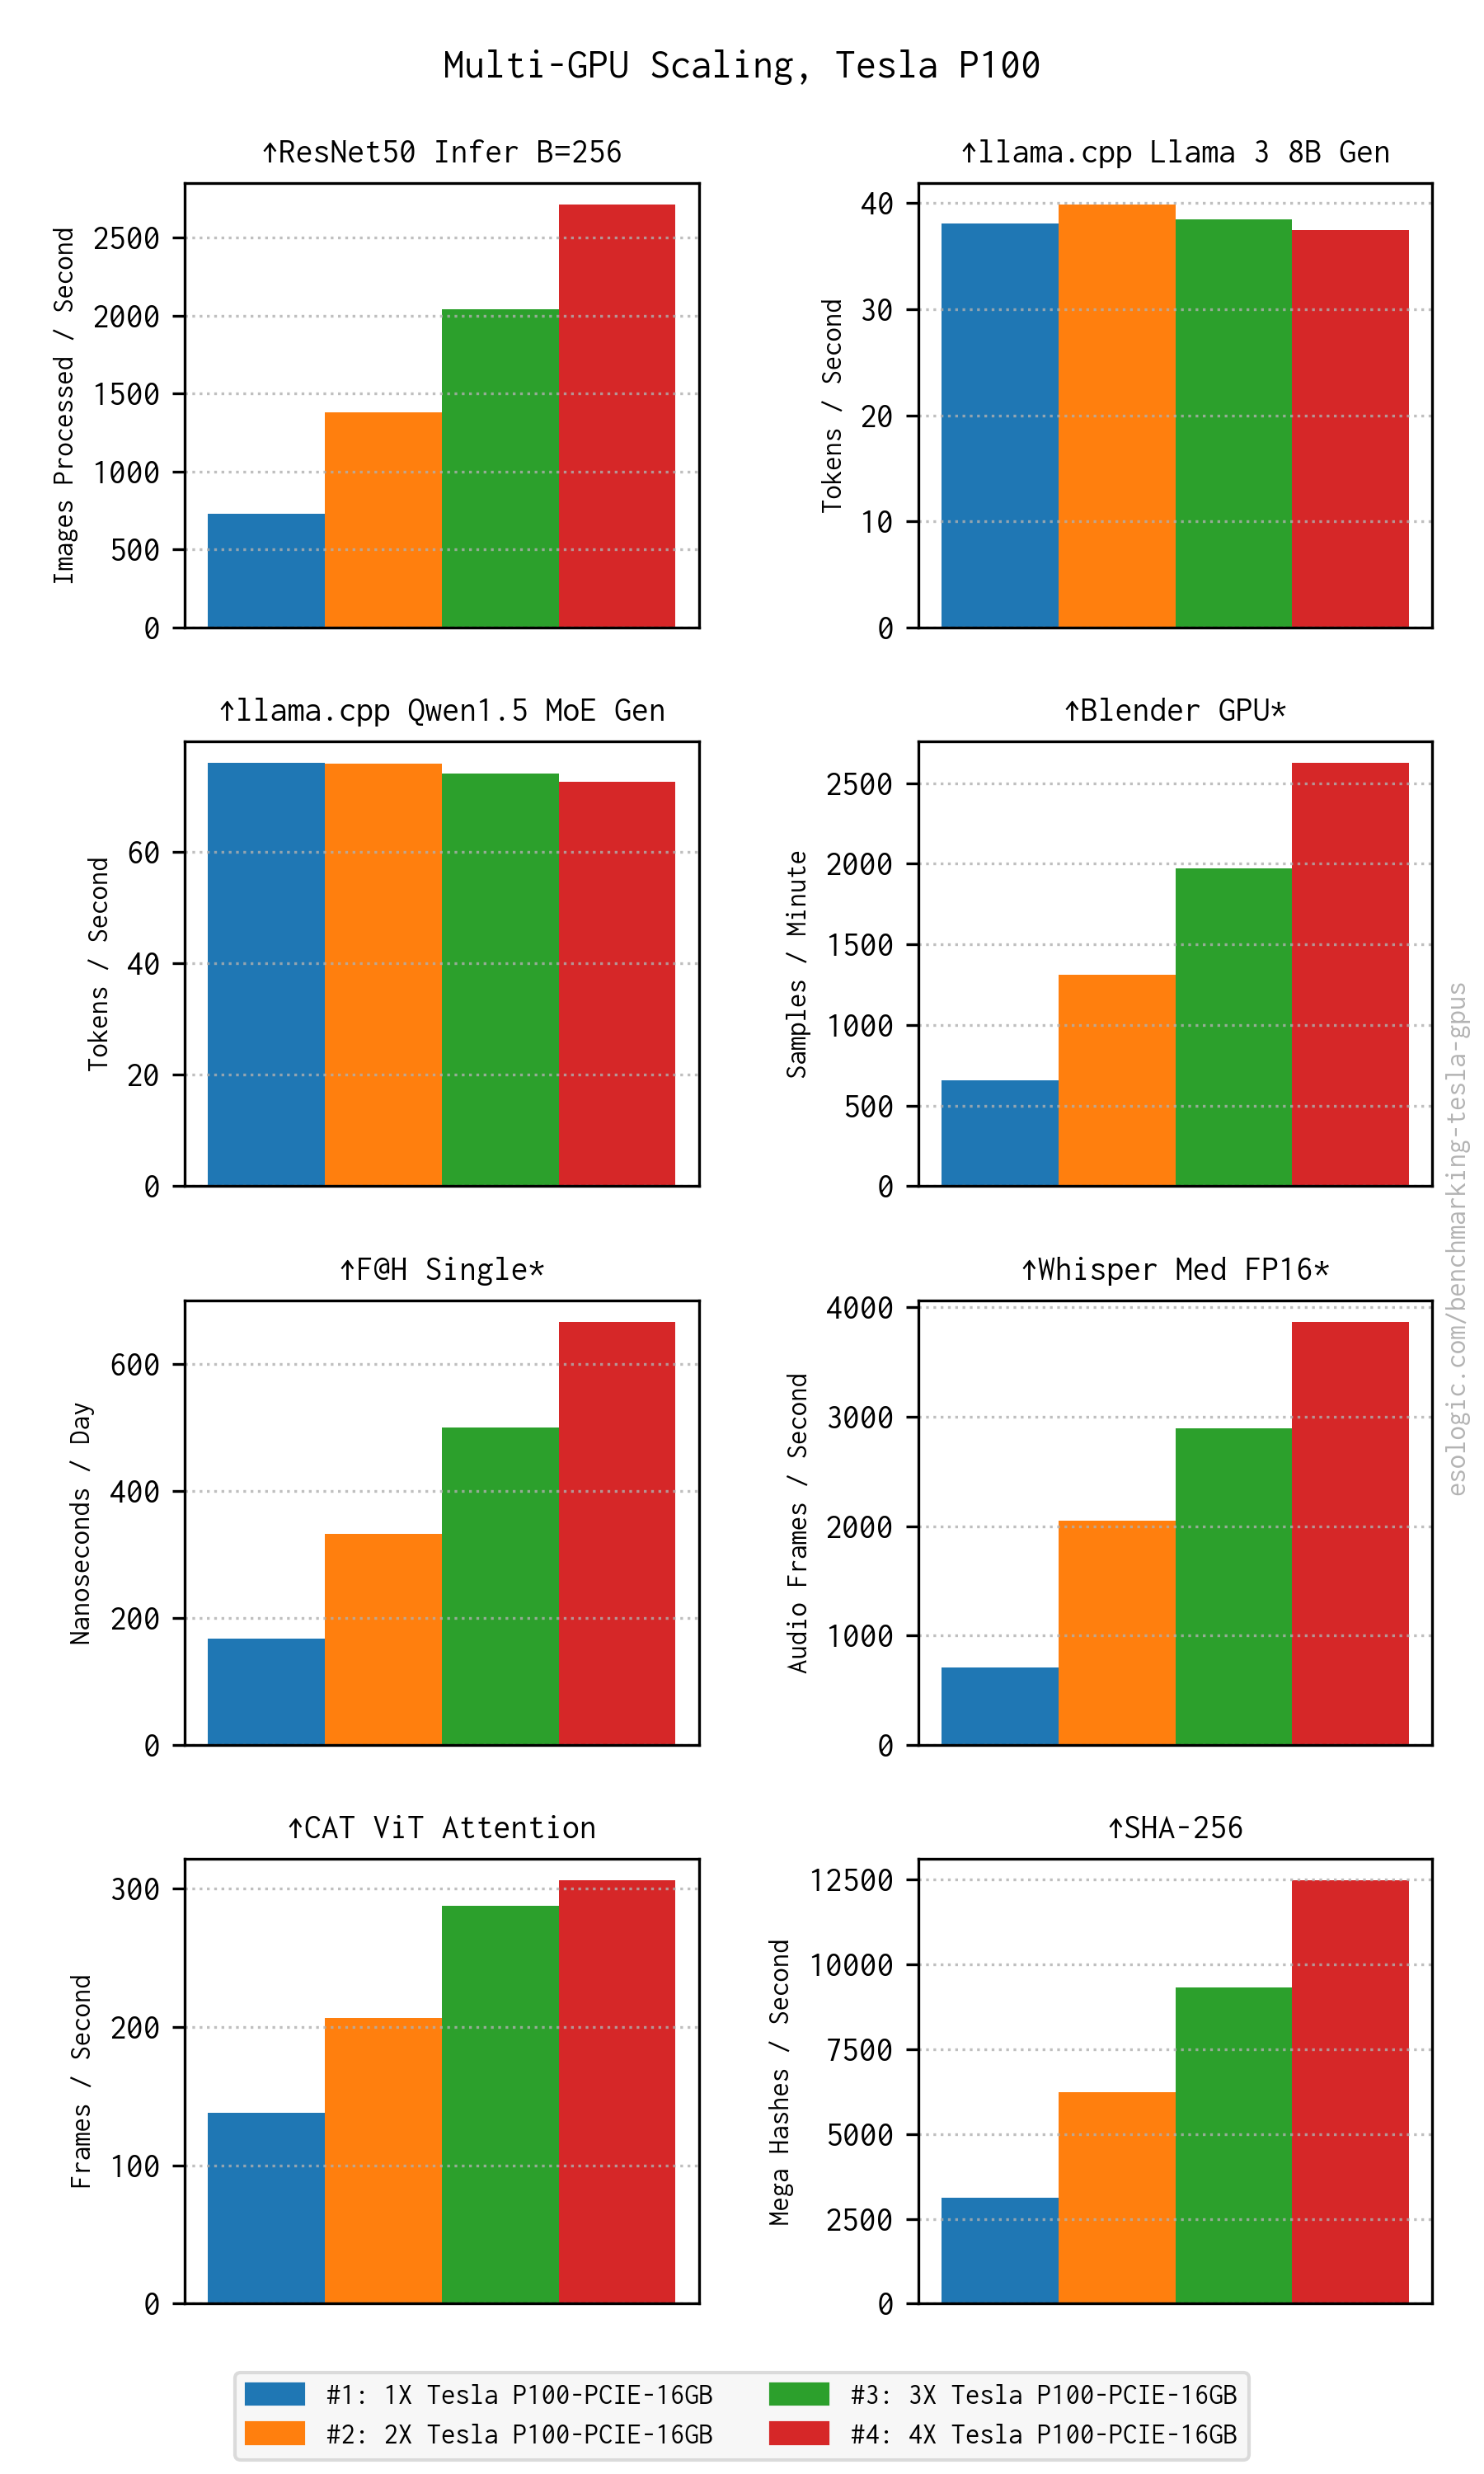
Scaling is mostly Linear: Stacking cards doesn’t hit a wall of diminishing returns within a 4U chassis. More GPUs generally equal linear performance scaling, though if you mix generations, slower cards will bottleneck your faster ones in LLM setups.
-
CPU/Mobo Choice: Faster single-core CPU speeds help slightly for tasks like Whisper and Vision Transformers, but generally, any cheap X99 board and high-lane Xeon will feed these GPUs perfectly fine.
The complete set of graphs and findings are on my blog. Now that I have the setup and tooling, I’d love to benchmark more workloads, anything missing from my findings?