About a month ago I intended to repurpose my 5950X on MSI Meg X570 ACE WiFi with 128GB worth of DDR4 into a VM host, home lab server, local LLM host, swiss-army-machine?.. but things have gotten far out of hand. I’ve bought a bunch of new hardware, investing more in the repurposing of this old system than I did on the 9850X3D system I built to replace it, culminating in an Intel Arc Pro B70 GPU… Long story short the B70 has me feeling buyers remorse. Experimenting with Qwen3.6, Gemma4, etc on this build and on my MacBook Pro M1 Max I find that my MacBook Pro is much faster running the same models. Maybe I don’t have my Linux legs under me yet to have correctly got the llama.cpp/SYCL back end worked out correctly? Should I rethink my build focus and the B70, should I struggle on, any advice or encouragement is appreciated.
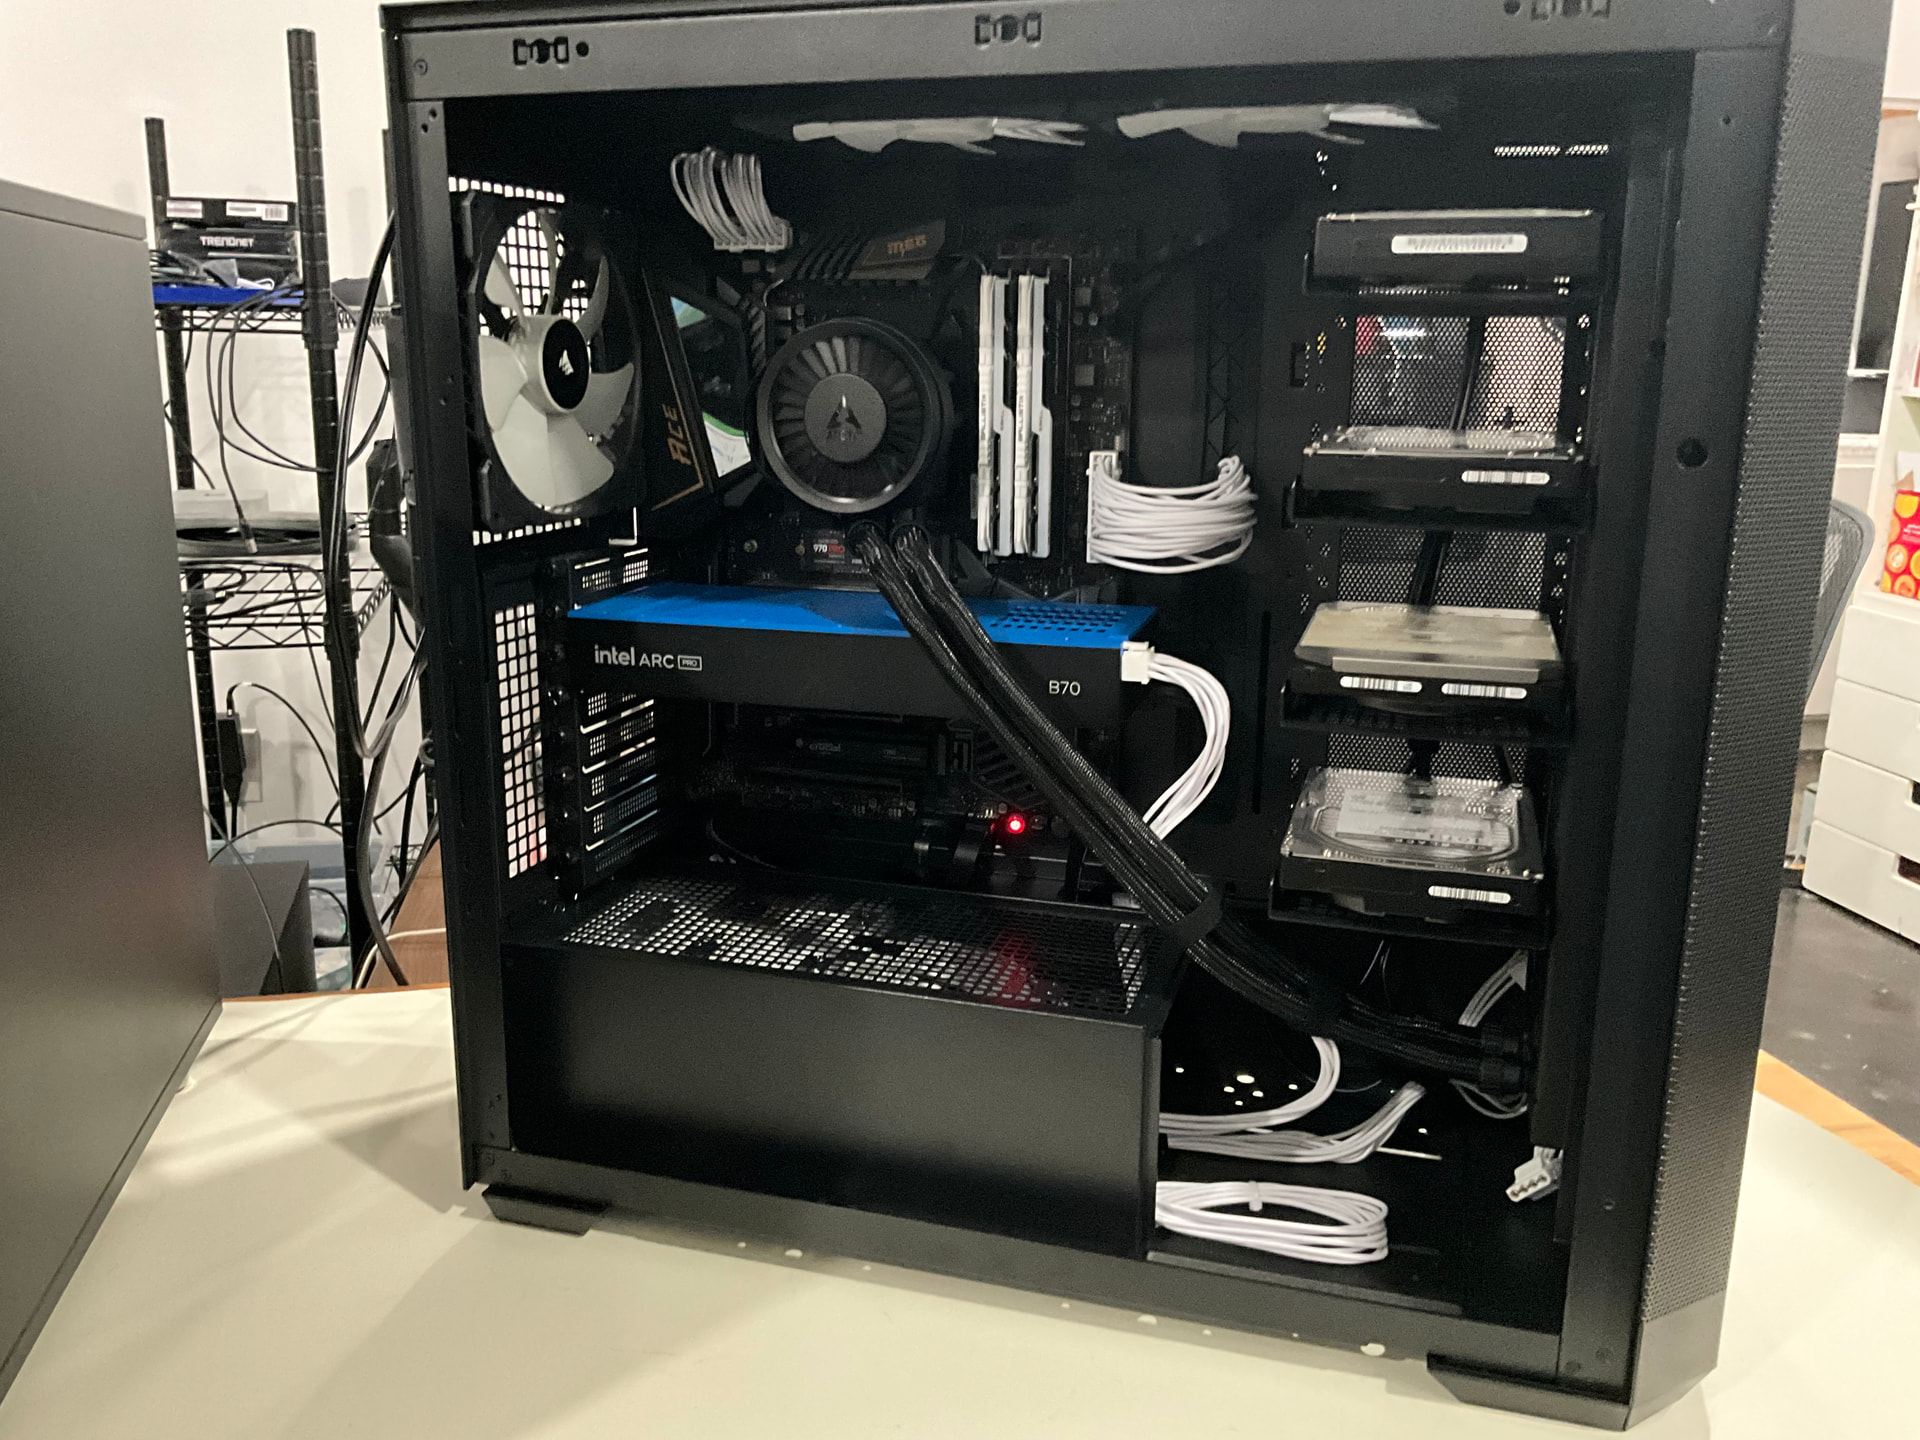
What kind of performance are you getting with the b70 now? I have had the kind of performance that I expected from it, with the big asterisk that is, I use LM Studio on Windows. It uses the Vulcan backend in llama.cpp which is the easiest way to get the card doing real work. SYCL native can be faster, but is limited in the models it can run well.
Same models and quant if possible, for example Gemma4 26B A4B QAT, ran in LM studio on both platforms. Though maybe I should have managed my expectations better, but…
~20 tk/s with the B70 and vulkan/llama.cpp. It seems to be loading the model in VRAM, loading down the GPU ~50%, the CPU ~60% and engaging some system memory as well..? Uhh? Wuht?!
~60 tk/s on M1 Max using metal. As Matthew McConaughey says “aalllllrightttt”.
I’ve seen between 7-20ish tokens per sec, depending on model, running the on the CPU and system memory so that makes me suspect the models are not running solely on the B70.
Check the vram utilization. If it’s not loading the whole model into vram, you will have a bad time.
Apologies if you’ve already tried this, but try launching llama.cpp with -ngl 99 - basically, forcing it to offload all the layers to GPU.
As a quick sanity check I started over. I reinstalled Fedora 44 with the B70 installed, updated, installed the Intel toolkits, etc. Still using vulkan/llama.cpp runtime in LM Studios. I went from ~20 tokens/s to ~47 tokens/s running Gemma4-26B-A4B-QAT and Qwen3.6-35B-A3B MoE models. So maybe I had conflicts with vulkan, mesa, and cuda after swapping different GPUs in and out of this computer so many times?
I would say…if you still have the opportunity to send the B70 back for a refund, and if AI is the main purpose, I’d recommend getting the R9700 instead. For single- and dual-GPU purposes, it’s far more performant; you’d be looking at 140-150t/s without MTP on Qwen3.6-35B-A3B, and 3-4kt/s prefill.
Apologies if that’s not an option and I’ve just made the buyer’s remorse worse 
Oh woe… the deep remorse!.. jk 
I could still send it back, but AI is not the only use case I’m considering. Although, that aspect has hijacked my focus the last couple of days for sure. Originally I was considering the B70, at sub-$1k, as a jack-of-all-trades master-of-none proposition for Linux, virtualization, AI, solidworks compatibility, and anything else that might come up. Now, I only feel sure about the master-of-none part.
Some other things I considered:
Trying to find a used RTX Pro A4000 to go with one I happen to have on-hand. Running 2 sounded plausible and that would give me 32GB of VRAM.
A Pro R9700, 32GB VRAM for $1600 to $1650.
A RTX Pro 4000 Blackwell. Fast, 24GB VRAM at ~$2k, actually more than I really want to spend atm.
A second RTX 5080, was never actually a serious contender.
Well, I know the R9700 is great at Linux and AI, the other bits…outside my wheelhouse.
What does boggle my mind is the price difference - I didn’t realise there was such a gulf between them in the US. Here in the UK, the B70 and R9700 are pretty much the same price (ie in the £1200-1300 range), which makes the B70 a definite “nope”.
What quantization on the models are you using?
I got my B70 not a long time ago and I get around 70-80 t/s using 4-Bit Quantization(Q4_K_P to be more specific ) on Qwen3.6.
There are also some optimizations to mesa and llama.cpp that are coming I think that should vastly increase performance.
I tried the SYCL backend and didn’t really see any noticeable difference.
Though if you are not happy with it, of course send it back.
The quantizations are:
Q4_K_M on Qwen3.6-35B-A3B
Q4_0 on Gemma4-26B-A4B-QAT and Gemma4-31B-QAT
A b70-pro-tip for you. For whatever reason, Intel doesn’t care for MoE models. You will get as good or better performance with the dense models. I use qwen-3.6 27b dense at Q6 and get the same token generation speed. With 128k context it just barely fills the entire 32G of VRAM.
You got 20 t/s with that? very strange.
There is a llama.cpp command to list devices, maybe it’s trying to spread the workload to your iGPU or something.
I was getting similar token generation for both the MoE and dense versions of the latest Gemma 4 version I tried. Qwen3.6 MoE was actually faster than Qwen3.6 dense.
I don’t believe the Ryzen 9 5950X has an iGPU. Unless I’m mistaken? I believe something is being loaded onto the CPU and system memory though, perhaps context? There is some small system memory consumption and slight CPU activity but it’s much smaller in magnitude than what is happening on the GPU side.
Did you make sure Above 4G Decoding and Resizable BAR are both enabled in your motherboard’s BIOS?
I have a B70 as well. Fun card to play with, but we’re not going to see what this card can really do for at least a few months at least. Your experience with an R9700 would be better for sure.
Thanks I’ll check those settings out.
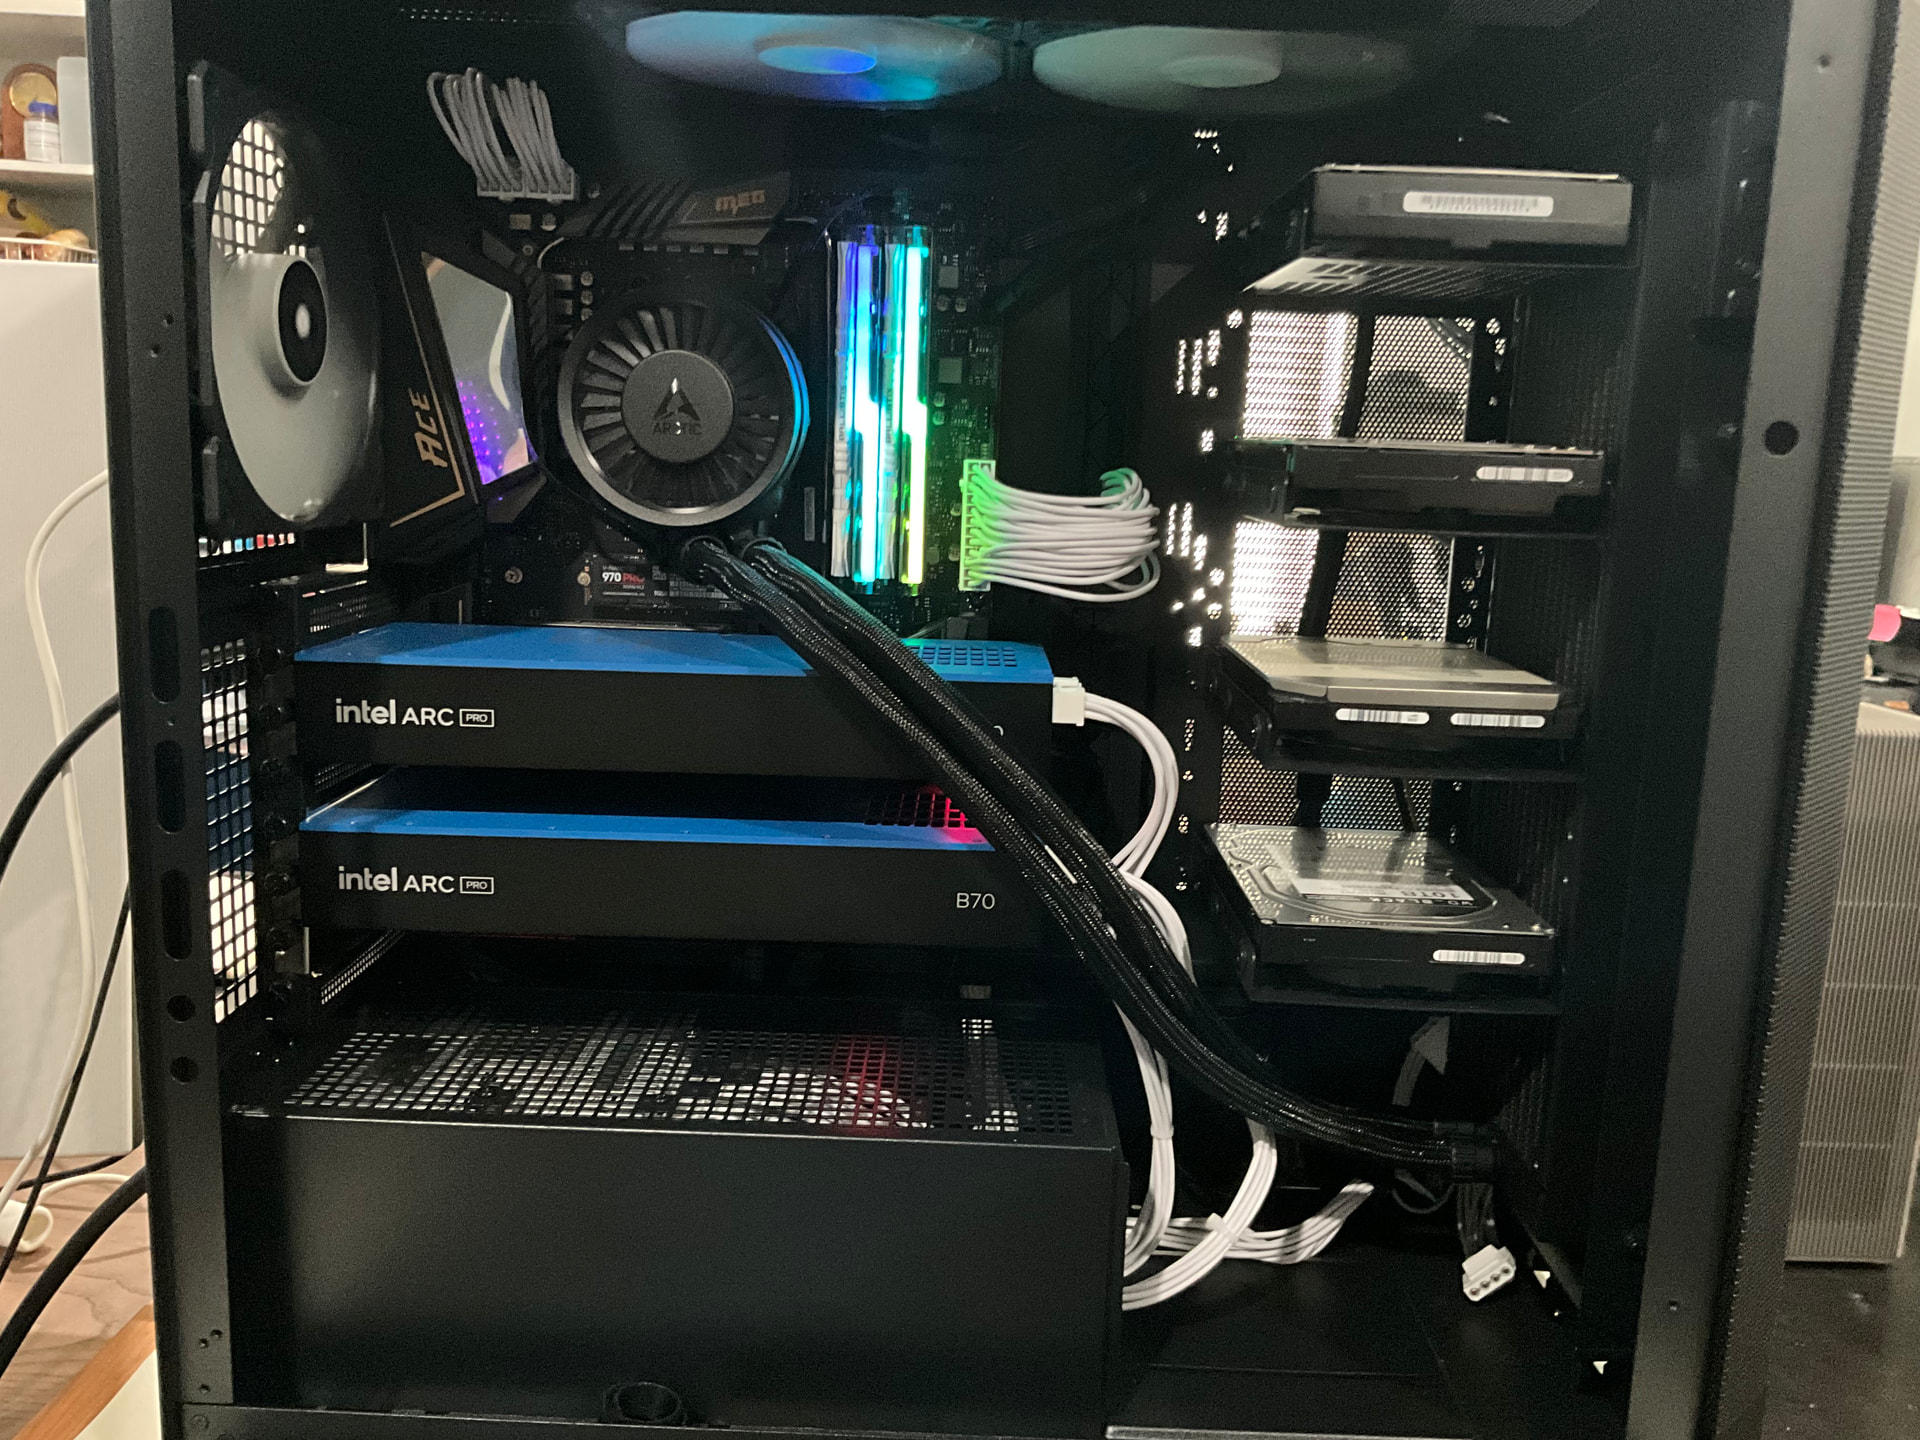
Through not much work on part I managed to get better performance out of the B70. At some point it turns out I did have Resizable BAR turned off BTW, though I did have more than that to deal with. Installing Fedora KDE helped things along. Once I had the first B70 working out, insanely, I got another one. After wrestling with that for a while… Finally as of today I was able to get +80t/s with the same model that is ~60t/s on my M1 Max MacBook. I wish I could systematically go through all I’ve done to get here but I attribute a lot of it just to trial and error at this point. I can’t believe I’ve fallen down this rabbit hole.
Intel just dropped vllm v0.21 support, so you might wanna give that a try. llm-scaler/vllm at main · intel/llm-scaler · GitHub
I haven’t had a chance to put it through its paces yet on my B60s, but I’m very optimistic. It’s relatively easy to install, see the Readme.
(vllm itself is kind of a pain to use. You have to get the incantation juuuust right, and even then sometimes it’s sometimes iffy)
a single b70 on its own is not that fast. though sycl helps a lot over vulkan. i used claude to help me build the full sycl stack. scaling up to two allows for long context qwen3.6 models. tensor parallelism helps a lot for speed but is currently broken on the xe drivers.