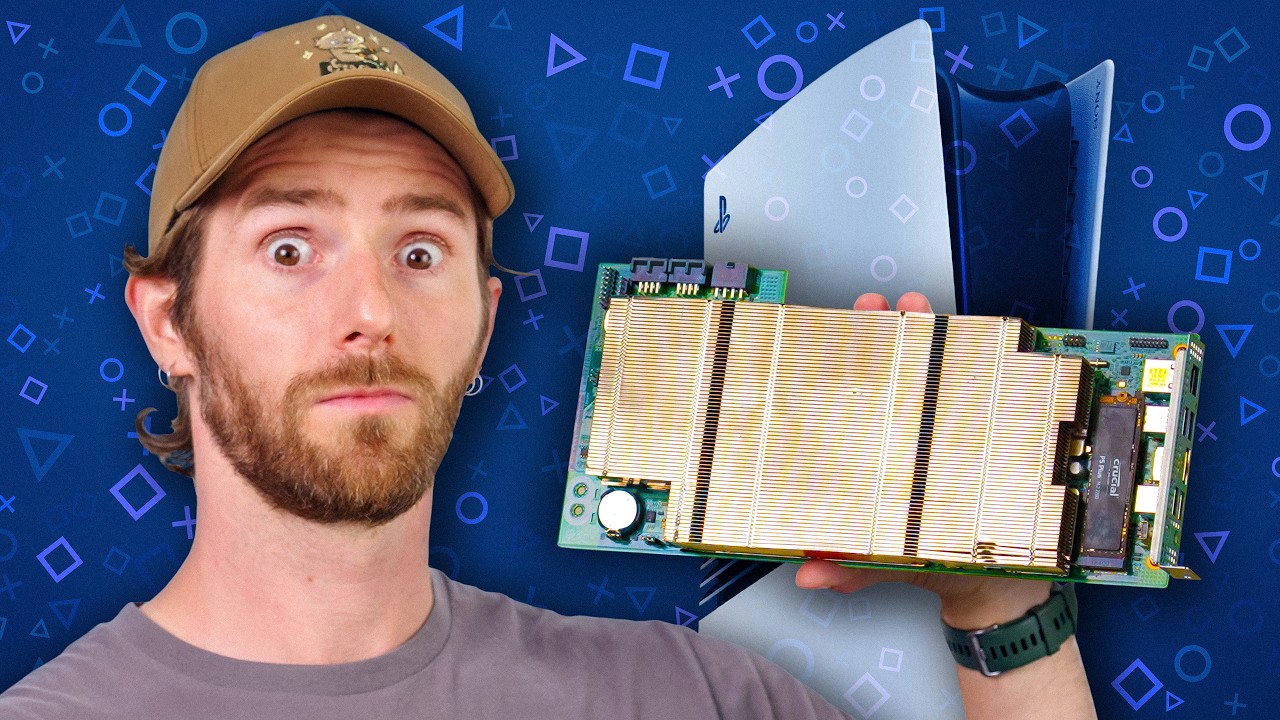
At ~$300 for 16gb VRAM, it might be a good dumpster dive ai cluster compared to the r9700, B60, or a single dgx spark
AMD BC-250 (PS5 APU) setup guide — Ollama + Vulkan inference, poor man's AI assistant via Signal, stable-diffusion.cpp image generation
TL;DR: The GFX1013 die physically has 40 Compute Units; the factory firmware masks 16 of them. A community kernel patch by S. Duggan re-enables the remaining CUs. After an independent FP32 sanity check (100M error-free multiply-adds), a controlled paired A/B re-run on 11 models followed. Key results at 4K context, llama.cpp b9265, verified-stock 24 CU → patched 40 CU:
Median generation speed-up: 1.32× (all 11 deltas positive, p < 0.01)Median prefill speed-up: 1.50× (prefill gains more because it’s more compute-bound)Granite 4.0-H Tiny (hybrid Mamba): 104 → 129 tok/s (+24%)GPT-OSS 20B MXFP4: 66 → 87.5 tok/s (+32%)Qwen3.5 35B-A3B MoE: 59.5 → 78.7 tok/s (+32%)QwQ-32B IQ2_M (reasoning dense): 9.6 → 14.9 tok/s (+55%)
The speed-up is larger for prefill than generation, consistent with generation being memory-bandwidth-bound on this hardware (adding compute units helps less than reducing weight bytes per token). A roofline measurement confirms: peak streaming bandwidth 357 GB/s, peak FP32 3901 GFLOP/s, ridge point 10.9 FLOP/byte — all LLM decode quantizations sit left of the ridge (bandwidth-bound regime). The unlock is bounded by power/cooling: the 40-CU arm ran at 116 W median vs 101 W at 24 CU, holding the clock ~3–4% lower under the oberon self-throttling governor. A better-cooled unit would likely gain more.
The long-context picture is strong. The Qwen3.5 35B-A3B MoE runs to 64K filled (16.6 tok/s, n=3) — provided ttm.pages_limit is genuinely at the full 16 GiB (§3.3). The dense qwen3.5:9b also runs to 64K (16.4 tok/s) and retrieves all 5 needles at 128K; its smaller footprint leaves more headroom alongside the always-on services, so it’s the safer production default — but the MoE is now a genuine long-context option, not short-context-only. And the 40-CU unlock carries this into long context : re-run under the 14.7 GiB working-set guard, all four heavy MoEs climb the full 4K→64K ladder at 40-CU with 2/2 needle retrieval at every tier — the flagship Qwen3.5-35B-A3B at 74→48 tok/s — so the active-parameter speed advantage survives the long-context regime under the unlock, not just at stock 24-CU (§B9.2).
@wendell did you manage to get any bc-250s back when they were cheap?
My understanding is that nothing supports it right now. You can try LLMs using vulkan, but I dn’t think the back end has been properly plumbed and ROCm does not recognize it currently.
1 Like