WHAT DO YOU WANT FROM THIS WALL OF TEXT? LIKE… WHY BRO?
I want real, actual agent concurrency testing and not benchmark testing.
Frankly, I need use case data about how and where I want to invest my resources in local LLM, and how I’ve assessed and continue to assess where and how to scale. Do I want more GPUs? Do I want a better GPU instead of more GPUs? Do I want more VRAM that’s slower or less VRAM that’s faster?
My current environment consists of an RTX 5090 32GB, an AMD Strix Halo 128GB, and an RTX 6000 Pro Blackwell 96GB. My focuses are on tiered workload distribution to ensure the right complexity of task runs on the right space and takes the right amount of time to complete, and the overall concurrency to ensure I can run the number of agents that I require in parallel without overloading or overspeccing. I have to still do that manually. Ultimately, the goal would be to use routeLLM or some kind of fine-tuned model to do complexity vetting that could redirect on demand based on complexity. That’d be sweet: later.
Notes before we dive in:
- I am entirely inferencing workloads, zero training.
- I am not going to investigate prefill. I’d probably only do that if I had one of those new Mac Studios with the M5 Ultra.
- I like rounding my figures and shooting from the hip, so I round and I don’t mind rounding errors because I’m lazy. If you want to be pedantic, then do it yourself. It’s all the same to me.
- I am not a machine learning PhD so forgive my gaps; I am an idiot with more money than sense. I just trial and error everything in sandboxes until I get what I want. Here’s some trial and error with my incredibly well developed scientific method. Cat not to scale.
By now, I know better than to put any workloads onto CPU/RAM because it’s entirely untenable. The performance is not interactive, and not sufficient for what I am doing. This brings about the next question: how important are CPU/RAM to the load? Am I creating bottlenecks by paring down the system and focusing entirely on VRAM capacity and compute capability on the GPU? I would say no. I want to verify that before I cheap out on it.
CPU/RAM BOTTLENECKS OR…NOT?
I ran a test using previous concurrency testing scripts:
- “busy” that hits the GPU with 12 simultaneous prefills and context load ups and then dumps them and does it again, over and over again for 22 minutes, and
- “human” that staggers the prefills and context load ups instead of running them all in parallel.
In the “busy” I wanted to fill the entire kvcache to force a bottleneck on the GPU, which it does; temperature throttling gets triggered and the PCIe bandwidth shrinks during this period and the CPU peaks at 6.1% usage on a 12700kf. In “human” the staggering prevents the kvcache pool from filling as much, and spends less time capped and throttled.
These charts have me at marginal single digit percentage movement on my CPU and RAM used going down.
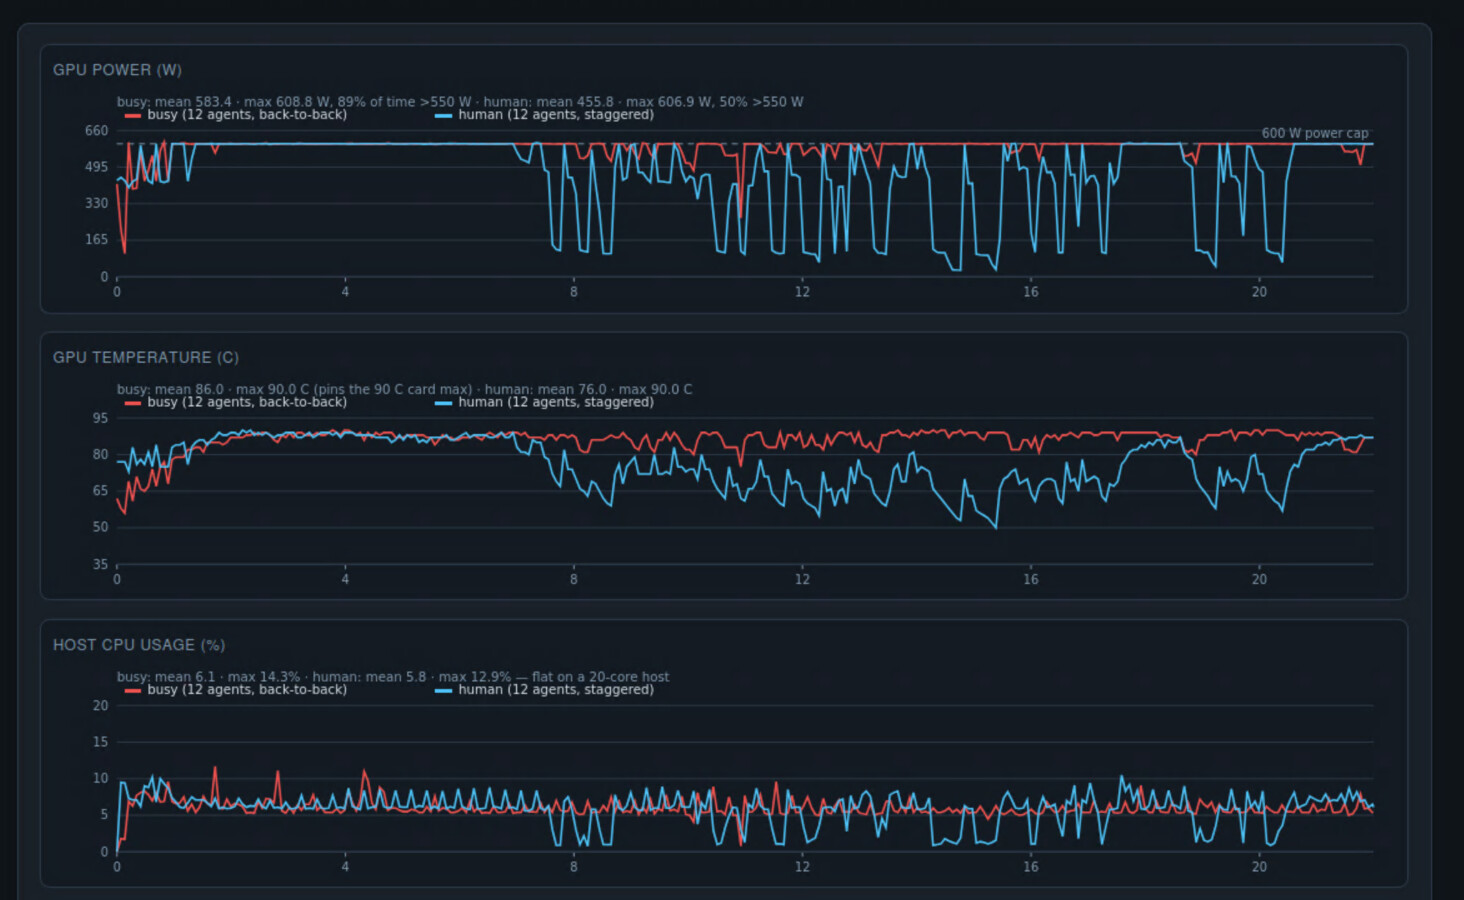
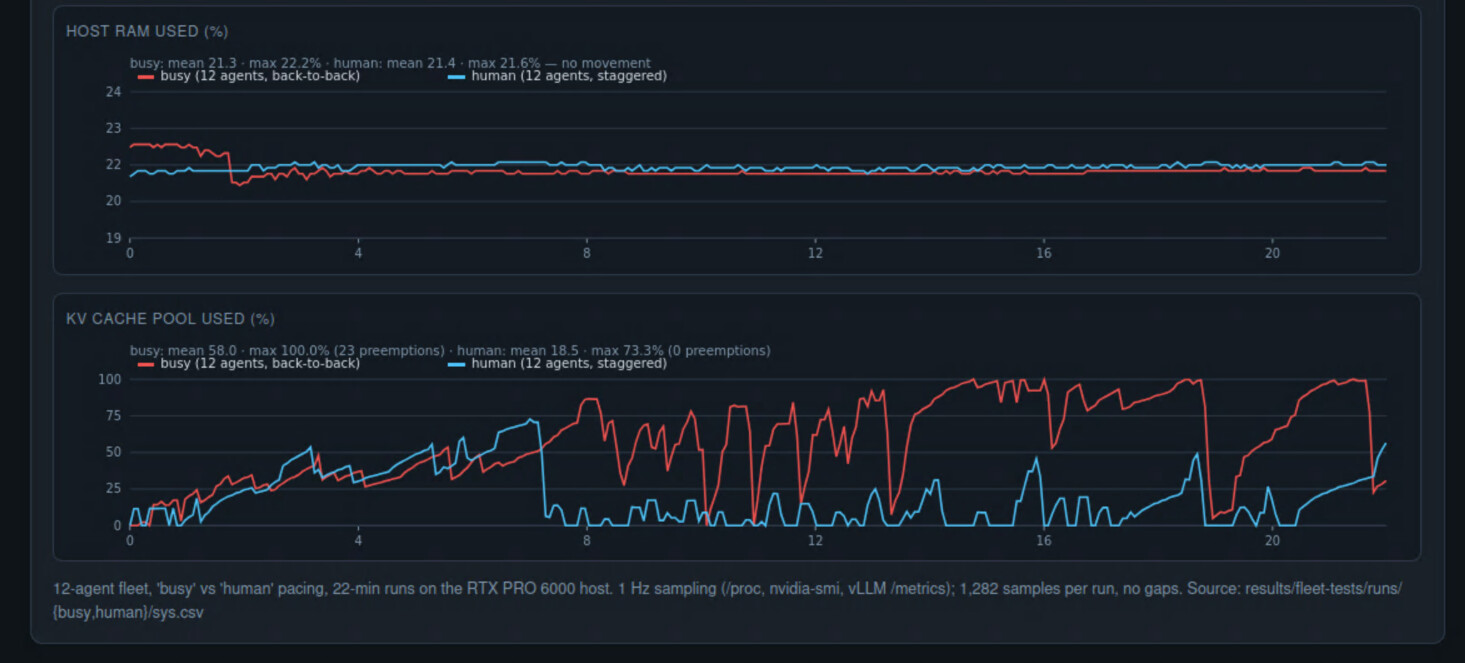
As a note, the kvcache pool used (last chart) shows pretty clearly when everything was done running in parallel, which is why I stretched the tests to as long a time period as I did. I wanted functional rotations to show up in this for a good sense of actual use cases.
In either case, there is a max out on the GPU side, and almost no movement on the CPU/RAM side. Question answered: CPU and RAM are nearly irrelevant for both fully offloaded workloads. Time to initially load a model is slower, sure, but that only happens at reboot. I’m content that I don’t need to scale out on RAM or CPU. Even a simple desktop combo can do it, and I could probably put it on even older hardware as long as the PCIe bus can handle it.
IT’S SCALIN’ TIME
Next up, I’ve been looking into concurrency across these three hosts to determine better how they scale and what can be loaded. Concurrency as defined by canned benchmarks is insufficient in my view. They are small context loads being thrown around at 2048 tokens over relatively short periods of time to measure burst aggregate token speeds. Great for benchmarks and overall speed/capacity, very poor for understanding what my actual use case concurrency performance is.

How many agents can I, personally, run before I start to slow down? Can I share tokens with friends without impacting my workloads? Just kidding, I don’t have any friends. But if I started selling excess capacity, how much can I share through liteLLM before it degrades?
It’s not an easy question to answer, but I will remind myself that scaling has a tipping point here. Aggregate token/sec will go up until I hit the maximum and then will decline. Token/s per agent will decline linearly. But where is that pivot point? Where’s my sweet spot? I have to measure.
Here’s what I’ve done: 4, 8, and 16 agent workloads on each of the systems. I’ve staggered them so they are filling at different rates, each running 100k context before compacting, and starting in a staggered way as well. That way they overlap at a mathematically predictable cadence but are otherwise running pseudo-independently of one another, just as they would if I was triggering and running agents (and agents calling subagents) in a real scenario. Things run at the same time, but not intentionally and not perfectly overlapping every time. This design is not perfect, but it’s 100x better than slamming the models with endless streams of context and seeing where they break down at max load.
I could tell you without these tests which host will run fastest, which will run the biggest models, which have the most available kvcache and can create the largest windows. I could also tell you which of these will be able to do the most precise or quality work at the most reasonable speeds. That’s on the back of the box, but I want to know how it will actually scale at doing those things. I must go faster.
HOW AM I TESTING?
So, the baseline:
qwen3.5-9b cyankiwi 4-bit. Why this one? This model is a Qwen3-Next hybrid: only 8 of 32 layers are full-attention (the rest are linear-attention with fixed-size state) — the reason the KV pool is 2.3× larger than a same-size dense transformer’s would be. I want to see how the kvcache pool impacts potential bottlenecks, so I want this.
I hear you saying it’s too small to do anything useful, and the 4-bit quantization makes it functionally useless! That’s not the point. The point is to determine how these systems scale with my workload timing/sizes so I can determine where I need to add more resources, or how I need to shift my workloads. I am making a big assumption that they’ll scale the same regardless of total parameter count or quantization, which is one I’m wiling to make based on what I’ve experienced to date.
Should I throw in a second 5090 for more VRAM? Should I cluster the Strix Halo? What’s the difference between two 5090s and two 6000 RTX pros other than VRAM? To figure these things out, I need to know how each scales and then I can decide what’s acceptable.
There are a million and one data points about loading the largest model you possibly can onto the biggest hardware you can afford (or get your hands on) but I have found that is worthless information to me.
I want to know the following: if I run the same model and the same context tests at different concurrency on different hardware, what is the degradation and fall-off of performance I can expect? This is completely independent of the consideration that I can only run 1x 100k context agent on my 5090 with a Qwen3.8 27B dense model. I can never run more than 1 agent of that size, but I need to know if I get more bang for my buck if I add a second 5090 to increase the VRAM for kvcache to run more agents, or if I should cluster the Strix Halo and accept the lower speed. Which one falls off quicker? Which one scales more?
Now I’m repeating myself. I’m data hungry. Important to know I’m on the right track. Something to remember is that concurrency is going to come down to memory bandwidth and compute and how they interact to form bottlenecks.
TESTING
Enough rambling. Here’s the 5090 chart. Self explanatory: agent count, tokens/s/agent, tokens/s aggregate, turns completed, kv cache max in use, compaction count.
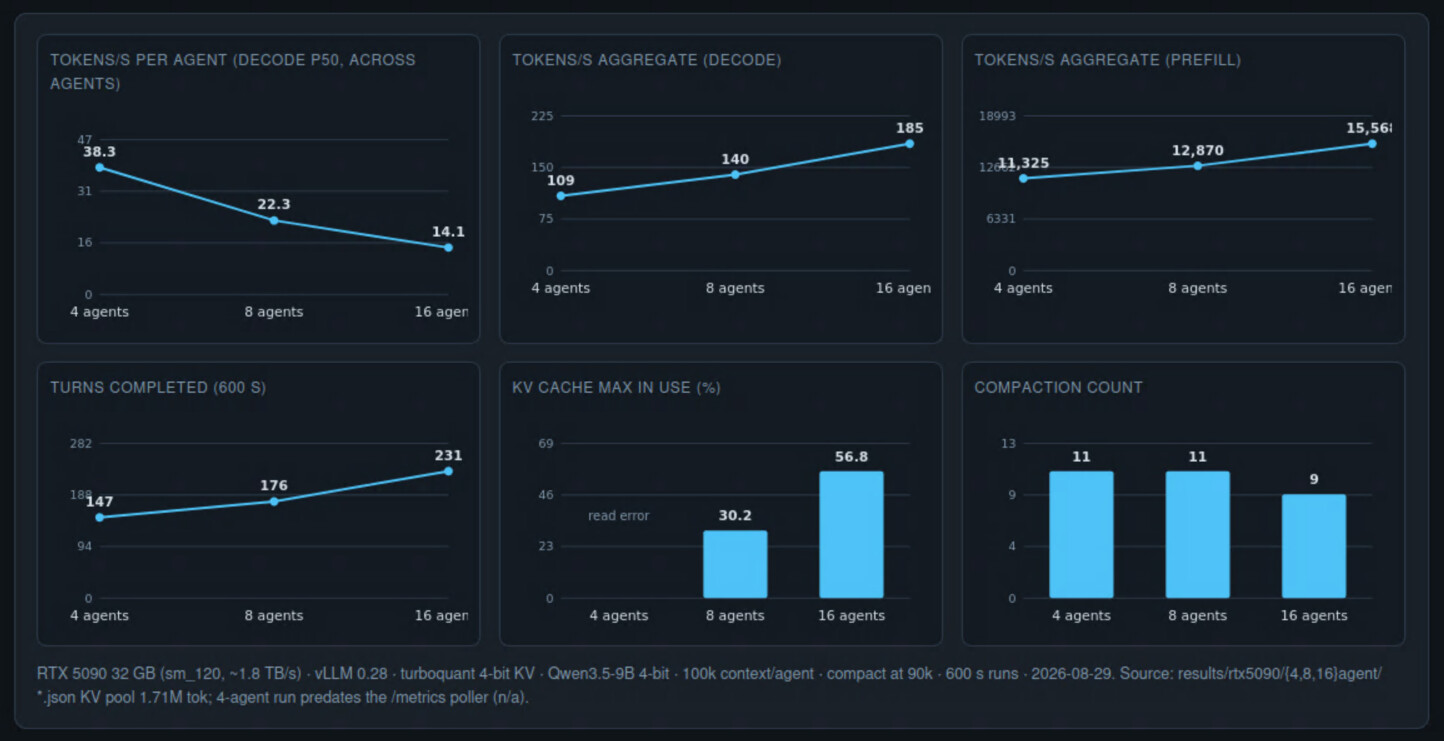
No data for 4 agents kvcache because I didn’t have that in my data collection for the first run. I’m not running it again, so you’ll have to use your imagination. I’m sure you’ll live.
Firstly, aggregate decode is not falling off even at 16 so it hasn’t hit max. However, the per agent decode is falling into dangerously useless territory for me at 13-17 tokens p50. It’s going to average very poorly as it scales up and by the time aggregate token/s hits max I won’t be happy with the performance. The number of times it got to the point where it compacted, despite having twice as many agents, was less at 16 than at 8. I don’t want this. It means interactivity performance drops.
Secondly, kvcache has very little to do in terms of limitations - the per-agent decode is dropping even though 16 agents are only hitting just over 50% of the max pool of kvcache at the peak.
I was expecting pre-emption where there would be waiting agents because kvcache pools maxed out, but it never happened because the system was unable to scale the memory usage past the agent count. This means adding more VRAM with a second 5090 is not going to get me what I want. Memory is less of an issue than compute. I can load larger models and more kvcache if I get memory, but I’m going to assume that scaling more actual agents is not going to work as well as I want. Tensor parallelism will help, but to what degree? A test for another day.
For now I’ll try the card made as an AI accelerator and see if there’s any difference other than VRAM available. I’ve run the same tests on the 6000. Here they are same as before.

As a reminder from the test setup - there is no VRAM limitation or comparison coming into play here. The 32GB on the 5090 vs the 96GB on the 6000 are being made inconsequential because I’ve ensured the smaller model size and kvcache normalizes the VRAM effects. This is purely a tensor compute and agent parallelization test. So here we see exactly what the difference is in choosing to use “consumer” GPUs.
As it turns out, if you want to scale agents up then it makes a difference. 20% boost on per agent decode, 25% on aggregate decode, and 37% on aggregate prefill (!). I do not expect this to change if I add more VRAM capacity to run multiple agents by adding a second 5090. The 6000 is the correct path forward if I want more agents to do more work at the same time. Probably get even better parallelism out of non-PCIe datacenter products so maybe I should get one of those.
For the third test unit, the Strix Halo is not so much of a head to head. It’s not going to go as fast as the other two, I already know that. It’s 5x slower than the other solutions pretty much all the time. I do want to know how it scales for my slower, low priority type tasks that I don’t mind setting and forgetting. How many can it handle before it slows down?
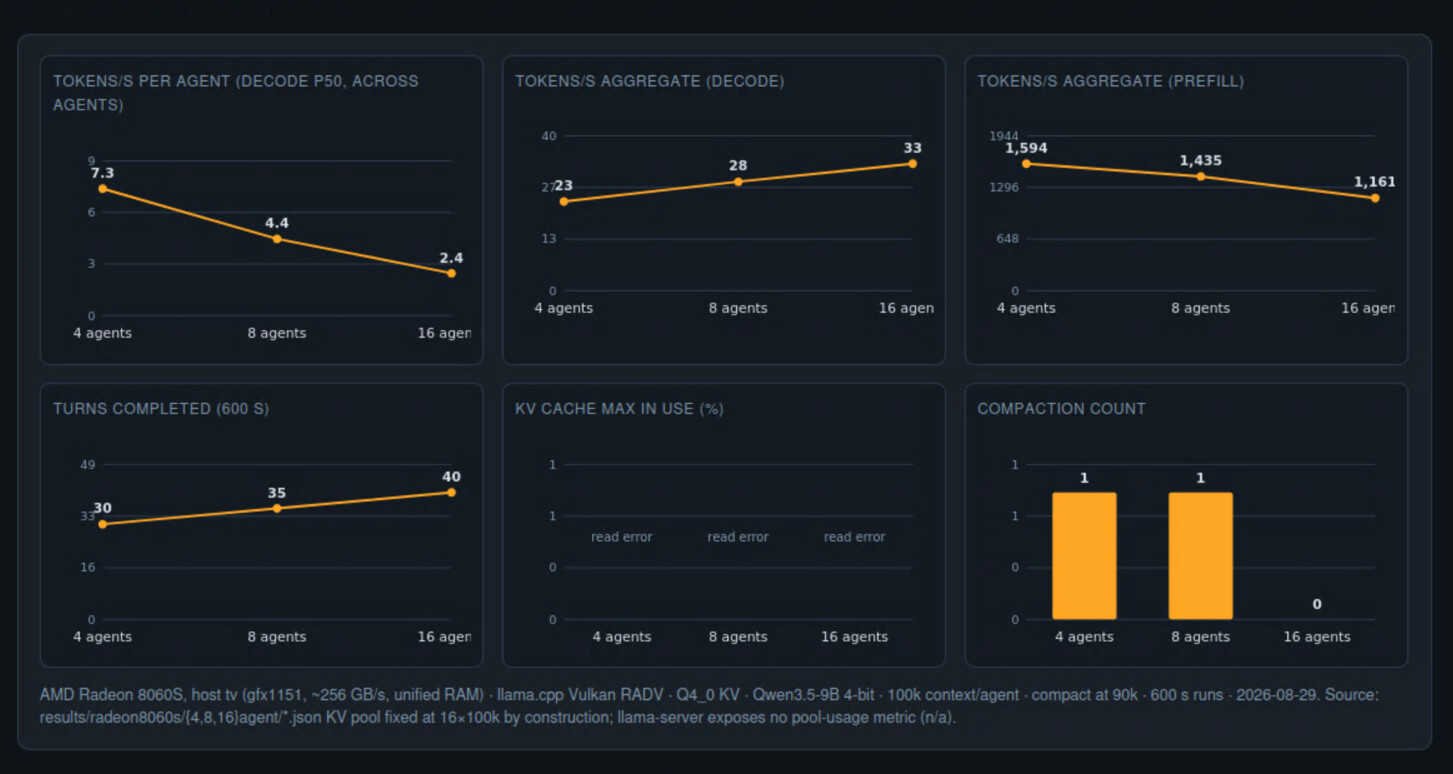
Scaling is not a surprise here. It matches other tests I’ve done in the past. 8x slower is more than the 5x I was expecting. The limiting factor in these small form factor unified VRAM systems like Mac Studios and Strix Halo are not the size or quantity of models you can load. They can load all kinds of things, but they’re bottlenecked all over the place and getting good performance means limiting what you’re doing and how you’re doing it. Niche machines, these ones, and I knew what I was getting into with that.
Edit: here’s all 3 on the same chart set since summaries are goodly.

MONEY MONEY MONEY
The final element is the dollars per agent I’m looking at here, along with a factoring in for the tokens/s that I could get. At 9b, I think this is skewed in the table below. All three hosts, $ per agent, $per aggregate decode, and $per token per agent.
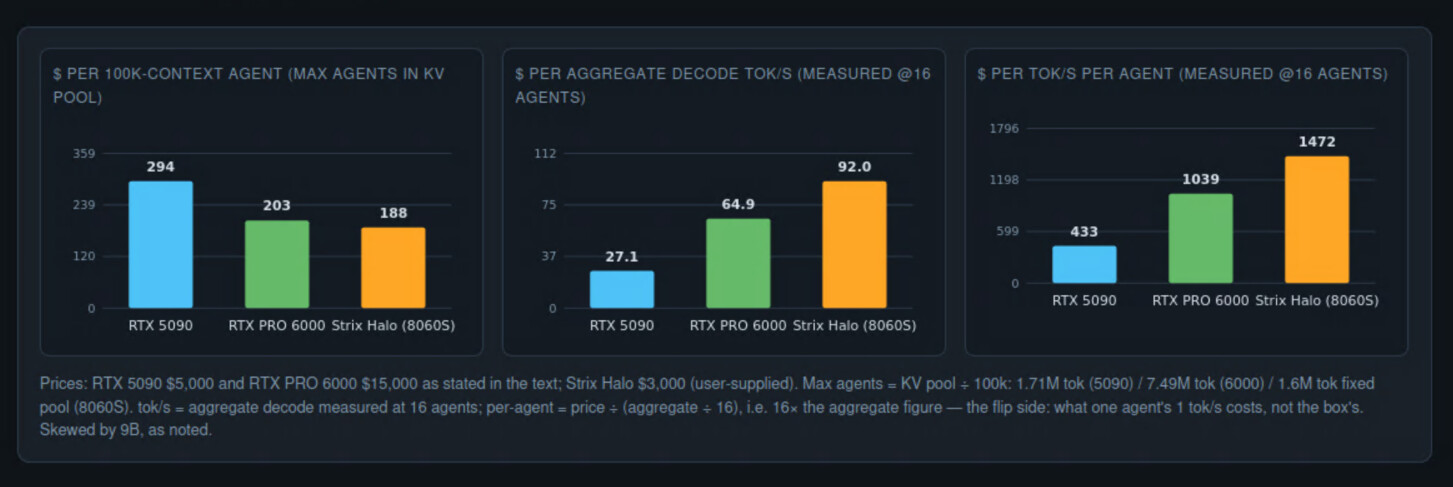
Let’s break this into 4 simple conclusions:
- If I want a single agent running for as cheaply as possible, the Strix Halo is the go-to.
- For a single agent at maximum speed for cost effectiveness, if I didn’t need to scale to more agents, then the 5090 is where it’s at.
- If my focus is scaling to the most agents possible and keeping speed up and scaling costs effectively, it’s the RTX 6000. This is supported by the aggregate decode token costs being lower than the 5090.
- If my focus is getting the fastest inference speed for the lowest price, then the more I spend the more this improves. (you had to read all this to come to that conclusion, right?)
It’s interesting to me that the more agents that are running, the more cost competitive the Strix Halo becomes… but it also becomes unbearably slow.
CONCLUSION(S) and next steps
If I run the 27b 3.8 model I’ll have a better idea of how that fits into scaling investments. Back of napkin on that one, though, I can tell you already that I can run only 1 agent on a 5090 at 100k context, and I can run 12 on the 6000. With model weights for each.
At kv quantization of 8, I’ll get roughly another 1m tokens of kvcache per 5090 with no model weights loaded onto it. At 100k context per agent, that’s an additional 10 agents. On a second 6000, it’s 30 agents. At $5000 versus $15000, the price per agent is roughly the same. However, as we’ve seen, the 5090 can’t actually scale compute parallelism as well. Not to mention trying to put more 5090s in an existing platform means you have to expand the platform - the case, the motherboard, the cpu to support enough pcie lanes. It’s all scalability issues on the 5090 side. A single 6000 does the job of 3x 5090 and I can save money on the CPU/motherboard platform because there is zero bottleneck to worry about - I bet you I could run this on a Celeron with only marginal speed degradation.
It seems clear to me that buying more consumer video cards is not a path to scaling, even though I don’t have datacenter needs. It’s better to get something more suited to task, and measuring my task properly. Benchmarks are insufficent, same with rankings boards or even other people’s head to heads.
I’d be curious to see how some of these older generation datacenter hardware pickups people are getting scale on this same setup. Maybe justification for just-for-funsies hardware.
On another note, I have running breakeven calculations and I track and aggregate all of my token production into a dashboard because I want to know if I’m wasting my money. I have an automated ledger that my instances write to for any token generation to keep track of input and output token aggregates.
I’m constantly accused of wasting my money with local LLMs and that cloud-based providers would be more cost effective. Aside from the ideological views I hold, I am also a cheap bastard so I run these numbers.
Non-benchmark based token generation I’m doing roughly 75m tokens per day, normalized over a 12 month growth pattern I’ve got an idea of how much I’ll likely use in the next 12 months.
I’m of the overinflated self-opinion that if I was doing what I’m doing I’d need to use Claude Sonnet or GPT-Terra. Some of it could be rote and pushed to Deepseek Flash v4, but I think it’s a rounding error. That would put my approximate cloud-equivalent costs to date at 15k, which is still less than my investment to date. if I continue to consume tokens at the current rate, then I’m looking at 437 days to recoup my investment. Assuming I don’t keep buying more hardware like an idiot, anyway.
I’ll also note that the leaps that are happening in open weights in 2026 so far means I’m likely to need less hardware rather than more at this point, and I’m looking purely at environment optimization which is the entire reason I’ve done this analysis.
Actually, I shouldn’t lie to myself- I overspecc’d and I want to justify it so here I am.
I should really get around to reading that routeLLM documentation and figuring out if I should be finetuning a model to my codebase.
If you actually read all of this instead of skipping to the end you should probably get a glass of water. Staying hydrated is important.