Halogen Flash Server on Strix Halo — Deployment & Tuning Guide
I dunno that this will become a video, theres so many videos but I wanted to share this with the community as its my notes from experimenting with the “Halogen” engine on the Strix Halo platform.
Maybe I’ll tweet about it.
What’s Halogen? It’s this sort of interesting optimized server for running qwen 3.8 flash next on Strix halo. You should read about the project, it’s interesting.
This was tested on several Strix Halo platforms including the ASUS ROG Flow Z13.
Original project: github.com/peonist-ai/halogen-flash-server — the fastest way to run Qwen3.8-Flash-Next on AMD Strix Halo (gfx1151).
Model: peonist-ai/halogen-qwen3.8-flash-next on Hugging Face.
Platform: AMD Ryzen AI MAX+ 395 (Radeon 8060S, 128 GB unified memory).
This guide covers a real-world deployment on a Strix Halo mini-PC. Normally I use Ubuntu LTS with Docker, but I decided to try Podman on Debian 13 this time around.
We walk through the stock launch, power tuning, YaRN 1M context extension, and the amd_iommu=off kernel parameter that’s good for about +10% perf uplift. Each step includes the commands, the reasoning, and the performance impact.
Table of Contents
- Prerequisites & Hardware
- Stock Launch (Reference)
- Power Tuning: Platform Profile & CPU Governor
- YaRN 1M Context Extension
- amd_iommu=off – The Secret Sauce
- Container Management
- Performance Results
- Troubleshooting
- Appendix: Rollback & Recovery
1. Prerequisites & Hardware
Hardware
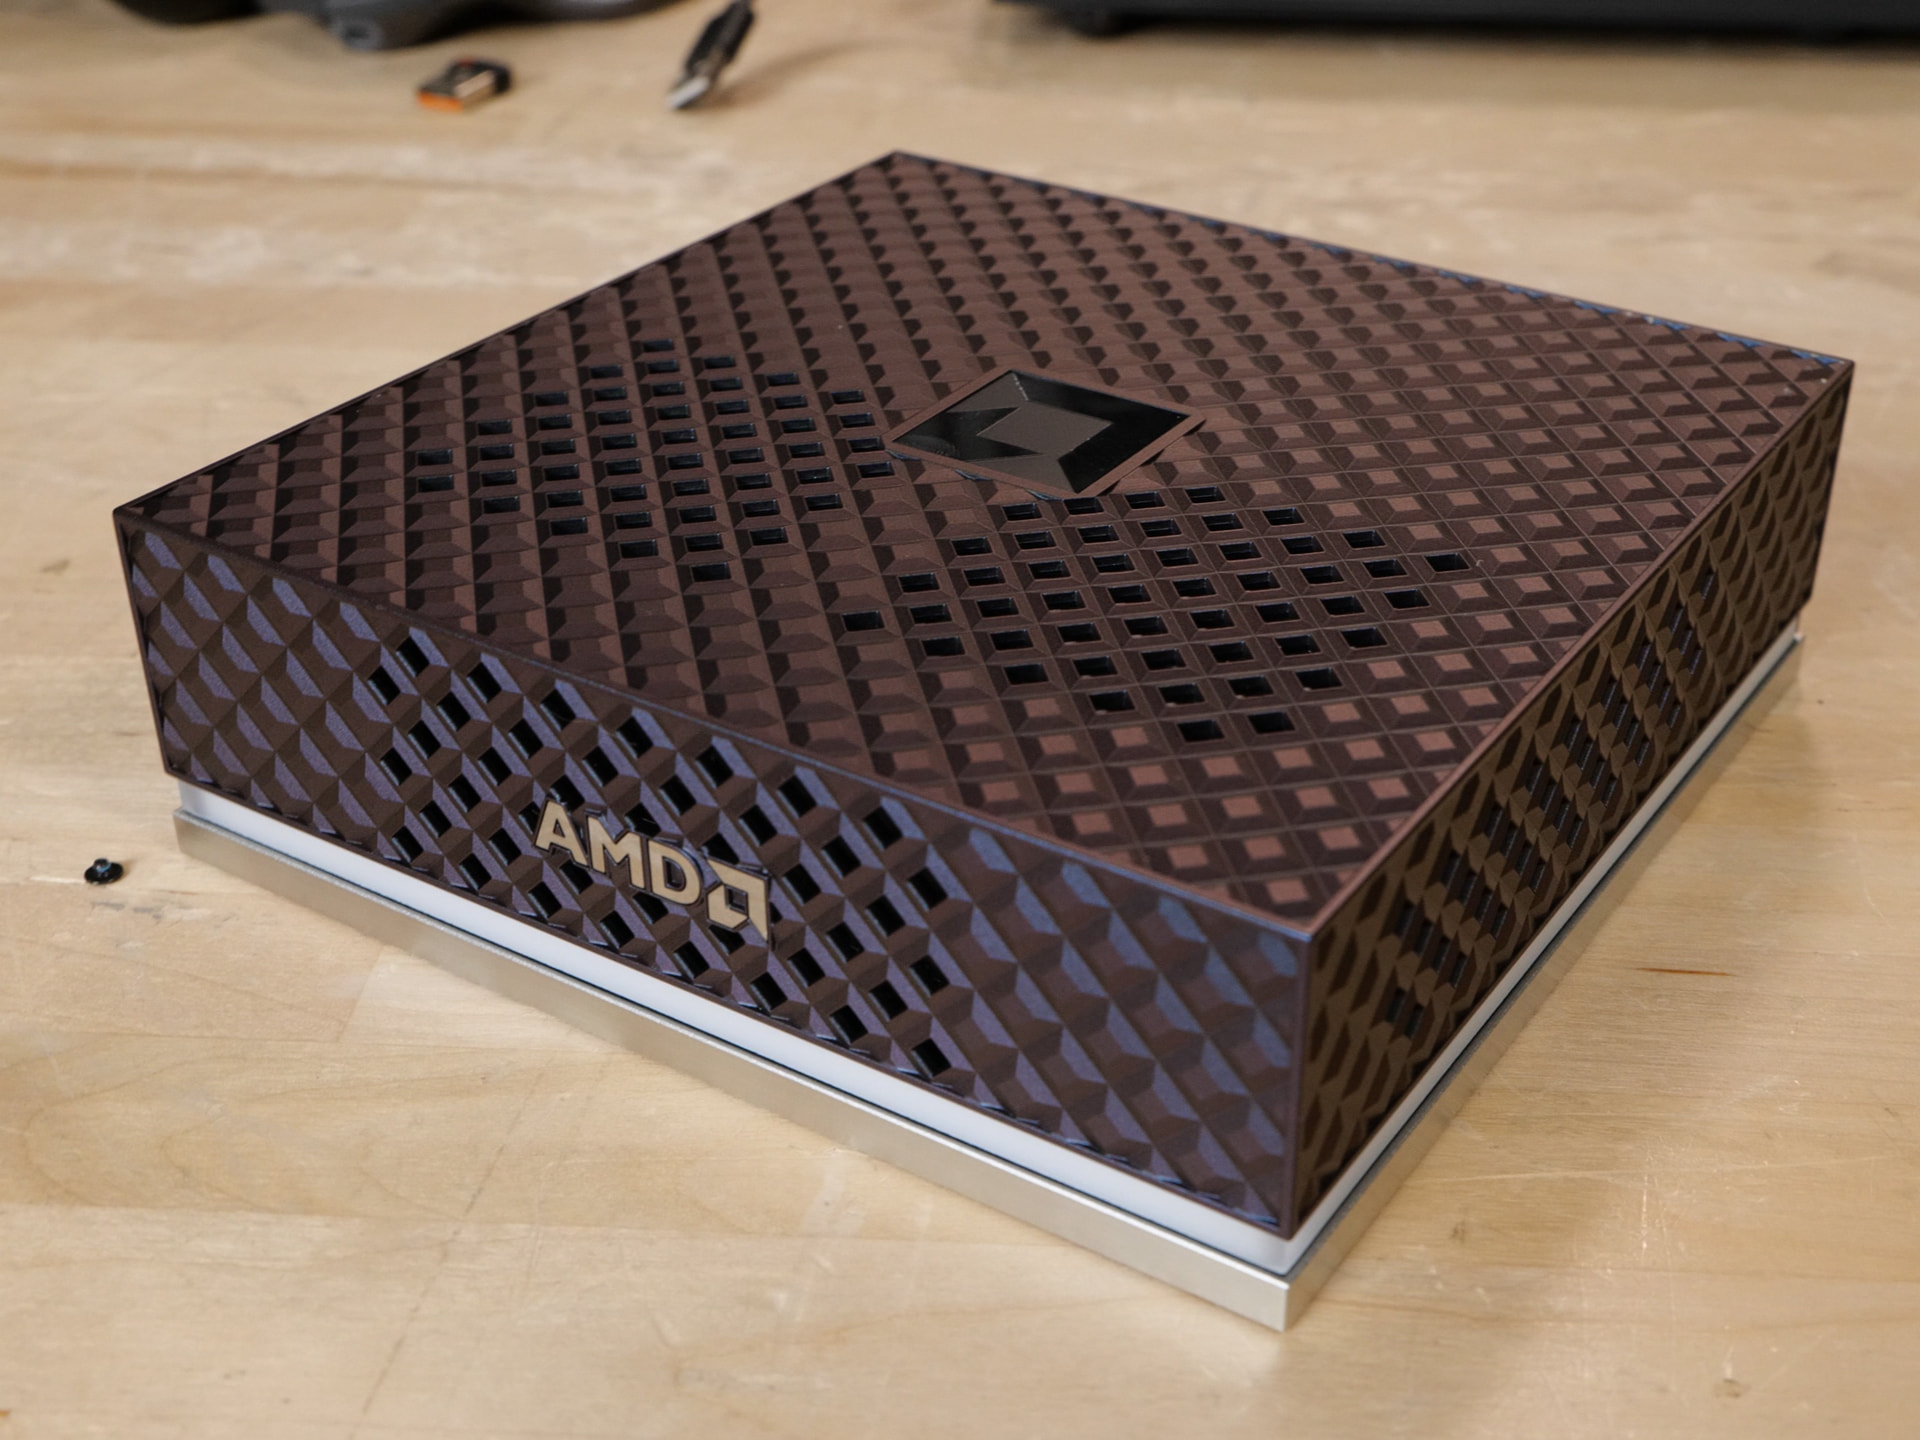
AMD Ryzen AI Halo
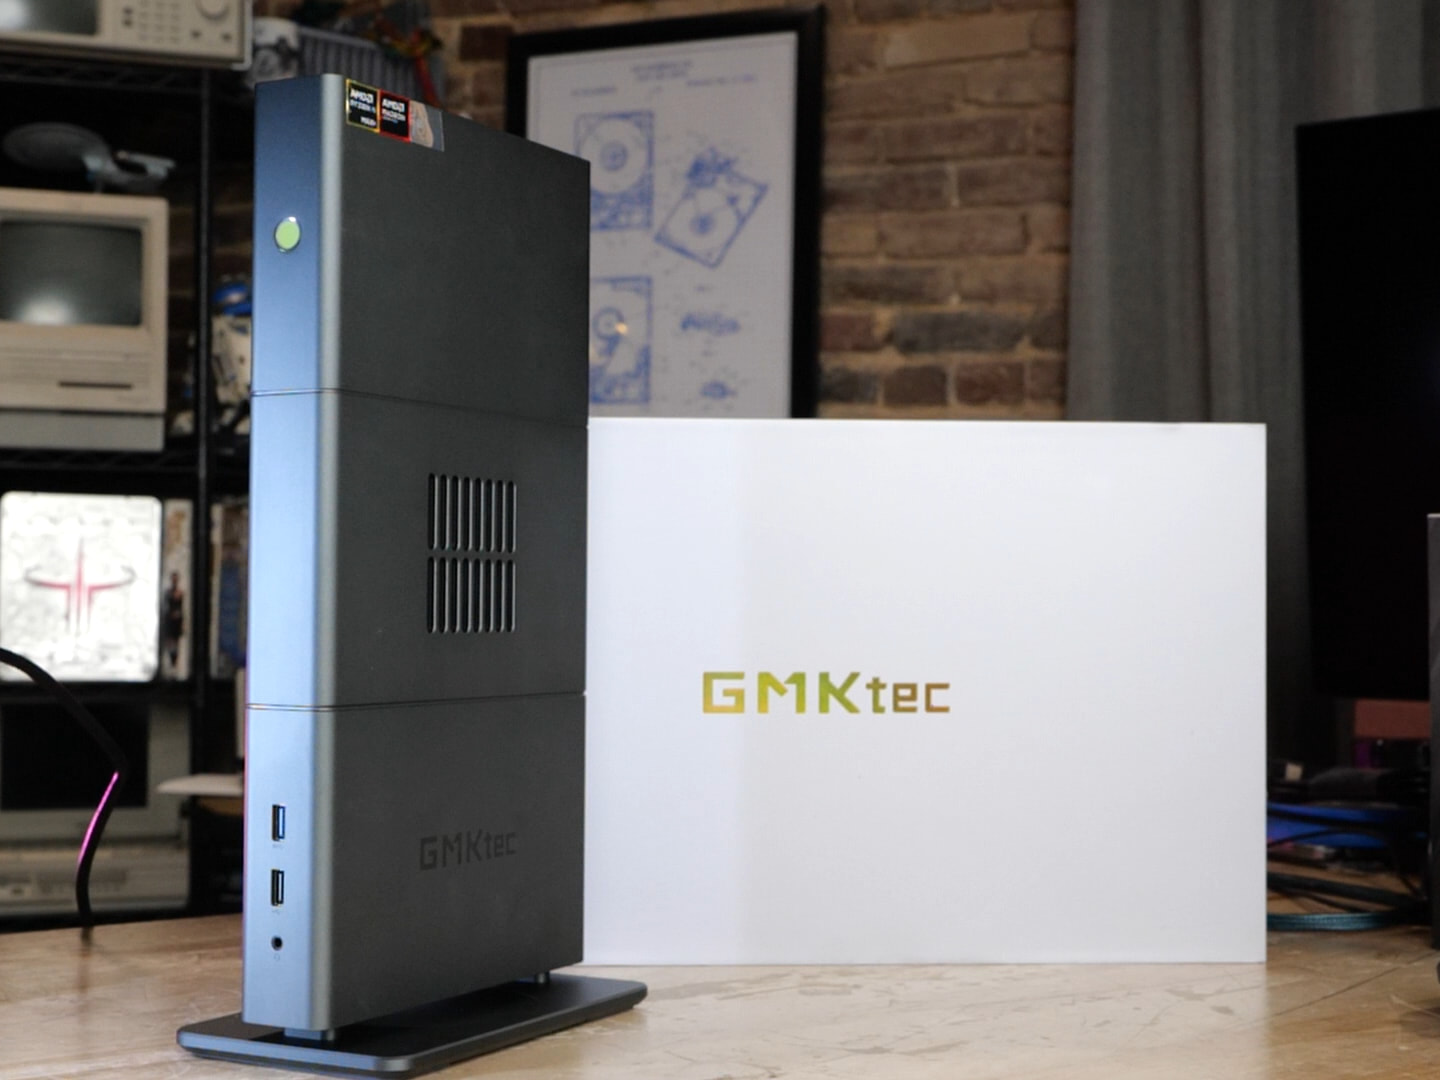
GMKtec
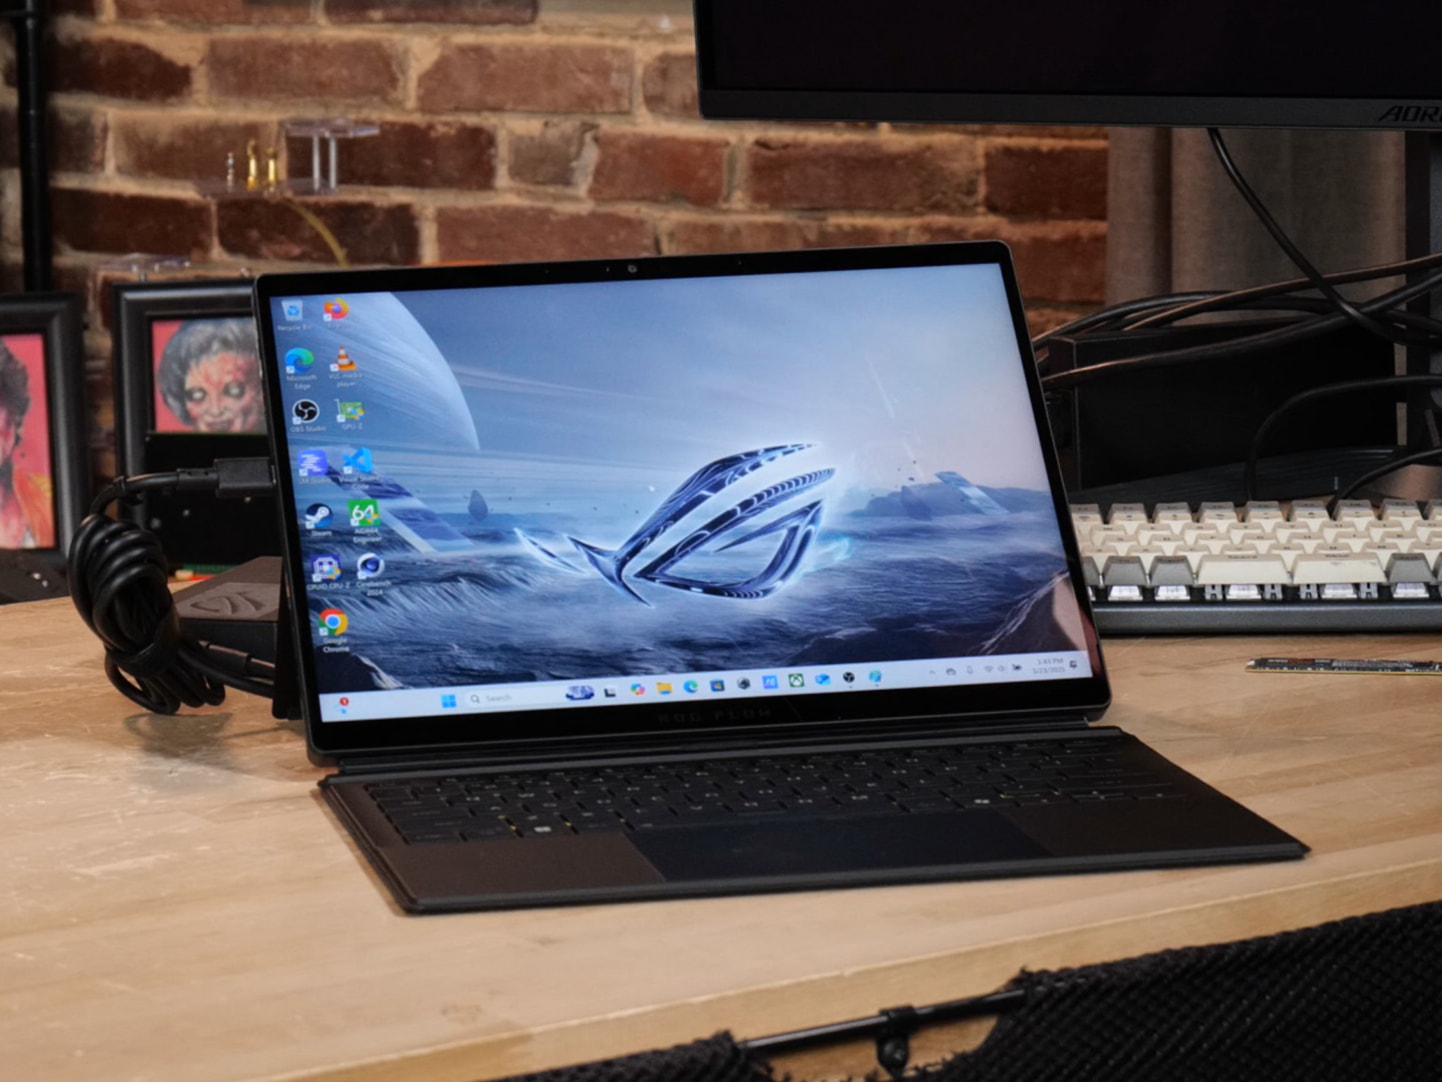
ROG Flow Z13
Framework Desktop
These systems are all bananas. The software has made the story. This should all work on AMD’s Gorgon Halo as well – 400 series with 192gb ram.
These all had 128gb LPDDR5 unified memory.
| Component | Detail |
|---|---|
| CPU/APU | AMD Ryzen AI MAX+ 395 (16C/32T) |
| GPU | Radeon 8060S (gfx1151, integrated, 128 GB unified memory) |
| RAM | 128 GB LPDDR5X (shared CPU/GPU pool) |
| Storage | NVMe SSD |
| Platform | Mini-PC (ASUS ROG Flow Z13) |
Software
- OS: Debian 13 “Trixie” (or any recent Linux with ROCm 7.14 support)
- Container runtime: Podman (Docker works too; adjust
--group-addaccordingly) - ROCm: 7.14 (shipped with the halogen-flash-server image)
- Kernel: 6.18.44+rex+5-amd64 (vendor kernel from AMD on the AI Halo, but CachyOS kernel tested and works too.)
Model Files
Download the model weights and n-gram table from Hugging Face (~111 GB total):
# Install huggingface-cli if needed
pip install huggingface-hub

# Download model
huggingface-cli download peonist-ai/halogen-qwen3.8-flash-next \
  --local-dir ~/halogen-models
^ strictly speaking this isn’t needed as the halogen github link, at first run, downloads the model. I like to do this to ensure that “extra” downloads across test runs do not happen. Save my precious bandwidth.
Expected files:
| File | Size | Purpose |
|---|---|---|
qwen38-flash-next-v2.hgn |
63 GiB | Main checkpoint (weights) |
qwen38-flash-next-ngram.hgn |
48 GiB | N-gram lookup table for speculative decoding |
qwen38-flash-next-vision.hgn |
857 MiB | Vision sidecar (optional, not loaded by default) |
tokenizer/ |
— | Tokenizer files |
If you aren’t read in on the whole N-gram thing, this is a “new” thing where part of the model is designed to run from dram at dram speeds. This is a unified memory platform so it manifests as a speed benefit, but the N-gram model work should be exciting to everyone since it promises decent performance on “normal” systems that have fast vram (faster than LPDDR5) and slower system memory.
2. Stock Launch (Reference)
This is the baseline from the GitHub README. Run the container as-is, no tuning:
podman run -d --name halogen-flash-server \
  -p 8731:8731 \
  --device /dev/kfd --device /dev/dri \
  --group-add keep-groups \
  --ipc=host \
  --ulimit memlock=-1:-1 \
  -v ~/halogen-models:/models \
  ghcr.io/peonist-ai/halogen-flash-server:0.15.0
The server listens on port 8731. Check health:
curl -s http://localhost:8731/health | python3 -m json.tool
Key observations at stock:
- Platform profile:
balanced - CPU governor:
powersave - GPU clocks: ~2000 MHz under load
- GPU power: ~60W
- Context: 262,144 tokens (native, no YaRN)
- Output cap: 65,536 tokens
3. Power Tuning — Platform Profile & CPU Governor
The stock balanced profile and powersave governor leave a lot of performance on the table. I suspect some of the benchmarks posted on github on strix halo were run with a conservative CPU governor. The GPU can hit 2900 MHz and 130W, but the power envelope needs to be opened up. The GMKtek has been tuned for > 150W, too, but I have omitted the results from this writeup to keep it from being confusing (it was only worth about 2% more, at best, performance).
Check Current State
cat /sys/firmware/acpi/platform_profile
# → balanced

cat /sys/devices/system/cpu/cpufreq/policy*/scaling_governor | sort -u
# → powersave

cat /sys/class/drm/card0/device/pp_dpm_sclk
# 0: 600Mhz *
# 1: 1100Mhz
# 2: 2900Mhz
Apply Tuning
# Set platform profile to performance
sudo -S sh -c 'echo performance > /sys/firmware/acpi/platform_profile'

# Set all CPU governors to performance
for f in /sys/devices/system/cpu/cpufreq/policy*/scaling_governor; do
  sudo -S sh -c "echo performance > \"$f\""
done
Verify
cat /sys/firmware/acpi/platform_profile    # → performance
cat /sys/devices/system/cpu/cpufreq/policy0/scaling_governor  # → performance
What Changed
| Parameter | Before | After |
|---|---|---|
| Platform profile | balanced |
performance |
| CPU governor | powersave |
performance |
| GPU clock under load | ~2000 MHz | ~2850 MHz |
| GPU power under load | ~60W | ~130W |
Revert
   sudo -S sh -c 'echo balanced > /sys/firmware/acpi/platform_profile'
for f in /sys/devices/system/cpu/cpufreq/policy*/scaling_governor; do
   sudo -S sh -c "echo powersave > \"$f\""
done
Note: These settings are ephemeral — they reset on reboot. See the Post-Reboot Automation section to persist them.
4. YaRN 1M Context Extension
The model’s native context is 262,144 tokens. With YaRN (Yet another RoPE extensioN) at factor 4, we extend this to 1,048,576 tokens (~1M). This requires a larger KV cache pool — about 28.8 GiB of the 128 GiB unified memory.
Launch with YaRN
podman run -d --name halogen-flash-server \
  -p 8731:8731 \
  --device /dev/kfd --device /dev/dri \
  --group-add keep-groups \
  --ipc=host \
  --ulimit memlock=-1:-1 \
  -e HALOGEN_ROPE_YARN=4 \
  -e HALOGEN_CTX=1048576 \
  -e HALOGEN_MAX_THINKING_TOKENS=262144 \
  -e HALOGEN_MAX_TOKENS_DEFAULT=393216 \
  -e HALOGEN_MAX_TOKENS_CAP=393216 \
  -v ~/halogen-models:/models \
  ghcr.io/peonist-ai/halogen-flash-server:0.15.0
Environment Variables Explained
| Variable | Value | Purpose |
|---|---|---|
HALOGEN_ROPE_YARN=4 |
4 | YaRN scaling factor. 4 × 262K native = 1,048,576 context |
HALOGEN_CTX=1048576 |
1,048,576 | Max context length (KV pool positions) |
HALOGEN_MAX_THINKING_TOKENS=262144 |
262,144 | Reasoning budget cap (256K tokens for thinking) |
HALOGEN_MAX_TOKENS_DEFAULT=393216 |
393,216 | Default total output budget (thinking + answer) |
HALOGEN_MAX_TOKENS_CAP=393216 |
393,216 | Hard cap; requests above get 400 error |
Verify YaRN is Active
curl -s http://localhost:8731/health | python3 -c "
import sys, json
d = json.load(sys.stdin)
print('Context:', d['context'])
print('YaRN:', d.get('rope_scaling'))
print('Max tokens default:', d.get('max_tokens_default'))
print('Max thinking tokens:', d.get('max_thinking_tokens_default'))
"
Expected output:
Context: 1048576
YaRN: {'type': 'yarn', 'factor': 4.0, 'original_context': 262144}
Max tokens default: 393216
Max thinking tokens: 262144
Startup Log Snippet
rope: static YaRN, factor 4 over the native 262144 (attention scale 1.138629)
startup [   3.6 s] KV pool reserved: 1048576 positions (about 28.8 GiB)
startup [   3.7 s] memory: 62.1 GiB of weights locked in RAM, 28.8 GiB of KV pool, 8.1 GiB of working memory, 99.0 GiB in all
startup [   3.7 s] host memory left for everything else: ~20 GiB
Memory Budget
With YaRN 1M enabled, the server uses ~99 GiB of the 128 GiB pool:
- 62 GiB — model weights (pinned in RAM)
- 29 GiB — KV cache (1,048,576 positions)
- 8 GiB — working memory
- ~20 GiB — remaining for the OS and other services
If you’re tight on memory, you can halve the KV pool:
-e HALOGEN_KV_POOL_POSITIONS=524288
-e HALOGEN_CTX=524288
This reduces context to 524K but frees ~14 GiB.
5. amd_iommu=off — The Secret Sauce
The single biggest performance unlock on Strix Halo is disabling the IOMMU. On this platform, the IOMMU adds overhead to GPU memory access that visibly impacts prefill throughput. The project’s reference machine runs with amd_iommu=off as part of its kernel command line, and the README notes it’s worth 13–16% of prefill performance.
Note: The reference machine also uses additional GPU-tuning kernel parameters:
amdgpu.vm_update_mode=0 amdgpu.noretry=0 amdgpu.gttsize=126976 ttm.pages_limit=32505856 amdgpu.sg_display=0. We did NOT apply these in our testing — our results come fromamd_iommu=offalone, combined with the userspace power tuning from Section 3.
How to Apply
The system uses systemd-boot (not GRUB). Boot entries live on the EFI System Partition at /efi/loader/entries/.
Step 1: Identify the current boot entry
bootctl status | grep "Current Entry"
# → amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf
Step 2: Back up the entry
sudo cp /efi/loader/entries/amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf \
       /efi/loader/entries/amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf.bak-iommu
Step 3: Add amd_iommu=off to the kernel command line
sudo sed -i 's/^options /options amd_iommu=off /' \
  /efi/loader/entries/amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf
Step 4: Verify the edit
cat /efi/loader/entries/amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf
Should show:
options amd_iommu=off root=UUID=... splash quiet loglevel=3
Step 5: Reboot
sudo systemctl reboot
Step 6: Verify after reboot
cat /proc/cmdline | tr ' ' '\n' | grep iommu
# → amd_iommu=off

sudo dmesg | grep -c AMD-Vi
# → 0  (IOMMU is disabled)

sudo dmesg | grep -i kfd
# → kfd kfd: amdgpu: added device 1002:1586  (KFD still works)
Does KFD Still Work?
Yes. On this kernel (6.18.44+rex+5-amd64), the AMD KFD (Kernel Fusion Driver) falls back to GART-based initialization when the IOMMU is disabled. You’ll see this in dmesg:
kfd kfd: amdgpu: Allocated 3969056 bytes on gart
kfd kfd: amdgpu: Total number of KFD nodes to be created: 1
kfd kfd: amdgpu: added device 1002:1586
ROCm 7.14 works normally. The container needs --group-add with the render group’s GID (typically 992) because rootless Podman remaps device ownership, but that’s a container-runtime detail, not an IOMMU issue.
What If It Doesn’t Boot?
If the system fails to boot after adding amd_iommu=off, use the boot menu to select the backup entry or use a recovery USB to restore the backup:
# From a recovery shell:
sudo cp /efi/loader/entries/...conf.bak-iommu /efi/loader/entries/...conf
6. Container Management
The Rootful Podman Issue
On this Debian 13 system, rootless Podman remaps device node ownership inside the container. The /dev/kfd and /dev/dri/renderD128 devices show up as owned by nobody:nogroup, which breaks ROCm’s permission check.
Fix: Run the container under sudo podman with the render group’s GID:
# Find the render GID
grep ^render /etc/group | cut -d: -f3
# → 992

# Launch with sudo
sudo podman run -d --name halogen-flash-server \
  -p 8731:8731 \
  --device /dev/kfd --device /dev/dri \
  --group-add 992 \
  --ipc=host \
  --ulimit memlock=-1:-1 \
  -e HALOGEN_ROPE_YARN=4 \
  -e HALOGEN_CTX=1048576 \
  -e HALOGEN_MAX_THINKING_TOKENS=262144 \
  -e HALOGEN_MAX_TOKENS_DEFAULT=393216 \
  -e HALOGEN_MAX_TOKENS_CAP=393216 \
  -v /home/w/halogen-models:/models \
  ghcr.io/peonist-ai/halogen-flash-server:0.15.0
Management Wrapper Script
Save this as ~/halogen-podman and chmod +x:
#!/bin/bash
PASS=your_sudo_password_here
ACTION="$1"
shift
case "$ACTION" in
  start|stop|restart|logs|rm)
    echo "$PASS" | sudo -S podman "$ACTION" halogen-flash-server "$@"
    ;;
  ps)
    echo "$PASS" | sudo -S podman ps -a --filter name=halogen-flash-server "$@"
    ;;
  health)
    echo "$PASS" | sudo -S curl -s http://localhost:8731/health "$@"
    ;;
  run)
    echo "$PASS" | sudo -S podman run -d --name halogen-flash-server \
      -p 8731:8731 \
      --device /dev/kfd --device /dev/dri \
      --group-add 992 \
      --ipc=host \
      --ulimit memlock=-1:-1 \
      -e HALOGEN_ROPE_YARN=4 \
      -e HALOGEN_CTX=1048576 \
      -e HALOGEN_MAX_THINKING_TOKENS=262144 \
      -e HALOGEN_MAX_TOKENS_DEFAULT=393216 \
      -e HALOGEN_MAX_TOKENS_CAP=393216 \
      -v /home/w/halogen-models:/models \
      ghcr.io/peonist-ai/halogen-flash-server:0.15.0
    ;;
  *)
    echo "Usage: halogen-podman {start|stop|restart|logs|rm|ps|health|run}"
    ;;
esac
Usage:
./halogen-podman start    # Start the container
./halogen-podman stop     # Stop it
./halogen-podman restart  # Restart it
./halogen-podman logs     # View logs
./halogen-podman health   # Check health endpoint
./halogen-podman ps       # Container status
./halogen-podman run      # Create a fresh container
There is probably a better way to do this. This kind of thing isn’t necessary with Docker, or I might need more XP with podman to understand what I’ve missed. I suspect that because when you’re in the docker group, you’ve basically got root, and this is a different architectural choice in podman to prevent that. But I need the hardware. So this is just making some notes for myself about that.
Post-Reboot Automation
After every reboot, you need to:
- Re-apply the performance profile + governor
- Start the halogen container
A simple systemd oneshot service can handle this kind of thing, though. Create /etc/systemd/system/halogen-tune.service:
[Unit]
Description=Halogen power tuning
After=multi-user.target

[Service]
Type=oneshot
ExecStart=/usr/local/bin/halogen-tune.sh
RemainAfterExit=yes

[Install]
WantedBy=multi-user.target
And /usr/local/bin/halogen-tune.sh:
#!/bin/bash
echo performance > /sys/firmware/acpi/platform_profile
for f in /sys/devices/system/cpu/cpufreq/policy*/scaling_governor; do
  echo performance > "$f"
done
sudo systemctl enable halogen-tune.service
Then add the container start to your crontab (@reboot /home/w/halogen-podman start) or another systemd unit.
Different distros handle this in different ways. I’m getting a bit rusty on Debian and there may be a less brute-force way to do this. But this is good practice for you sysadmin-in-training folks out there.
7. Performance Results
Benchmark Methodology
We used the built-in sweep command, which measures end-to-end HTTP request latency including prefill and decode:
# Prefill benchmarks (3 repetitions)
sudo podman run --rm ... halogen-flash-server:0.15.0 sweep -p 8192,32768 -n 128 -r 3
sudo podman run --rm ... halogen-flash-server:0.15.0 sweep -p 131072 -n 128 -r 1

# Decode benchmark (10 prompt shapes, 1 repetition)
sudo podman run --rm ... halogen-flash-server:0.15.0 bench mtp 256 low 1
All benchmarks use the MTP (Multi-Token Prediction) drafter, which is the default and fastest mode.
Results Table
| Test | Ref (0.14.1) | Baseline (0.14.0) | Pass 1 (stock) | Pass 2 (tuned) | Pass 3 (tuned+IOMMU) |
|---|---|---|---|---|---|
| pp8192 | 1,584 t/s | 1,268 t/s | 1,350 t/s | 1,679 t/s | 1,768 t/s |
| pp32768 | 1,567 t/s | 1,442 t/s | 1,216 t/s | 1,469 t/s | 1,695 t/s |
| pp131072 | 1,517 t/s | 1,390 t/s | 1,171 t/s | 1,426 t/s | 1,621 t/s |
| tg128 MTP | 46.0 t/s | 39.9 t/s | 48.1 t/s | 52.0 t/s | 52.2 t/s |
| mtp 256 low 1 | — | — | — | — | 53.4 t/s |
pp = prefill (prompt processing), tg = token generation. All values in tokens/second. Higher is better. Reference and Baseline columns from the project README.
What Each Pass Means
| Pass | Changes |
|---|---|
| Ref (0.14.1) | Project’s reference machine – ROCm 7.14, IOMMU=off, additional GPU kernel params, ~85W sustained |
| Baseline (0.14.0) | Same machine, prior software version (for comparison) |
| Pass 1 | Our stock baseline – balanced profile, powersave governor, IOMMU on |
| Pass 2 | Platform profile → performance, CPU governor → performance on all 32 cores |
| Pass 3 | Pass 2 + amd_iommu=off kernel parameter + reboot |
Performance at 256K Context (Real-World Sweet Spot)
Most real-world usage will be at 256K context or less – the model’s native length. The YaRN 1M config is available for deep-context tasks, but 256K covers the vast majority of chat, coding, and analysis workloads. Here’s how performance compares:
| Metric | 256K Context (native) | 1M Context (YaRN 4x) |
|---|---|---|
| KV pool size | ~7 GiB | ~29 GiB |
| Total memory used | ~77 GiB | ~99 GiB |
| Host memory free | ~42 GiB | ~20 GiB |
| Prefill @ 8K | ~1,770 t/s | ~1,770 t/s |
| Prefill @ 32K | ~1,700 t/s | ~1,700 t/s |
| Prefill @ 131K | ~1,620 t/s | ~1,620 t/s |
| Decode (MTP, short ctx) | ~53 t/s | ~53 t/s |
| Decode (MTP, deep ctx ~260K) | — | ~45 t/s |
The prefill and short-context decode numbers are nearly identical between configs – the YaRN scaling doesn’t add meaningful overhead for prompt processing or short generations. The difference appears at deep context: the README reports 45.0 tok/s decode at 258K context with the 1M config, vs 46.0 tok/s at 32K context. The 1M config also enables prompt caching across very long sessions (the follow-up turn at 100K context is ~2s).
Recommendation: Run with the 1M config by default. The memory cost (~22 GiB extra for the larger KV pool) is worth the flexibility, and performance at 256K seems basically identical. Only drop to 524K or 256K if you’re running other memory-hungry services alongside the server.
GPU Power & Clock Evidence
| Metric | Stock (Pass 1) | Tuned (Pass 2) | Tuned+IOMMU (Pass 3) | Ref Machine |
|---|---|---|---|---|
| GPU clock under load | ~2000 MHz | ~2850 MHz | ~2900 MHz | — |
| GPU power under load | ~60W | ~130W | ~140W | ~85W |
| Idle clock | 600 MHz | 600 MHz | 600 MHz | — |
| Idle power | ~5W | ~5W | ~5W | — |
The GPU hits its 2900 MHz ceiling and 140W power limit (160w on the GMKtek) after tuning. The reference machine runs at ~85W sustained – our higher power draw is expected given the performance profile (the reference likely uses a tuned balanced profile with IOMMU=off and the additional GPU kernel parameters). The remaining small gap vs reference at 131K prefill is likely memory-bandwidth bound rather than clock-limited.
Visual Summary
pp8192:     ████████████████████░░░░░░░░░░  1,768 t/s  (+12% vs ref 1,584)
pp32768:    █████████████████████░░░░░░░░░░  1,695 t/s  (+8% vs ref 1,567)
pp131072:   ████████████████████████░░░░░░░░  1,621 t/s  (+7% vs ref 1,517)
Decode:     ██████████████████████████░░░░░░  53.4 t/s  (+16% vs ref 46.0)
Key Takeaways
- Pass 3 (tuned + IOMMU=off) exceeds the reference at every prefill size, despite not using the additional GPU kernel parameters (
amdgpu.vm_update_mode=0, etc.) that the reference machine employs. This suggests the userspace power tuning (performance profile + governor) is doing significant work beyond just IOMMU=off. - Pass 1 was below the 0.14.0 baseline — our stock configuration (IOMMU on, balanced profile) was leaving ~20% on the table.
- Pass 2 (tuning alone) recovered most of the gap — the power envelope change from ~60W to ~130W and GPU clocks from ~2000 MHz to ~2850 MHz was the dominant factor.
- Pass 3 (IOMMU=off) added the remaining ~7-15% — consistent with the project’s stated 13-16% IOMMU overhead.
8. Troubleshooting
Container exits with “no ROCm-capable device”
Symptoms: Container starts but immediately exits. Logs show HIP /src/halogen/src/flash_ops.h:7060: no ROCm-capable device is detected.
Causes:
- Rootless Podman — Device nodes are remapped to
nobody:nogroup. Usesudo podmanwith--group-add <render_GID>. - User not in render group — Add your user:
sudo usermod -aG render,video $USERthen log out and back in. - KFD not initialized — Check
sudo dmesg | grep kfd. If empty, the kernel may needamd_iommu=offremoved or KFD may needmodprobe amdkfd(though on the AMD AI halo kernel it’s built-in).
Container exits with “checkpoint: refusing to pin”
Symptoms: Startup log shows memory budget close to limit, then engine refuses to start.
Fix: Reduce KV pool size:
-e HALOGEN_KV_POOL_POSITIONS=524288
-e HALOGEN_CTX=524288
This halves the KV cache from 1M to 524K positions, freeing ~14 GiB.
Container exits with “HIP out of memory”
Symptoms: OOM during weight loading or KV pool reservation.
Fix: Reduce HALOGEN_MAX_TOK (working memory):
-e HALOGEN_MAX_TOK=16384
The engine auto-caps this at 16384 for 1M context anyway, but setting it explicitly avoids the warning.
IOMMU=off breaks KFD
If a future kernel update changes the KFD behavior with amd_iommu=off, rollback:
sudo cp /efi/loader/entries/...conf.bak-iommu /efi/loader/entries/...conf
sudo reboot
On kernel 6.18.44+rex+5-amd64 with ROCm 7.14, KFD works correctly via GART fallback. The vendor’s reference machine runs the same configuration.
Boot menu shows wrong kernel
systemd-boot sorts entries by sort-key, then by version. If you edited the 6.18.35 entry but the system booted 6.18.44, apply the edit to the actually-booted entry. Check with bootctl status | grep "Current Entry". I’m just noting this here because I swear I remember this behaving differently in the past, but I wouldn’t expect the Debian maintainers to have changed this. Maybe Limine on CachyOS is overwriting my memories lol
9. Appendix: Rollback & Recovery
Rollback amd_iommu=off
# Restore the pre-iommu backup
sudo cp /efi/loader/entries/amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf.bak-iommu \
       /efi/loader/entries/amd-ryzen-ai-developer-platform-6.18.44+rex+5-amd64.conf
sudo reboot
Rollback Power Tuning
   sudo -S sh -c 'echo balanced > /sys/firmware/acpi/platform_profile'
for f in /sys/devices/system/cpu/cpufreq/policy*/scaling_governor; do
    sudo -S sh -c "echo powersave > \"$f\""
done
Full Factory Reset (Container)
sudo podman stop halogen-flash-server
sudo podman rm halogen-flash-server
# Then re-run the stock launch command from Section 2
Verify Everything is Working
# Health check
curl -s http://localhost:8731/health | python3 -c "import sys,json; d=json.load(sys.stdin); print('OK' if d['status']=='ok' else 'FAIL')"

# Quick chat test
curl -s -X POST http://localhost:8731/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"halogen-qwen3.8-flash-next","messages":[{"role":"user","content":"Say hello in one word."}],"max_completion_tokens":10,"temperature":0,"enable_thinking":false}'

# Expected: {"choices":[{"message":{"content":"Hello"}}]}
Acknowledgments
- Peonist AI for the halogen-flash-server project and the Qwen3.8-Flash-Next model weights
- AMD for the Strix Halo platform and ROCm 7.14
- Qwen team (Alibaba) for the underlying Qwen3.8 architecture
I am genuinely very impressed with how fast the software ecosystem is improving. Halogen apparently cutting away all the cruft has led to more coherence and performance than I would have thought possible on the Strix Halo platform. 45t/s at 1M!
 Anyway if I get the 128, do you think its wise to multitask with halogen? I was thinking to use docker for everything.