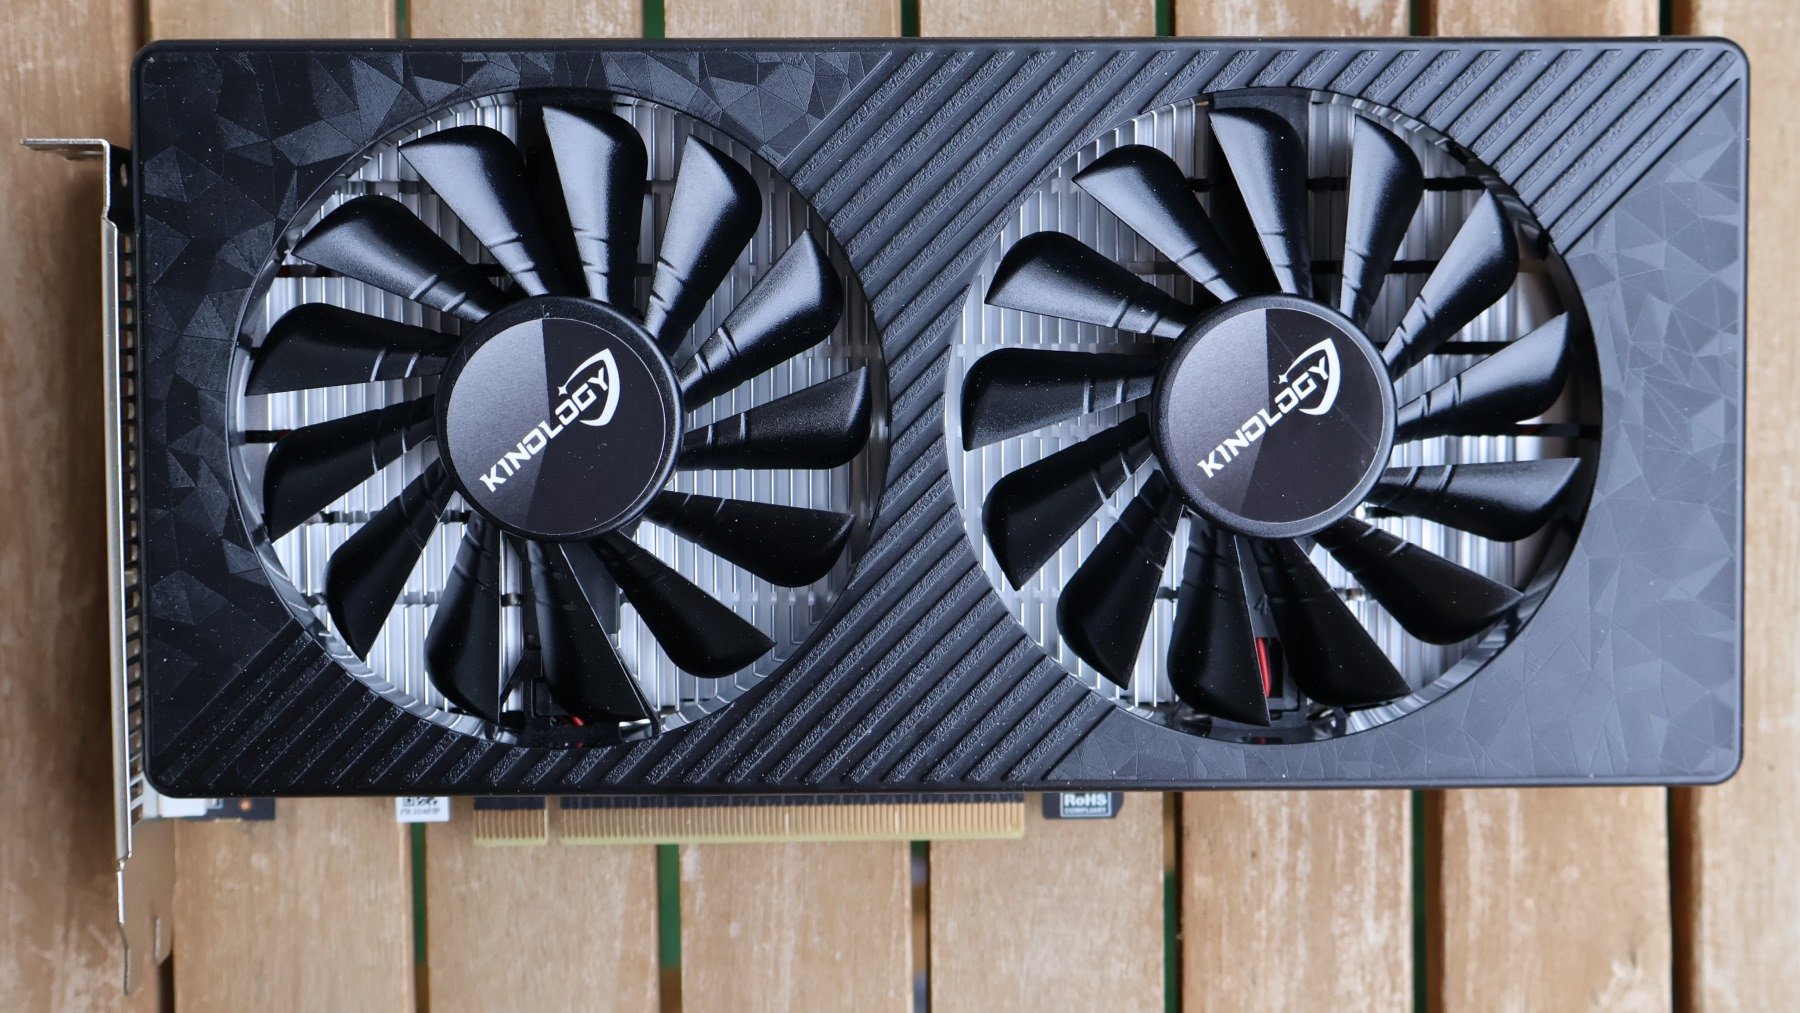
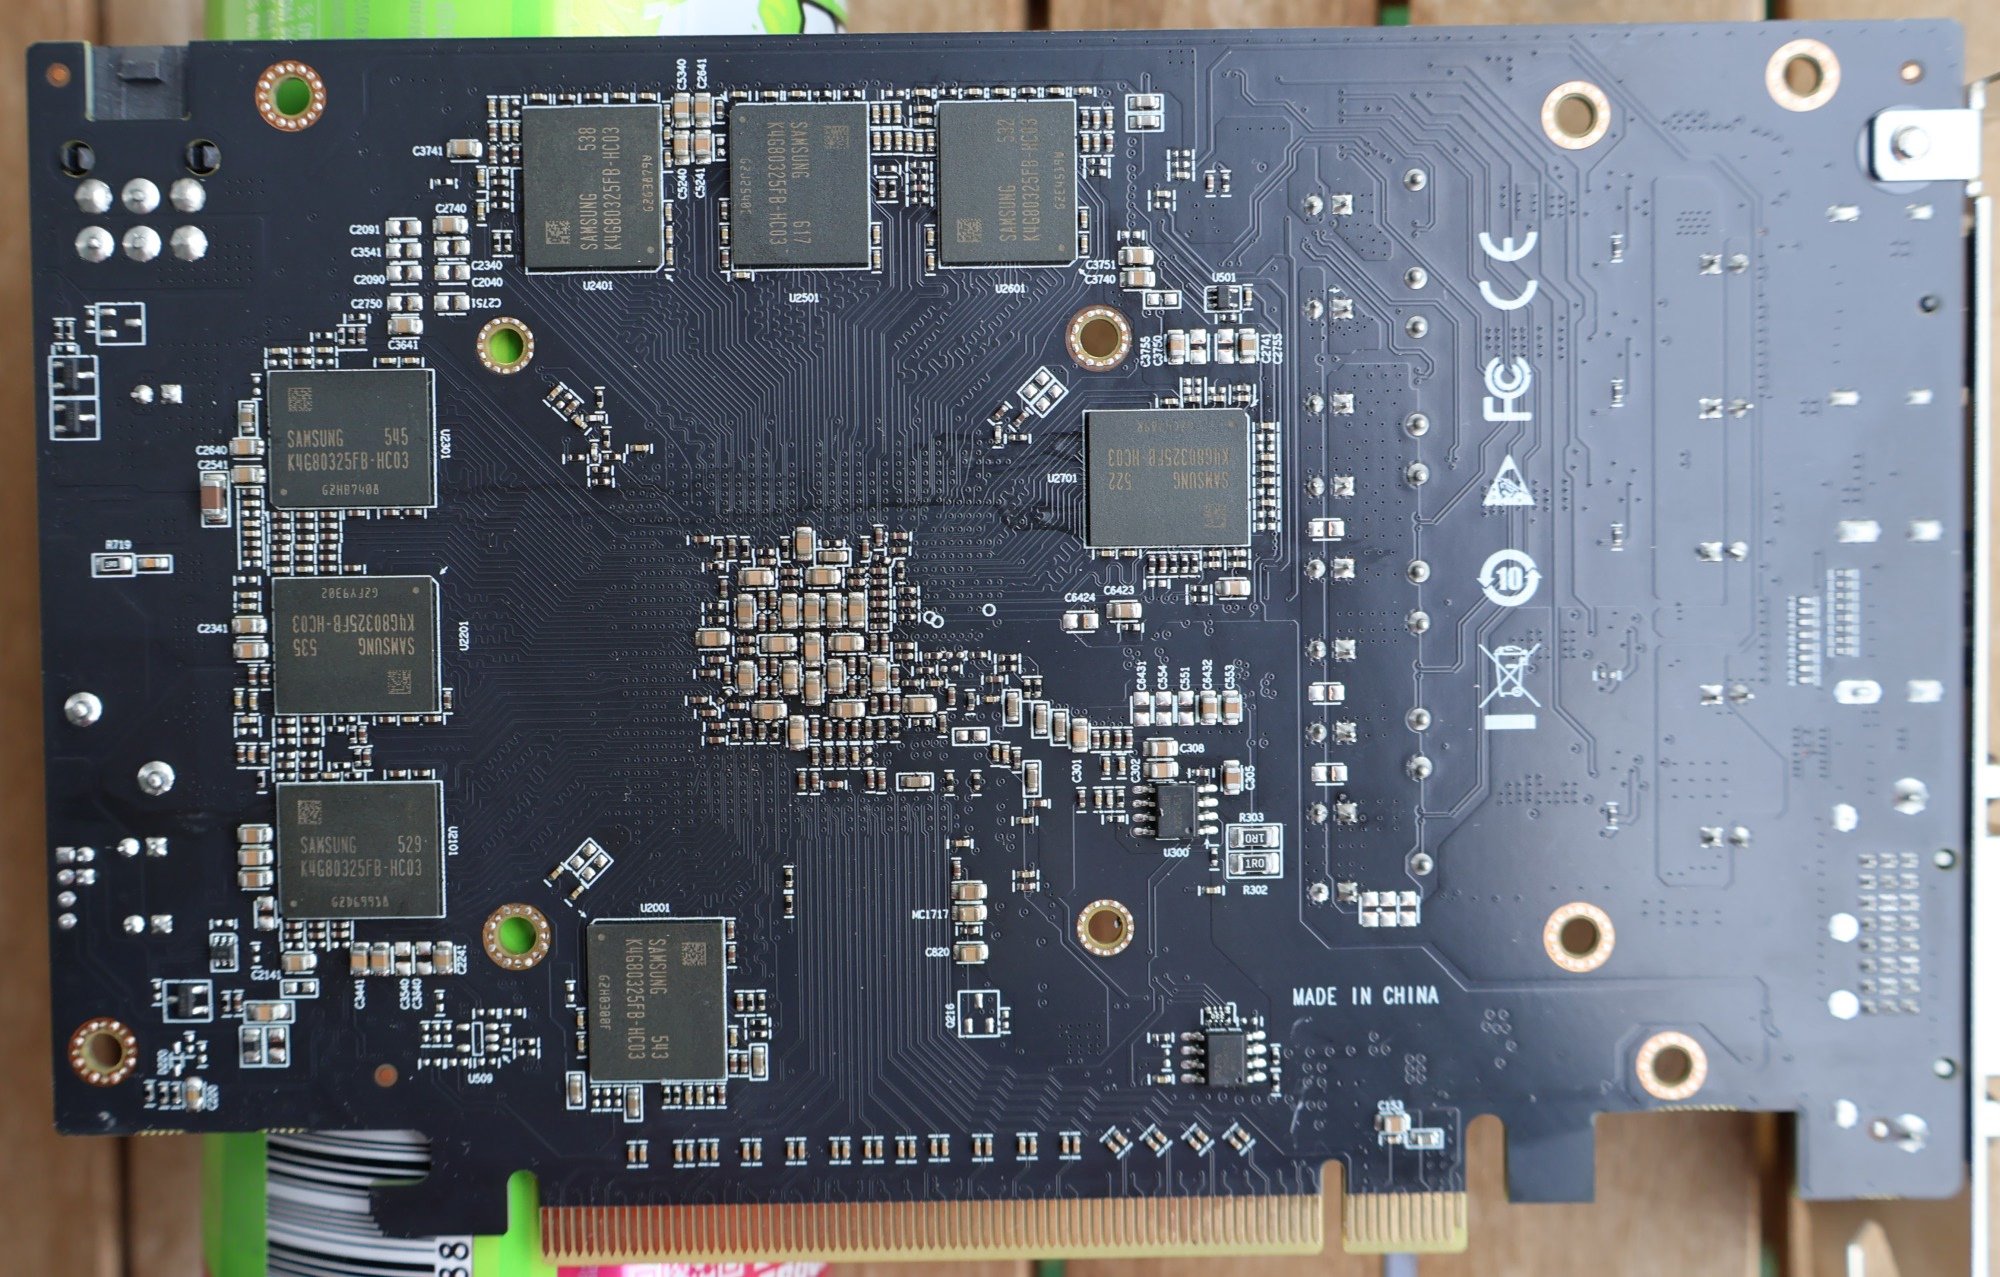
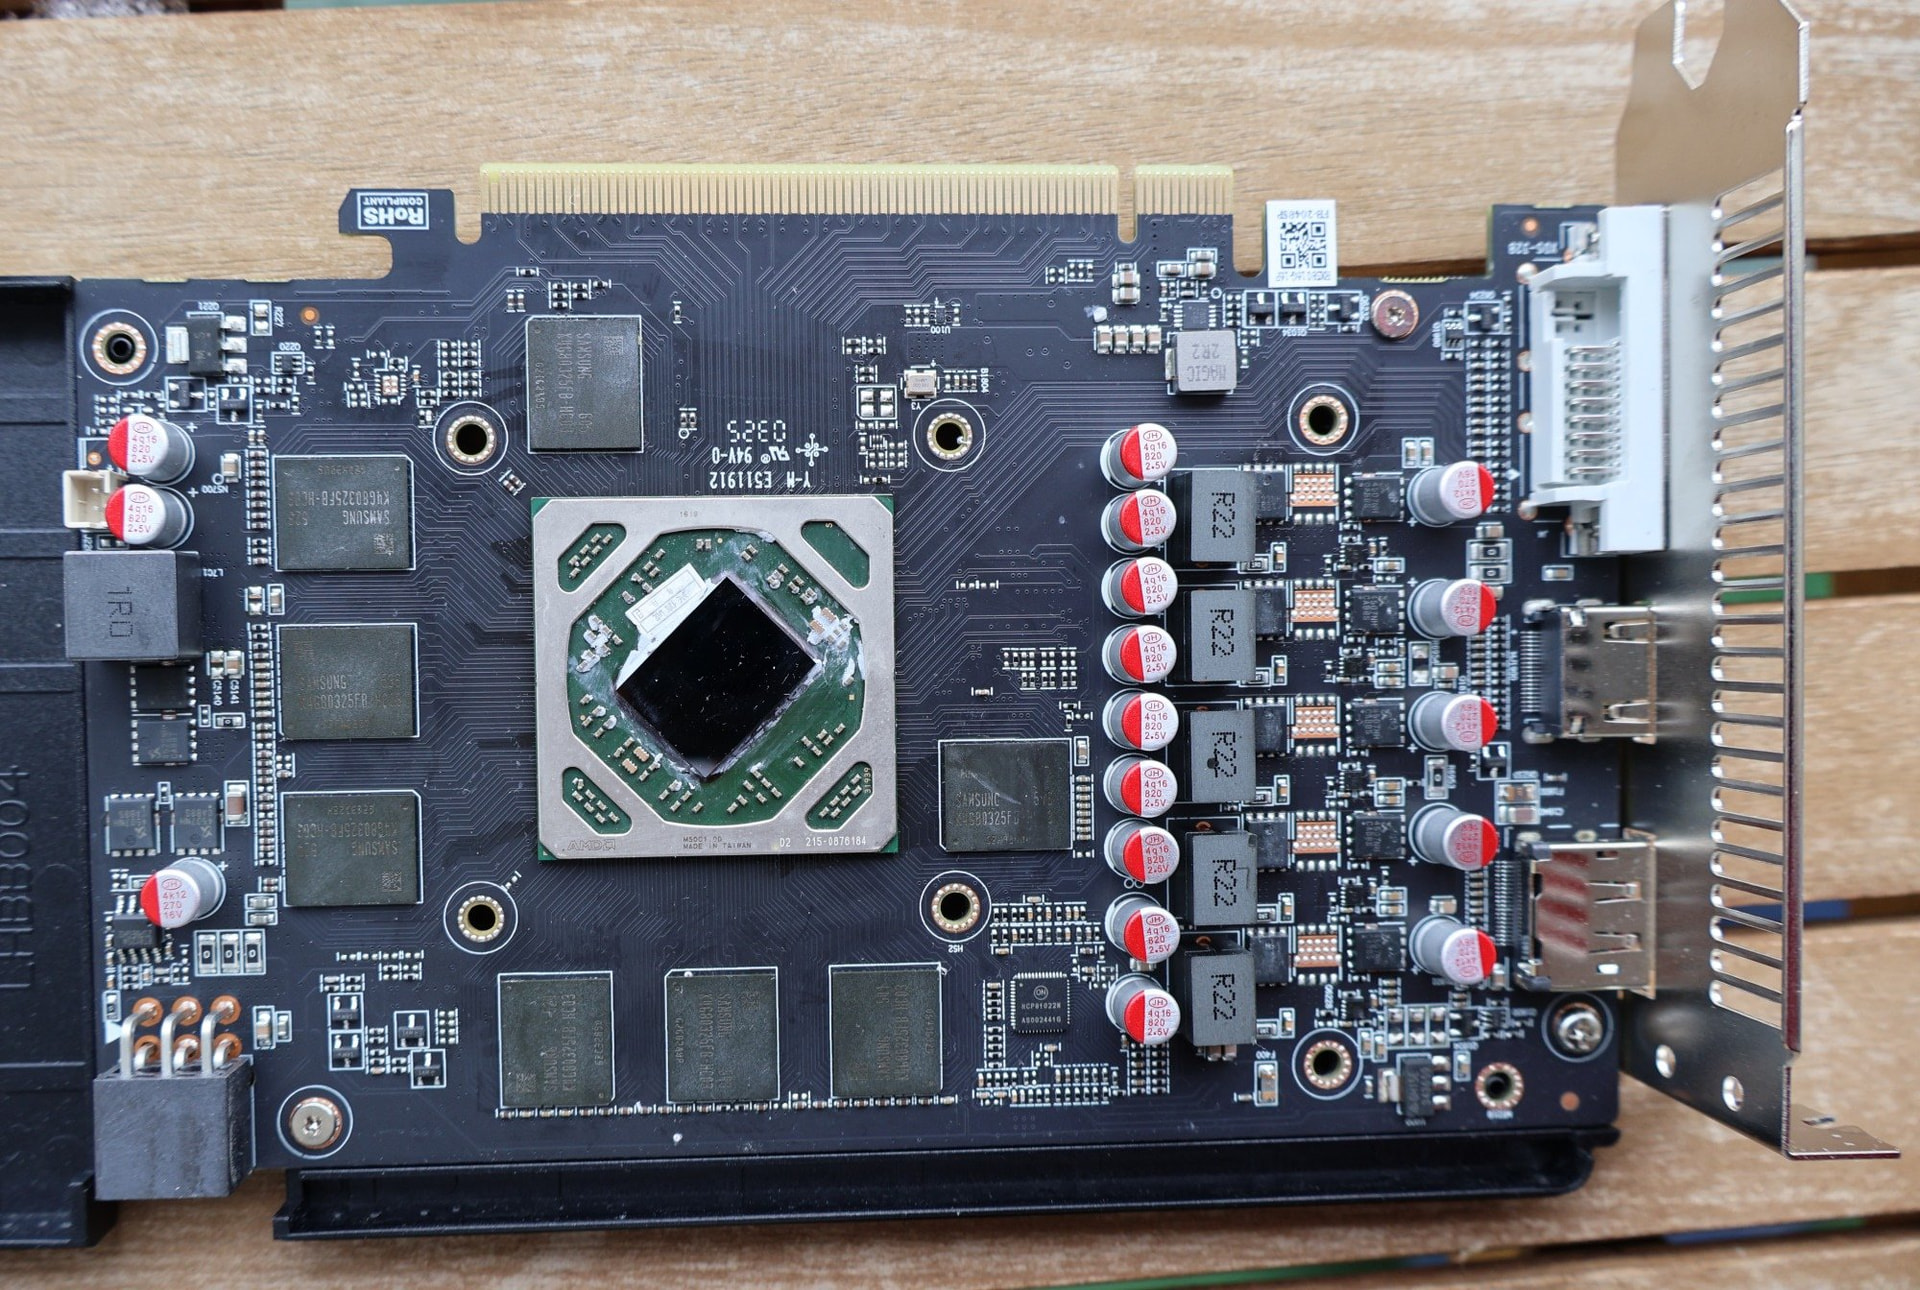
Some time ago, I got a Kinology RX 570 16GB GPU from AliExpress. Compared to standard consumer variants, it has 16GB of VRAM instead of 8GB. AMD had some prosumer and white-label Polaris cards with such VRAM, and at some point someone decided to make “consumer” cards like that:
I did a few gaming benchmarks, but it’s rather impossible to get capped by 8GB of VRAM on a standard RX 570/580 while not getting limited by the card’s raster capabilities (<<30 FPS).
Still a bit curious if it can do any meaningful compute with that VRAM for the memes (or maybe more?).
Be curious to know how some smaller LLMs run on it. They won’t be blisteringly fast, but surely faster than CPU.
At 224GB/Sec the memory bandwidth is still better than most consumer platform CPUs (e.g., 12700k) by 2-3x.
You might need to run a rolling release linux with vulkan support (doesn’t support rocm any more from what google/gemini AI tells me) for llama-cli to get it working? Not sure with AMD that old.
Look at 4 bit models in the ~12-20b parameter size. Which should be interesting as an experiment. If you can get these cheap enough you could get a pair and run 32GB models for cheap!
gpt-oss-20b is still a pretty good general chat model in the 16 ish GB size. Based on totally unscientific measurement of my ~960GB/sec 7900xtx getting 160 tokens/sec, and token generation being memory bandwidth limited, you could potentially get up to 40 tokens/sec on that model, which is actually pretty good for interactive chat?