Model performance on the Radeon VII

Using my Radeon VII daily with LLMs, I figure I’ll make a single source of model performance on my workstation.

5950X
64GBRAM
RVII
llama-swap
my own harness
Ubuntu 24.04 ESR
kernel: 6.14.0-37-generic

I frequently test new quantizations and finetunes. I try to keep models busy as often as possible mostly on coding verification and documentation currently.

The test for this run is: osc/registry/productivity/home-inventory.osc.md at 4ce739037c1c3dd9c7394be05d82fcfb4a64f085 · s1ugh34d/osc · GitHub

The prompt is only the OSC raw data. I use 0.7 temp in the prompts, and although many of the models write code, the software is far from complete in each first one-shot.
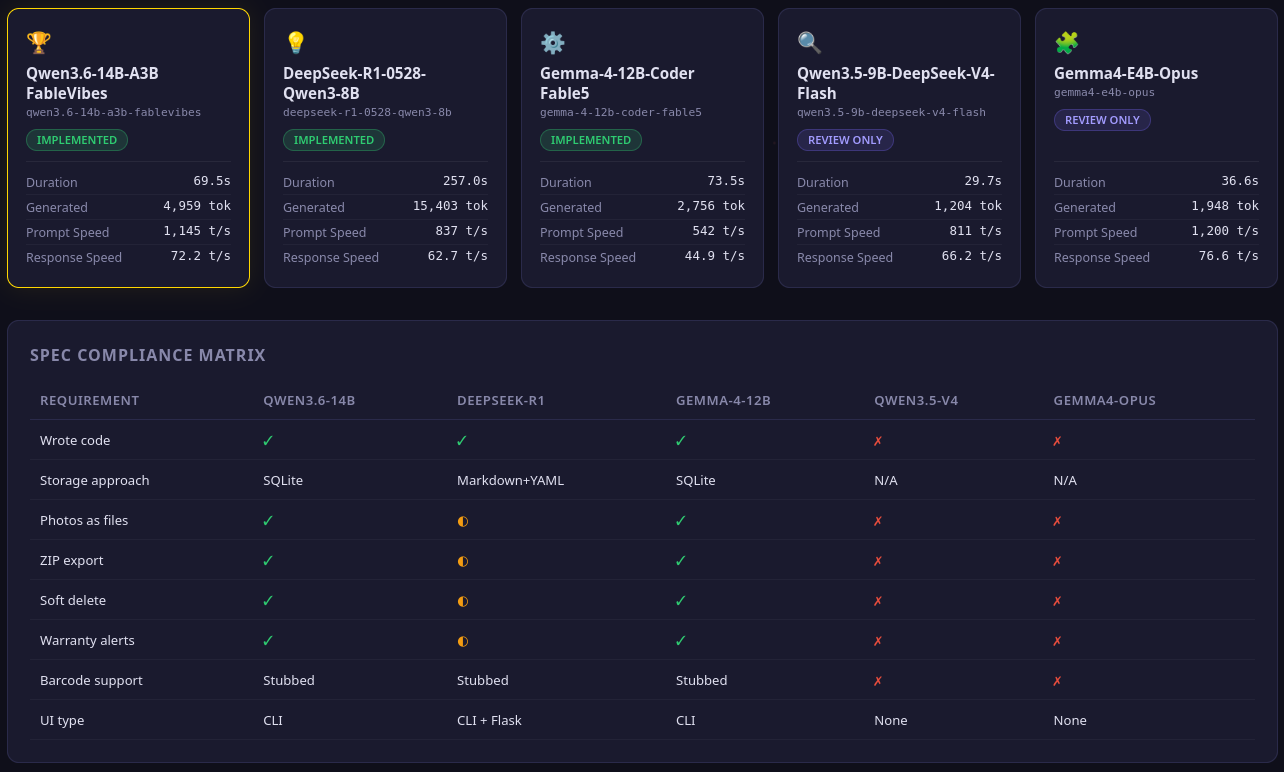
I haven’t tuned out the build to where I can upload snapshots to OSC datasets yet, but the one-shot contracted software I find gives me a feel for the performance a given trained weights will have for my workflow.

| Model                        | Cached Prompt Tokens | New Prompt Tokens | Generated Tokens | Prompt Speed | Generation Speed | Duration |
| ---------------------------- | -------------------: | ----------------: | ---------------: | -----------: | ---------------: | -------: |
| gemma4-e4b-opus              |                    - |             1,034 |            1,948 | 1,199.50 t/s |        76.59 t/s |  36.55 s |
| qwen3.5-9b-deepseek-v4-flash |                    - |             1,015 |            1,204 |   810.67 t/s |        66.20 t/s |  29.70 s |
| gemma-4-12b-coder-fable5     |                    - |             1,035 |            2,756 |   541.56 t/s |        44.92 t/s |  73.53 s |
| deepseek-r1-0528-qwen3-8b    |                    - |               981 |           15,403 |   837.05 t/s |        62.73 t/s | 256.97 s |
| qwen3.6-14b-a3b-fablevibes   |                    - |             1,015 |            4,959 | 1,144.87 t/s |        72.23 t/s |  69.54 s |

For the plaintext data^

2 Likes

Holy crap. A Radeon 7? The rare market-failure competition to the nVidia 20xx series? Glad it’s still supported by ROCm. I know AMD recently dropped support for old Polaris (RX 580) cards.

ROCM 7.1.x added MI50 card support, effectively extending the RVII’s reign as still valueable more than 6 years after I bought it. They retail for like $300 on fleabay sometimes new. The W/C block took me 8 months to find back in 2020/21 But is well worth it.

Prior to rocm 7.1 support I used rocm 6.3/6.4 successfuly with similar performance, just to use new models you need newer stuff.

Tested over 100 quants and base models within ability of 16GB HBM2. I use it for actual workloads, riding it until I can find chump change for the 32GB upgrade, secondary GPU

1 Like

you definitely should to check repo mixa3607/ML-gfx906

Not GPU model testing

  ┌─────────────────┬──────────┬──────────────┬─────────────────────┬─────────────────┐
  │      Model      │ Accuracy │ 1-question   │ 16 questions, one   │    Peak RAM     │
  │                 │          │     p50      │        state        │                 │
  ├─────────────────┼──────────┼──────────────┼─────────────────────┼─────────────────┤
  │ OpenJev-1.7B    │ 95%      │ 619 ms       │ 5.4 s               │ 8.0 GB (hit its │
  │                 │          │              │                     │  cap)           │
  ├─────────────────┼──────────┼──────────────┼─────────────────────┼─────────────────┤
  │ Kahn1-3B (k=3)  │ 92.5%    │ 2.9 s        │ 142 s               │ 16 GB (hit its  │
  │                 │          │              │                     │ cap)            │
  ├─────────────────┼──────────┼──────────────┼─────────────────────┼─────────────────┤
  │ jiwo-0.8b       │ 90%      │ 545 ms       │ 25.5 s              │ 5.6 GB          │
  ├─────────────────┼──────────┼──────────────┼─────────────────────┼─────────────────┤
  │ laya            │ 80%      │ 165 ms       │ 11.9 s              │ 1.8 GB          │
  ├─────────────────┼──────────┼──────────────┼─────────────────────┼─────────────────┤
  │ rlcd-modernbert │ 55%      │ 51 ms        │ 3.9 s               │ 2.4 GB          │
  ├─────────────────┼──────────┼──────────────┼─────────────────────┼─────────────────┤
  │ NanoJev         │ 50%      │ 442 ms       │ 38 s                │ 4.3 GB          │
  └─────────────────┴──────────┴──────────────┴─────────────────────┴─────────────────┘

Testing decision models on my 5950 with RAM. I have 3 other models testing, but things like clef use a lot of RAM(~18GB)