Hello guys, I am looking to build a high end system for AI inference.
I badly need your advice since there is a lot of conflicting floating around.
Also long term software support and quality is a consideration. The hardware I have these GPUs running in might also be a bottle neck. I have a old Gigabyte G291-Z20 GPU server, that only connects the GPUs on PCIe 3.0, has no ReBAR nor above 4G decoding
In theory I would expect to get more throughput on 8x R9700 than the dgx spark. But I can’t seem to find any benchmarks.
I already have four R9700 but my own performance tests are worse than what people report on a single dgx spark. Maybe its because my prefill is faster as everyone seems laser focused on decode speed.
Like this dude on Huggingface reports getting 10 tps (token per second) on such a system:
And then there is this repo on Github claiming 21.65 tok/s on his two dgx spark.
But luckily I did some experiments and ran into an Issue regarding brownouts / over-current protection. Seems like my G291-Z20 can’t support more than 4x R9700. Its rated for each card to be a 300Watt card. But these can apparently spike to more than that without it being reported by NVTOP. It caused individual cards to crash. I solved that by having a single card in each dual card bay.
So because of this issue I would have to get a external PSU and somehow route cables into the server. But I won’t bother with that and instead go with two DGX Sparks. They may be more slower but hopefully might have better Software support and are more scalable.
I also tried to the power limit to 210W and it failed. I could only imagine that possibly undervolting could help? But my AI agent failed to modify the clock speed.
What on earth kinds of workloads are you running that you can even approach 100% on these cards? I have three of them in a threadripper pro system and between those and the cpu a 1200 watt supply feels like overkill. I never see power usage over maybe 50%. Normally 30 or less. Maybe I am doing something wrong. Actually, I’m kind of hoping so. How can I blow up this PSU so I have an excuse to get a bigger one?
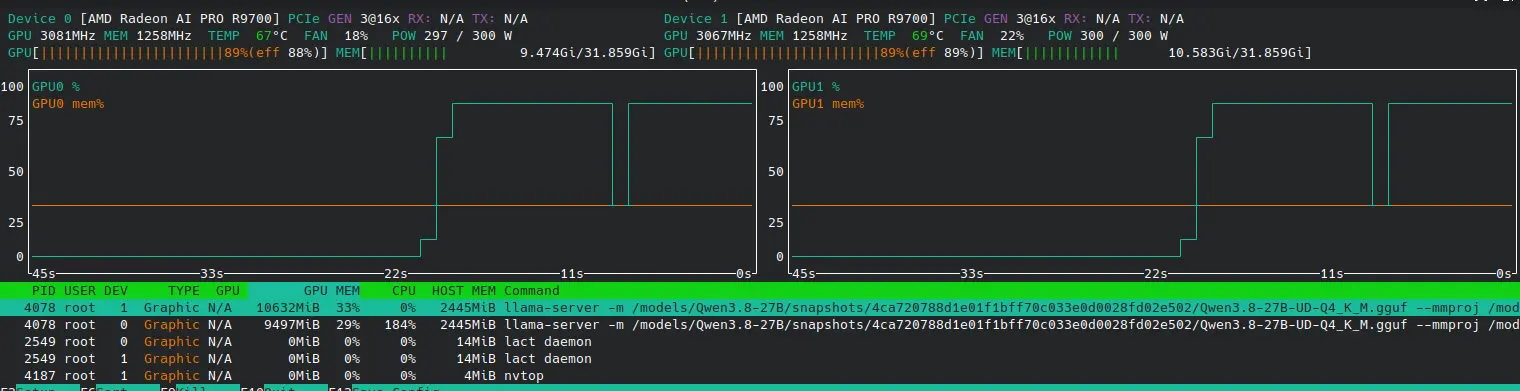
I have been doing some testing with latest llama.cpp build on ROCm and even on NVTOP.
I see the 300W being pulled during stable operation running Qwen3.8-27B-UD-Q4_K_M.gguf
Concurrency
No MTP per-stream
No MTP aggregate
MTP per-stream
MTP aggregate
1
32.1
31.4
45.0
43.6
2
28.0
53.8
37.4
67.8
4
22.2
69.3
31.3
90.8
8
22.2
66.5
25.5
73.3
I guess you are getting way less tok/s?
My Agent also did these optimizations for max performance: 0000:c6:00.0: runtime PM -> on, power profile -> COMPUTE
0000:07:00.0: runtime PM -> on, power profile -> COMPUTE
#!/bin/bash
# amdgpu-power-tune: apply LLM-inference power tuning to AMD dGPUs at boot.
#  - runtime PM -> on        (prevents PCIe link autosuspend / Gen3 downtraining)
#  - power profile -> COMPUTE (better perf/watt for llama.cpp)
#  - optional power cap      (set AMD_GPU_POWER_CAP_W=<watts> in /etc/default/amdgpu-power-tune)
set -u

LOG() { echo "amdgpu-power-tune: $*"; }

CAP_UW=""
if [ -n "${AMD_GPU_POWER_CAP_W:-}" ]; then
    CAP_UW=$(( AMD_GPU_POWER_CAP_W * 1000000 ))
fi

# Wait up to 30s for amdgpu cards to enumerate
cards=""
for i in $(seq 1 30); do
    cards=$(ls -d /sys/class/drm/card[0-9]* 2>/dev/null)
    [ -n "$cards" ] && break
    sleep 1
done

applied=0
for card in /sys/class/drm/card[0-9]*; do
    dev="$card/device"
    [ -f "$dev/pp_power_profile_mode" ] || continue        # not an AMD dGPU with amdgpu sysfs
    [ "$(cat "$dev/vendor" 2>/dev/null)" = "0x1002" ] || continue

    loc=$(basename "$(readlink -f "$dev")")

    if [ -f "$dev/power/control" ]; then
        echo on > "$dev/power/control" 2>/dev/null && LOG "$loc: runtime PM -> on"
    fi

    if echo 5 > "$dev/pp_power_profile_mode" 2>/dev/null; then
        LOG "$loc: power profile -> COMPUTE"
    else
        LOG "$loc: WARN: could not set COMPUTE profile"
    fi

    hwmon=$(ls -d "$dev"/hwmon/hwmon* 2>/dev/null | head -1)
    if [ -n "$CAP_UW" ] && [ -n "$hwmon" ]; then
        max=$(cat "$hwmon/power1_cap_max" 2>/dev/null)
        min=$(cat "$hwmon/power1_cap_min" 2>/dev/null)
        if [ -n "$max" ] && [ "$CAP_UW" -le "$max" ] && [ "$CAP_UW" -ge "${min:-0}" ]; then
            echo "$CAP_UW" > "$hwmon/power1_cap" 2>/dev/null && LOG "$loc: power cap -> ${AMD_GPU_POWER_CAP_W}W"
        else
            LOG "$loc: cap ${AMD_GPU_POWER_CAP_W}W out of range ($((${min:-0}/1000000))-$(($max/1000000))W), skipped"
        fi
    fi
    applied=$((applied+1))
done

LOG "tuned $applied AMD GPU(s)"
exit 0
I get about 30 tokens/sec decode but the power usage on each card doesn’t exceed 100 watts. I also use the compute power profile and slightly bumped the memory. That’s whether I use Q4 or Q8. I prefer Q8 because if it fits, why not?